Command Palette
Search for a command to run...
L'ancrage visuel favorise l'apprentissage de la signification des mots dans les régimes à faible volume de données
L'ancrage visuel favorise l'apprentissage de la signification des mots dans les régimes à faible volume de données
Chengxu Zhuang Evelina Fedorenko Jacob Andreas
Résumé
Les modèles linguistiques neuronaux modernes constituent des outils puissants pour la modélisation de la production et de la compréhension des phrases par l'humain, et leurs représentations internes s'avèrent remarquablement alignées sur les représentations du langage dans le cerveau humain. Pour atteindre de tels résultats, ces modèles doivent toutefois être entraînés selon des modalités radicalement différentes de celles de l'humain : ils exigent plusieurs ordres de grandeur plus de données linguistiques que celles dont disposent les enfants au cours de leur développement, et ce en l'absence de contexte perceptif ou social. Les modèles entraînés de manière plus naturelle, avec une supervision ancrée, présentent-ils un apprentissage linguistique plus proche de celui de l'humain ? Nous examinons cette question dans le cadre de l'apprentissage des mots, sous-tâche essentielle de l'acquisition du langage. Nous entraînons un ensemble diversifié d'architectures de modèles linguistiques, avec et sans supervision visuelle auxiliaire, sur des ensembles de données de tailles variables. Nous évaluons ensuite l'apprentissage par ces modèles des catégories syntaxiques, des relations lexicales, des traits sémantiques, de la similarité entre mots et de l'alignement avec les représentations neurales humaines. Nous constatons que la supervision visuelle peut effectivement améliorer l'efficacité de l'apprentissage des mots. Toutefois, ces gains restent limités : ils se manifestent presque exclusivement dans le régime à faible volume de données et sont parfois annulés par l'inclusion de signaux distributionnels riches issus du texte. Les informations véhiculées par le texte et par les images ne sont pas redondantes — les modèles principalement guidés par l'information visuelle produisent des représentations qualitativement différentes de celles des modèles principalement guidés par les co-occurrences de mots. Néanmoins, nos résultats suggèrent que les approches actuelles de modélisation multimodale ne parviennent pas à exploiter efficacement l'information visuelle pour construire des représentations lexicales humaines à partir de données à échelle humaine.
One-sentence Summary
Researchers at MIT and Harvard find that auxiliary visual supervision in neural language models improves word learning efficiency primarily in low-data regimes, yet current multimodal approaches still fail to effectively leverage visual information to build human-like word representations from human-scale data.
Key Contributions
-
The work evaluates word learning across diverse language-model architectures, including CLIP, GIT, and Flamingo, trained with and without auxiliary visual supervision on datasets of varying scales. It assesses syntactic categories, lexical relations, semantic features, word similarity, and alignment with human neural representations.
-
Visual supervision improves word-learning efficiency mainly in low-data regimes, where visually supervised models can learn from less text than language-only models.
-
Visual and textual information are not redundant: models driven mainly by visual information yield qualitatively different word representations from models driven mainly by word co-occurrences, while current multimodal methods still struggle to integrate both signals effectively at larger data scales.
Introduction
Neural language models are powerful tools for both NLP and computational models of human language processing, but they are poor models of human cognitive development because they require far more training data than children receive during language acquisition. Vision may be a promising way to address this gap, because human learners ground words in perceptual experience across modalities such as vision, touch, and hearing.
Prior multimodal models have made progress on tasks that require reasoning over images and text together, but it has remained unclear whether these models actually acquire more human-like language learning efficiency, especially word knowledge. Existing studies also often examine narrow aspects of language acquisition or simplified settings, leaving open how current visually grounded architectures learn lexical semantics under controlled conditions.
The authors address this by testing whether visual grounding improves word learning in neural language models. They compare visually grounded models such as CLIP, GIT, and Flamingo against language-only controls, carefully varying dataset size and the amount of word co-occurrence information. They evaluate the models with diverse tests of word knowledge, including syntactic categories, lexical relations, semantic features, semantic similarity, and neural response prediction. Their main contribution is showing that visual grounding can improve some aspects of word learning, but only in very small data regimes and when distributional linguistic information is limited. The results also reveal that current models often fail to effectively combine perceptual and textual contexts, limiting their value as computational models of visually grounded language acquisition.
Dataset
-
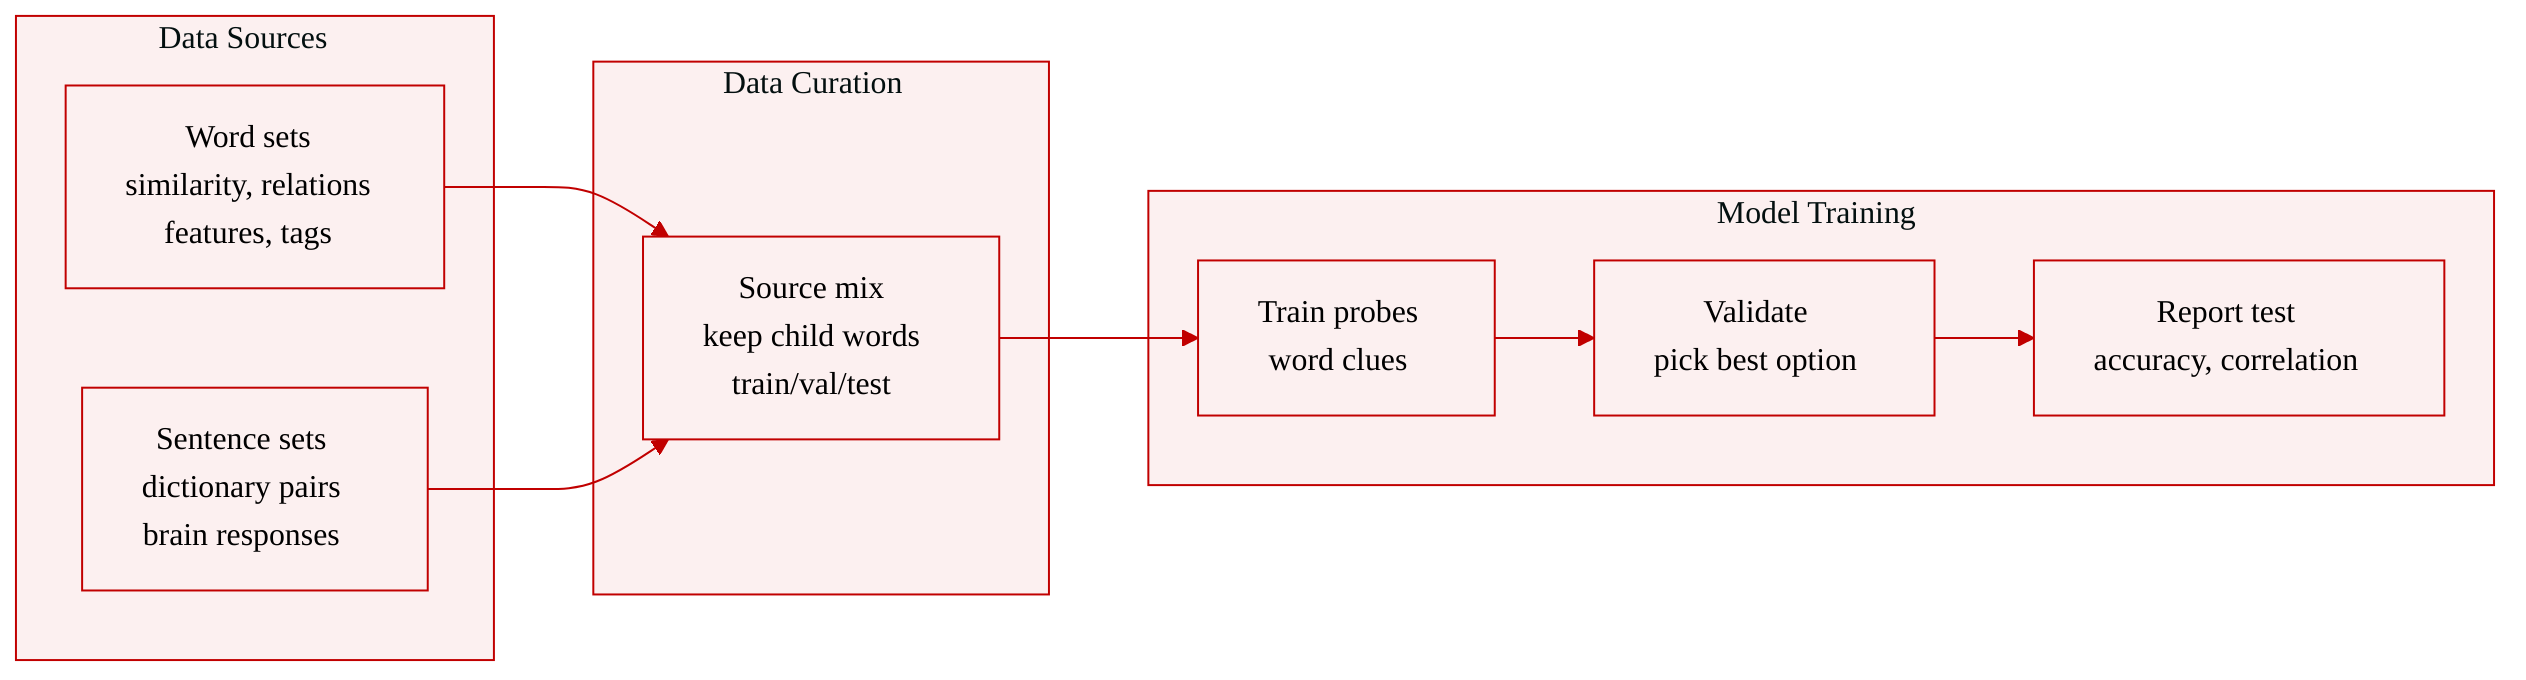
The authors do not introduce a training corpus; they assemble a suite of evaluation benchmarks for word learning. The data come from human word-similarity judgments, a lexical-relation dataset, human semantic feature norms, corpus part-of-speech tags, dictionary sentences, and human brain-response measurements.
-
Word similarity benchmark:
- Source: Human relatedness judgments collected by Bruni et al. (2012), related to common word-similarity benchmarks such as WordSim-353, SimLex-999, SimVerb-3500, and MEN.
- Composition: Word pairs judged for semantic similarity or relatedness.
- Filtering rule: The authors keep words typically acquired by children under age 10 using age-of-acquisition information from Kuperman et al. (2012). They note that this filtering barely changes results.
- Processing and usage: Hidden-layer word representations are extracted from language models, pairwise cosine similarities are computed, and Spearman correlation is used to compare model similarities with human judgments. The best layer is selected by correlation.
-
Lexical relation prediction benchmark:
- Source: CogALex-V.
- Composition: More than 2500 word pairs in both training and test sets.
- Label schema: Five lexical relation categories: synonymy, antonymy, hypernymy, part-whole meronymy, and random.
- Processing and usage: The difference between hidden representations of each word pair is used as input to a linear probe. A probe is trained per layer, the best layer is chosen using validation accuracy, and reported performance is test accuracy.
-
Semantic feature prediction benchmark:
- Source: Dataset constructed by Buchanan et al. (2019).
- Composition: Human annotators write semantic features for target words, such as features describing edibility or size.
- Processing and usage: Language model representations are evaluated on their ability to predict human-produced semantic features.
-
Part-of-speech prediction benchmark:
- Source: Corpus-based part-of-speech tags.
- Composition: Each word is labeled with its most frequent part of speech in the corpus.
- Coverage: Includes all words contained in the word similarity, lexical relation, and semantic feature benchmarks.
- Processing and usage: Models are evaluated on their ability to predict the most frequent corpus-based part-of-speech tag for single words.
-
Context-based word-understanding benchmark:
- Source: Real sentences containing target words from sentence.yourdictionary.com.
- Composition: Sentence pairs containing an original sentence and a minimally modified sentence.
- Scale: 280K sentence pairs for nouns, 128K for verbs, and 72K for adjectives, forming three sub-benchmarks.
- Construction rule: Sentences are minimally altered to make the target word context less appropriate while keeping the sentence grammatical. The modifications are selected using a large-scale pretrained language model to make the modified sentence less likely but still grammatical.
- Usage: Model performance is measured as the fraction of pairs in which the model assigns higher probability to the original sentence than to the modified sentence.
-
Brain-response prediction benchmark:
- Source: Sentence-level brain-response dataset collected by Pereira et al. (2018), also used by Schrimpf et al. (2021).
- Composition: Brain responses to sentences paired with sentence representations from language models.
- Processing and usage: A linear regression model is trained to predict brain response from hidden representations. Performance is evaluated as correlation between predicted and actual brain responses on held-out data, following the fitting procedure of Kauf et al. (2023).
Method
The authors construct a controlled training pipeline for comparing language-only models, visually grounded language models, and single-word word-learning baselines under the same data conditions. The pipeline samples image-caption pairs from a large web-scale multimodal corpus and trains models using next-token prediction, contrastive image-caption matching, or single-word label prediction. This design isolates the contribution of visual information, distributional context, and syntactic organization to word learning.
The basic training data consist of image-caption pairs. For language-only models, only the text portion is used. The training objective is standard next-token prediction, where the model is given a partial caption and trained to predict the next token. The language architecture is a compact six-layer GPT-2-style transformer. Keeping the architecture shallow and fixed allows the authors to examine learning behavior without the confounding effect of large model capacity.
For visually grounded models, the authors begin with image representations produced by a pre-trained vision model rather than learning visual features from paired image-caption data. Specifically, they use a DINO Vision Transformer pretrained on unlabeled images. The image feature is taken from the final hidden state of the special class token, producing a single vector that summarizes the entire image. This choice allows the visual encoder to remain frozen while the downstream language module learns how to use the visual representation.
The first visually grounded family follows a generation-style objective similar to GIT. In this setup, the image representation is inserted into the model context, and the language model is trained to generate the next word in the caption conditioned on both the visual context and the preceding text. In effect, the image feature becomes part of the prompt or conditioning signal for language generation. This architecture tests whether a language model can learn caption generation when grounded in a fixed visual representation.
The second visually grounded family uses a contrastive image-caption matching objective related to CLIP. Here, the model learns an embedding space in which representations of matching image-caption pairs are pulled closer together, while representations of mismatched pairs are pushed farther apart. In the authors’ implementation, the visual features are precomputed from the unsupervised visual encoder, and the language module is trained from scratch to align with these features. This design is not identical to standard pretrained CLIP, because the visual encoder is not co-trained on text-image pairs and the language component is smaller than the typical CLIP text encoder. The important feature of this setup is that the model learns word-related semantic structure through cross-modal contrastive alignment rather than through sequential generation alone.
To isolate the effect of visual information from the effects of sentence context, the authors also train single-word models. In these models, a caption is decomposed into individual words, and each word is treated independently as a label for the corresponding image. The model is then trained either with a generation-style objective, using the single word as the target sequence, or with a contrastive objective, using the single word as the text-side representation to be matched with the image. This removes co-occurring words, word order, and syntactic structure from the learning signal. As a result, the learned word representation depends only on the visual evidence and the word label, not on the distributional context that normally accompanies the word in natural language.
The pipeline also includes word-only baselines. These models attempt to predict a single-word label from the special class token alone, without visual input or contextual tokens. Because the model can only exploit the frequency of each word in the training labels, these baselines provide a trivial reference point for measuring how much performance comes from nonlinguistic memorization or prior statistics rather than from grounded representation learning.
Training scales are varied to examine how model performance changes with exposure to more or fewer image-caption pairs. The number of samples ranges from very small to large, and the training duration is adjusted according to evaluation-set loss. Smaller datasets generally require more training epochs to converge, while larger datasets require less repeated exposure per example. Across all model variants, the training process is structured to keep the core comparison clean: each model receives the same basic supervision signal but differs in whether it sees visual features, word context, syntactic structure, or only isolated word labels.
Experiment
The evaluation framework compares language-only and multimodal models through benchmarks for word similarity, lexical relations, semantic feature prediction, part-of-speech tagging, context-based word understanding, and brain-response prediction, using hidden representations, linear probes, likelihood comparisons, and regression analyses. The experiments show that visual input, especially single-word grounding, can improve learning of concrete words and semantic features in small-data regimes, but it does not consistently help lexical relations, part-of-speech tagging, verb or color word judgments, sentence processing, or brain alignment. Adding textual context or using different architectures and visual encoders mostly fails to produce robust multimodal gains, indicating that current models struggle to effectively combine visual and distributional information.