Command Palette
Search for a command to run...
Ne jamais apprendre à partir de zéro : une comparaison équitable des modèles de séquences longues nécessite des a priori pilotés par les données
Ne jamais apprendre à partir de zéro : une comparaison équitable des modèles de séquences longues nécessite des a priori pilotés par les données
Ido Amos Jonathan Berant Ankit Gupta
Résumé
La modélisation des dépendances à longue portée au sein de séquences constitue un objectif de longue date en apprentissage automatique et a conduit à des architectures, telles que les modèles à espace d'état, qui surpassent considérablement les Transformers sur les séquences longues. Toutefois, ces gains empiriques impressionnants ont été pour la plupart démontrés sur des jeux de référence (par exemple Long Range Arena) où les modèles sont initialisés aléatoirement puis entraînés à prédire une étiquette cible à partir d'une séquence d'entrée. Dans ce travail, nous montrons que l'initialisation aléatoire conduit à une surestimation considérable des différences entre architectures et que le pré-entraînement avec des objectifs standards de débruitage, en utilisant uniquement les données de la tâche en aval, engendre des gains remarquables pour plusieurs architectures ainsi que des écarts très faibles entre les Transformers et les modèles à espace d'état (SSM). En contraste marqué avec les travaux antérieurs, nous constatons que les Transformers standards égalent la performance de S4 sur Long Range Arena lorsqu'ils sont correctement pré-entraînés, et nous améliorons les meilleurs résultats rapportés pour les SSM sur la tâche PathX-256 de 20 points absolus. Ensuite, nous analysons l'utilité des paramétrisations structurées précédemment proposées pour les SSM et montrons qu'elles deviennent pour la plupart redondantes en présence d'une initialisation pilotée par les données, obtenue par pré-entraînement. Notre travail démontre que, lors de l'évaluation de différentes architectures sur des tâches supervisées, l'incorporation d'a priori pilotés par les données via le pré-entraînement est essentielle pour une estimation fiable des performances, et peut être réalisée de manière efficace.
One-sentence Summary
Random initialization grossly overestimates architectural gaps between Transformers and state space models on benchmarks like Long Range Arena, whereas pretraining with denoising objectives using only downstream task data allows vanilla Transformers to match S4 and improves SSM results on PathX-256 by 20 absolute points.
Key Contributions
-
This paper shows that random initialization on long-range benchmarks can grossly underestimate architecture differences and proposes supervised pretraining with standard denoising objectives on downstream task data to learn data-driven priors for reliable evaluation.
-
On Long Range Arena, pretraining improves vanilla Transformers by more than 30% in mean absolute performance, enabling them to match state-of-the-art SSMs such as S4 without architectural changes, and improves S4 on five of six tasks, including a 20-point gain on PathX-256 from 67 to 87.
-
This work analyzes structured SSM parameterizations and finds they become mostly redundant once pretraining learns data-driven initialization, providing competitive Long Range Arena results with Transformers and diagonal linear RNNs and using learned convolution kernels to reveal learned long-range priors.
Introduction
Self-supervised pretraining is widely used in machine learning, and downstream models are typically finetuned from pretrained checkpoints to obtain strong performance. This is especially important for modeling long-range dependencies, where benchmarks such as Long Range Arena have suggested that standard Transformers struggle, motivating new architectures with hand-crafted inductive biases. However, training these architectures from scratch can conflate performance differences caused by architecture choices with the absence of a useful pretraining objective. The authors show that this discrepancy largely comes from training and evaluation practices, and they introduce self pretraining, a simple data-driven approach that applies denoising objectives directly on the downstream training data. This produces better inductive biases without requiring large pretrained corpora or architectural modifications, improving Transformers and state space models on Long Range Arena and showing that many manual biases become unnecessary.
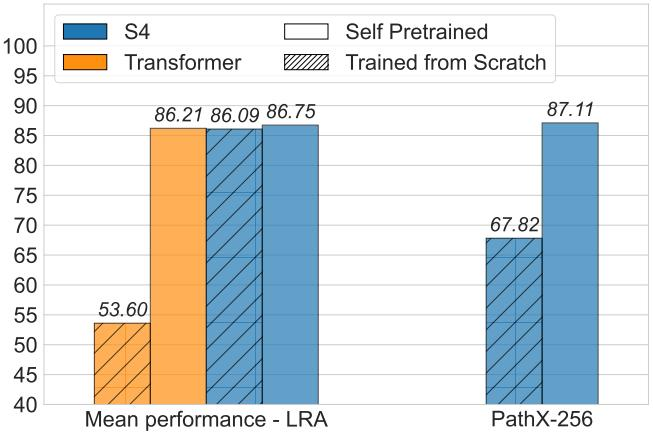
Experiment
The experiments evaluate Transformers and state space models on long-range sequence tasks, including Long Range Arena and additional modalities, primarily by comparing models trained from scratch with models self-pretrained on task-specific data. The results show that self-pretraining substantially improves the reliability of comparisons and reveals that Transformers can learn effective long-range dependencies without specialized architectural assumptions. Across model choices, data scales, and modalities, the findings indicate that data-driven priors are often competitive with or more effective than manually designed biases for capturing sequence structure.
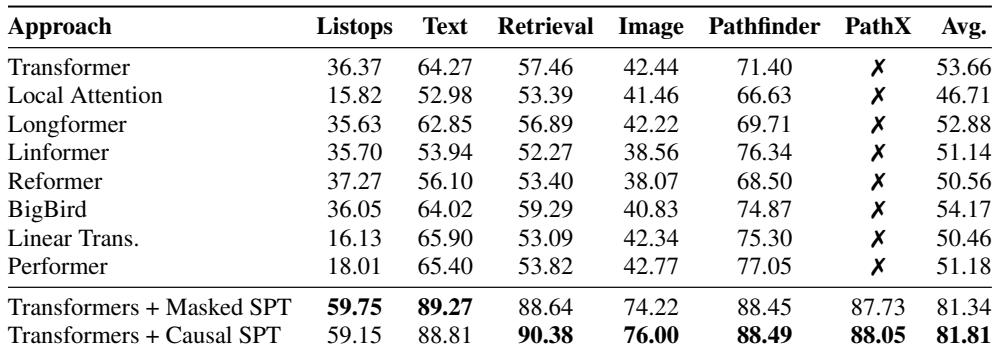
Self-pretraining Transformers on task data before finetuning produces much larger gains than training from scratch on Long Range Arena, increasing average accuracy by roughly 30%. These improvements appear for both causal and masked objectives, including tasks such as LISTOPS where context may not strongly support token prediction, indicating that learned priors from self-pretraining are central to more reliable evaluation. Self-pretraining substantially improves Transformer performance across Long Range Arena tasks compared with random initialization. Causal and masked self-pretraining lead to similar gains, even on tasks where causal models offer no clear advantage. Transformer baselines trained from scratch show uneven results and remain at chance accuracy on PathX.
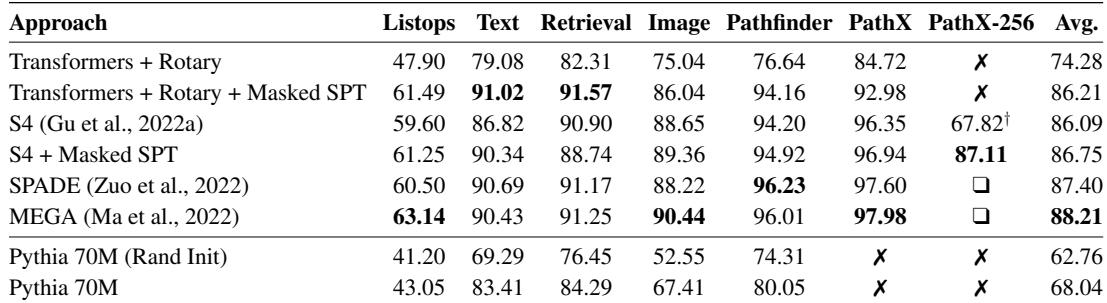
Self pretraining substantially strengthens Transformers on sequence modeling tasks, closing the gap with strong structured sequence models and showing that much of the needed inductive bias can be learned from data. S4 also benefits from self pretraining, especially on the longest Pathfinder task, while text pretrained Transformers remain useful but less effective than pretraining directly on the target modality. The results support pure attention models as competitive when trained with task-specific pretraining. Masked self pretraining produces broad gains for rotary Transformers across the benchmark. Self pretraining helps S4 modestly overall and strongly on the longest Pathfinder task. Text pretrained Pythia improves over random initialization but lags behind Transformers pretrained on the task data.
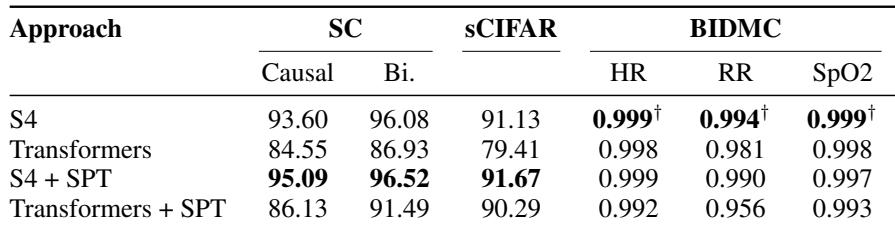
Across Speech Commands and sequential CIFAR, SPT produces large improvements for Transformers and smaller gains for S4. The method also narrows the gap between trained from scratch Transformers and S4, and reduces the difference between causal and bidirectional S4 on speech. On BIDMC regression tasks, all models are already near ceiling, so the benefit of SPT is difficult to observe. SPT gives Transformers large gains on Speech Commands and sequential CIFAR. SPT modestly improves S4 and narrows Transformer versus S4 performance gaps. BIDMC scores are very high for both model families, limiting visible SPT improvements.
The experiments evaluate task-specific self-pretraining before finetuning on Long Range Arena, sequence modeling, Speech Commands, sequential CIFAR, and BIDMC, comparing randomly initialized Transformers, S4 variants, and text-pretrained models. They show that pretraining on the target task data substantially strengthens Transformers and makes learned priors central to reliable evaluation, while causal and masked objectives perform similarly. Self-pretraining also narrows gaps between Transformers and stronger structured sequence models, gives S4 modest or task-dependent gains, and outperforms text-based pretraining, whereas near-ceiling BIDMC results limit visible improvements.