Command Palette
Search for a command to run...
Quand le multilinguisme est-il une malédiction ? La modélisation du langage pour 250 langues à ressources élevées et faibles
Quand le multilinguisme est-il une malédiction ? La modélisation du langage pour 250 langues à ressources élevées et faibles
Tyler A. Chang Catherine Arnett Zhuowen Tu Benjamin K. Bergen
Résumé
Les modèles de langage multilingues sont largement utilisés pour étendre les systèmes de traitement automatique des langues aux langues à faibles ressources. Cependant, les preuves concrètes de l'effet du multilinguisme sur les performances de la modélisation du langage pour chaque langue individuelle restent rares. Nous pré-entraînons ici plus de 10 000 modèles de langage monolingues et multilingues pour plus de 250 langues, incluant plusieurs familles linguistiques peu étudiées en TALN. Nous évaluons comment les performances de modélisation du langage pour chaque langue varient en fonction de (1) la taille des données monolingues, (2) la taille des données multilingues ajoutées, (3) la similarité linguistique des langues ajoutées et (4) la taille du modèle (jusqu'à 45 M de paramètres). Nous constatons que, ajoutées de manière modérée, les données multilingues améliorent les performances en modélisation du langage pour les langues à faibles ressources, de façon comparable à une augmentation de la taille des jeux de données à faibles ressources pouvant atteindre 33 %. Les améliorations dépendent de la similarité syntaxique des données multilingues ajoutées, avec des effets additionnels marginaux du recouvrement lexical. Toutefois, les langues à ressources élevées voient systématiquement leurs performances se dégrader dans les scénarios de pré-entraînement multilingue. À mesure que la taille des jeux de données augmente, l'ajout de données multilingues commence à nuire aux performances tant pour les langues à faibles ressources que pour celles à ressources élevées, probablement en raison de la capacité limitée du modèle (la « malédiction du multilinguisme »). Ces résultats suggèrent que le pré-entraînement massivement multilingue peut ne pas être optimal pour aucune des langues concernées, mais que des modèles plus ciblés peuvent améliorer significativement les performances.
One-sentence Summary
UC San Diego pre-trains over 10,000 language models across 250 languages, finding that moderate multilingual data improves low-resource language modeling by up to 33% depending on syntactic similarity, while large-scale multilingual pre-training degrades performance for both low- and high-resource languages due to the curse of multilinguality, suggesting that targeted models can be superior to massively multilingual ones.
Key Contributions
-
The paper contributes a large-scale controlled study of multilingual pre-training by pre-training over 10,000 monolingual and multilingual language models for 252 languages and evaluating performance as a function of target-language data size, added multilingual data size, linguistic similarity, and model size up to 45M parameters.
-
This work shows that moderate multilingual data can improve low-resource language modeling, with gains comparable to increasing the target-language dataset by up to 33%, and it identifies syntactic similarity as the main driver of these gains, with vocabulary overlap having only a marginal effect.
-
The paper demonstrates that multilingual pre-training consistently degrades high-resource language performance, in some cases equivalent to reducing the target dataset by more than 85%, and it links this degradation to the curse of multilinguality, suggesting that targeted multilingual models can outperform broadly multilingual ones for language modeling.
Introduction
Multilingual language models are central to modern NLP, especially for low-resource languages, cross-lingual transfer, and multilingual generation. They are typically pre-trained once on a fixed set of many languages, but that fixed recipe can favor high-resource languages and may not reveal how pre-training choices affect each language individually. Prior work gives mixed evidence about whether multilingual training helps or harms languages, and many studies rely on already-trained models or downstream tasks, making it hard to isolate the effects of language selection, data volume, similarity, and model size.
The authors address this by pre-training over 1,900 monolingual models for 252 languages and over 8,400 multilingual models. They systematically vary monolingual dataset size, multilingual dataset size, linguistic similarity of added languages, and model size up to 45M parameters. Their main contribution is a quantitative map of when multilingual pre-training helps or hurts raw language modeling. They find that moderate amounts of similar multilingual data can improve low-resource language performance, but multilingual data often damages high-resource language performance, especially as model capacity becomes a bottleneck.
Dataset
-
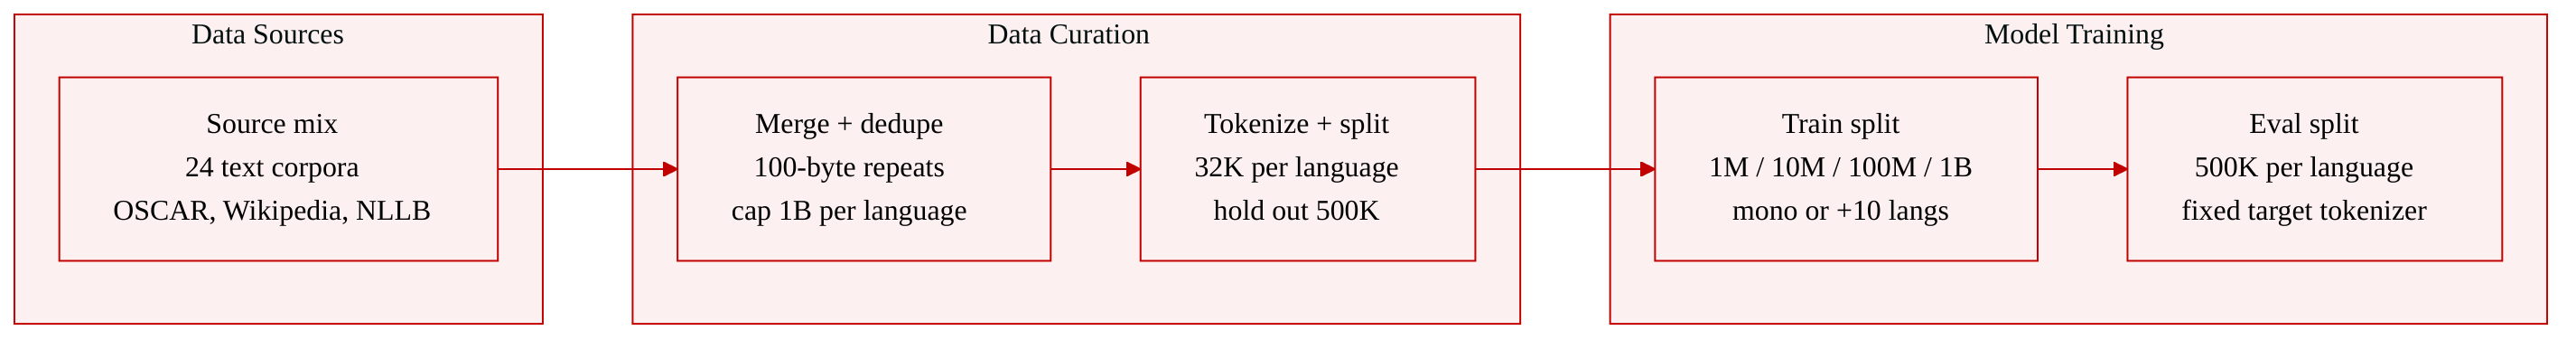
The authors construct a large multilingual text corpus from 24 sources, including OSCAR, Wikipedia, and NLLB. They merge corpora per language and deduplicate repeated sequences of 100 UTF-8 bytes.
-
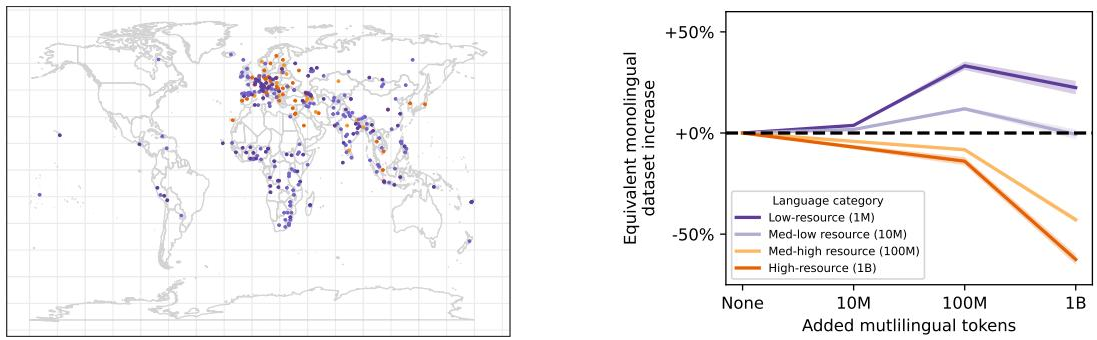
The final corpus contains 41.4B tokens across 1572 languages, with each language capped at 1B tokens. For language modeling experiments, they keep 252 languages with at least 1.5M tokens. These languages span five continents, 29 language families, and 30 scripts.
-
They build metadata for each language, including token counts and geographic coordinates from Glottolog. Appendix sections report the full language list, token counts, and resource categories.
-
Dataset subsets are defined by per-language token budgets: 1M, 10M, 100M, and 1B tokens. These correspond to low, med-low, med-high, and high-resource settings, respectively. Each language set also excludes 500K tokens for evaluation.
-
Among the 252 analyzed languages, 252 have at least the low-resource size, 167 have med-low resource size, 48 have med-high resource size, and 28 have high-resource size.
-
For each language, the authors train a SentencePiece tokenizer with a maximum vocabulary of 32K. Tokenizer training uses 10K randomly sampled lines per language, and this cutoff is applied uniformly to control tokenization quality across languages.
-
In monolingual experiments, the authors pretrain models on each language subset at the specified data size, using the fixed language-specific tokenizer.
-
In multilingual experiments, each model has one target language and keeps that language’s monolingual tokenizer fixed. The target language data is mixed randomly with added multilingual data from 10 other languages.
-
The added multilingual data totals 10M, 100M, or 1B tokens, with equal token counts from each of the 10 added languages. The added languages are selected from the 48 med-high resource languages that have at least 100M tokens.
-
For multilingual models, the 10 added languages share a separate 32K multilingual tokenizer, trained on 10K randomly sampled lines from each added language. Target language data and added language data are tokenized separately, then token IDs are merged for shared vocabulary items while preserving the target language tokenizer.
Method
The authors construct a measurement framework that first establishes monolingual scaling baselines and then uses those baselines to interpret multilingual pre-training gains. For each target language, they pre-train autoregressive Transformer language models at three capacities, corresponding to tiny, mini, and small model sizes. Each language receives a fixed SentencePiece tokenizer with a vocabulary of about 32K tokens. Training is run at several monolingual data scales when available, and evaluation is held out from the corresponding training data. These monolingual models provide calibration points for later comparison against multilingual models.
A central component of the method is the conversion of raw evaluation log-likelihood into an interpretable estimate of monolingual data equivalence. The authors observe that relative log-likelihood follows a power-law relationship with monolingual dataset size. They fit a function of the form
ℓ=−ax−b+c,where ℓ denotes relative evaluation log-likelihood and x denotes monolingual data size expressed in log tokens. For languages with many data points, the curve can be fit directly from performance measured across multiple training-data scales. For lower-resource languages, the available points are too sparse to fit all parameters reliably, so one coefficient is fixed using the median value from better-fitted languages, while the remaining parameters are estimated from the available measurements.
The resulting fitted and language-specific curves are shown in the figure below.
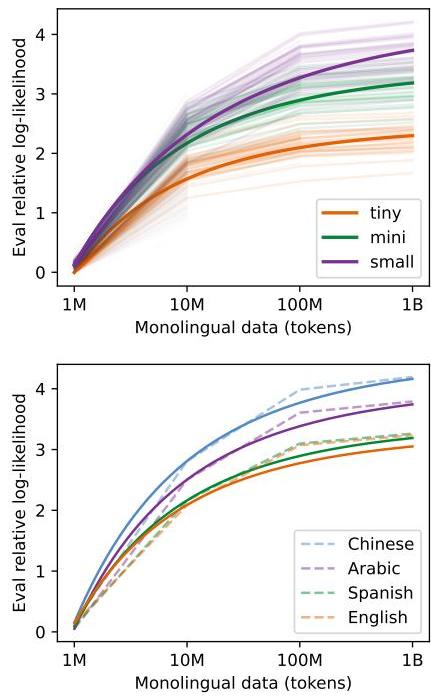
These curves allow the authors to invert a measured multilingual model likelihood and estimate how many monolingual tokens would be needed to reach the same performance level. Even when the absolute token estimate is imperfect, the mapping remains monotonic with respect to log-likelihood, so relative model rankings are preserved.
The multilingual pre-training design is built around a target language and a controlled set of added languages. For each target language, the model retains the monolingual tokenizer for that language throughout both pre-training and evaluation. This is essential because perplexity and log-likelihood are only comparable within a language when the same tokenizer is used. To avoid excessively large vocabularies when multiple languages are mixed, the added languages share a separate multilingual tokenizer with a 32K vocabulary. The target-language tokenization is preserved, while token IDs for the added languages are merged into the shared vocabulary for overlapping items. This keeps the target evaluation space fixed across different multilingual conditions.
Multilingual data is introduced in controlled quantities and can vary along several axes. For a given target language, the authors vary the amount of monolingual target-language data, the amount of added multilingual data, the linguistic similarity of the added languages, and the model size. Added multilingual tokens are randomly interleaved with monolingual target tokens during training. The added languages are selected based on similarity to the target language, measured using normalized syntactic similarity, geographic proximity, and lexical similarity. The three normalized similarity scores are averaged to produce a combined linguistic similarity score, allowing the authors to contrast models trained with either the most similar or least similar added languages.
This architecture and training procedure creates a paired comparison between monolingual and multilingual regimes while keeping the target language evaluation interface stable. By controlling tokenization, data quantities, linguistic similarity, and model size, the method isolates how cross-lingual data affects performance in the target language and translates those effects into estimates of monolingual data equivalence.
Experiment
The experiments establish monolingual baselines for 252 languages and convert relative likelihood into estimated monolingual token counts to compare multilingual models. They show that adding multilingual data can benefit low-resource languages, particularly when the added languages are syntactically similar and the amount of multilingual data is moderate, while the benefits are smaller or negative when data volume or model capacity is inadequate. By contrast, high-resource languages consistently suffer from multilingual pre-training, with degradation that eases only at larger model scales. Overall, multilinguality is useful primarily for low-resource settings with sufficiently large models, whereas targeted monolingual training remains more suitable for high-resource languages.