Command Palette
Search for a command to run...
Pertes perceptuelles pour le transfert de style en temps réel et la super-résolution
Pertes perceptuelles pour le transfert de style en temps réel et la super-résolution
Justin Johnson Alexandre Alahi Li Fei-Fei
Résumé
Nous considérons des problèmes de transformation d'images, dans lesquels une image d'entrée est transformée en une image de sortie. Les méthodes récentes pour de tels problèmes entraînent typiquement des réseaux de neurones convolutifs de type feed-forward à l'aide d'une perte pixel à pixel entre l'image de sortie et l'image de référence. Des travaux parallèles ont montré que des images de haute qualité peuvent être générées en définissant et en optimisant des fonctions de perte perceptuelle fondées sur des attributs de haut niveau extraits de réseaux pré-entraînés. Nous combinons les avantages des deux approches et proposons l'utilisation de fonctions de perte perceptuelle pour l'entraînement de réseaux feed-forward destinés à des tâches de transformation d'images. Nous présentons des résultats sur le transfert de style, où un réseau feed-forward est entraîné pour résoudre en temps réel le problème d'optimisation proposé par Gatys et al. Comparé à la méthode basée sur l'optimisation, notre réseau produit des résultats qualitativement similaires tout en étant trois ordres de grandeur plus rapide. Nous expérimentons également avec la super-résolution à partir d'une seule image, où le remplacement d'une perte pixel à pixel par une perte perceptuelle donne des résultats visuellement satisfaisants.
One-sentence Summary
Stanford University authors propose training feed-forward convolutional networks with perceptual loss functions based on high-level features from pretrained networks, achieving real-time style transfer that matches the qualitative results of Gatys et al.'s optimization-based method at three orders of magnitude faster speed while also improving single-image super-resolution.
Key Contributions
-
Feed-forward convolutional transformation networks are trained with perceptual loss functions computed from high-level features of pretrained convolutional networks instead of conventional per-pixel losses, combining fast feed-forward architectures with optimization-based perceptual image generation.
-
The approach is evaluated on image style transfer by training a feed-forward network to approximate the optimization objective of Gatys et al. in real time. The trained network gives qualitatively similar results while being three orders of magnitude faster than the optimization-based method.
-
On single-image super-resolution, replacing a per-pixel loss with a perceptual loss produces visually pleasing results and better reconstruction of fine details and edges.
Introduction
Many image transformation tasks, such as denoising, super-resolution, colorization, segmentation, and style transfer, involve mapping an input image to a structured output image. A common solution is to train a feedforward convolutional network with a per-pixel loss, which makes inference fast but can poorly reflect human-perceived differences, such as small misalignments or missing fine details. Optimization-based methods using perceptual losses improve output quality by comparing high-level features from a pretrained network, but they require slow test-time optimization. The authors address this gap by training feedforward networks directly with perceptual loss functions derived from a pretrained CNN. This approach preserves real-time inference while transferring semantic and perceptual knowledge from the loss network, yielding fast style transfer results and improved detail reconstruction in single-image super-resolution.
Method
The authors leverage a learning-based image transformation framework rather than optimizing each output image directly from an initial noise image. The system contains two main components: a trainable image transformation network fW and a fixed loss network ϕ that defines the objective functions used during training. Refer to the framework diagram.
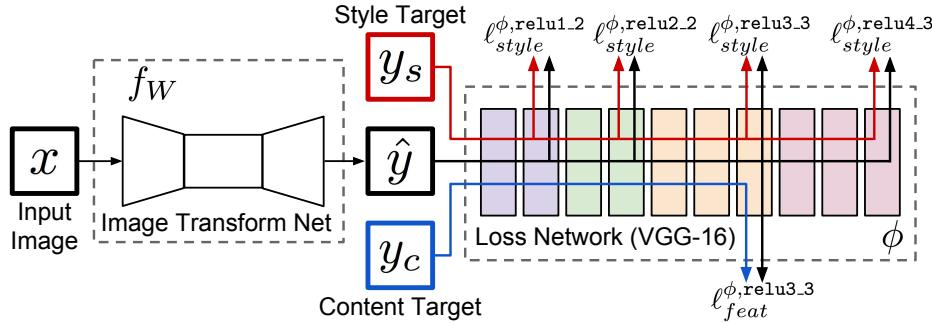
The transformation network is a deep residual convolutional network parameterized by weights W. Given an input image x, it produces an output image y^=fW(x). The loss network ϕ is used to compute perceptual measurements between y^ and target images such as a content target yc or a style target ys. The network is trained with stochastic gradient descent to minimize a weighted combination of loss functions:
W∗=argWminEx,{yi}[i=1∑kλiℓi(fW(x),yi)].The loss network is pretrained for image classification and remains fixed during training. In the presented method, this loss network is typically a 16-layer convolutional classification network, and its learned feature representations serve as a perceptual metric for content and style. The key design insight is that a network trained for classification already contains informative intermediate features that correlate with human-perceived image similarity, so these features can be reused inside the loss function instead of relying only on raw pixel distance.
The transformation network follows fully convolutional architectural guidelines with residual blocks. It does not use pooling layers. Instead, downsampling and upsampling are performed with strided and fractionally strided convolutions. All non-residual convolutional layers are followed by spatial batch normalization and ReLU nonlinearities, except the output layer, which uses a scaled tanh activation to constrain the output pixel values. The first and final layers use 9×9 kernels, while the remaining convolutional layers use 3×3 kernels.
For style transfer, the network maps color images of size 3×256×256 to color images of the same size. For single-image super-resolution with upsampling factor f, the network produces a high-resolution patch of size 3×288×288 from a low-resolution patch of size 3×288/f×288/f. Because the architecture is fully convolutional, it can be applied to images of different resolutions at test time.
The downsampling and upsampling design is central to both efficiency and receptive field growth. In style transfer, the network uses two stride-2 convolutions to reduce spatial size, then several residual blocks, then two fractionally strided convolutions with stride 1/2 to restore the original resolution. For super-resolution, after a sequence of residual blocks, it applies log2f convolutional layers with stride 1/2. This avoids using a fixed interpolation step for upsampling. Instead, the upsampling behavior is learned jointly with the rest of the transformation network.
Downsampling before the deep residual body has two practical benefits. First, it reduces computational cost. A 3×3 convolution with C filters applied to a feature map of size C×H×W has the same computational cost as a 3×3 convolution with DC filters applied to a feature map of size DC×H/D×W/D. Therefore, after downsampling, the network can use wider feature representations at similar cost. Second, downsampling enlarges the effective receptive field. Without downsampling, each 3×3 convolution increases the effective receptive field by 2 pixels. After downsampling by a factor D, the same 3×3 convolution increases the effective receptive field by 2D. This is important for style transfer because coherent style effects require large, spatially aware changes across the image.
The perceptual loss design uses the fixed loss network ϕ to compute both content and style objectives. Let ϕj(x) denote the activations at layer j of the loss network when processing image x. If layer j is convolutional, ϕj(x) is a feature map of shape Cj×Hj×Wj. Instead of matching raw pixels between y^ and a target image y, the feature reconstruction loss encourages similar feature representations:
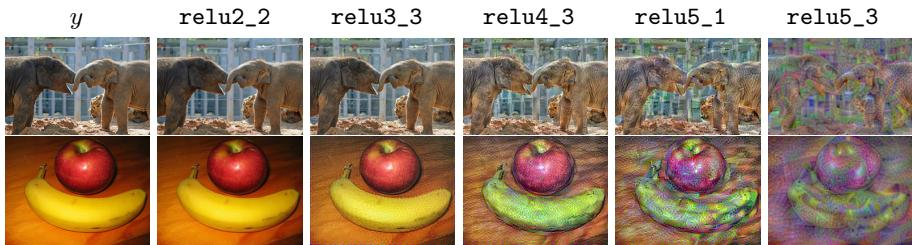
ℓfeatϕ,j(y^,y)=CjHjWj1∥ϕj(y^)−ϕj(y)∥22.Early layers in the pretrained classification network preserve low-level appearance details, so reconstructing from early layers tends to produce images that are very close to the original in color, texture, and local structure. Higher layers preserve content and global spatial organization while ignoring many fine texture details. Refer to the visual feature-reconstruction comparison across network depths.
The style reconstruction loss measures differences in texture, color statistics, and co-occurring feature patterns. It is defined using the Gram matrix of the feature map. For image x, the Gram matrix at layer j is a Cj×Cj matrix whose entries are
Gj,c,c′ϕ(x)=CjHjWj1h=1∑Hjw=1∑Wjϕj(x)h,w,cϕj(x)h,w,c′.If ϕj(x) is interpreted as Cj-dimensional features extracted at each spatial location, the Gram matrix approximates the uncentered covariance of those features across spatial positions. It captures which features activate together. The Gram matrix can be computed efficiently by reshaping ϕj(x) into a Cj×HjWj matrix ψ and computing
Gjϕ(x)=CjHjWjψψT.The single-layer style loss is then
ℓstyleϕ,j(y^,y)=Gjϕ(y^)−Gjϕ(y)F2.For style transfer from a set of layers J, the style loss is summed over those layers:
ℓstyleϕ,J(y^,y)=j∈J∑ℓstyleϕ,j(y^,y).This formulation is useful because the Gram matrix is computed from feature statistics rather than spatially aligned pixel values. Therefore, the style loss remains well-defined even when the output image and the style target have different sizes. Minimizing this loss encourages the output image to reproduce the statistical appearance patterns of the style target while not requiring preservation of the exact spatial layout of that target.
In addition to perceptual losses, the method uses simple pixel-space objectives when needed. The pixel loss is the normalized squared Euclidean distance between the output and target image:
ℓpixel(y^,y)=CHW1∥y^−y∥22.This loss is appropriate when a ground-truth target image exists, such as in super-resolution. A total variation regularizer is also applied to the output to discourage excessive spatial noise and encourage smoother local structure.
For style transfer, the training setup usually uses one transformation network per style target. The content target is the input image x, and the style target ys controls the visual style of the output. The network is trained to minimize a weighted combination of feature reconstruction loss, style reconstruction loss, and total variation regularization. For super-resolution, the input x is the low-resolution image, the content target yc is the high-resolution ground truth, and the style loss is typically omitted. One network is trained for each super-resolution factor.
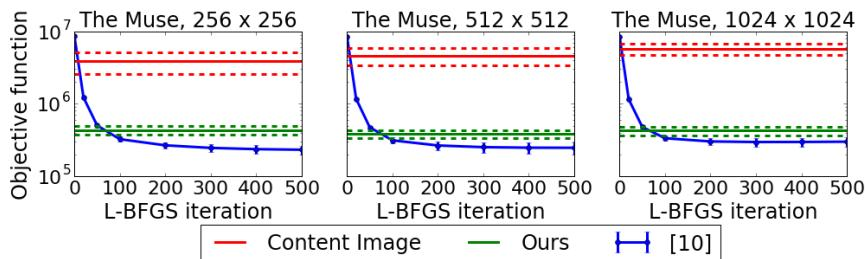
The resulting training process shifts the computational burden from inference to training. Direct optimization generates one image at a time by repeatedly minimizing the same perceptual objective through the fixed loss network. The proposed method instead trains a feedforward transformation network so that, after training, style transfer or super-resolution can be performed by a single forward pass. The learned network is optimized against the same perceptual objective family used by iterative optimization methods, while also being able to generalize to larger input images than those used during training. This objective and generalization behavior is shown in the comparison of loss values during iterative optimization and output quality across resolutions.
Experiment
The experiments evaluate the approach on style transfer and single-image super-resolution. For style transfer, feed-forward networks trained on MS-COCO are compared with an optimization-based baseline, showing similar visual quality while greatly reducing inference time and preserving semantic content even at larger resolutions. For super-resolution, models trained with feature reconstruction loss are compared with pixel-loss and SRCNN baselines, demonstrating that perceptual features improve sharp edges and fine details despite possible increases in low-level artifacts.
For style transfer, the feed-forward network is much faster than the iterative optimization baseline while producing similar qualitative results. The speed advantage is large across multiple image resolutions and remains strong as resolution increases. Generates style-transfer results in a fraction of the time required by the baseline. Can be faster than a single optimization step of the baseline method. Maintains similar qualitative output quality despite a large runtime reduction.
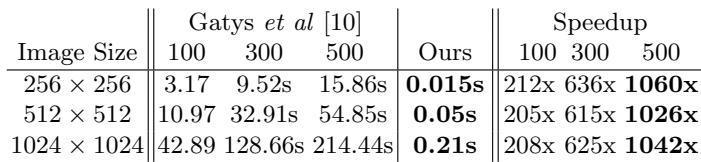
Experiments compare a feed-forward network with an iterative optimization baseline for style transfer across multiple image resolutions. The results validate that the feed-forward model generates stylized images much faster while maintaining similar qualitative output, with the speed advantage remaining strong at higher resolutions and even exceeding a single optimization step of the baseline.