Command Palette
Search for a command to run...
CxMP : un banc d'essai linguistique fondé sur les paires minimales pour l'évaluation de la compréhension constructionnelle dans les modèles de langage
CxMP : un banc d'essai linguistique fondé sur les paires minimales pour l'évaluation de la compréhension constructionnelle dans les modèles de langage
Miyu Oba Saku Sugawara
Résumé
La compréhension de l'acquisition linguistique dans les modèles de langage demeure une question ouverte. Or, de nombreux bancs d'essai se concentrent sur l'acceptabilité grammaticale, accordant nettement moins d'attention à l'interprétation des sens véhiculés par les formes grammaticales. Nous introduisons le Linguistic Minimal-Pair Benchmark for Evaluating Constructional Understanding in Language Models (CxMP), fondé sur la Grammaire des constructions, qui considère les couplages forme–sens (constructions) comme des unités linguistiques fondamentales. Il évalue si les modèles interprètent l'information sémantique impliquée par les constructions, en s'appuyant sur des paires minimales contrôlées couvrant neuf types. Nos résultats montrent que la compréhension constructionnelle se développe plus progressivement et demeure limitée pour certaines constructions, y compris dans les grands modèles de langage (LLM), alors que la performance en acceptabilité grammaticale apparaît plus tôt, les heuristiques superficielles dans CxMP présentant un profil en U. Ces résultats soulignent la nécessité d'élargir les évaluations linguistiques existantes afin de saisir les sens encodés dans la forme linguistique.
One-sentence Summary
Researchers at Nara Institute of Science and Technology, National Institute of Informatics, and The University of Tokyo introduce CxMP, a linguistic minimal-pair benchmark grounded in Construction Grammar that evaluates whether LLMs interpret meanings encoded in grammatical constructions across nine types, finding that constructional understanding develops more gradually and remains limited even in large models, whereas grammatical acceptability emerges earlier.
Key Contributions
- CxMP is introduced as a Construction Grammar-based benchmark that evaluates whether language models interpret the semantic information implied by constructions, rather than only judging grammatical acceptability.
- The benchmark uses controlled minimal pairs across nine construction types, multiple noun variants, swapped participant roles, and a multi-sentence design to isolate constructional meanings from lexical associations and shallow heuristics.
- Experiments show that constructional understanding develops more gradually and remains limited for some constructions in both small models and large language models, whereas grammatical acceptability emerges earlier and shallow heuristics in CxMP exhibit a U-shaped pattern.
Introduction
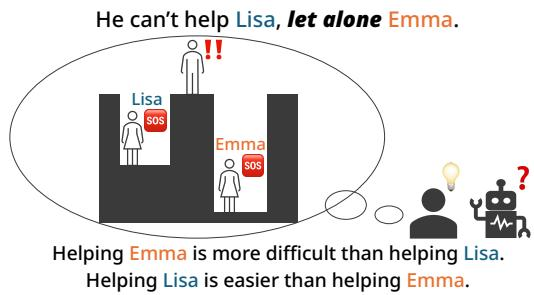
The authors place language model evaluation within Construction Grammar, which treats paired linguistic forms and meanings as basic units of grammar. This matters because current evaluations often focus on grammatical acceptability rather than whether models understand meanings conveyed by syntactic patterns, such as roles and semantic relations implied by a construction. Prior work is limited by fragmented construction benchmarks, a narrow focus on single constructions, and NLI-style formats that obscure model reasoning and disadvantage smaller models. To address this, the authors introduce CxMP, a controlled benchmark covering nine constructions and using minimal pairs to test whether language models, from small developmentally plausible models to modern LLMs, capture construction-encoded meanings.
Dataset
-
CxMP is an evaluation benchmark dataset for constructional understanding. The authors use it to test whether language models can map sentence forms to construction-level meanings across models of different sizes.
-
Dataset scale and structure:
- The dataset contains 43,000 evaluation pairs in total.
- Each pair contains a constructional example sentence with a target construction and a diagnostic sentence that probes its meaning.
- The diagnostic sentence is written as a minimal contrast between a plausible and an implausible interpretation.
- Each construction has two variants, labeled A and B, which probe complementary perspectives.
- The data are not described as a training corpus, and the paper does not report a training split, mixture ratio, or data-mixing strategy.
-
Main data sources and generation pipeline:
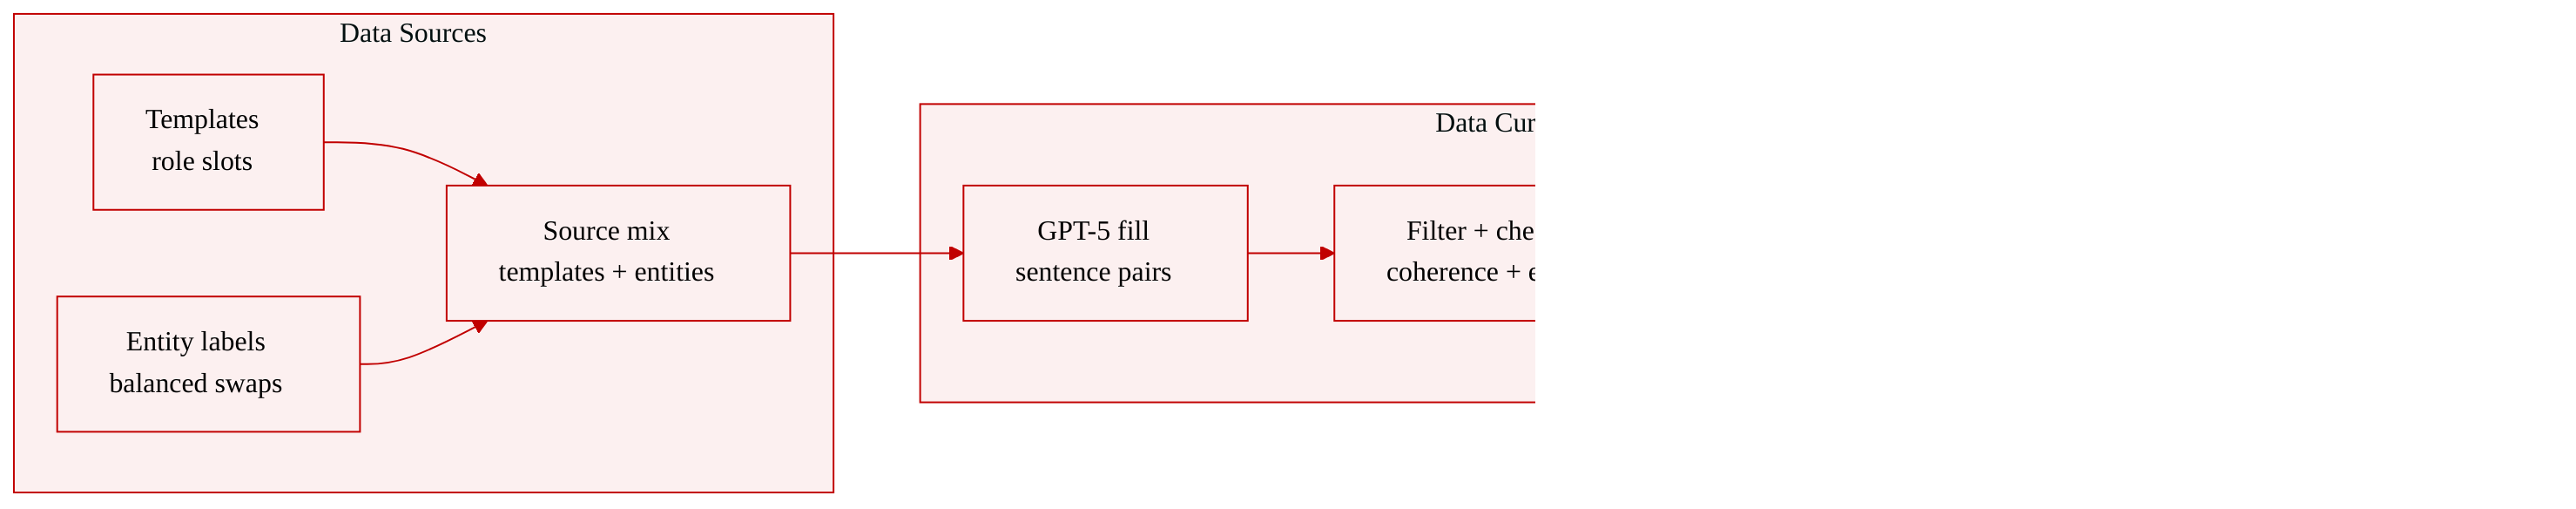
- The authors generate constructional examples using GPT-5 from predefined templates.
- Templates contain slots for structural roles such as subject, verb, object, oblique phrase, open clausal complement, and entity names.
- Plausible diagnostic sentences are predefined for each construction.
- Implausible diagnostic sentences are created by changing selected words into implausible alternatives.
- Generated sentences are filtered using heuristic rules and LLM-based semantic coherence checks.
- A subset of the data is manually inspected to verify that evaluation pairs are coherent.
-
Human validation subset:
- The authors validate a human annotation subset with native English speakers recruited through Prolific.
- Annotators read a sentence and choose the more plausible continuation.
- The validation sample contains 896 items.
- Each item receives three independent annotations.
- Majority-vote accuracy is 96.65%.
- Full annotator agreement is 83.59%.
- Item counts vary by construction, typically 112 and 56 for constructions without switched variants.
-
Entity and variant control:
- Four entity label types are used:
- Female names.
- Male names.
- Name plus alphabet labels, such as Name B.
- Common nouns.
- These entity types are used in equal proportion.
- For constructions with two participants, the authors create swapped versions that reverse subject and object positions.
- Swapped and non-swapped versions are balanced.
- This design reduces dependence on lexical biases, word order heuristics, and gender-associated name patterns.
- Four entity label types are used:
-
Constructional subsets and design details:
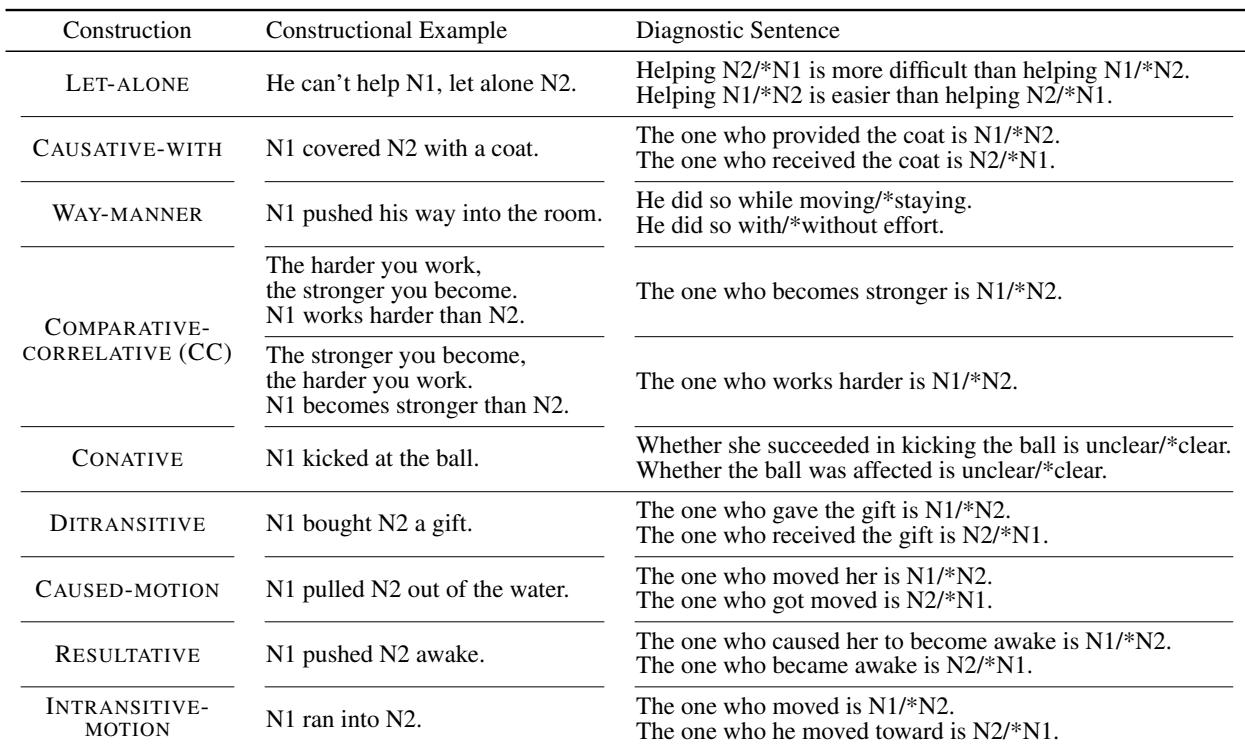
- LET-ALONE:
- Uses nominal comparison with a negative polarity environment.
- Includes negative auxiliaries such as cannot and don’t.
- Probes which action is harder along a negative scalar dimension.
- The related MUCH-LESS construction is omitted because it is treated as surface variation of let alone.
- CAUSATIVE-WITH:
- Uses a with-phrase after the direct object.
- Restricts subject and object to human nouns.
- Tests whether models interpret the affected entity and supplied or provided entity correctly.
- WAY-MANNER:
- Uses the fixed phrase one’s way in object position followed by a path or location phrase.
- Probes motion versus rest and intentional effort.
- COMPARATIVE-CORRELATIVE:
- Uses two clauses beginning with the followed by a comparative adjective or adverb.
- The second clause depends on the first.
- Probes which entity exhibits a resulting property when the first clause sets a relational condition.
- CONATIVE:
- Uses a direct object preceded by at to indicate attempted action without guaranteed success.
- Includes half conative examples and half standard transitive examples.
- Probes whether models distinguish attempted but uncertain action from successful affected-object action.
- DITRANSITIVE:
- Uses the schema subject, verb, object 1, object 2.
- Encodes transfer or giving of a theme to a recipient.
- Probes who gave an item and who received it.
- CAUSED-MOTION:
- Uses the schema subject, verb, object, oblique phrase.
- The oblique phrase denotes direction or path.
- Probes who caused motion and which participant was moved.
- RESULTATIVE:
- Uses the schema subject, verb, object, open clausal complement.
- The complement typically denotes a changed state.
- Probes which participant underwent the change and which participant caused it.
- INTRANSITIVE-MOTION:
- Uses the schema subject, verb, oblique phrase.
- The oblique phrase denotes an animate entity serving as a goal.
- Probes who moved and which participant was the goal of motion.
- LET-ALONE:
-
Metadata and processing features:
- Each instance is associated with a construction label, such as conative, ditransitive, caused-motion, resultative, intransitive-motion, comparative-correlatives, way-manner, causative-with, or let-alone.
- Instances include variant labels A and B.
- Structural roles are controlled through templates, including subject, verb, object, oblique, and open clausal complement.
- Entity-role labels are included to track name types and participant swaps.
- The dataset is text-only, so no cropping strategy is used.
- The main metadata needed for evaluation consists of the constructional example, diagnostic sentence, plausibility label, construction type, variant, entity type, and swap status.
-
Use in the paper:
- The authors use CxMP as a model-agnostic evaluation dataset.
- It is intended for consistent evaluation across small models and large language models.
- The multi-sentence minimal-pair format is used to assess semantic contributions of constructions rather than only grammatical naturalness.
- The swapped entity conditions are used to detect whether models rely on superficial heuristics instead of constructional form-meaning mapping.
Method
The authors construct a unified evaluation framework that operationalizes constructional understanding as the ability to map a construction’s syntactic form to the semantic roles, relations, and event structure it imposes on the entities in a sentence. Rather than testing only lexical recognition or broad factual knowledge, the framework treats a correct interpretation as one in which the model identifies the meaning, role, or relation of entities within a specific construction.
The method is built around nine construction types that span a spectrum from partially fixed expressions to highly schematic argument structure patterns. Each construction is paired with diagnostic sentences that require the model to recover the construction-specific semantic contribution. For a comparative correlative, the first clause establishes a relation between entities, and the diagnostic sentence asks which entity exhibits the resulting property. For a caused motion construction, the oblique phrase indicates a path or direction, and the diagnostic sentence asks which participant caused the motion and which participant moved. For a resultative, the diagnostic sentence targets the change of state and the participant who caused it. This design converts constructional knowledge into targeted interpretation judgments rather than surface-level pattern matching.
The constructional examples and diagnostic pairs are produced through a template based generation pipeline. For each construction, the authors prepare slot filling templates that specify the required syntactic roles, such as subject, verb, object, oblique phrase, or complement, along with the intended entity type. A language model is prompted to fill these slots with contextually appropriate words. The templates constrain the constructional structure, while the model supplies natural lexical material. Plausible diagnostic sentences are also predefined for each construction. Implausible alternatives are then created by replacing selected words with alternatives that violate the intended constructional interpretation. This yields paired items in which the correct answer depends on understanding the construction rather than simply selecting a plausible sentence.
Entity realization is deliberately controlled to reduce superficial lexical or positional cues. The framework uses four kinds of entity expressions: female names, male names, names with alphabet labels, and common nouns. Common nouns tend to be the most natural but can introduce strong semantic bias. Names with alphabet labels are the most controlled, although less naturalistic. Human names provide an intermediate option, although they may still carry gender associations. For constructions involving two entities, the authors also generate swapped versions in which the two entity positions are reversed. These swapped and unswapped versions are balanced in the dataset, allowing the framework to test whether a model relies on word order or positional heuristics rather than true constructional interpretation.
The generated outputs pass through several filtering stages. Heuristic checks remove malformed or structurally invalid sentences. Additional LLM based assessments evaluate semantic coherence and whether the diagnostic sentence matches the intended constructional meaning. A subset of the resulting evaluation pairs is manually inspected to confirm reliability. Human validation with native English speakers further checks that the items are interpretable, with high majority vote agreement on the more plausible continuation. The resulting pipeline produces a controlled evaluation set of construction semantic pairs that test form meaning mapping across a broad range of syntactic constructions.
Experiment
The experiments evaluate the CxMP benchmark across model sizes, training corpora, data scales, objectives, and instruction tuning to determine whether language models understand constructional meanings rather than only surface grammaticality. Models trained under developmentally constrained conditions perform near chance, while larger models improve unevenly, with masked objectives generally better and instruction tuning helping only for some constructions. Further analyses show that constructional meaning emerges later than grammatical acceptability, mid-sized models often depend on lexical and positional biases, and pseudoword substitutions reveal strong reliance on real-word semantics.
The reviewed constructions include partially fixed and fully schematic patterns, such as let alone, causative with, way manner, comparative correlative, conative, and ditransitive. Each construction is evaluated with a short example plus a diagnostic sentence that contrasts a plausible reading with an implausible one, probing scalar, role, motion, or effort relations. Related model results show that scores fall when content words are replaced with pseudowords, but some patterns retain above chance performance when closed class or inflectional cues remain. The evaluation design uses minimal plausible and implausible contrast pairs rather than a single open ended judgment. Pseudoword replacement weakens model performance, indicating reliance on lexical cues, while motion and argument structure patterns show relative stability with grammatical cues.
Among the small models listed, the larger MLM model obtains the highest score, while the CLM models remain lower. Model size helps within the MLM pair, but the CLM model trained on more data still does not surpass the larger MLM model. The overall pattern is consistent with the surrounding results that small-scale models struggle with constructional meaning. The larger MLM model scores above its smaller MLM counterpart and above the listed CLM models. A larger training corpus for one CLM model does not produce the highest score among the models shown.
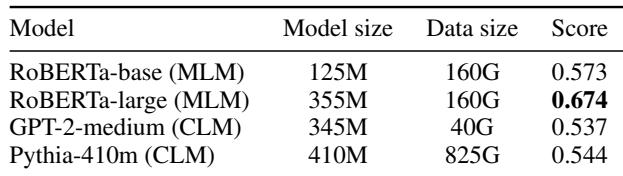
Experiments evaluate partially fixed and schematic constructions using minimal plausible-implausible contrast pairs and pseudoword replacements to test whether models capture constructional meaning beyond surface lexical content. Results show that replacing content words weakens performance, implying reliance on lexical cues, while some motion and argument-structure patterns remain relatively robust when grammatical cues are available. Across the compared models, the larger MLM performs best, and expanding CLM training data does not ensure superior results, indicating that small-scale models still struggle with constructional meaning.