Command Palette
Search for a command to run...
Reconsidérer le rôle des stratégies de prompting dans l'extension du calcul au moment du test des LLM : une perspective de la théorie des probabilités
Reconsidérer le rôle des stratégies de prompting dans l'extension du calcul au moment du test des LLM : une perspective de la théorie des probabilités
Yexiang Liu Zekun Li Zhi Fang Nan Xu Ran He Tieniu Tan
Résumé
Récemment, l'augmentation de la puissance de calcul au moment du test pour les grands modèles de langage (LLM) a suscité une large attention. Cependant, peu d'études ont examiné la manière dont différentes stratégies de prompting de raisonnement se comportent lors de la montée en échelle. Dans cet article, nous nous concentrons sur une configuration d'extension standard et réaliste : le vote majoritaire. Nous menons systématiquement des expériences sur 6 LLM, 8 stratégies de prompting et 6 ensembles de référence. Les résultats expérimentaux montrent de manière constante que, à mesure que le nombre d'échantillonnages et le surcoût computationnel augmentent, les stratégies de prompting complexes présentant une performance initiale supérieure finissent par se laisser distancer par la simple approche Chain-of-Thought. Nous analysons ce phénomène et fournissons des preuves théoriques. De plus, nous proposons une méthode probabiliste permettant de prédire efficacement la performance de l'extension et d'identifier la meilleure stratégie de prompting en cas de grand nombre d'échantillonnages, éliminant ainsi le besoin de processus d'inférence coûteux en ressources dans les applications pratiques. Par ailleurs, nous introduisons deux approches dérivées de notre analyse théorique permettant d'améliorer significativement la performance de l'extension. Nous espérons que nos recherches encourageront à réexaminer le rôle du prompting complexe, à libérer le potentiel des stratégies de prompting simples et à fournir de nouvelles perspectives pour améliorer la performance de l'extension au moment du test.
One-sentence Summary
Researchers from the Chinese Academy of Sciences and UC Santa Barbara show that under majority-voting test-time scaling, complex prompting strategies progressively underperform simple Chain-of-Thought as sampling budgets increase, and they provide theoretical proofs, a probabilistic method to predict optimal prompting strategies at large sampling budgets, and two theory-derived techniques to significantly improve scaling performance.
Key Contributions
-
The paper systematically studies test-time scaling under majority voting across 6 LLMs, 8 prompting strategies, and 6 benchmarks, showing that simple Chain-of-Thought can surpass more complex prompting strategies as sampling and computational overhead increase.
-
The paper provides theoretical proofs and experimental evidence that Chain-of-Thought improves more rapidly because it has fewer hard questions, more easy questions, and less susceptibility to incorrect answers.
-
The paper introduces an O(1) probabilistic method to predict scaling performance and select the best strategy without resource-intensive inference, and proposes difficulty-adaptive scaling and dynamic strategy selection, which raise Majority@10 accuracy from 86.0% to 97.4% on GSM8K and from 15.2% to 61.0% on MATH-500 for LLaMA-3-8B-Instruct.
Introduction
The authors focus on improving the reasoning abilities of large language models by scaling test-time compute, especially through majority voting, which is a practical way to boost model outputs when additional inference budget is available. Prior work has introduced many prompting strategies, such as Chain of Thought, and shown that test-time scaling can improve reasoning, but it remains unclear how different strategies behave under equivalent sampling time or computation budgets. The authors compare eight mainstream prompting strategies across six LLMs and six reasoning benchmarks, finding that simple Chain of Thought often becomes the best strategy as scaling increases. They explain this result theoretically and experimentally, propose an efficient method to predict scaling performance, and introduce two techniques that improve scaling by adapting to question difficulty and selecting the best prompting strategy.
Dataset
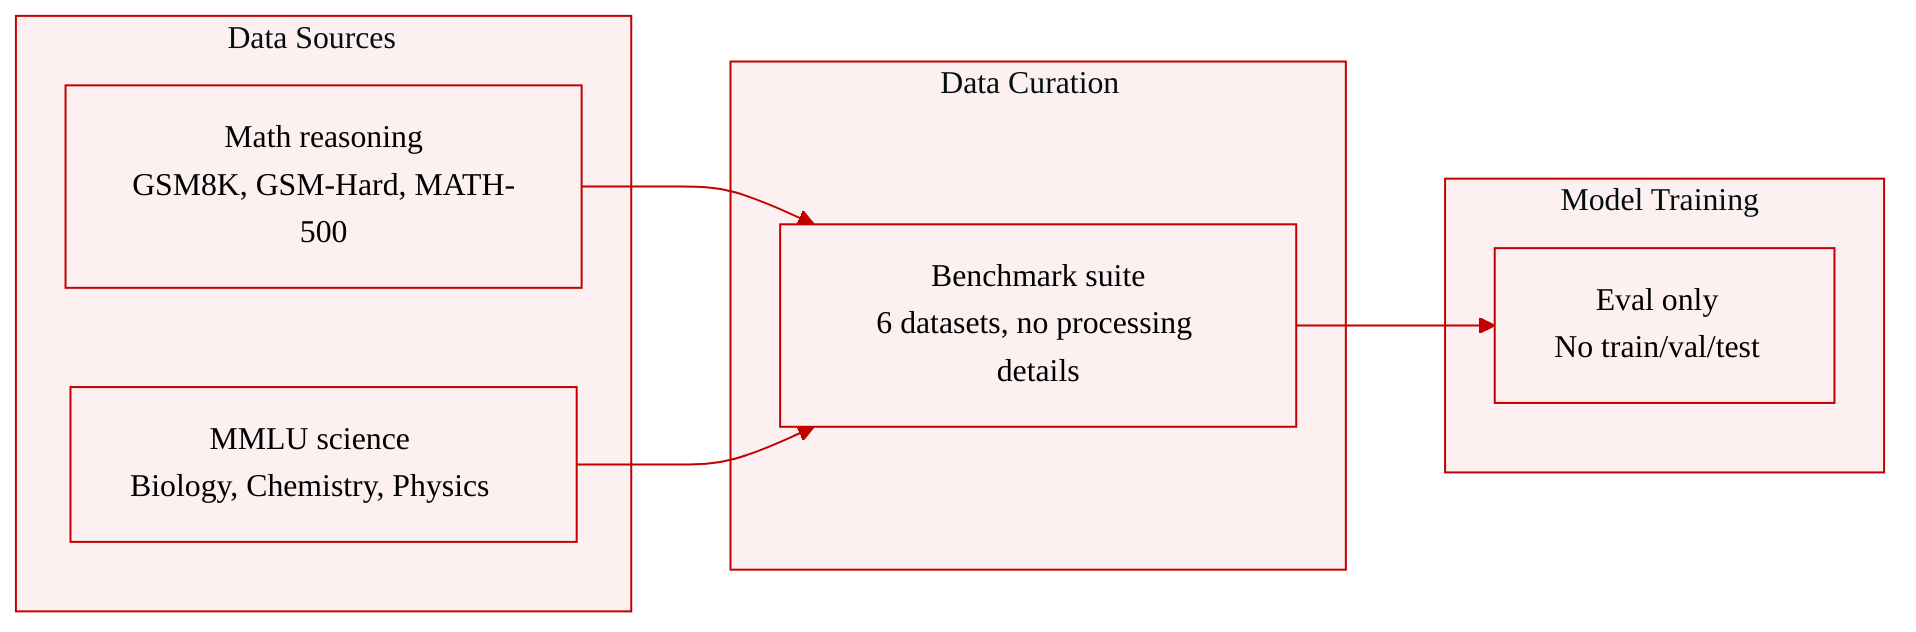
- The authors evaluate their prompting strategies on a benchmark suite of six datasets drawn from reasoning and domain-knowledge tasks used in the original papers.
- The benchmark set includes three math reasoning datasets: GSM8K, GSM-Hard, and MATH-500.
- It also includes three subject-specific science datasets from MMLU: highschool-biology, chemistry, and physics.
- The provided text does not specify subset sizes, collection sources, filtering rules, metadata construction, cropping strategies, or schema details for these benchmarks.
- The data is used for evaluation rather than training, and no training split, mixture ratios, or dataset processing steps are described in the excerpt.
Method
The method treats test time scaling as an inference time prompt selection problem rather than a training or fine tuning problem. The system uses a language model M, a prompting strategy Pi, and an answer extractor ϕ that converts generated output into a discrete answer candidate, typically through pattern matching. For a question x, a single sample is represented as ϕ[M(x∣Pi)]. Under the main setting, the final answer is obtained from N sampling operations.
The authors divide prompting strategies into two families. Non iterative strategies include Direct Prompting, Chain of Thought, Least to Most, Step Back Prompting, and Analogous Prompting. These are grouped as
P1={DiP,CoT,L2M,SBP,AnP}.For these methods, the model generates N independent answers and the final answer is selected by majority voting:
ϕ[M(x∣Pi);N]=mode{ϕ[M(x∣Pi)]}1N,Pi∈P1.Iterative strategies include Self Refine, Multi Agent Debate, and Tree of Thoughts. These are grouped as
P2={S-RF,MAD,ToT}.For Self Refine and Multi Agent Debate, the model performs N rounds of refinement or debate, and the answer is obtained at the end of the process. For Tree of Thoughts, the model explores and evaluates multiple reasoning paths and selects the best one. Formally,
ϕ[M(x∣Pi);N]=ϕ[M(x∣Pi;N)],Pi∈P2.This notation allows different strategies to be compared under an equivalent interpretation of “sampling N times.” If the sampling budget is fixed, the optimal strategy is defined as
PN∗=PiargmaxEx∈D1{ϕ[M(x∣Pi);N]=y},where y is the ground truth answer for x. However, different prompts can generate different numbers of prompt tokens and completion tokens. Since completion tokens are usually more expensive than prompt tokens, the authors define a weighted computational overhead
C(x∣M;Pi;N)and compare strategies under a fixed total cost O:
PO∗=PiargmaxNmaxEx∈D1{ϕ[M(x∣Pi);N]=y},s.t.x∈D∑C(x∣M;Pi;N)≤O.For open source models, closed model token pricing can be used as a proxy for this cost calculation.
To understand why some prompts, especially Chain of Thought, may perform poorly at small N but better at large N, the method models the answer distribution. For a fixed question x, let the possible extracted answers be
A={a1,a2,…,am},and let the corresponding one sample probabilities under strategy Pi be
pi,1,pi,2,…,pi,m.The vector of answer occurrence counts after N samples follows a multinomial distribution:
Xi∼Mult(N,pi,1,pi,2,…,pi,m).The final majority vote answer is one of the answers with the largest occurrence count. If multiple answers share the maximum count, one is selected randomly. The correctness probability for the true answer a1 can therefore be written as
Pr(a1∣Pi;N).The authors characterize question difficulty through the probability mass ranking. Let
pmax=max{pi,1,…,pi,m}and define
S={aj∣pi,j=pmax}.A question is easy for Pi if the correct answer belongs to S and S contains only that answer. It is moderate if the correct answer belongs to S but other incorrect answers tie with it. It is hard if the correct answer is not in S. Easy questions tend to improve with more samples, moderate questions improve with an upper limit, and hard questions can degrade when more samples are taken because the model consistently votes for an incorrect answer.
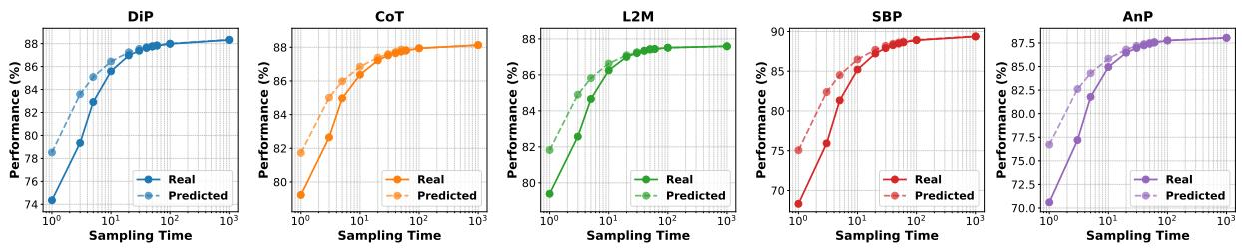
This probabilistic view motivates a prediction module. Instead of evaluating a strategy with very large N, the system estimates the answer probabilities {pi,1,pi,2,…,pi,m} from a small number of samples and predicts large N performance. By the central limit theorem, for sufficiently large N, the occurrence count of the correct answer can be approximated as
x1∼N(Np1,Np1(1−p1)).The maximum occurrence count among incorrect answers is denoted
M=max(x2,…,xm).When N is large, the distribution of M is approximated by
M∼N(Npmax,Npmax(1−pmax)),where pmax is the highest incorrect answer probability. The probability that the correct answer wins the majority vote is approximated by comparing two normal variables. Defining
Z=x1−M,the distribution of Z is
Z∼N(N(p1−pmax),N[p1(1−p1)+pmax(1−pmax)]).Therefore,
Pr(a∗=a1)≈Pr(Z>0).Using the standard normal cumulative distribution function Φ, the predicted scaling performance is
Pr(a1∣Pi;N)≈1−Φ−Np1(1−p1)+pmax(1−pmax)p1−pmax.The dataset level predicted accuracy for a prompting strategy is then
Accuracy(Pi,N)=Ex∈DPr(a1∣Pi;N),and the predicted optimal strategy under sampling time N is
PN∗=PiargmaxAccuracy(Pi,N).This provides an inexpensive scaling law for majority voting. The predicted and realized scaling behavior of different prompting strategies is shown in the figure below.
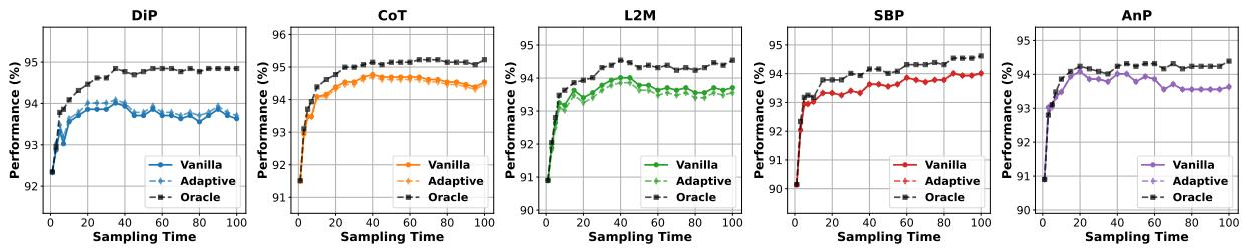
The method also introduces an adaptive scaling module that uses the difficulty analysis. If the system estimates that a question is hard for the current prompting strategy, it stops increasing the sampling count and returns a single answer, because additional majority voting can worsen performance. If the question is estimated to be easy or moderate, the system applies the usual scaling procedure. Two sources of difficulty information are considered. In the self adaptive variant, the language model itself determines whether the question is hard. In the oracle variant, the difficulty label is provided externally as an upper bound reference. The two strategies are used to decide whether a question receives normal scaling or single sample answering.
The adaptive behavior for non iterative prompting strategies is compared against standard fixed scaling in the figure below.
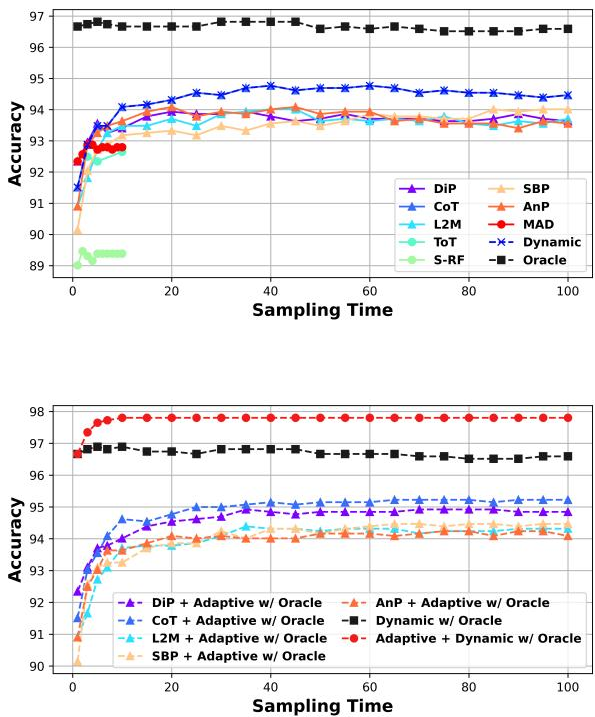
A second improvement module treats prompt selection as a per question decision. A question may be hard for a strategy that is otherwise accurate, while the same question may be easy for another strategy with lower average accuracy. The system can therefore choose the optimal prompting strategy Pi for each individual input. In the oracle setting, the best strategy for each question is provided directly, yielding an upper bound. In the dynamic setting, the model is asked to select the most suitable strategy itself. The design can be further combined with adaptive scaling by first choosing the best prompt for each question and then deciding whether to scale or answer once based on estimated difficulty.
Experiment
Experiments evaluate several open and closed LLMs across multiple reasoning benchmarks by comparing prompting strategies under different sampling-time and inference-cost budgets. The main qualitative finding is that simple chain-of-thought generally becomes the strongest option under large test-time scaling, because it contains more easy questions and produces answer distributions that are less disturbed by wrong answers. Additional analysis validates a low-cost method for predicting scaling behavior and shows that difficulty-aware sampling and per-question strategy selection can further improve performance when guided by strong oracles.
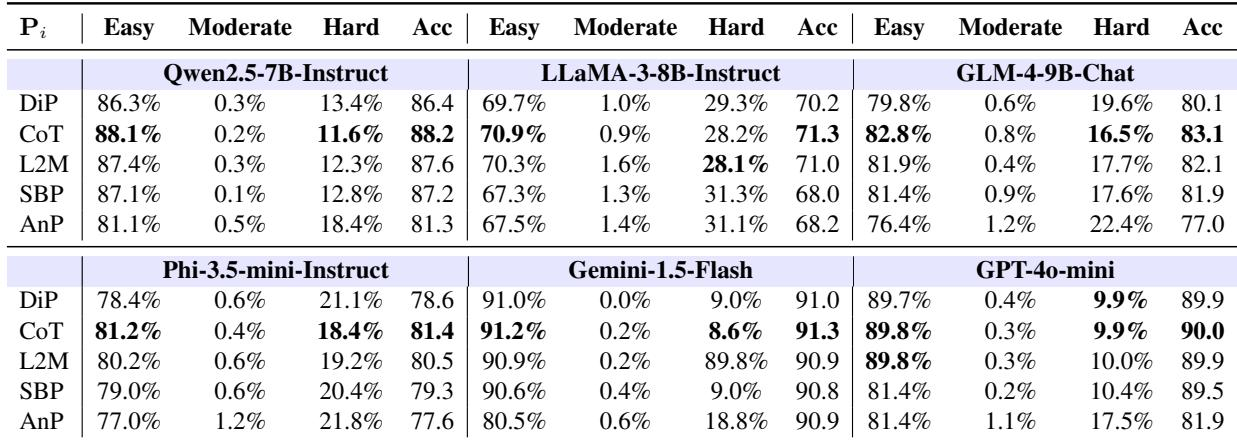
The table compares prompting strategies by the share of easy, moderate, and hard questions and by their limiting accuracy across several language models. CoT generally has the largest share of easy questions and the smallest share of hard questions, which aligns with its strongest limiting accuracy. Strategies with relatively more hard questions, such as AnP, tend to show weaker limiting accuracy. CoT shifts the question mix toward easier items and away from hard items across the reported models. CoT reaches the highest limiting accuracy among the compared prompting strategies. Prompting strategies with higher hard-question proportions tend to have lower limiting accuracy.
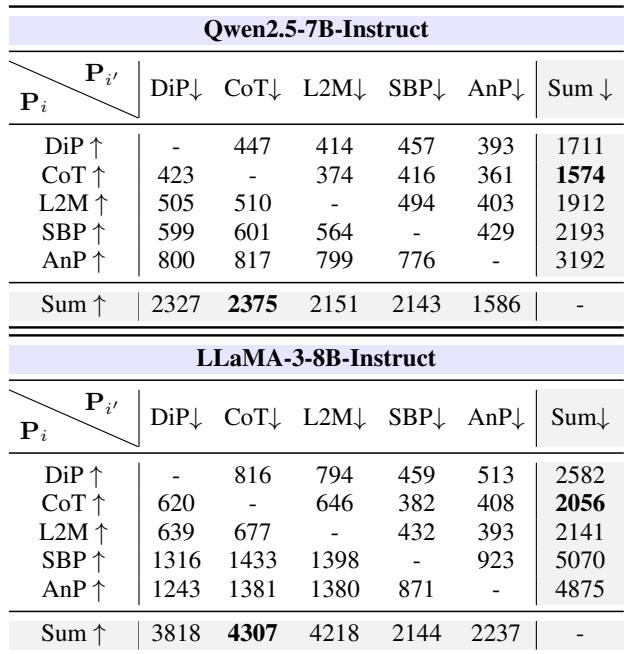
The table counts how often one prompting strategy starts with higher accuracy than another but can be overtaken after scaling. In the shown Qwen2.5-7B-Instruct results, CoT is the strategy that most often overtakes other methods and is the least often overtaken itself. This pattern supports the conclusion that CoT has stronger scaling potential than the other tested prompting strategies. CoT has the highest total as the strategy that can gain after scaling against another method. CoT has the lowest total as the strategy that starts ahead but later loses. AnP shows the most cases of beginning ahead while still being overtaken after scaling.
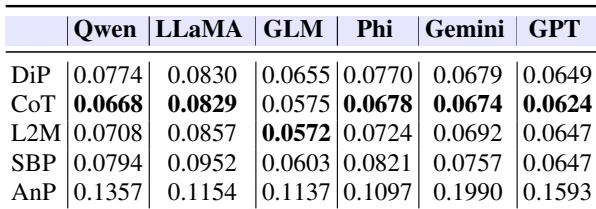
The table compares how uniformly prompting strategies assign probability across incorrect answers, with lower values indicating a flatter erroneous answer distribution. CoT generally produces the most uniform wrong-answer distributions across models, while strategies with stronger guidance tend to concentrate probability on fewer incorrect answers. L2M is the main exception, reaching slightly lower divergence on GLM, but CoT is nearly as uniform there. CoT shows the most uniform wrong-answer distribution on most tested models. AnP has the least uniform wrong-answer probabilities across all tested models. More guided prompting strategies tend to produce more concentrated incorrect-answer distributions than CoT.
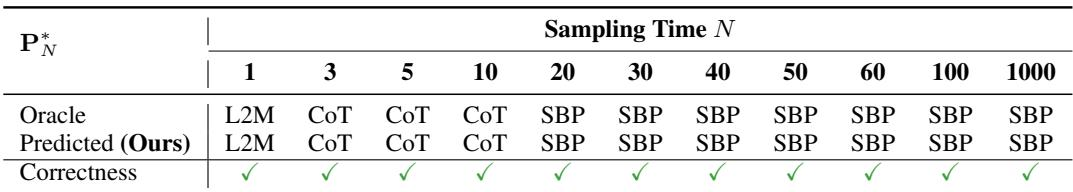
The table compares the true best prompting strategy with the method's predicted strategy across increasing sampling time limits. The prediction matches the true best strategy at every evaluated limit, supporting the use of lower-cost evaluations to anticipate optimal test-time scaling behavior. The true best strategy shifts from L2M at the smallest limit to CoT at short limits and then to SBP at larger limits. The predicted strategy remains correct across all tested sampling time limits, indicating stable prediction under resource constraints. The result supports using smaller sampling budgets to infer the best strategy for much larger sampling budgets.
The experiments compare prompting strategies across several language models by their question-difficulty distributions, limiting accuracy, scaling dynamics, wrong-answer concentration, and budget-constrained strategy selection. CoT consistently shows stronger scaling behavior, often producing easier question mixes, higher limiting accuracy, and more uniform incorrect-answer distributions than more directive strategies such as AnP. Strategy rankings also vary with sampling budget, with low-cost evaluations correctly predicting the best higher-budget strategy. These results suggest that prompting methods can be distinguished by scaling behavior and error patterns, and that inexpensive evaluations can help identify effective test-time scaling strategies.