Command Palette
Search for a command to run...
MMToM-QA : Réponse aux questions sur la théorie de l'esprit multimodale
MMToM-QA : Réponse aux questions sur la théorie de l'esprit multimodale
Chuanyang Jin Yutong Wu Jing Cao Jiannan Xiang Yen-Ling Kuo Zhiting Hu Tomer D. Ullman Antonio Torralba Joshua B. Tenenbaum Tianmin Shu
Résumé
La théorie de l'esprit (ToM), c'est-à-dire la capacité de comprendre les états mentaux d'autrui, est un ingrédient essentiel pour développer des machines dotées d'une intelligence sociale comparable à celle des humains. Les modèles d'apprentissage automatique récents, en particulier les grands modèles de langage, semblent manifester certains aspects de la compréhension de la ToM. Toutefois, les benchmarks existants pour la ToM reposent sur des jeux de données unimodaux – vidéo ou texte. Or, la ToM humaine dépasse la simple compréhension de la vidéo ou du texte. Les personnes peuvent raisonner de manière flexible sur l'esprit d'autrui à partir de représentations conceptuelles (p. ex. objectifs, croyances, plans) extraites de toute donnée disponible. Pour remédier à cette limitation, nous introduisons MMToM-QA, un benchmark de réponse aux questions portant sur la théorie de l'esprit multimodale. MMToM-QA évalue de manière exhaustive la ToM artificielle aussi bien sur des données multimodales que sur différents types de données unimodales relatives à l'activité d'une personne dans un environnement domestique. Pour construire une capacité de ToM multimodale, nous proposons une nouvelle méthode, BIP-ALM (Bayesian Inverse Planning Accelerated by Language Models). BIP-ALM extrait des représentations unifiées à partir de données multimodales et utilise les modèles de langage pour une planification bayésienne inverse évolutive. Nous avons mené une comparaison systématique des performances humaines, de BIP-ALM et des modèles de l'état de l'art, dont GPT-4. Les expériences démontrent que les grands modèles de langage et les grands modèles multimodaux manquent encore d'une capacité robuste de ToM. BIP-ALM, en revanche, obtient des résultats prometteurs en tirant parti conjointement de l'inférence mentale fondée sur des modèles et des modèles de langage.
One-sentence Summary
New York University, Harvard University, MIT, and others introduce MMToM-QA, a multimodal Theory of Mind question-answering benchmark evaluating machines on both multimodal and unimodal data from household environments, along with BIP-ALM, a method that extracts unified representations from multimodal data and leverages language models for scalable Bayesian inverse planning, showing that while large language and multimodal models still lack robust ToM capacity, BIP-ALM achieves promising results by combining model-based mental inference with language models.
Key Contributions
- The paper introduces MMToM-QA, a multimodal Theory of Mind question answering benchmark for household activities that evaluates reasoning about a person's goals and beliefs from video, text, and combined multimodal inputs, with human experiments providing a baseline.
- The paper proposes BIP-ALM, a method that extracts symbolic representations from multimodal data and extends Bayesian inverse planning with a language model finetuned on human activity data to evaluate hypotheses about a person's beliefs and goals.
- The paper systematically compares human performance, BIP-ALM, and state-of-the-art models including GPT-4(V), showing that existing large language and multimodal models make systematic Theory of Mind errors while BIP-ALM significantly outperforms them.
Introduction
Theory of Mind lets systems infer people’s goals, beliefs, and desires from their behavior, supporting safer and more effective human-facing AI such as assistive robots, AI teachers, and autonomous vehicles. The authors note that most prior Theory of Mind benchmarks use only text or video, which limits whether models are tested on the kind of causal, multimodal mental reasoning that humans use. They also argue that reliance on large training data may encourage pattern matching rather than genuinely humanlike reasoning. To address this, the authors introduce MMToM-QA, a multimodal Theory of Mind benchmark combining video, text, and questions about goals and beliefs. They also propose BIP-ALM, which combines Bayesian inverse planning with language models to perform efficient, interpretable, multimodal mental state reasoning.
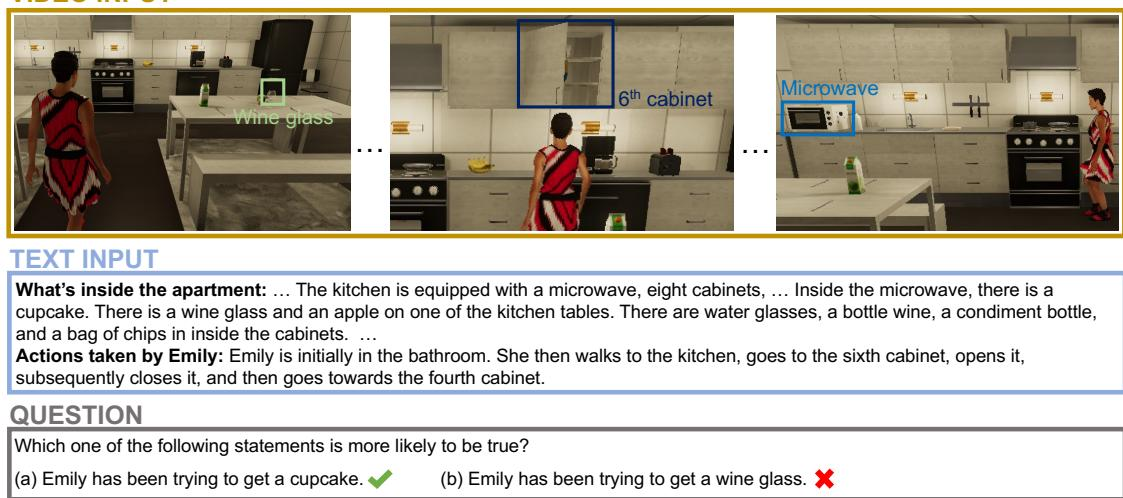
Dataset
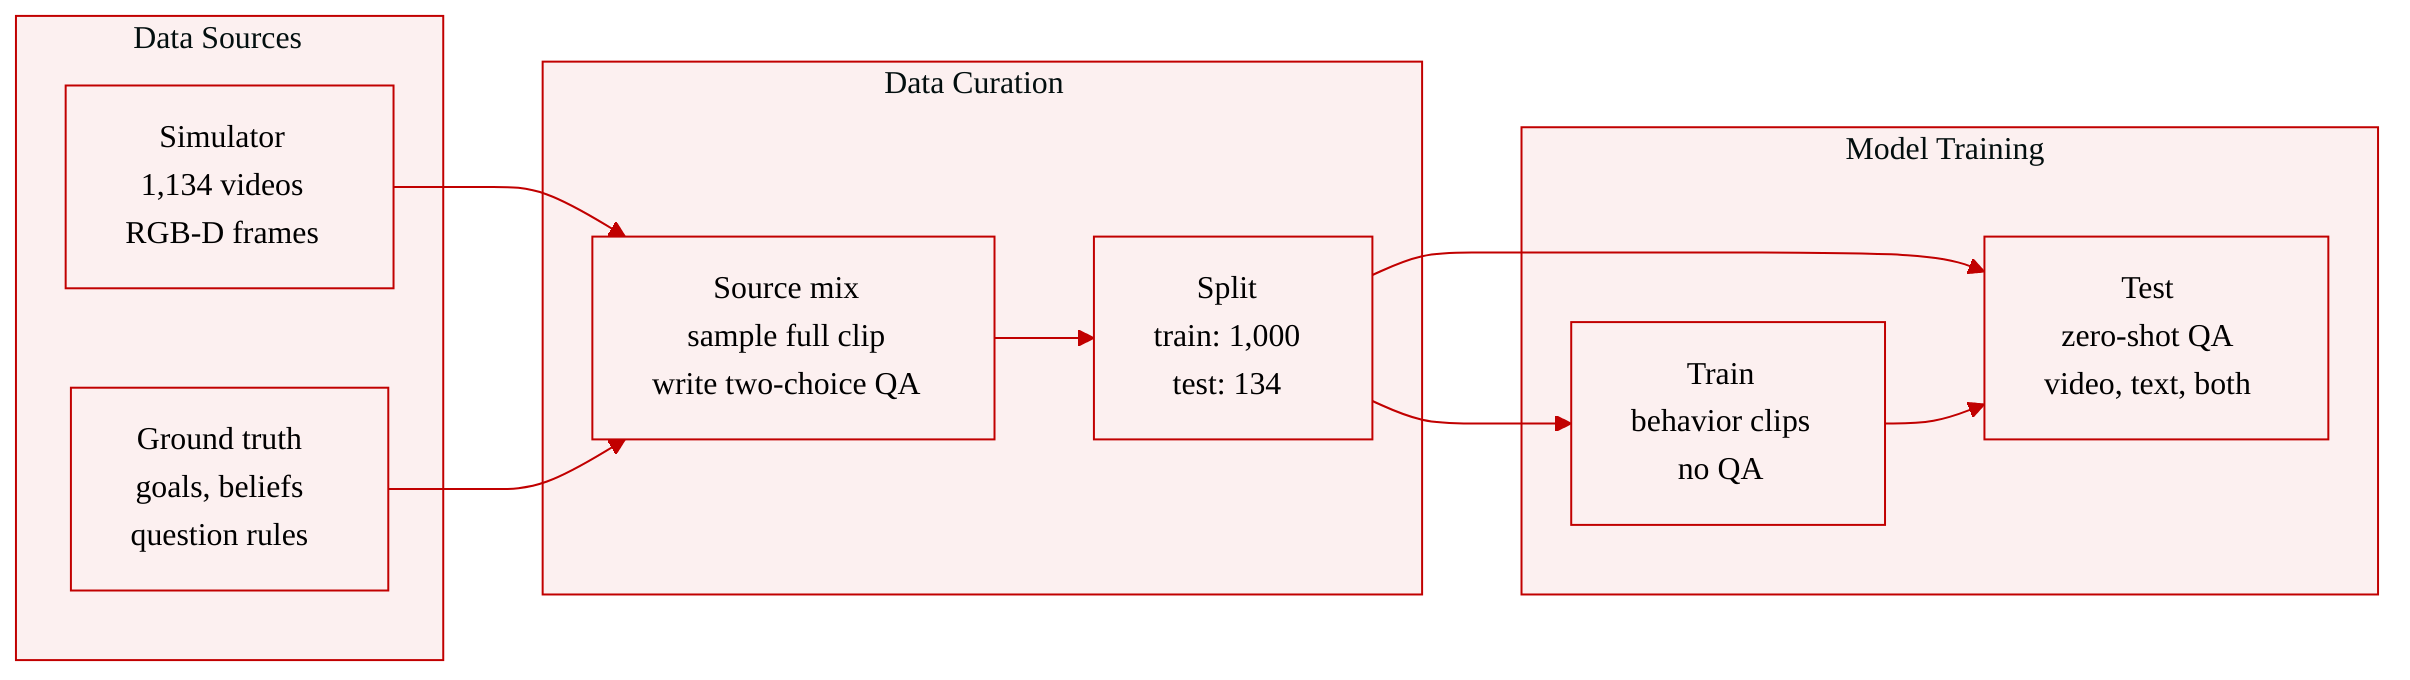
-
The authors build the MMToM-QA benchmark from simulated household videos. The benchmark contains 134 videos of a person searching for daily objects in household environments. On average, each video has 1,462 frames and depicts 36 human actions.
-
The benchmark includes 600 two-choice questions about a person’s goals and beliefs. Each question is paired with a clip of the full activity in the video, provided as RGB-D frames, and with a text description of the scene and the actions taken by the person.
-
The questions are divided into seven question types. The three belief inference types each contain 100 questions, for 300 belief questions in total. The four goal inference types each contain 75 questions, for 300 goal questions in total.
-
The question types cover true belief, false belief, long-term belief tracking, goal inference under true belief, goal inference under false belief, goal inference under updated belief, and goal inference that requires reasoning about possible future actions and spatial relations.
-
The videos and questions are produced with a procedural generation pipeline in the VirtualHome-Social embodied household simulator. This simulator generates human-like activities and provides ground-truth annotations for scene, objects, actions, goals, and beliefs.
-
For each question, the authors sample a question type and two opposing hypotheses according to the definition of that type. The text description and question are then generated from the ground-truth state, actions, and sampled hypotheses using GPT-4.
-
The data are not cropped to a local temporal window. The evaluation clip covers the full activity in the corresponding video, while the accompanying text describes the scene and the person’s observed actions.
-
For training, the authors use a separate synthetic human behavior dataset with 1,000 procedurally generated household videos. These training videos include ground-truth annotations of the scene, objects, goals, and beliefs.
-
The authors use the training set so that models learn how people update beliefs and goals while acting in a physical environment. They do not provide example QA pairs during training.
-
The benchmark is used for zero-shot evaluation in three settings: multimodal QA with both video and text, text-only QA, and video-only QA. No explicit additional filtering or cropping strategy is described beyond the procedural generation rules, predefined question types, and full-activity clips.
Method
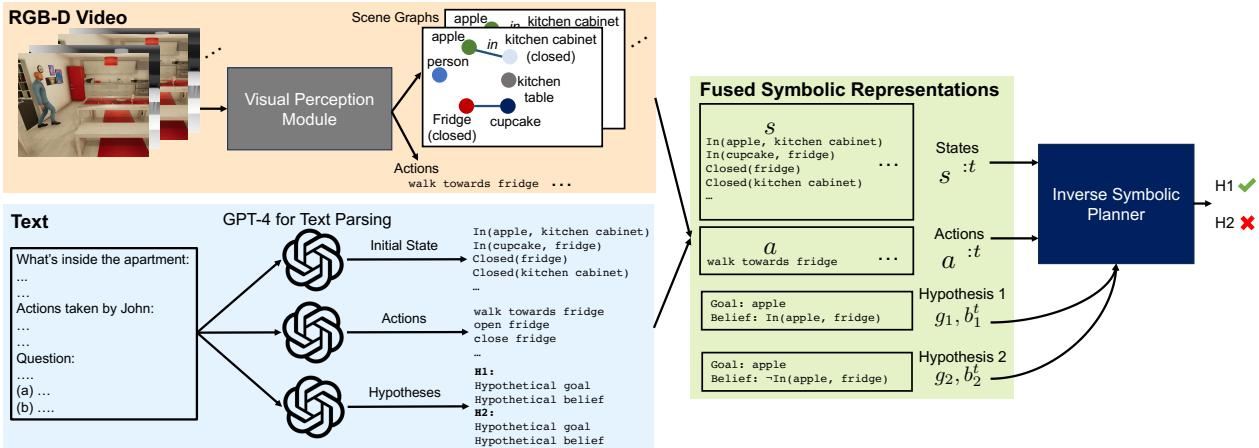
The authors build the model around a multimodal inverse planning pipeline. Instead of directly mapping video and text to mental state labels, they first convert both modalities into shared symbolic representations, then use a planner to evaluate competing explanations of a person’s goal and belief. The overall architecture, including visual perception, text parsing, symbolic fusion, and inverse symbolic planning, is shown in the figure below:
Before the model operates on real test data, the benchmark and training examples are created through procedural generation. The authors synthesize household activity videos in an embodied simulator, where each activity is associated with ground truth states, actions, goals, and beliefs. At each video step, they sample a question type and two opposing hypotheses. A language model then converts the ground truth state sequence, action sequence, and sampled hypotheses into natural language descriptions and question-answer items. The same procedural pipeline is reused to produce training data, giving the model supervisory signals for symbolic state tracking, action prediction, belief representation, and mental state comparison.
For a given inference instance, BIP-ALM has four main modules. The visual perception module processes an RGB-D video frame by frame. It constructs a voxel map of the scene and extracts a scene graph that captures entities, object states, and spatial relations. From the scene graph, the model derives symbolic predicates, such as the location of an object or whether a container is closed, and it also extracts high-level action indicators, such as a person walking toward a particular area.
The text parsing module handles the accompanying language input. A large language model is prompted to separate the text into three parts: the initial environment description, the person’s action sequence, and the question. The environment description is converted into predicates that encode object locations and container states. The action sequence is converted into discrete action commands. The question is transformed into two competing hypotheses about the person’s mental state. Each hypothesis contains a goal object and a belief predicate, which may be positive or negative. For example, one hypothesis may state that the person believes an object is inside a location, while the other states that the person does not believe the object is there.
The fusion module aligns these modality-specific symbolic outputs into a unified state and action history. The scene graphs from the video are translated into predicates that are compatible with the text-derived predicates. The initial symbolic state is formed by merging predicates extracted from the video and from the text. The model then aligns textual actions with video-detected actions and partitions the video into intervals, where each interval corresponds to one action and defines a time step. Starting from the initial state, the state predicates are updated step by step using the video frame associated with the current action interval. This produces a symbolic state sequence s1:t and a symbolic action sequence a1:t. At the same time, the two parsed mental-state hypotheses are prepared as candidate goal-belief pairs.
The inverse symbolic planner compares these two hypotheses under a generative model of rational action. The authors model the person as a partially observable agent whose behavior is generated by a POMDP defined by the tuple S,A,T,G,R,Ω,O,γ. Here, st∈S is the true state at time t, at∈A is the action, T(st∣s,a) is the state transition model, g∈G is a goal, rt=R(st,at,g) is the reward induced by the goal, ot∈Ω is the observation, ot=O(st) maps states to observations, and γ∈(0,1] is a discount factor. The agent’s belief b(s) is a probability distribution over states. In this work, belief is factorized across objects, so the model maintains beliefs about the possible locations of individual goal objects.
Under this model, a rational agent chooses actions from the optimal policy π(at∣g,bt) to maximize expected discounted return. The authors therefore define inverse inference as the task of recovering the goal and belief from observed states and actions. With a deterministic transition assumption, the posterior over a goal and belief can be written as
P(g,bt∣s1:t,a1:t−1)∝τ=1∏tπ(aτ∣g,bτ)P(bτ∣bτ−1,sτ)P(b0)P(g).Given two hypotheses H1=⟨g1,b1t⟩ and H2=⟨g2,b2t⟩, the planner evaluates which hypothesis better explains the observed history through the ratio
P(g2,b2t∣s1:t,a1:t)P(g1,b1t∣s1:t,a1:t)=π(at∣g2,b2t)P(b2t∣b^t−1,st)π(at∣g1,b1t)P(b1t∣b^t−1,st)⋅∏τ=1t−1π(aτ∣g2,b^τ)∏τ=1t−1π(aτ∣g1,b^τ).The hypothesis with the higher relative likelihood is selected as the answer. The term b^τ denotes the estimated belief at an earlier step. Because the question specifies a belief about the current step, the model estimates past beliefs by propagating the agent’s observations through time. The initial belief is initialized as uniform, and the observation at each step is represented by the subset of state predicates visible to the agent. These observations are then used to update the estimated belief sequence.
The computational bottleneck in this formulation is the policy likelihood π(at∣g,bt). Rather than learning a conventional planner through explicit symbolic search or reinforcement learning, the authors amortize the policy using a language model. The state, goal, and estimated belief at a step are rendered into a symbolic prompt. The belief is expressed as a list of possible locations for the goal object. The language model receives the current symbolic state, the hypothesized goal, and the hypothesized belief, then generates a score or probability distribution over the observed action based on its output logits. During training, the language model is finetuned on procedural data containing ground truth state sequences, belief sequences, goal sequences, and action sequences, so that it learns to approximate action likelihoods from symbolic context.
Experiment
The experiments evaluate the MMToM-QA benchmark in multimodal, text-only, and video-only zero-shot settings to test belief and goal reasoning from household videos. Human participants perform strongly, confirming question validity, while generic language and multimodal models remain near chance and mainly succeed on simple true-belief retrieval but fail to track false beliefs, belief updates, and future-oriented goal inference. The BIP-ALM approach surpasses these baselines by using model-based inference over possible actions and mental states, and it generalizes to real human behavior and unseen environments, though it still struggles with missing visual state and continuous spatial reasoning.
In multimodal evaluations, human participants performed very strongly across belief and goal inference, while baseline models were generally near chance, with GPT-4V and SymbolicToM with GPT-4 showing some selective strength. GPT-4V performed well on true belief questions and some related belief tasks, but struggled with false belief and goal inference, especially harder cases where the agent's updated belief or unseen goal must be inferred. BIP-ALM with GPT-J outperformed these baselines by a large margin across both belief and goal inference, supporting the benefit of model-based reasoning over direct multimodal prediction. Humans were strongest on multimodal ToM inference and validated the question design. Most baselines performed close to chance across belief and goal inference types. GPT-4V showed selective success on true belief reasoning but had systematic weaknesses in false belief and goal inference. BIP-ALM achieved markedly higher accuracy than baseline methods in both belief and goal inference.
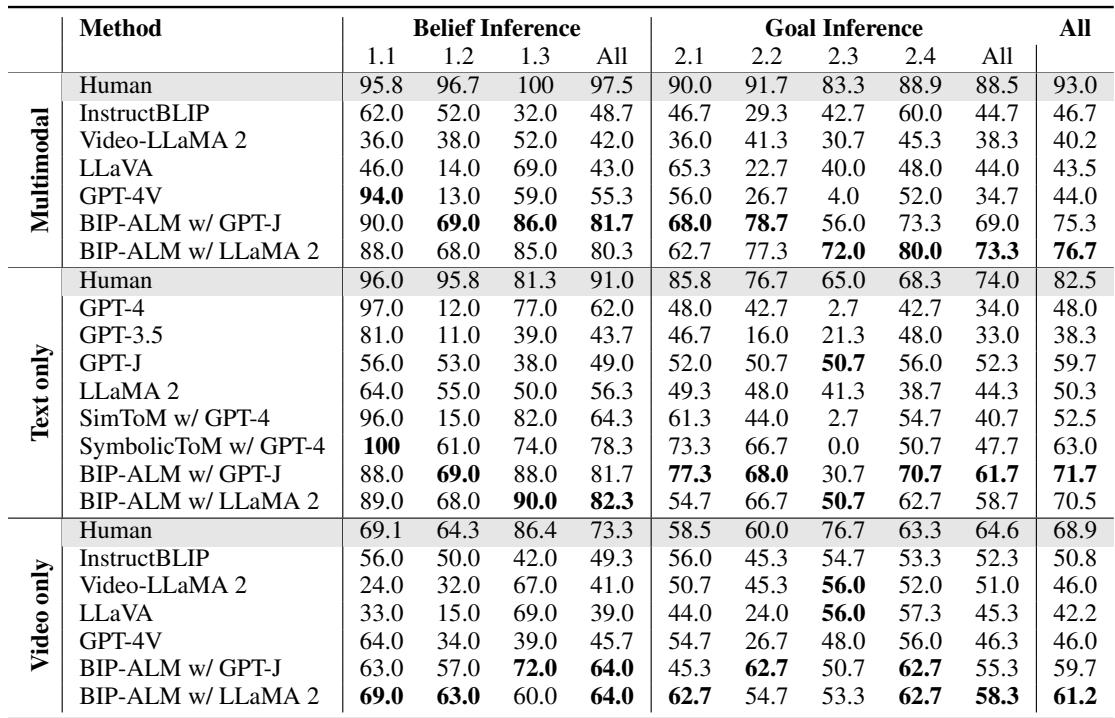
In multimodal evaluations, human participants inferred beliefs and goals effectively, supporting the validity of the task design. Most baseline models performed near chance, while GPT-4V showed only selective strength on true belief reasoning and struggled with false belief and goal inference. BIP-ALM substantially outperformed these baselines across both belief and goal tasks, highlighting the advantage of model-based reasoning over direct multimodal prediction.