Command Palette
Search for a command to run...
Modèles de langue à la mission impossible
Modèles de langue à la mission impossible
Julie Kallini Isabel Papadimitriou Richard Futrell Kyle Mahowald Christopher Potts
Résumé
Chomsky et d'autres ont affirmé de manière très directe que les grands modèles de langue (LLM) sont tout aussi capables d'apprendre les langues possibles et impossibles pour l'humain. Cependant, très peu de preuves expérimentales publiées viennent étayer une telle affirmation. Nous développons ici un ensemble de langues impossibles synthétiques de complexités variables, chacune conçue en modifiant systématiquement des données anglaises par des ordres de mots et des règles grammaticales non naturels. Ces langues s'inscrivent sur un continuum d'impossibilité : d'un côté se trouvent des langues intrinsèquement impossibles, telles que des permutations aléatoires et irréversibles de mots anglais, et de l'autre, des langues qui ne sont peut-être pas intuitivement impossibles mais sont souvent considérées comme telles en linguistique, notamment celles dont les règles reposent sur le comptage des positions des mots. Nous rapportons un large éventail d'évaluations destinées à mesurer la capacité des modèles GPT-2 de petite taille à apprendre ces langues incontestablement impossibles, et nous effectuons ces évaluations à différents stades de l'entraînement afin de comparer le processus d'apprentissage pour chaque langue. Notre résultat principal est que GPT-2 peine à apprendre les langues impossibles par rapport à l'anglais pris comme condition de contrôle, ce qui met en question l'affirmation centrale. Plus important encore, nous espérons que notre approche ouvre une voie de recherche productive dans laquelle différentes architectures de LLM sont testées sur une variété de langues impossibles afin de mieux comprendre comment les LLM peuvent être utilisés comme outils pour ces investigations cognitives et typologiques.
One-sentence Summary
Researchers at Stanford University, UC Irvine, and UT Austin create synthetic impossible languages with systematically altered word orders and grammar rules to test whether GPT-2 learns them as readily as English, finding that it struggles with these languages and thereby challenging claims that LLMs are equally capable of learning human-possible and impossible languages, while proposing this framework as a tool for cognitive and typological linguistic investigation.
Key Contributions
- A controlled set of synthetic impossible languages is constructed by transforming English data with unnatural word orders and grammar rules, spanning random or irreversible word shuffles to position-counting rule systems.
- An experimental framework evaluates GPT-2 small models on these languages against natural English, comparing performance across multiple checkpoints during training.
- Results show that GPT-2 learns the impossible languages less effectively than English, challenging the claim that LLMs learn possible and impossible languages equally and supporting LLMs as tools for studying linguistic learnability.
Introduction
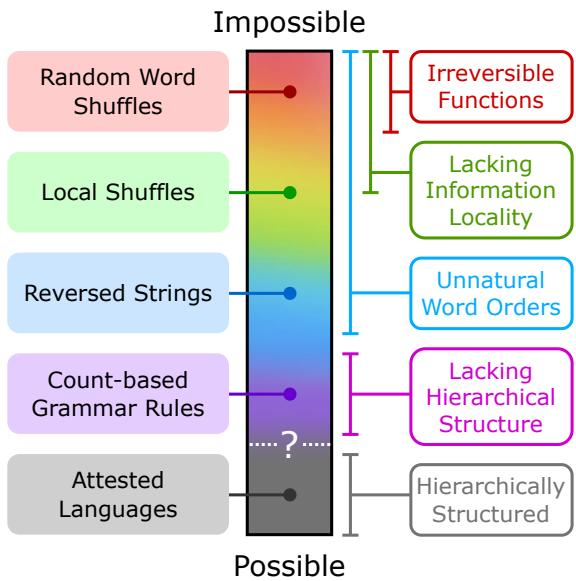
Large language models are increasingly used as experimental tools for linguistic theory, but some researchers argue that they cannot distinguish human-possible languages from impossible ones. If true, this would weaken the case that LLMs can inform models of human language learning.
The main challenge is that linguists do not share a precise definition of possible versus impossible languages, and prior evidence for this strong claim was limited, especially for modern LLMs.
The authors address this by creating a suite of synthetic impossible languages with varying intuitive complexity and testing GPT-2 models trained on BabyLM data. They find that the models learn natural languages more efficiently, react more strongly to unnatural count-based grammar patterns, and use modular internal representations that do not fully capture these impossible rules. This evidence challenges the claim that LLMs are equally good at learning possible and impossible languages, while also showing that model architecture and tokenization choices shape their linguistic preferences.
Dataset
-
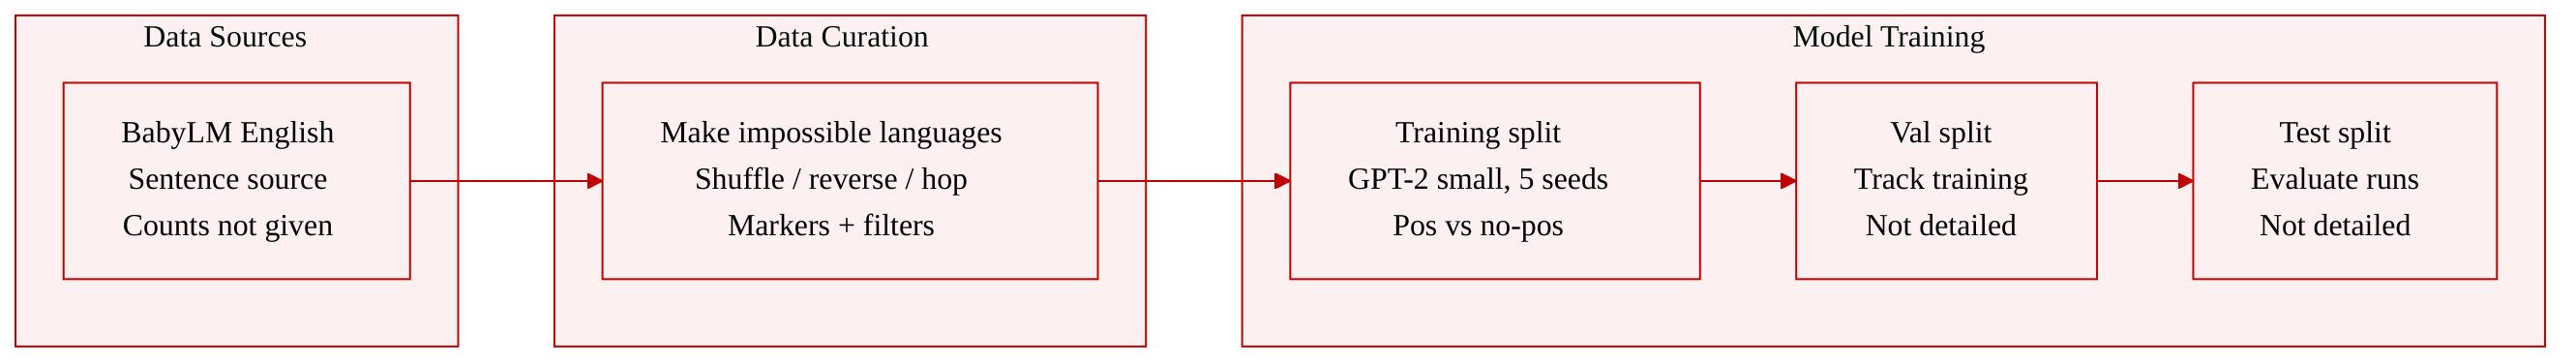
The authors use BabyLM English sentences as the source data and synthesize impossible language datasets by applying deterministic or random perturbation functions to each sentence.
-
The dataset is organized into three language families: SHUFFLE, REVERSE, and HOP. Each family includes a control language that is close to normal English and several perturbed languages that vary in locality, reversibility, and grammatical rule counting.
-
SHUFFLE languages operate on tokenized sentences:
- NOSHUFFLE keeps the original token order and serves as an English control.
- NONDETERMINISTICSHUFFLE randomly shuffles tokens independently for each sentence, destroying order information.
- DETERMINISTICS HUFFLE uses a fixed shuffle pattern based on token sequence length and a chosen random seed.
- LOCALSHUFFLE shuffles tokens only within fixed-length local windows.
- EVENODDSHUFFLE places all even-indexed tokens before all odd-indexed tokens.
-
REVERSE languages insert a special marker token and reverse all or part of the sentence:
- NOREVERSE inserts a marker at a fixed position across the dataset and keeps token order unchanged.
- PARTIAL REVERSE inserts a marker and reverses tokens after the marker.
- FULL REVERSE inserts a marker and reverses the entire token sequence.
- Marker positions are controlled across languages to isolate the effect of reversal rather than marker randomness.
-
HOP languages modify verb agreement information to test counting-based grammar rules:
- NOHOP lemmatizes third-person present tense verbs and places a singular or plural marker immediately after the verb.
- TOKENHOP places the same marker four tokens after the verb.
- WORDHOP places the marker four words after the verb, skipping punctuation.
- The markers use special tokens to encode number and tense information.
-
The provided text does not give exact sentence or token counts for the BabyLM dataset.
-
The authors apply each perturbation function to every BabyLM sentence to create a transformed dataset for that impossible language.
-
The data schema is primarily a token sequence produced from English input, with additional special marker tokens used in REVERSE and HOP languages.
-
Language-specific filtering and preprocessing are used to enforce each language definition, though the precise filtering rules are not detailed in the provided excerpt.
-
The authors use the resulting datasets to train GPT-2 small models on causal language modeling, producing five model runs per language using different random seeds.
-
The main experiments use GPT-2 small models with absolute positional encodings, and the authors also train models with positional encodings removed to compare how word order is learned from the language modeling objective alone.
Method
The method introduces the *HOP languages as controlled perturbations of English text to test whether GPT‑2 can learn grammar rules that depend on positional counting. The transformation pipeline focuses on third-person present-tense verbs, replacing their surface inflection with a lemmatized verb and an explicit grammatical marker that encodes number. The model is then evaluated on how well it can predict or process this controlled representation.
For each input sentence, the pipeline first identifies all third-person present-tense verbs. Each identified verb is lemmatized, and a special marker is inserted to represent the verb’s number. Singular verbs receive a special token, for example S, and plural verbs receive another special token, for example P. This design removes normal English inflectional cues and replaces them with artificial markers whose placement depends on the chosen *HOP rule.
The three variants differ only in where the marker is placed relative to the verb.
-
NoHOP places the marker immediately after the lemmatized verb in token space. If the verb occupies token position t, the marker is inserted at position t+1. This version most closely resembles English word order, since the number cue remains directly adjacent to the verb.
-
TOKENHOP applies the same verb lemmatization and marker assignment as NoHOP, but the marker is placed four tokens after the verb. In this case, the marker is associated with the verb even though intervening words, spaces, punctuation, or subword fragments may separate them. This forces the model to rely on token-distance counting rather than local adjacency.
-
WORDHOP also uses the same transformation of verbs and markers, but places the marker four words after the verb while skipping punctuation. Here, the counting unit is linguistic words rather than model tokens. Punctuation is ignored when measuring distance, so the marker’s placement depends on a word-level count that may not align with the tokenizer’s token boundaries.
As a compact formulation, for a verb v and its number marker mv∈{S,P}, NoHOP inserts mv at pos(v)+1, TOKENHOP inserts mv at postoken(v)+4, and WORDHOP inserts mv at the position following four intervening words after v, with punctuation excluded from the count.
The purpose of this module is to create a family of grammars in which syntactic agreement is encoded through variable offsets. NoHOP tests whether a marker adjacent to a verb can be learned as a conventional local dependency. TOKENHOP tests whether GPT‑2 can learn fixed token-counting rules, where the distance between verb and marker is defined in the tokenizer’s space. WORDHOP tests whether the model can learn word-counting rules that operate at a level coarser than tokens and ignore punctuation. Together, these languages probe whether a transformer language model can represent grammatical rules that require counting positions across separated elements.
Experiment
GPT-2 models were trained on synthetic impossible language variants of BabyLM and evaluated through perplexity, surprisal-based verb-marker tests, and causal interventions to examine how well they learn unnatural grammars compared with natural controls. Across the experiments, models learned possible language patterns more easily and reliably than impossible ones, with natural verb-marking rules and more local or deterministic perturbations producing clearer learning signals. Probing the models’ internal mechanisms showed that they can form functional agreement representations even for unnatural count-based rules, but do so less robustly and more slowly than for natural grammar, indicating a bias toward informationally local, natural linguistic structure.
The examples contrast English-like control outputs with synthetic variants that reorder or scramble tokens, illustrating an impossibility continuum from familiar patterns to more complex artificial sequences. In the GPT-2 experiments, models trained on these languages diverge in perplexity, with nondeterministic shuffling producing the highest perplexity and deterministic shuffling yielding more learnable patterns. English-like control languages preserve recognizable word order and token patterns. Deterministic shuffle languages remain more learnable than nondeterministic shuffle languages because their token rearrangements follow consistent rules.
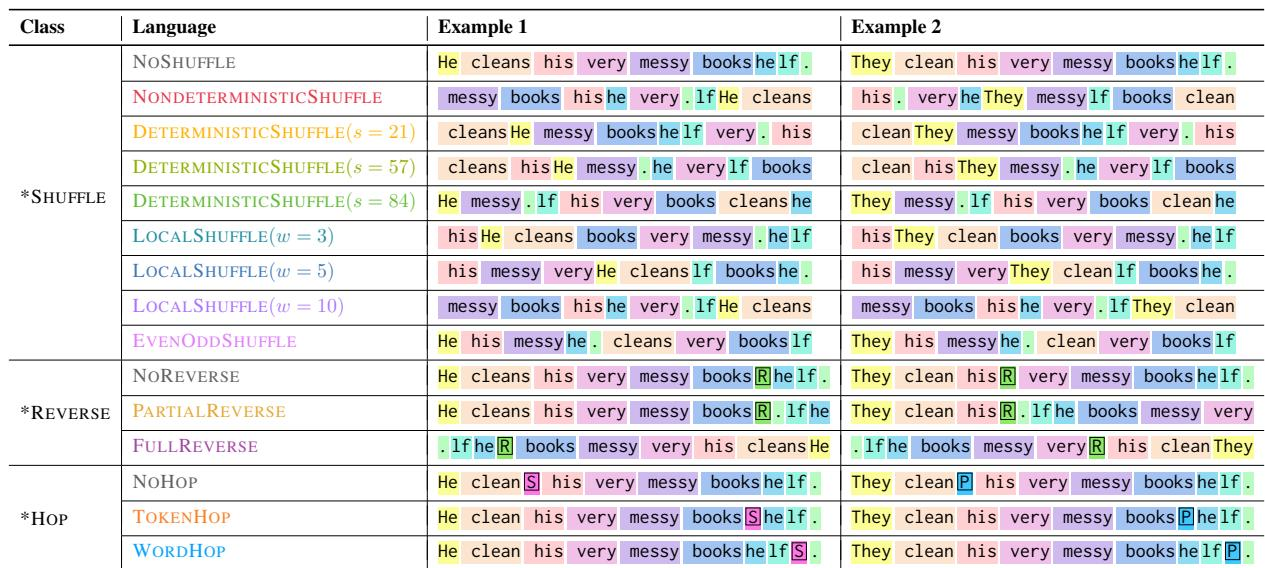
Experiments evaluate GPT-2 models trained on English-like languages and synthetic variants that impose controlled token reorderings, ranging from recognizable patterns to scrambled sequences. The results show that familiar English-like order is most learnable, deterministic shuffling remains learnable when rules are stable, and nondeterministic shuffling is hardest because its patterns are inconsistent. This supports the view that syntactic consistency and predictable token relationships shape model difficulty.