Command Palette
Search for a command to run...
ReconVLA : un modèle Vision-Langage-Action à reconstruction comme percepteur robotique efficace
ReconVLA : un modèle Vision-Langage-Action à reconstruction comme percepteur robotique efficace
Wenxuan Song Ziyang Zhou Han Zhao Jiayi Chen Pengxiang Ding Haodong Yan Yuxin Huang Feilong Tang Donglin Wang Haoang Li
Résumé
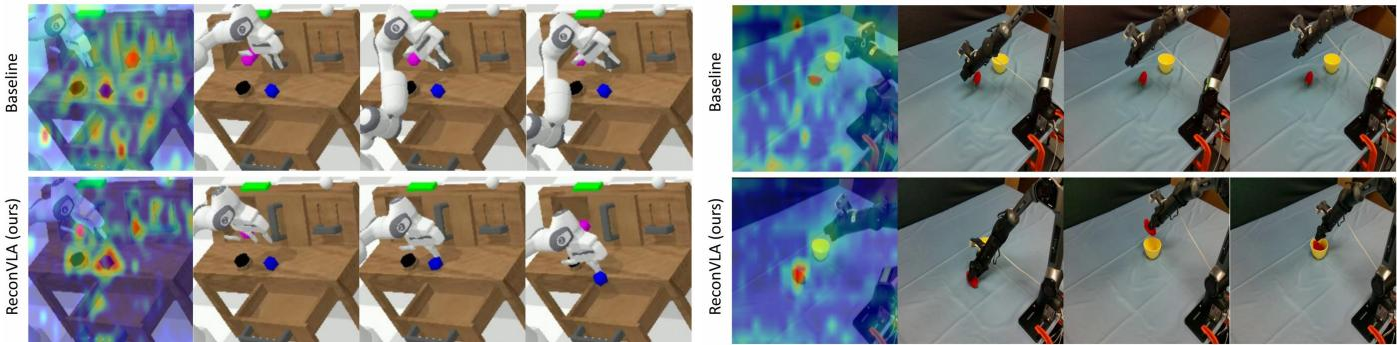
Les avancées récentes dans les modèles Vision-Langage-Action (VLA) ont permis aux agents robotiques d'intégrer la compréhension multimodale à l'exécution d'actions. Toutefois, notre analyse empirique révèle que les VLA actuels peinent à allouer l'attention visuelle aux régions cibles. En effet, l'attention visuelle reste systématiquement dispersée. Afin de guider l'ancrage de l'attention visuelle sur la cible appropriée, nous proposons ReconVLA, un modèle VLA à reconstruction fondé sur un paradigme d'ancrage implicite. Conditionné par les sorties visuelles du modèle, un transformer à diffusion vise à reconstruire la région du regard sur l'image, correspondant aux objets cibles manipulés. Ce processus incite le modèle VLA à apprendre des représentations fines et à allouer précisément l'attention visuelle, exploitant ainsi efficacement l'information visuelle spécifique à la tâche et réalisant une manipulation précise. De plus, nous constituons un grand ensemble de données de préentraînement comprenant plus de 100 000 trajectoires et 2 millions d'échantillons issus de jeux de données robotiques en libre accès, renforçant davantage la capacité de généralisation du modèle en reconstruction visuelle. Des expériences approfondies en simulation et dans le monde réel démontrent la supériorité de notre méthode d'ancrage implicite, mettant en évidence ses capacités de manipulation précise et de généralisation.
One-sentence Summary
HKUST (Guangzhou), Westlake University, Zhejiang University, and Monash University propose ReconVLA, which conditions a diffusion transformer on the VLA model's visual outputs to reconstruct the gaze region corresponding to target manipulated objects, thereby implicitly grounding visual attention and enabling precise robotic manipulation.
Key Contributions
- ReconVLA is a reconstructive Vision-Language-Action framework trained under an implicit grounding paradigm, conditioning a diffusion transformer on its visual outputs to reconstruct the gaze region corresponding to the manipulation target, thereby guiding precise visual attention allocation.
- A large-scale robot pretraining dataset is curated from open-source robotic datasets, containing over 100k trajectories and 2 million data samples, to strengthen visual reconstruction and generalization across scenes and unseen objects.
- Simulation and real-world experiments demonstrate that implicit reconstructive grounding supports accurate visual attention allocation, precise manipulation, and generalization to unseen targets.
Introduction
Vision-language-action models aim to translate multimodal perception into robot actions, making accurate visual grounding essential for precise grasping in cluttered and long-horizon tasks. Prior VLAs often distribute attention across the scene and rely on explicit grounding pipelines, such as inputting grounded images or predicting bounding boxes, which improves region awareness but does not fundamentally teach the policy to allocate attention to the target. The authors introduce ReconVLA, a reconstructive VLA framework that uses a lightweight diffusion transformer to reconstruct target gaze regions from visual outputs, implicitly guiding fine-grained representation learning and sharper attention. To support visual generation and generalization, they curate a large-scale robot pretraining dataset with over 100k trajectories and 2 million samples, enabling stronger manipulation performance in simulation and real-world settings.
Dataset
-
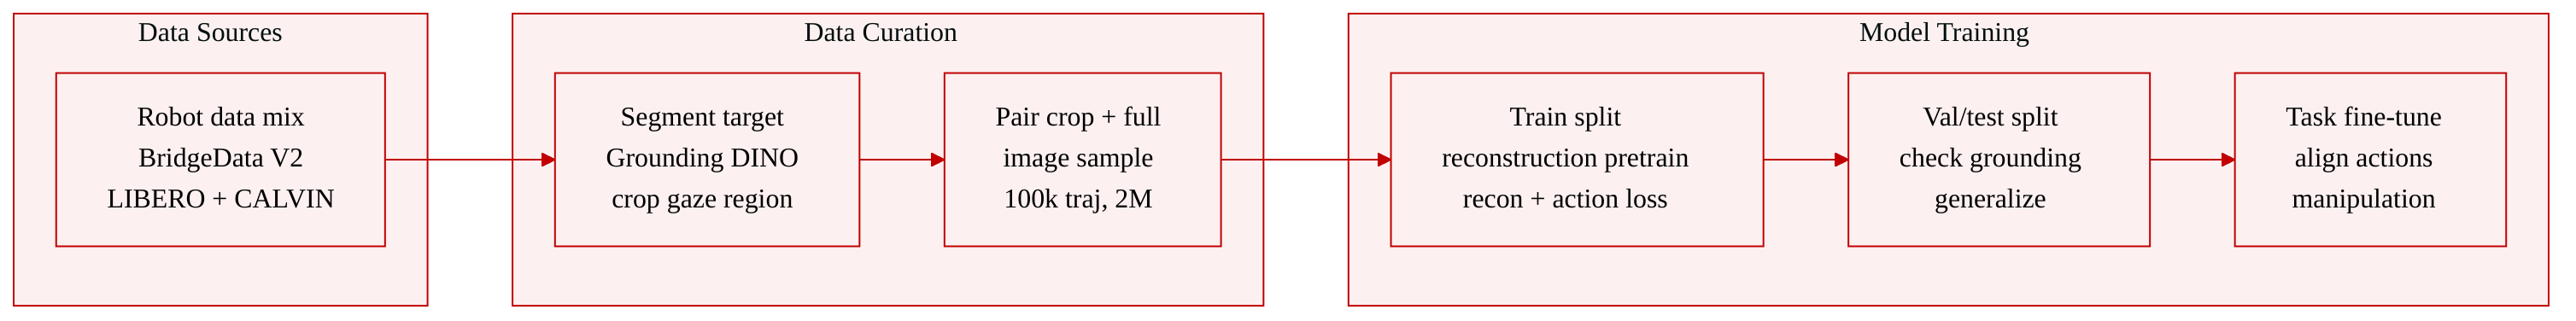
The authors build a visual pretraining dataset from large-scale open-source robot data, BridgeData V2, and simulation datasets, LIBERO and CALVIN.
-
The dataset is organized from image-text pairs, with annotations derived from the region the robot is instructed to interact with.
-
They fine-tune Grounding DINO, an open-vocabulary object detector, to segment and crop the target gaze region for each instruction.
-
Each sample stores the cropped target region and the original full image as a paired example, supporting reconstruction and grounding supervision.
-
The final visual pretraining corpus contains over 100k trajectories and 2 million samples.
-
The authors use this dataset to pretrain the model’s ability to reconstruct instructed visual regions, then fine-tune it on specific tasks for manipulation.
Method
The authors leverage a standard vision language action model as the foundation of their method. Given an observation pair consisting of images I and a text instruction S, the model produces executable robot actions A. A vision encoder E converts images into image tokens hI, while a text tokenizer T converts instructions into text tokens hS. These tokens are processed by a large language model LLM, which generates discrete action tokens a, and an action detokenizer Q maps those tokens into continuous or executable control signals:
A=Q(a)=Q(LLM(hI,hS))=Q(LLM(E(I),T(S))).The action tokens are generated autoregressively:
p(a)=i=1∏NpLLM(ai∣a1∼i−1;hI;hS),where ai is the ith action token and N is the total number of action tokens.
To address dispersed visual attention, the proposed Reconstructive Vision Language Action model adds an auxiliary visual supervision pathway. The core idea is to train the model to focus on the region intended for manipulation, which the authors call the gaze region. This target region acts as a visual anchor, helping the model select the correct object among several potentially actionable candidates and improving fine grained perception for precise control.
Refer to the framework diagram.
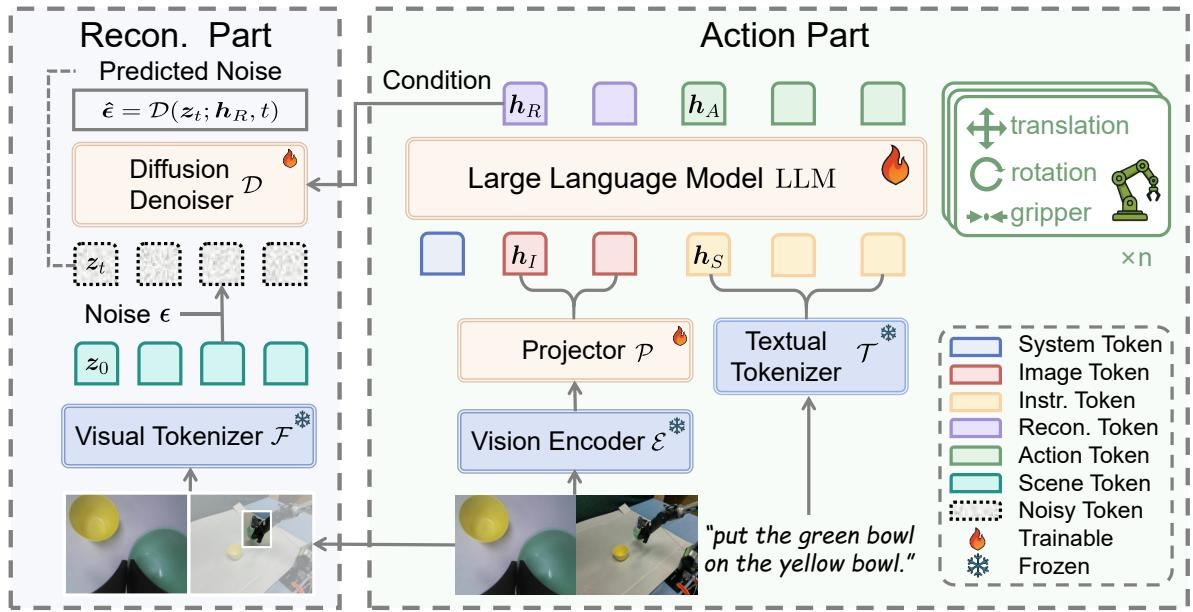
The architecture contains two coupled parts: an action part and a reconstruction part. The action part receives image tokens and instruction tokens, passes them through the large language model, and outputs action tokens for robotic control. The reconstruction part produces special reconstructive tokens hR from the large language model states. These tokens serve as conditioning information for a diffusion denoising process that reconstructs the gaze region from noisy latent tokens.
Formally, the reconstruction target is a cropped image I′ corresponding to the manipulated region. A visual tokenizer F converts this target into scene tokens z0=F(I′). A forward diffusion process adds noise ϵ to obtain noisy tokens zt. The denoiser D is then trained to predict the noise conditioned on the reconstructive tokens hR:
LVLAvisual(hR,I′)=Et,ϵ[∥D(zt;hR,t)−ϵ∥2],where t denotes the diffusion timestep. The denoiser consists of transformer encoder blocks with self attention modules, allowing noisy scene tokens and reconstructive tokens to exchange information. Because reconstruction is performed in a latent visual space, the model is encouraged to capture intrinsic structural and semantic features of the target region rather than merely copying explicit RGB values.
The overall training objective combines action supervision and reconstruction supervision:
LReconVLA=LVLAaction+LVLAvisual.Here, LVLAaction is a cross entropy loss over demonstration action tokens, while LVLAvisual measures reconstruction quality in the latent visual space. This joint formulation couples manipulation prediction with region aware visual grounding.
A key design detail is the token ordering. Instruction tokens are placed before image tokens, enabling image tokens to attend to the instruction context through causal attention. This helps ensure that visual tokens are associated with the instructed target rather than irrelevant scene content, while preserving the language modeling capability of the large language model.
The method also uses a staged training process. First, the model undergoes visual reconstruction pretraining on robot trajectory data paired with cropped gaze regions. In this stage, gradient backpropagation is applied to both the reconstruction loss and the action loss, keeping the visual grounding objective aligned with the control objective. This step strengthens the model’s ability to locate and reconstruct task relevant regions across varied scenes. After pretraining, the model is adapted on task specific manipulation data to align its vision language understanding, visual reconstruction behavior, and action generation with the target action space.
Experiment
The experiments evaluate ReconVLA in simulation and real-world robotic manipulation, using benchmark long-horizon tasks and practical multi-task setups to test visual grounding, pretraining generalization, and precise control. Comparisons with explicit and chain-of-thought grounding show that implicit grounding better focuses attention on target objects and avoids redundant or ambiguous spatial cues, while ablations confirm that pretraining and gaze-region reconstruction improve generalization and target selection. The proposed method also performs well in long-horizon simulation and real-world tasks, including unseen objects, indicating stronger visual grounding, manipulation precision, and adaptability than baseline methods.
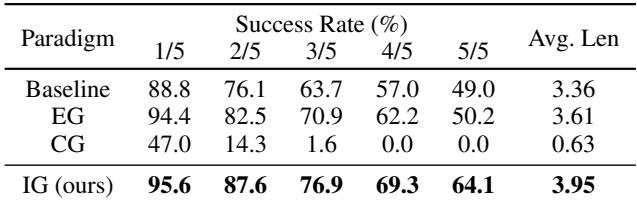
Implicit grounding gives the strongest overall manipulation performance and the best gains as task length increases. Explicit grounding also improves the baseline, especially for short chains, but is less effective than implicit grounding at longer horizons. Chain-of-thought grounding performs poorly overall and drops off sharply as consecutive tasks increase. Implicit grounding achieves the highest success rate and longest average task sequence in the comparison. Explicit grounding improves the baseline but trails implicit grounding, particularly on longer sub-task chains. Chain-of-thought grounding degrades severely with task length, indicating poor scalability in this setting.
The results and surrounding discussion show that reconstruction-based training is stronger when it uses large-scale pretraining and focuses on the gaze region rather than the full image. These techniques improve object grounding and generalization in unseen robot manipulation settings, while full-image reconstruction can still help by enhancing holistic visual attention. The compared generative baselines show strong early performance but lower success on later subtasks. Pretraining on large-scale datasets improves generalization and success in unseen manipulation environments. Reconstructing the gaze region helps the model focus on the target object and supports more reliable manipulation. Listed generative methods perform best on early subtasks and weaken across consecutive subtasks.
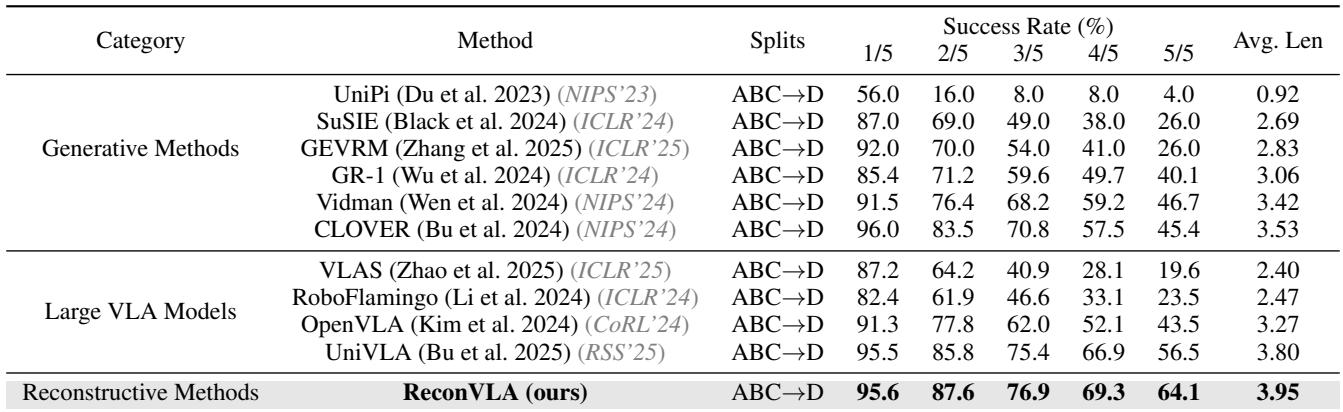
ReconVLA compares favorably with generative methods and large vision language action models on the CALVIN manipulation benchmark. It attains the highest reported average consecutive task length and a strong first-step success rate while maintaining competitive performance across later subtasks. The trend suggests that grounding the current visual observation can improve long-horizon manipulation reliability. Highest reported average consecutive task completion among the compared models. Strong first-step success compared with generative and large VLA baselines. Reported advantage over generative baselines on later subtasks in unseen background settings.
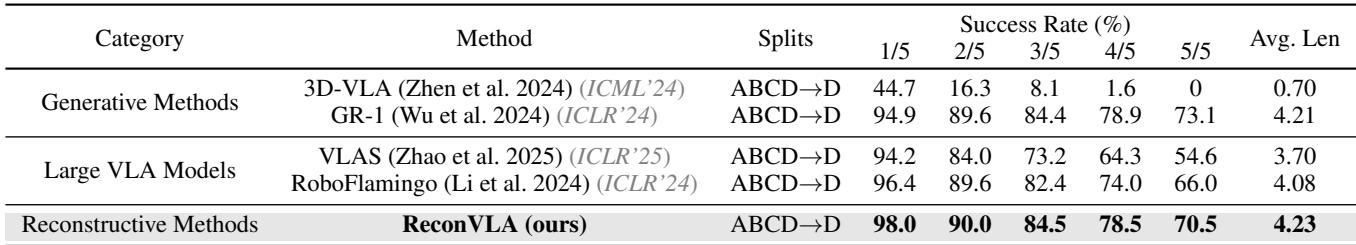
The experiments evaluate grounding strategies, reconstruction-based training variants, and ReconVLA against generative and large vision language action baselines on robot manipulation tasks, including CALVIN. Implicit grounding provides the strongest overall manipulation performance and scales better with longer task chains, while explicit grounding helps mainly short chains and chain of thought grounding degrades sharply with length. Reconstruction training is most effective with large-scale pretraining and gaze region reconstruction, improving object grounding and generalization in unseen settings, though full image reconstruction can still support visual attention. ReconVLA outperforms the compared generative baselines on long horizon and unseen manipulation, achieving strong first step success and the best consecutive task length, indicating that grounding the current observation improves long horizon reliability.