Command Palette
Search for a command to run...
Tokenisez une fois, recommandez partout : tokenisation unifiée des éléments pour la recommandation multi-domaines basée sur les LLM
Tokenisez une fois, recommandez partout : tokenisation unifiée des éléments pour la recommandation multi-domaines basée sur les LLM
Yu Hou Won-Yong Shin
Résumé
Les systèmes de recommandation basés sur les grands modèles de langage (LLM) ont atteint des performances de haute qualité en comblant l'écart entre l'espace des éléments et l'espace linguistique grâce à la tokenisation des éléments. Cependant, les méthodes existantes de tokenisation des éléments exigent généralement l'entraînement de modèles séparés pour chaque domaine d'éléments, ce qui limite la généralisation. De plus, les distributions et les sémantiques diverses entre les domaines d'éléments rendent difficile la construction d'une tokenisation unifiée qui préserve les informations spécifiques au domaine. Pour relever ces défis, nous proposons UniTok, un cadre de tokenisation unifiée des éléments qui intègre notre propre architecture de mélange d'experts (MoE) avec une série de livres de codes pour convertir les éléments en jetons discrets, permettant une tokenisation évolutive tout en préservant les informations sémantiques dans plusieurs domaines d'éléments. Spécifiquement, les éléments de différents domaines sont d'abord projetés dans un espace latent unifié via un encodeur partagé. Ils sont ensuite routés vers des experts spécifiques au domaine pour capturer la sémantique unique, tandis qu'un expert partagé, toujours actif, encode les connaissances communes transférables entre les domaines. De plus, pour atténuer le déséquilibre sémantique entre les domaines, nous présentons un mécanisme de calibration par information mutuelle, qui guide le modèle vers la rétention de niveaux similaires d'informations sémantiques pour chaque domaine. Des expériences approfondies sur des ensembles de données réelles variés démontrent que le cadre UniTok proposé est (a) hautement efficace : atteignant jusqu'à 51,89 % d'amélioration par rapport à des références solides, (b) théoriquement fondé : montrant la validité analytique de notre conception architecturale et de notre optimisation ; et (c) hautement généralisable : démontrant des performances robustes dans divers domaines sans nécessiter de réentraînement par domaine, une capacité non prise en charge par les références existantes.
One-sentence Summary
Researchers at Yonsei University propose UniTok, a unified item tokenization framework that employs a mixture-of-experts architecture with a series of codebooks to convert multi-domain items into discrete tokens via a shared encoder and domain-specific experts, supplemented by a mutual information calibration mechanism to balance semantic information across domains, achieving up to 51.89% improvements over strong benchmarks without requiring per-domain retraining.
Key Contributions
-
Introduces UniTok, a unified item tokenization framework that combines a customized mixture-of-experts architecture with codebook-based token extraction to map items from multiple domains into discrete semantic tokens. The design routes inputs through domain-specific experts and an always-active shared expert, while a mutual information calibration mechanism reduces semantic imbalance across domains.
-
Experiments on diverse real-world datasets demonstrate that UniTok achieves up to 51.89% gains over strong baselines in NDCG@10, reduces trainable parameters by 9.63×, and maintains robust zero-shot performance without per-domain retraining.
-
Theoretical analysis shows that UniTok induces a higher entropy token space, achieves lower quantization error, and reduces mutual information variance across domains, ensuring semantic consistency and stable performance.
Introduction
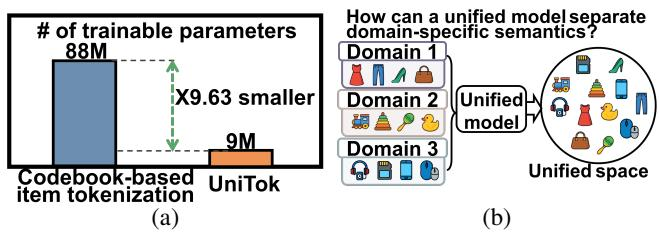
Large language models (LLMs) are increasingly used for generative recommendation, but they require item tokenization to convert items into discrete identifiers that bridge the item space and language space. Existing tokenization methods are tailored to single-domain settings, requiring separate tokenizers for each item domain. As recommendation tasks span multiple domains, this siloed approach leads to inefficiencies in training, deployment, and maintenance, hindering scalability. Two key challenges arise: (C1) training overhead from repeatedly learning domain-specific tokenizers, and (C2) semantic alignment, where a shared token space across domains risks semantic mixing and biased token assignments.
The authors introduce UniTok, the first unified item tokenization framework for multi-domain LLM-based recommendation. To address C1 and partially C2, they propose Token-MoE, a mixture-of-experts architecture that separates domain-specific experts from a shared expert, enabling the model to retain domain specialization while sharing common knowledge across domains. To fully solve C2, they add a mutual information calibration mechanism that encourages latent embeddings from each domain to remain semantically informative and consistent, reducing inter-domain performance variability. In experiments, UniTok achieves up to 51.89% improvement in NDCG@10, reduces trainable parameters by 9.63x compared to codebook-based baselines, and shows strong zero-shot generalization without retraining. The authors also provide theoretical guarantees for higher entropy token space, lower quantization error, and semantic consistency via reduced MI variance.
Method
The authors propose UniTok, a unified framework designed to address the challenges of multi-domain item tokenization for large language model-based recommender systems. As illustrated in the framework diagram, the architecture comprises four core components: a shared autoencoder, a Mixture of Experts (MoE) module named TokenMoE, codebook-based identifiers, and a Mutual Information (MI) calibration mechanism. This design enables the model to project heterogeneous item domains into a consistent latent space while preserving domain-specific nuances.
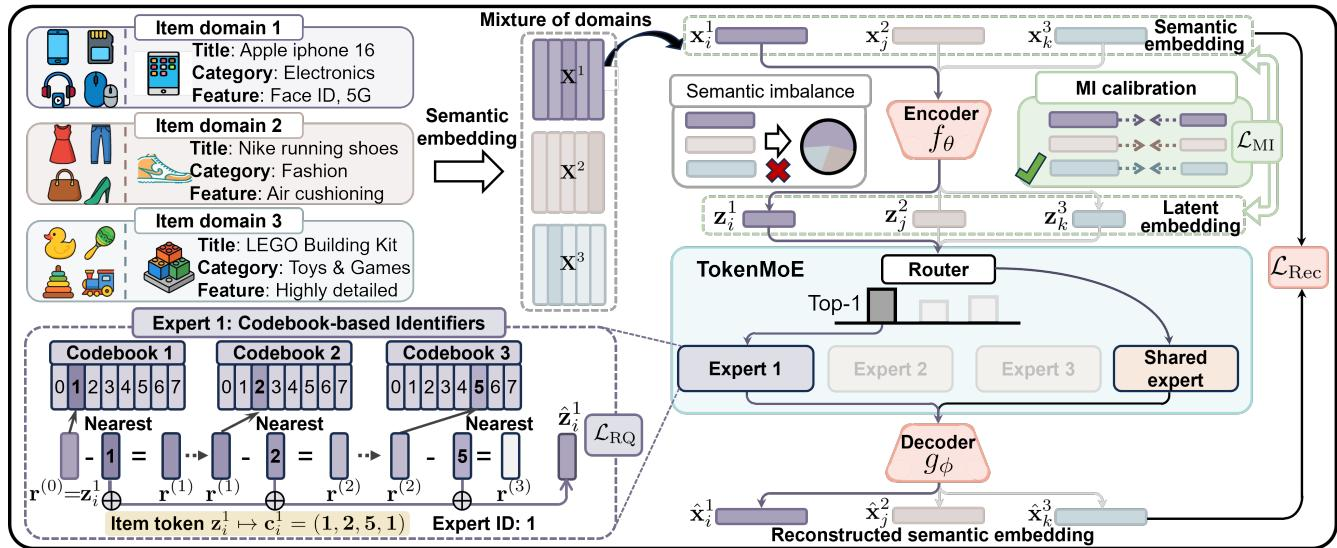
The pipeline begins with a shared autoencoder that maps continuous semantic embeddings from diverse item domains into a unified latent space. Given an input item embedding xik from domain k, the encoder fθ produces a latent representation zik. The decoder gϕ subsequently reconstructs the original embedding from the processed latent representation. This component establishes a common structural foundation across domains, optimized via a reconstruction loss that minimizes the L2 distance between the original and reconstructed embeddings.
To capture domain-specific semantics without conflating them, the framework employs TokenMoE. This module routes each latent embedding zik through a learnable router that computes a softmax distribution over K domain-specific experts. The router selects the top-N experts based on the highest activation scores. Concurrently, a shared expert is deterministically activated to facilitate cross-domain knowledge transfer. The final processed latent representation z^ik is computed as a weighted combination of the outputs from the selected domain-specific experts and the shared expert. Each expert module is initialized with the mean feature of its corresponding domain to provide an inductive bias for specialization.
Within each expert, the model utilizes codebook-based identifiers to discretize the continuous latent embeddings into compact token sequences. This is achieved through Residual Quantization (RQ), which recursively applies a series of codebooks to quantize the input residual vectors. At each quantization stage, the nearest code vector is selected from the corresponding codebook, and the residual is updated. This hierarchical quantization process generates a discrete codeword sequence that effectively represents the item. The quantization module is trained using an RQ loss that aligns the code vectors with the target residuals while enforcing commitment from the encoder and router.
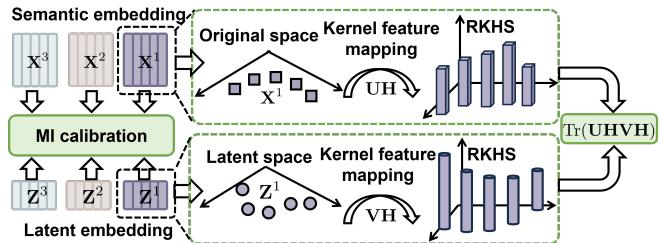
A critical challenge in multi-domain settings is semantic imbalance, where the quality of latent embeddings varies significantly across domains. To mitigate this, the authors introduce an MI calibration mechanism. This component measures the statistical dependence between the original semantic embeddings and the learned latent embeddings using the Hilbert-Schmidt Independence Criterion (HSIC) as a proxy for mutual information. By mapping both the input and latent spaces to a reproducing kernel Hilbert space (RKHS), the model computes the cross-covariance between the two spaces. The MI calibration loss is designed to penalize the variance of mutual information estimates across different domains, thereby enforcing semantic balance. Additionally, it encourages each domain to retain sufficient domain-specific information.
The overall training process optimizes the model end-to-end by minimizing a combined objective function. This total loss aggregates the reconstruction loss, the RQ loss, and the MI calibration loss, weighted by respective hyperparameters. Once trained, UniTok tokenizes each item into discrete semantic tokens, which are then utilized by downstream LLM-based recommenders to predict user interactions based on item token sequences.
Experiment
The experiments validate UniTok's unified tokenization framework across ten recommendation domains, showing consistent accuracy gains over both collaborative filtering and tokenization-aided methods, with notable improvements in semantic capture and generalization. Efficiency experiments reveal a substantial reduction in trainable parameters compared to traditional per-domain codebook tokenizers, while maintaining superior performance even under a shared training budget. Zero-shot tests on unseen domains confirm robust transferability without retraining. Ablation studies demonstrate that both the TokenMoE module and mutual information calibration are essential, as removing either degrades recommendation quality.
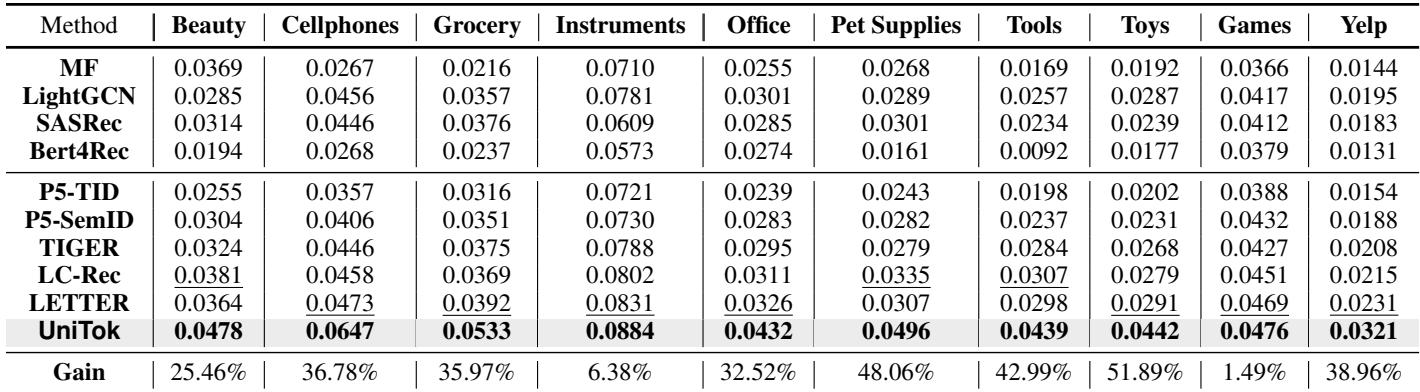
UniTok consistently outperforms all competing methods across ten diverse benchmark datasets in NDCG@10, with a maximum improvement of 51.89% on the Tools dataset. The results confirm that unified tokenization with shared semantics is more effective than dataset-specific tokenizers, while LLM-based recommender systems generally surpass traditional collaborative filtering baselines. UniTok achieves the highest NDCG@10 on every dataset, with the largest gain of 51.89% on Tools. LLM-based tokenization methods (TIGER, LC-Rec, LETTER, UniTok) outperform traditional collaborative filtering models like MF and LightGCN. Unified tokenization maintains strong accuracy across domains, whereas competitors trained jointly show substantial degradation.
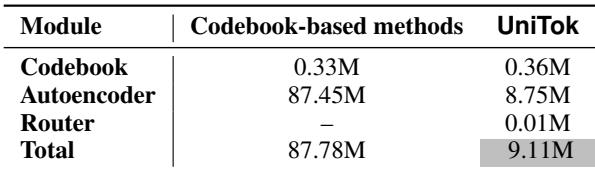
UniTok reduces trainable parameters by about an order of magnitude compared to codebook-based methods by using a single shared model across datasets, while competitors accumulate parameters per dataset. The savings come almost entirely from a smaller autoencoder, with codebook and router parameters being minimal. UniTok's total trainable parameters are roughly one tenth of codebook-based competitors (9.11M vs 87.78M), achieved through parameter sharing across all ten datasets. The autoencoder accounts for nearly all parameter reduction (8.75M vs 87.45M), while codebook size is similar (0.36M vs 0.33M) and the router adds only 0.01M.
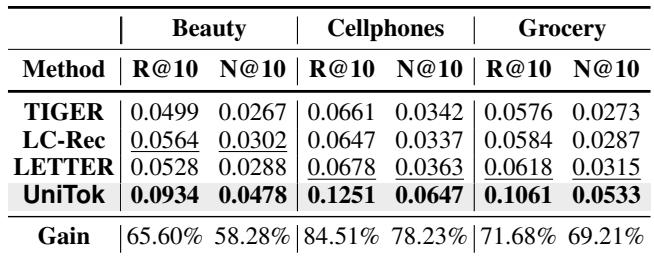
Under a unified training setup with comparable parameter budgets, UniTok consistently outperforms traditional codebook-based tokenizers across all evaluated domains, while competitors suffer substantial performance degradation. The gains are particularly pronounced on Cellphones, where UniTok improves Recall@10 by up to 84.51%. UniTok achieves large relative gains over all competitors, with Recall@10 improvements ranging from 65.60% on Beauty to 84.51% on Cellphones. Competing methods degrade notably in the unified multi-domain setting, likely due to difficulty in distinguishing items from different domains with shared tokenization. UniTok's modular TokenMoE architecture enables domain-specific experts to learn independently while sharing a unified token space, preserving performance.
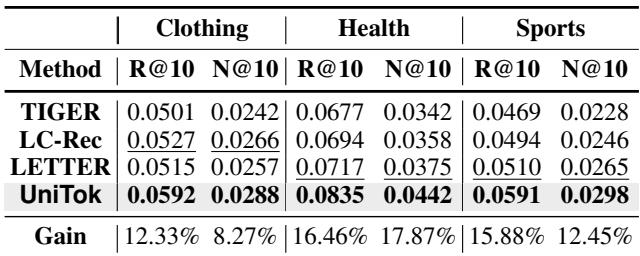
In a zero-shot generalization test across three unseen domains (Clothing, Health, Sports), UniTok consistently achieves the best recall and NDCG at 10 compared to existing item tokenization-based methods, with relative gains ranging from about 8% to nearly 18%. The improvement is most pronounced on the Health domain, where NDCG@10 increases by 17.87% over the strongest baseline. UniTok attains the highest Recall@10 and NDCG@10 on all three unseen datasets. The largest relative gain is 17.87% in NDCG@10 on the Health domain. Baselines like TIGER, LC-Rec, and LETTER perform lower across all metrics, with UniTok showing up to 15.88% improvement in Recall@10 on Sports.
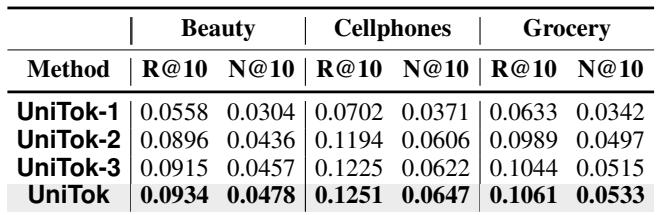
An ablation study progressively removing the TokenMoE module, shared expert, and MI calibration shows that each component contributes to recommendation accuracy. The largest performance drop occurs when TokenMoE is removed, while MI calibration provides additional consistent gains across all datasets. The full model achieves the best results on every dataset. Removing TokenMoE causes the most significant performance decline across all datasets. Adding the shared expert improves accuracy over using only TokenMoE without it. MI calibration further boosts performance on top of TokenMoE and the shared expert. The complete UniTok model consistently outperforms all ablated variants.
The evaluation shows UniTok consistently outperforms all baselines across ten benchmark datasets, with large gains in NDCG@10 and Recall@10, and superior zero-shot generalization on unseen domains. It achieves these results while reducing trainable parameters by nearly an order of magnitude through shared tokenization and a modular architecture. Ablation studies confirm that the TokenMoE module, shared expert, and MI calibration each contribute meaningfully to accuracy, with the full model yielding the best performance across all settings.