Command Palette
Search for a command to run...
Correction Efficace des Incohérences de Raisonnement Neuro-Symbolique par Réflexion Abductive
Correction Efficace des Incohérences de Raisonnement Neuro-Symbolique par Réflexion Abductive
Wen-Chao Hu Wang-Zhou Dai Yuan Jiang Zhi-Hua Zhou
Résumé
L'IA neuro-symbolique (NeSy) peut être considérée comme une analogie à la cognition humaine à double processus, modélisant le Système 1 intuitif avec des réseaux de neurones et le Système 2 algorithmique avec le raisonnement symbolique. Cependant, pour des cibles d'apprentissage complexes, les systèmes NeSy génèrent souvent des sorties incohérentes avec les connaissances du domaine, et il est difficile de les corriger. Inspirés par la réflexion cognitive humaine, qui détecte rapidement les erreurs dans notre réponse intuitive et les révise en invoquant le raisonnement du Système 2, nous proposons d'améliorer les systèmes NeSy en introduisant la réflexion abductive (ABL-Ref) basée sur le cadre d'apprentissage abductif (ABL). ABL-Ref exploite les connaissances du domaine pour inférer par abduction un vecteur de réflexion pendant l'entraînement, qui peut ensuite signaler les erreurs potentielles dans les sorties du réseau de neurones et invoquer l'abduction pour les corriger et générer des sorties cohérentes lors de l'inférence. ABL-Ref est très efficace par rapport aux implémentations ABL précédentes. Les expériences montrent qu'ABL-Ref surpasse les méthodes NeSy de pointe, atteignant une excellente précision avec moins de ressources d'entraînement et une efficacité accrue.
One-sentence Summary
Researchers from Nanjing University propose ABL-Ref, an Abductive Learning-based framework inspired by human Cognitive Reflection that leverages domain knowledge to abduce a reflection vector during training, flagging potential errors in neural network outputs and invoking abduction to rectify them for consistent inference, achieving state-of-the-art accuracy in Neuro-Symbolic reasoning with fewer training resources and enhanced efficiency.
Key Contributions
- Introduces ABL-Ref, an Abductive Reflection method built on the Abductive Learning framework, which uses domain knowledge to abduce a reflection vector during training that flags potential errors in neural network outputs and triggers abduction to produce knowledge-consistent outputs at inference time.
- The reflection vector acts as an attention mechanism for symbolic reasoning, narrowing the problem space substantially and achieving higher efficiency than prior ABL implementations, which suffered from high consistency-optimization complexity.
- Experimental results show ABL-Ref outperforms state-of-the-art NeSy methods in reasoning accuracy while requiring fewer training resources, and it is validated on diverse tasks including combinatorial optimization on graphs, demonstrating versatility across data types, dimensions, and knowledge base formalisms.
Introduction
Neuro-Symbolic (NeSy) AI mirrors human reasoning by pairing neural networks, which act like System 1 for fast pattern recognition, with symbolic reasoning that resembles System 2 for deliberate, knowledge-driven logic. The appeal is that symbolic domain knowledge can catch and rectify the unreliable outputs that neural networks often produce on complex tasks. However, prior approaches have struggled to maintain the full expressive power of both sides: some relax symbolic knowledge into neural constraints, while others approximate logical calculus with distributed representations, both of which sacrifice complete reasoning ability. Abductive Learning (ABL) preserves full symbolic reasoning, but it comes at a cost: the approach relies on a highly discrete consistency optimization step that is computationally expensive and limits scalability to large problems.
To address this, the authors propose Abductive Reflection (ABL-Ref), a general enhancement to the ABL framework. Inspired by cognitive reflection in humans, where fast intuitive responses trigger a check against domain knowledge, ABL-Ref generates a reflection vector alongside the neural network's output. This vector flags potential errors and invokes symbolic abduction to rectify them, effectively acting as an attention mechanism that narrows the search space for the symbolic solver. Crucially, this replaces the expensive consistency optimization, and the reflection vector is abduced from domain knowledge in an unsupervised manner, requiring no extra training data beyond what state-of-the-art NeSy systems already use. The authors validate ABL-Ref on Sudoku benchmarks in both symbolic and visual forms, where it achieves higher reasoning accuracy with fewer training resources than prior NeSy methods, and they also show improved reasoning efficiency on combinatorial graph optimization tasks.
Method
The authors propose Abductive Reflection (ABL-Ref) to address the computational inefficiencies inherent in standard Abductive Learning (ABL). In the conventional ABL framework, a neural network f maps an input x to an intuitive output y^. If this output contains errors inconsistent with the Knowledge Base (KB), an external consistency optimization module must identify the erroneous positions. This module typically employs zeroth-order optimization and repeatedly queries the KB, leading to exponential time consumption as the data scale increases.
Refer to the framework diagram. As shown in the figure, the standard ABL process involves a consistency optimization phase that pinpoints incorrect truth assignments before the abduction step can rectify them. This reliance on repetitive symbolic reasoning queries creates a significant bottleneck, limiting ABL to small datasets.
To resolve this, ABL-Ref introduces a learnable Reflection Layer (R) that replaces the external optimization module. The model architecture processes the input through a body block f1 to generate high-dimensional embeddings. These embeddings are then split into two paths. One path feeds into an output layer f2 to produce the intuitive output y^. The other path feeds into the reflection layer R, which generates a reflection vector r.
As illustrated in the architecture diagram below, the reflection vector r acts as a binary mask with the same dimensionality as y^. Each element ri indicates whether the corresponding element y^i is an error (1) or correct (0). This reflection mechanism operates concurrently with the intuitive output generation, mimicking human cognitive reflection.
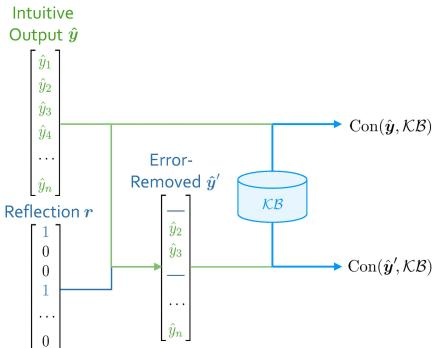
Using the reflection vector r, the model constructs an error-removed output y^′ by masking the elements flagged as errors. The KB then performs abduction on these masked positions to fill in the blanks, resulting in a final output yˉ that is consistent with the domain knowledge. This approach significantly reduces the need for repetitive KB queries, requiring only a single abduction invocation after the reflection layer identifies the errors.
The training of ABL-Ref focuses on optimizing the reflection mechanism to maximize consistency improvements. The authors define a consistency measurement function Con(y^,KB), which returns 1 if the output adheres to KB constraints and 0 otherwise. The training objective is to maximize the consistency gain ΔConr(y^)=Con(y^′,KB)−Con(y^,KB). Since this gain is discrete, the REINFORCE algorithm is employed to optimize the neural network parameters.
The total loss function combines three components:
- Consistency Loss (Lcon): Encourages the reflection vector to identify errors that lead to higher consistency after abduction.
- Reflection Size Loss (Lsize): Penalizes the reflection vector for flagging too many elements as errors, ensuring that abduction is invoked only when necessary. This loss uses a hyperparameter C to control the maximum proportion of errors allowed.
- Supervised Loss (Llabeled): A standard cross-entropy loss applied to labeled data.
The combined loss is formulated as:
L=∣Dl∣1(x,y)∈Dl∑Llabeled(x,y)+∣Dl∪Du∣1x∈Dl∪Du∑(αLcon(x)+βLsize(x))where Dl and Du represent labeled and unlabeled datasets, respectively, and α,β are hyperparameters.
Experiment
The experiments evaluate ABL-Ref across symbolic Sudoku, visual Sudoku with image inputs, and NP-hard graph optimization problems. Results show that ABL-Ref consistently outperforms existing neuro-symbolic baselines in reasoning accuracy while reducing training time and labeled data requirements. The reflection mechanism narrows the symbolic reasoning search space, lowering inference time compared to pure symbolic solvers. The method also demonstrates versatility by handling both symbolic and sub-symbolic data, as well as domain knowledge expressed in propositional or first-order logic or as mathematical formulations, with further analysis confirming that the reflection mechanism detects neural network errors more effectively and efficiently than alternative approaches.
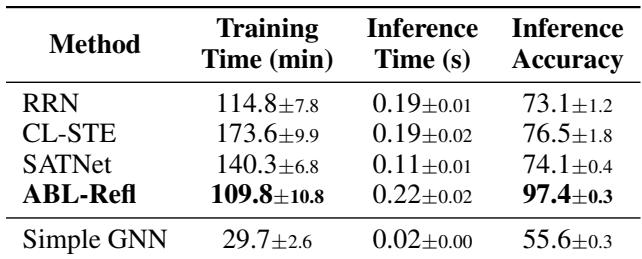
The table compares methods for solving Sudoku, showing that ABL-Refl achieves the highest inference accuracy (97.4%) while maintaining competitive training and inference times. Simple GNN, the fastest approach, has significantly lower accuracy (55.6%), highlighting a trade-off between speed and correctness. ABL-Refl outperforms all baselines in inference accuracy, reaching 97.4%, nearly 20 percentage points higher than the next best method Simple GNN is the fastest in both training and inference but yields the lowest accuracy, indicating that pure neural outputs are insufficient for rule-constrained tasks The inference time of ABL-Refl (0.22s) is only slightly higher than other methods, yet its accuracy gain is substantial Among the baseline methods, CL-STE has the highest accuracy (76.5%) but the longest training time, while SATNet offers a moderate balance
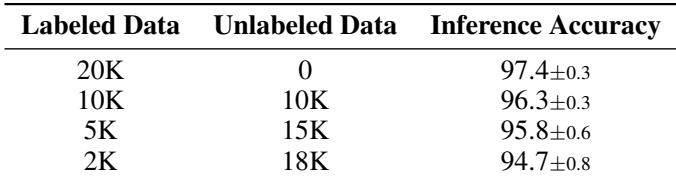
Across a fixed 20K-example dataset, reducing the amount of labeled data from 20K to 2K while increasing unlabeled data correspondingly leads to a gradual decline in Sudoku inference accuracy. The accuracy remains high even with only 2K labels, indicating the method's resilience to label scarcity. Accuracy stays above 94% even when labeled data is reduced to 10% of the total dataset. The drop in accuracy is modest, under 3 percentage points, when labeled data is reduced from 20K to 2K.
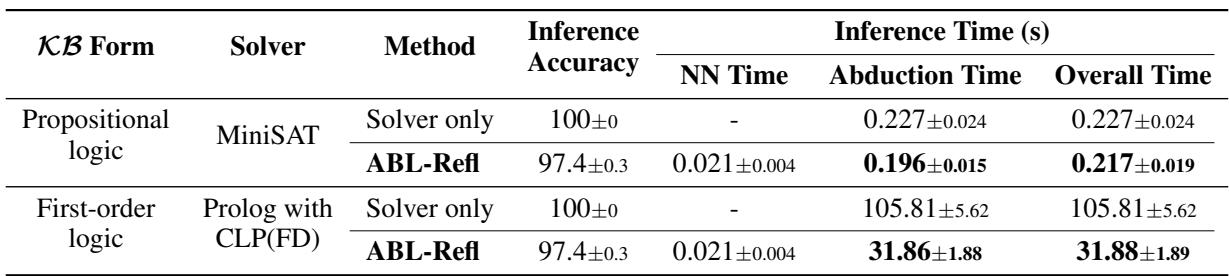
ABL-Ref integrates neural network inference with symbolic reasoning to solve Sudoku, achieving near-perfect accuracy while substantially reducing inference time compared to using symbolic solvers alone. The speedup is especially pronounced when the knowledge base is expressed in first-order logic, where the overall inference time drops by more than a factor of three. ABL-Ref maintains high inference accuracy (97.4%) while cutting overall inference time compared to solver-only baselines. The acceleration is more dramatic for first-order logic: overall time is reduced from over 100 seconds to around 32 seconds. The NN component adds only minimal time, and the major savings come from reducing the abduction time despite added neural reflection.
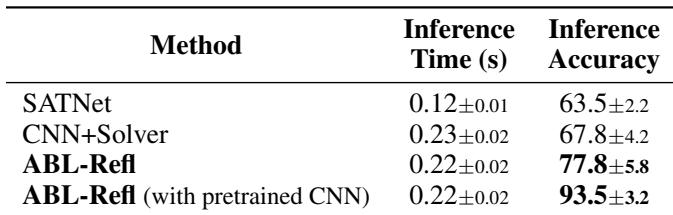
ABL-Refl achieves higher inference accuracy than SATNet and CNN+Solver on visual Sudoku, and pretraining the CNN further boosts accuracy while keeping inference time comparable. The method demonstrates that end-to-end reasoning with reflection improves both accuracy and robustness over existing approaches. ABL-Refl outperforms SATNet in inference accuracy with similar or slightly higher inference time. Pretraining the CNN for ABL-Refl substantially increases accuracy without changing inference time. CNN+Solver has lower accuracy and higher inference time than ABL-Refl, partly due to errors from the CNN not being revisable.
The table compares approximation ratios for maximum clique finding across four datasets, showing that the proposed method consistently achieves the highest or near-highest ratios with notably lower variance than the other two baselines. The gains are especially pronounced on the COLLAB dataset, where the baseline methods drop in performance but the proposed method remains stable. The proposed method attains the best average approximation ratio on ENZYMES, PROTEINS, and COLLAB, and ties for best on IMDB-Binary. Variance under the proposed method is substantially smaller than that of the baselines across all datasets, indicating more reliable performance. Baseline methods show a marked decline on COLLAB, whereas the proposed method maintains a high ratio, suggesting better scalability to larger graphs.
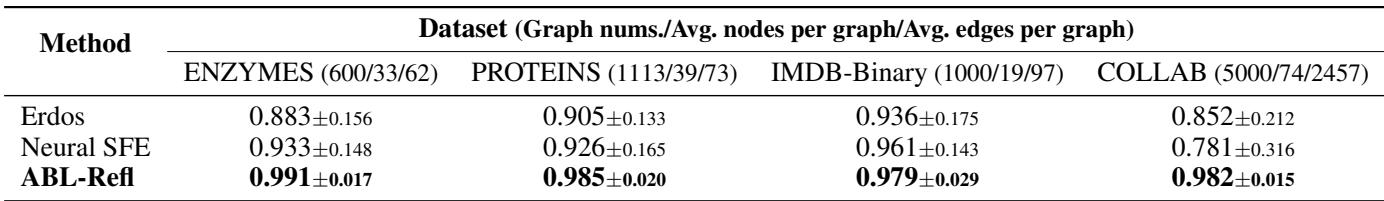
The experiments demonstrate that ABL-Refl achieves superior inference accuracy on Sudoku compared to baselines, while maintaining competitive training and inference times, and it remains highly accurate even with only 10% labeled data. Integrating neural and symbolic reasoning cuts overall inference time, particularly for first-order logic, without sacrificing accuracy. On visual Sudoku and maximum clique tasks, ABL-Refl consistently outperforms or matches existing methods, with lower variance and better scalability, confirming its robustness and practical efficiency across different reasoning problems.