Command Palette
Search for a command to run...
HINT-WAM : entraînement informé par le recul pour les modèles d'action du monde
HINT-WAM : entraînement informé par le recul pour les modèles d'action du monde
Phuong Tuan Dat Qi Li Xinchao Wang
Résumé
Les modèles d'action du monde (WAM) ont montré une généralisation et une efficacité en données prometteuses en manipulation robotique en couplant la génération d'actions à la prédiction de dynamiques visuelles futures. Transposer ces capacités en une exécution fiable des tâches reste toutefois un défi pour les méthodes de post-entraînement existantes. L'ajustement supervisé hors ligne fournit une supervision dense sur des trajectoires d'expert, mais son expert d'action par flux d'appariement n'est entraîné que sur des actions de démonstration bruitées et jamais sur les états intermédiaires produits par son propre échantillonneur ; l'adaptation spécifique à une tâche peut en outre compromettre les capacités pré-entraînées. L'apprentissage par renforcement en politique entraîne sur le comportement propre de la politique, mais les récompenses de tâche éparses rendent l'exploration et l'attribution de crédit difficiles, tandis que la mise en forme dense des récompenses ne fournit encore que des évaluations scalaires plutôt que des cibles d'action directes. Nous introduisons HINT-WAM, le premier cadre d'auto-distillation en politique qui supervise l'expert d'action sur ses propres trajectoires d'échantillonnage en utilisant le recul, la vidéo future de la démonstration, comme information privilégiée disponible pour le WAM lui-même. Pour chaque observation de démonstration, l'étudiant génère son action par sa propre trajectoire de débruitage, et aux états le long de cette trajectoire, le même modèle agit comme enseignant conditionné en outre par ce recul, fournissant une distribution d'actions conditionnelle comme cible d'entraînement dense, tandis que l'étudiant ne voit que les entrées disponibles au moment du déploiement et n'a besoin ni de récompenses environnementales ni d'interaction avec le simulateur. Pour transférer cette supervision à un expert d'action par flux d'appariement, HINT-WAM distille l'enseignant dans l'étudiant au moyen d'un score d'énergie, un objectif au niveau de la distribution qui fait correspondre la distribution d'actions de l'enseignant à partir des propres échantillons de l'étudiant plutôt que de régresser son champ de vitesse. Le site web du projet est disponible à ce lien.
One-sentence Summary
Researchers at the National University of Singapore introduce HINT-WAM, the first on-policy self-distillation framework for world action models, which supervises a flow-matching action expert on its own sampling trajectories by using hindsight as privileged information and distills the teacher into the student via an energy score to match the teacher’s action distribution from the student’s own samples rather than regressing its velocity field for reliable manipulation.
Key Contributions
- HINT-WAM is introduced as the first on-policy self-distillation framework for world action models, with a hindsight teacher sharing the student backbone to provide dense action targets at states from the action expert's own sampling trajectory.
- The framework uses future demonstration video as privileged hindsight information and distills the flow-matching action expert with an energy score, matching the teacher's action distribution from the student's own samples instead of regressing a velocity field and requiring no external teacher, rewards, or simulator interaction.
- Experiments show HINT-WAM improves post-training performance over supervised fine-tuning and matched baselines on LIBERO-90 and RoboTwin 2.0, while reducing catastrophic forgetting of pretrained skills and composing with replay.
Introduction
World action models improve robot manipulation by coupling action generation with future visual prediction, and recent flow-matching action experts produce continuous action chunks. Reliable adaptation remains challenging because supervised fine-tuning suffers from exposure bias, since it trains only on demonstration actions rather than the model’s own sampled states, and cannot resolve ambiguous action continuations. On-policy reinforcement learning can address the state mismatch but often struggles with sparse rewards, while existing on-policy distillation methods assume discrete tokens, require a separate teacher, or regress a velocity field that averages over modes. The authors introduce HINT-WAM, an on-policy self-distillation framework in which the policy acts as its own teacher using hindsight future frames, supervises the flow-matching action expert on its own sampler states, and uses an energy-score objective to match the teacher’s action distribution without likelihood evaluation. This approach needs no external teacher, rewards, or simulator interaction, and improves post-training performance on LIBERO-90 and RoboTwin 2.0 while reducing catastrophic forgetting.
Method
The authors present HINT-WAM, a post-training framework that enables a pretrained World Action Model (WAM) to act as its own teacher by leveraging hindsight information. The overall pipeline is divided into three distinct stages: supervised fine-tuning, hindsight teacher training, and on-policy self-distillation.
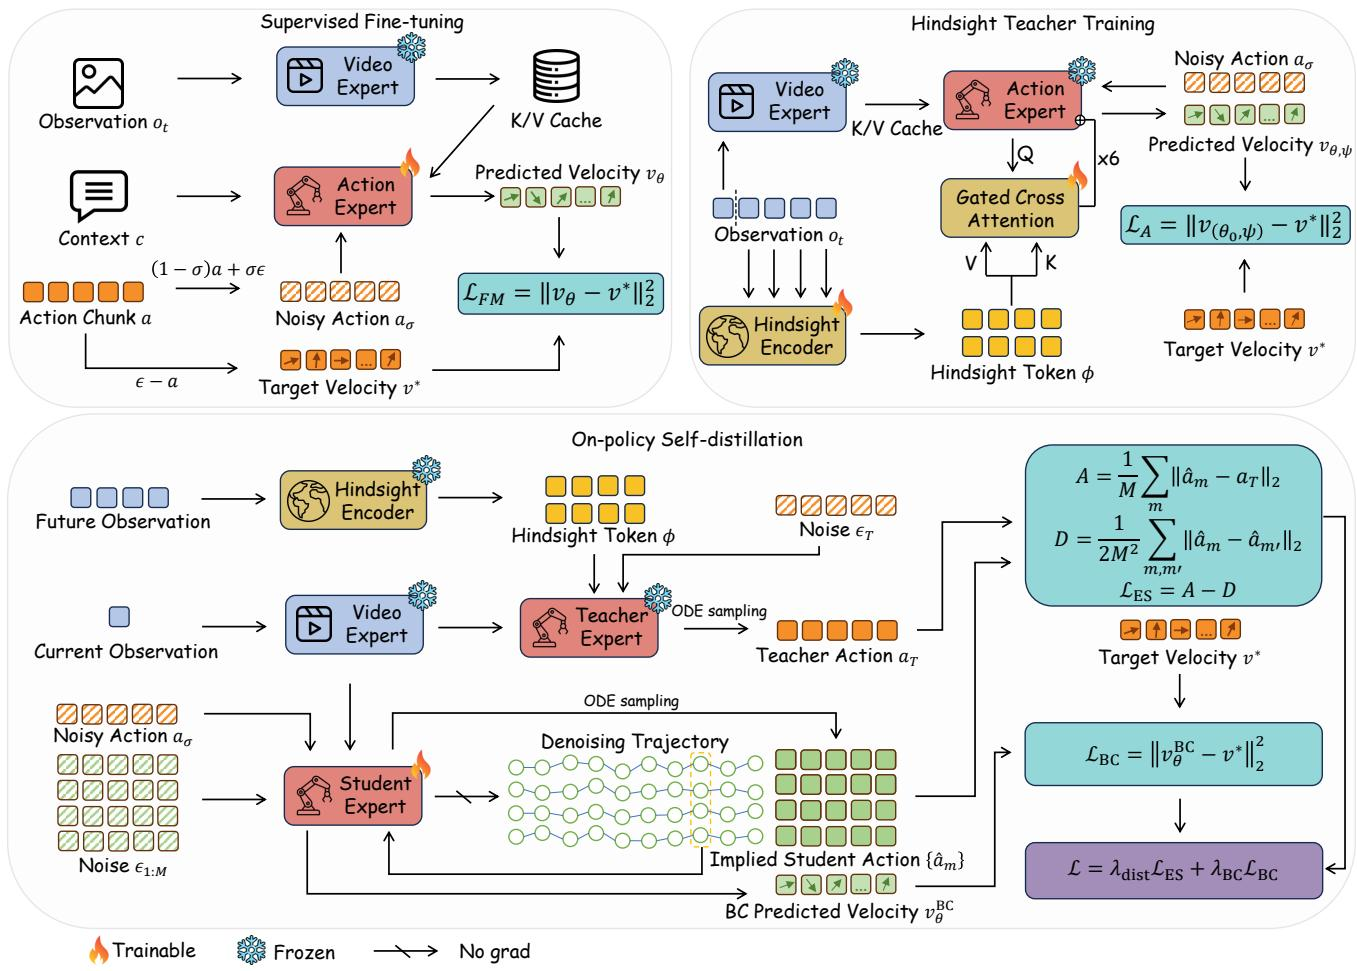
In the first stage, the authors perform Supervised Fine-Tuning (SFT) to initialize the student model. The base architecture is Fast-WAM, which utilizes a Mixture-of-Transformers backbone with two experts sharing a single attention operation per layer. The video expert processes the current camera frame, while the lightweight action expert generates an action chunk a∈RH×D conditioned on the observation o=(I,ℓ,s). The action expert operates as a flow-matching model, predicting a velocity vθ(aσ,σ,o) for a noisy action chunk aσ=(1−σ)a+σϵ. The model is trained by minimizing the flow-matching loss:
LFM(θ)=E(o,a),σ,ϵvθ(aσ,σ,o)−(ϵ−a)22.This stage yields the student initialization θ0.
Next, the authors construct the Hindsight Teacher in Stage A. To resolve target ambiguity without altering the base weights, they freeze the SFT model θ0 and introduce two trainable modules: a hindsight encoder and gated cross-attention adapters. The hindsight encoder processes the future video latents of the demonstration. It drops the first latent frame to prevent information leakage, mean-pools the remaining frames over space, and projects the sequence. A set of learned queries then pools this sequence via multi-head attention to produce hindsight tokens ϕψ(z). These tokens are injected into the action expert through gated cross-attention adapters attached after a subset of layers. The adapter computes:
h′=h+tanh(αl)WupWoutAttn(q,k,v),where q is derived from the action-token hidden states, and k,v are derived from the hindsight tokens. The entire backbone remains frozen, and only the encoder and adapter parameters ψ are trained using the flow-matching loss augmented with hindsight.
Finally, Stage B focuses on On-policy Self-distillation to address exposure bias. The student θ, initialized from θ0, is trained to match the frozen teacher T=(θ0,ψ) on its own sampling trajectories. The student integrates its own probability-flow ODE without gradients to record the denoising states visited during inference. To supervise these states efficiently, the authors select the top-K points where the local Euler step error is highest and renormalize their weights to wˉk.
To align the student with the teacher, the authors employ two distillation objectives. The first is velocity matching, which minimizes the difference between the student and teacher velocities at the selected states:
Lvel(θ)=k=1∑KwˉkEvθk−sg[vTk]22.Because the teacher behavior is multimodal from the student perspective, matching the conditional mean can be suboptimal. Therefore, the authors also utilize an energy score for distribution matching. The student draws M independent trajectories to obtain implied actions a^m,k, while the teacher draws a single action aT using its ODE. The energy score loss is defined as:
LES(θ)=k=1∑Kwˉk[M1m=1∑M∥a^m,k−aT∥2−2M21m,m′=1∑M∥a^m,k−a^m′,k∥2].This objective pulls the student samples toward the teacher sample while pushing them apart to prevent mode collapse. To prevent the student from blindly following teacher errors, a behavior-cloning anchor LBC(θ)=LFM(θ) is added. The final Stage-B objective balances the distillation and behavior-cloning terms:
LB(θ)=λdistLdist(θ)+λBCLBC(θ),where Ldist∈{Lvel,LES}. At deployment, only the student model is utilized, ensuring the policy operates without requiring future observations.
Experiment
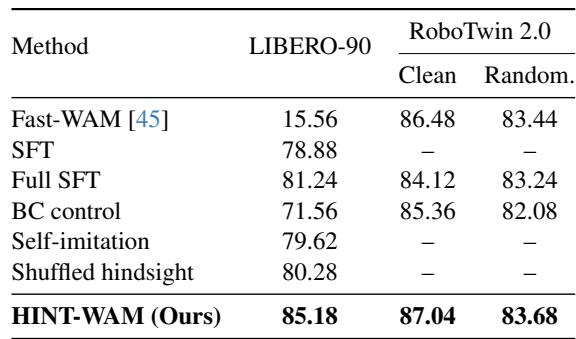
The experiments evaluate HINT-WAM on LIBERO-90 and RoboTwin 2.0, starting from a shared Fast-WAM checkpoint and comparing against SFT, full SFT, BC control, self-imitation, and shuffled-hindsight baselines. On unseen LIBERO-90 tasks, hindsight distillation improves over SFT and full SFT while remaining computationally cheaper than full SFT, and on RoboTwin it prevents the degradation caused by continued imitation. Continual learning results show that HINT-WAM forgets less than SFT and composes well with experience replay. Ablations indicate that the energy-score distribution matching, the behavior-cloning anchor, multiple student samples, and on-policy states each contribute, with the anchor and hindsight correction jointly producing the main improvement.
Fine-tuning the action expert improves LIBERO-90 success dramatically over the released Fast-WAM checkpoint, while RoboTwin results remain broadly high across methods. Ablations show that the strongest LIBERO-90 result comes from combining a behavior-cloning anchor with energy-score distribution matching, on-policy states, and multiple student samples. Individual ablations, including removing the anchor or using demonstrated states, fall back toward or below SFT. Fast-WAM shows a large LIBERO-90 gap relative to fine-tuned baselines, but RoboTwin success rates stay close across evaluated methods. Energy-score distribution matching outperforms velocity matching, MMD, and action-space MSE under matched ablation conditions. Combining the behavior-cloning anchor with distillation yields a strong positive interaction, whereas each component alone reduces success. Using the student's own on-policy states outperforms substituting demonstrated states noised like SFT, and more student samples improve success monotonically.
Post-training on LIBERO-90 without experience replay causes severe forgetting on the four original suites for every method, reducing average success from 96.55% to below 45%. HINT-WAM retains the most original-suite performance without replay, while full SFT forgets the most. With experience replay, the gap largely closes and HINT-WAM benefits further, outperforming SFT on both new and original tasks and nearly matching the released checkpoint. Without replay, all methods fall below 45% average success on the original suites after LIBERO-90 training. HINT-WAM preserves the most pretrained skill without replay, while full SFT loses the most. Experience replay largely recovers original-suite performance, and HINT-WAM with replay exceeds SFT on both new and original tasks. The largest replay gain for HINT-WAM appears on the long-horizon suite.
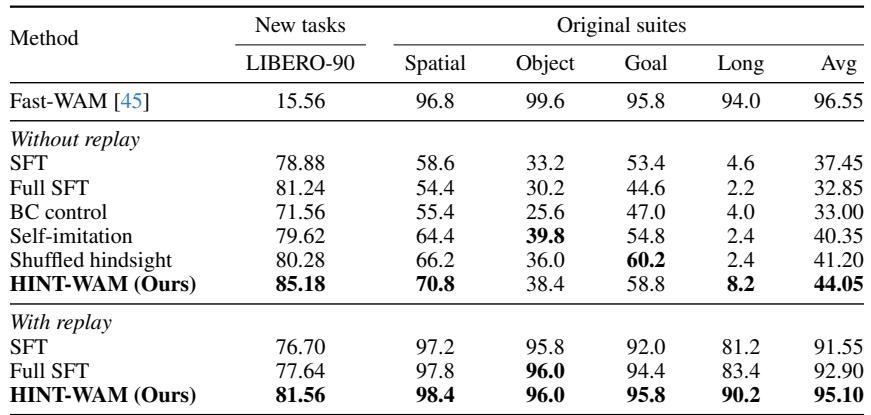
The evaluation covers fine-tuning on LIBERO-90 and RoboTwin, ablations on distillation components, and post-training retention on four original suites. Fine-tuning the action expert greatly improves LIBERO-90 over the released Fast-WAM checkpoint, and the best setup combines a behavior-cloning anchor with energy-score distribution matching, on-policy states, and multiple student samples, while RoboTwin success stays broadly high across methods. Without experience replay, LIBERO-90 post-training causes severe forgetting on original suites for all methods; replay largely restores performance, with HINT-WAM retaining the most pretrained skill and exceeding SFT on new and original tasks.