Command Palette
Search for a command to run...
AscendGYM : un banc d’essai d’optimisation de noyaux sensible au coût pour des charges de travail réelles sur NPU Ascend
AscendGYM : un banc d’essai d’optimisation de noyaux sensible au coût pour des charges de travail réelles sur NPU Ascend
Résumé
L’optimisation des noyaux est essentielle pour un entraînement et une inférence efficaces des grands modèles de langage (LLM) sur les NPU Ascend. Les bancs d’essai Ascend existants se concentrent principalement sur la génération de noyaux, en accordant moins d’importance à la capacité des agents à optimiser des implémentations existantes sous des configurations d’entrée issues de charges de travail réelles. Pour répondre à ce besoin, nous présentons AscendGYM, un banc d’essai dont la suite initiale comprend 48 noyaux répartis sur trois niveaux de difficulté. Chaque noyau est associé à des cas de test dont les types de données et les formes de tenseurs sont collectés à partir de tâches réelles d’entraînement et d’inférence. Par conséquent, les gains de performance sur AscendGYM se traduisent directement sur les charges de travail correspondantes. En termes d’utilisabilité, AscendGYM prend en charge deux modes d’évaluation : l’évaluation de modèles et l’évaluation de modèles avec harnais. Les capacités d’optimisation de noyaux des modèles entraînés comme des agents personnalisés peuvent ainsi être mesurées. Il fournit un environnement d’exécution complet qui reproduit fidèlement la manière dont les noyaux Ascend sont invoqués dans des pipelines réels. Pour l’évaluation de modèles, il inclut en outre un harnais intégré doté d’une orchestration de recherche et d’une accumulation d’expérience. Enfin, nous proposons une nouvelle métrique, le Speedup–Token Score (STS), qui quantifie les gains de performance par rapport au coût en jetons. En considérant conjointement l’accélération et le coût, le STS permet d’évaluer la capacité pratique d’optimisation de noyaux d’un modèle ou d’un harnais dans le cadre d’un budget acceptable. AscendGYM est disponible à l’adresse https://github.com/SLAI-AITP/AscendGYM.
One-sentence Summary
Researchers from Shenzhen Loop Area Institute introduce AscendGYM, a cost-aware Ascend NPU kernel optimization benchmark with 48 kernels across three difficulty levels and real-workload test cases, supporting model and model-harness evaluation via a built-in harness and proposing the Speedup-Token Score to assess practical kernel optimization gains relative to token cost.
Key Contributions
- The paper introduces AscendGYM, a kernel optimization benchmark for Ascend NPUs with 48 kernels across three difficulty levels, complete runnable initial source code, and input configurations drawn from real LLM training and inference workloads.
- It provides AscendForge, an execution environment for candidate compilation, correctness checking, and performance measurement, supporting both model evaluation with a built-in harness and model-harness evaluation.
- It proposes the Speedup-Token Score (STS), a metric that combines performance gains with cumulative token cost, and reports Batch 1 results on 17 tasks showing the benchmark remains challenging and STS reveals differences that speedup alone does not capture.
Introduction
Efficient large language model training and inference depend heavily on low-level kernel performance, and on Ascend NPUs optimizing existing kernels for real workloads is a critical engineering task. Prior benchmarks primarily evaluate whether models can generate correct kernels from task specifications, but they do not systematically assess iterative optimization of already correct implementations under workload-derived input configurations and explicit resource budgets. The authors introduce AscendGYM, a benchmark with 48 kernel optimization tasks drawn from real LLM training and inference workloads. It provides runnable baseline implementations, workload-matched input shapes and data types, an execution sandbox called AscendForge for compilation, correctness checking, and performance measurement, and a Speedup-Token Score that jointly captures achieved speedup and token consumption. Evaluation on Batch 1 shows most current agents achieve only modest gains, confirming that optimizing existing Ascend kernels remains challenging.
Dataset
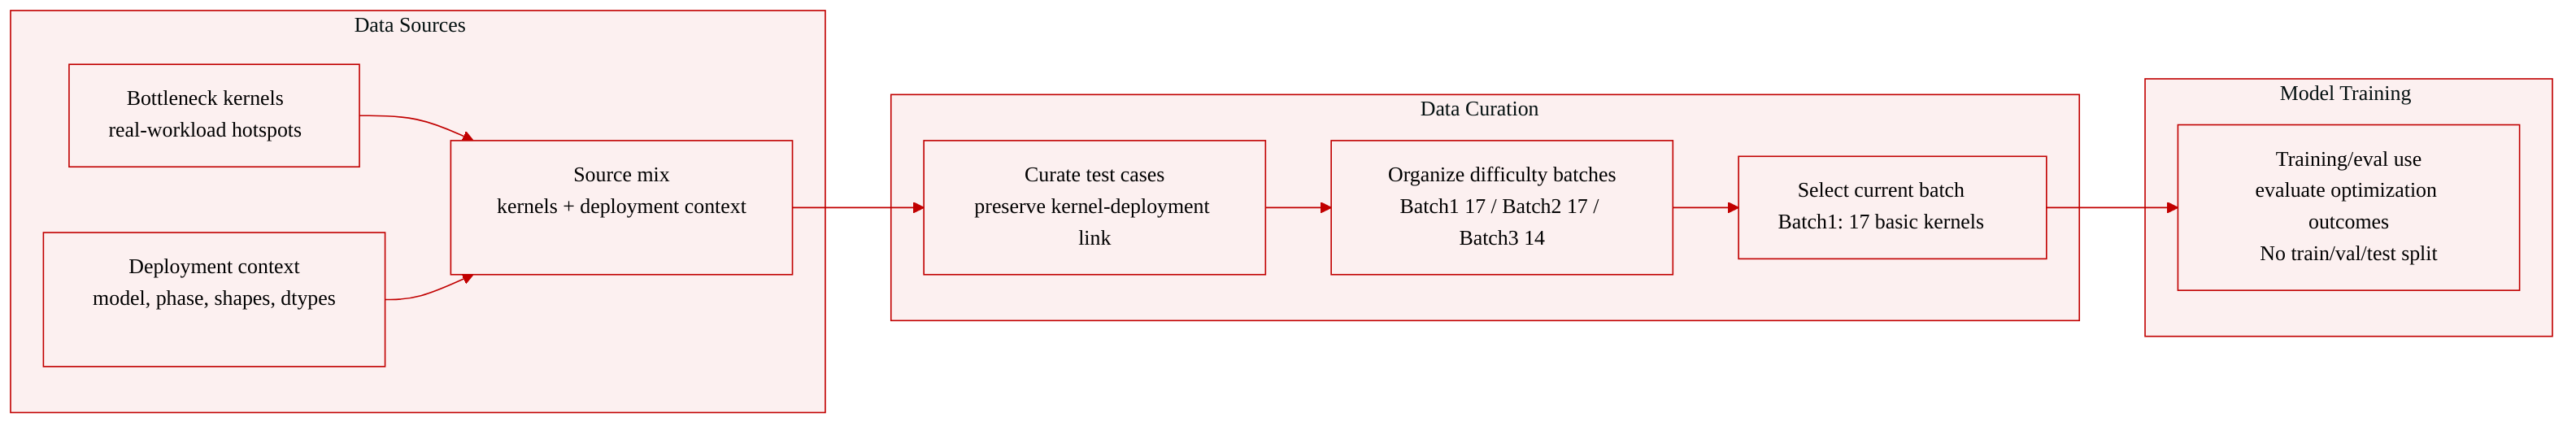
The authors describe AscendGYM as a kernel optimization benchmark for Ascend NPUs, not as a model training dataset. It is designed to evaluate whether model-harness systems can improve existing kernel implementations under consistent rules.
Dataset composition and sources
- The benchmark has four main components:
- Kernel optimization task set and test cases
- AscendForge evaluation environment and tools
- Evaluation metrics
- Shared evaluation workflow
- Tasks are sourced from bottleneck kernels that have substantial performance impact in real workloads.
- Tasks are organized into three difficulty batches:
- Batch 1: 17 basic kernels, focused on memory access optimization
- Batch 2: 17 tasks covering multistep computations such as normalization and quantization
- Batch 3: 14 tasks covering complex attention mechanisms and fused computations, including sparse attention
- The current paper evaluates only the 17 Batch 1 tasks. Batch 2 and Batch 3 results are left for future updates.
Test case design and metadata
- Each test case preserves the connection between kernel inputs and deployment context.
- The context includes:
- Target model
- Execution phase
- Hardware and parallelism configurations
- Tensor shapes
- Data types
- Computational parameters
- For example, the AddRMSNorm task captures residual addition followed by RMS normalization in a forward pass of Qwen3-0.6B inference.
- That test case uses:
- Prefill phase
- No quantization
- Eager execution
- Single NPU
- Tensor parallelism 1
- BF16 precision
- Batch size 1
- Input sequence length 32 tokens
- Profiling metadata for AddRMSNorm reports 56 invocations per forward pass, accounting for 8.77 percent of total computation time and ranking among the top-5 kernels by cumulative execution time.
Processing and evaluation usage
- The benchmark provides tasks and execution feedback to assess optimization outcomes.
- Evaluation covers multiple deployment cases, best achievable performance for specific shapes and scenarios, and optimization cost.
- These dimensions are used to characterize:
- Cross-case applicability
- Shape specialization
- Optimization efficiency
- No training split or data mixture ratio is reported, because AscendGYM is used for evaluation rather than model training.
Method
AscendGYM organizes kernel optimization tasks into three batches of increasing difficulty, progressing from largely independent kernels to multistage fusion and complex execution coordination. Batch 1 focuses on memory access optimization for basic kernels, Batch 2 covers multistep computations like normalization and quantization, and Batch 3 targets complex attention mechanisms and fused computations. Task selection prioritizes bottleneck kernels with substantial performance impact in real workloads. Each test case preserves the connection between kernel inputs and their deployment context, including the target model, execution phase, hardware and parallelism configurations, and resulting tensor shapes. This context links measured kernel speedups to corresponding operator invocations in real workloads, aligning evaluation with deployment requirements.
AscendGYM includes AscendForge, an Ascend-native execution sandbox for candidate compilation, correctness checking, and performance measurement. Building on SandboxFusion, AscendForge introduces adapters that manage dependencies among host-side registration, device-side kernels, the target system-on-chip, and custom kernel packages, enabling compilation and Python interface binding for NPU devices.
As shown in the figure below:
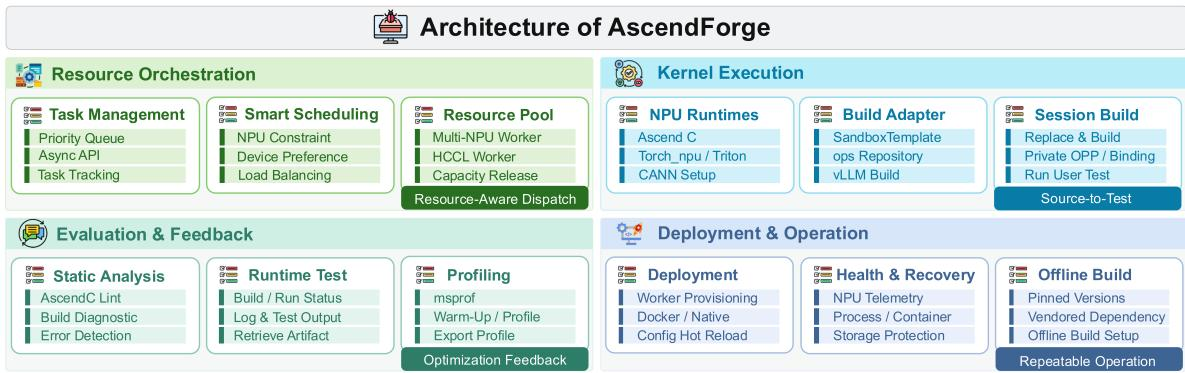
AscendForge comprises four layers for kernel building and execution, resource scheduling, development feedback, and deployment and operations. The Execution and Build Layer supports Ascend C and Python NPU execution backends, with adapters for CANN kernel repositories and projects like vLLM Ascend. It automates source submission, compilation and installation, Python interface binding, and test execution. The Resource Orchestration Layer manages evaluation requests through a scheduling proxy, task queues, and multiple execution nodes, allocating resources according to the required NPU count and device model. The Development Feedback Layer integrates static code analysis and performance profiling, returning build logs, correctness results, and performance measurements to help agents diagnose errors and guide the next optimization iteration. The Deployment and Operations Layer provides hardware health monitoring, configuration hot reloading, and automatic process recovery.
The authors leverage joint performance-budget metrics, standalone performance and budget metrics, and a reliability metric to evaluate optimization outcomes and the resources required to achieve them.
The Speedup-Token Score (STS) jointly measures the best speedup achieved within a token budget and the token consumption required to obtain improvements:
STS=final performance gain100log2Sn−penalty for delayed improvements50k=1∑nBmaxBkΔgkHere, Bmax>0 is the token budget, n is the number of candidate evaluations completed within that budget, and Bk denotes the cumulative token consumption when evaluation k completes. Sk denotes the best correctness-validated speedup available after evaluation k, relative to the reference implementation. The incremental log-speedup gain is Δgk=log2Sk−log2Sk−1.
The Cost-to-Gain (CTG) metric measures the additional token consumption required to increase speedup by a specified fraction relative to a reference checkpoint:
CTG(δ;r)=r≤k≤nSk≥(1+δ)Srmin(Bk−Br),δ∈{0.01,0.05,0.10}Lower CTG indicates greater token efficiency.
For standalone performance, AscendGYM reports GM Speedup and the fastp metric. The fastp metric measures the fraction of tasks for which a correct implementation achieves a speedup strictly greater than p:
fastp=N1i=1∑N1[Si,ni>p],p≥1GM Speedup summarizes performance across tasks using their geometric mean:
GM Speedup=(i=1∏NSi,ni)1/NBudget metrics measure optimization cost using cumulative and mean token consumption, LLM interaction rounds, and wall-clock time. Reliability metrics include the Candidate Pass Rate, which measures how reliably an LLM or agent harness produces correct candidates, and the Task Pass Rate, which measures the fraction of attempted tasks with at least one candidate that passes correctness checks.
AscendGYM supports two evaluation modes: model-harness evaluation, which evaluates a model-harness pair as a complete system, and model evaluation, which runs the model with a default harness called AuraKernel.
As shown in the figure below:
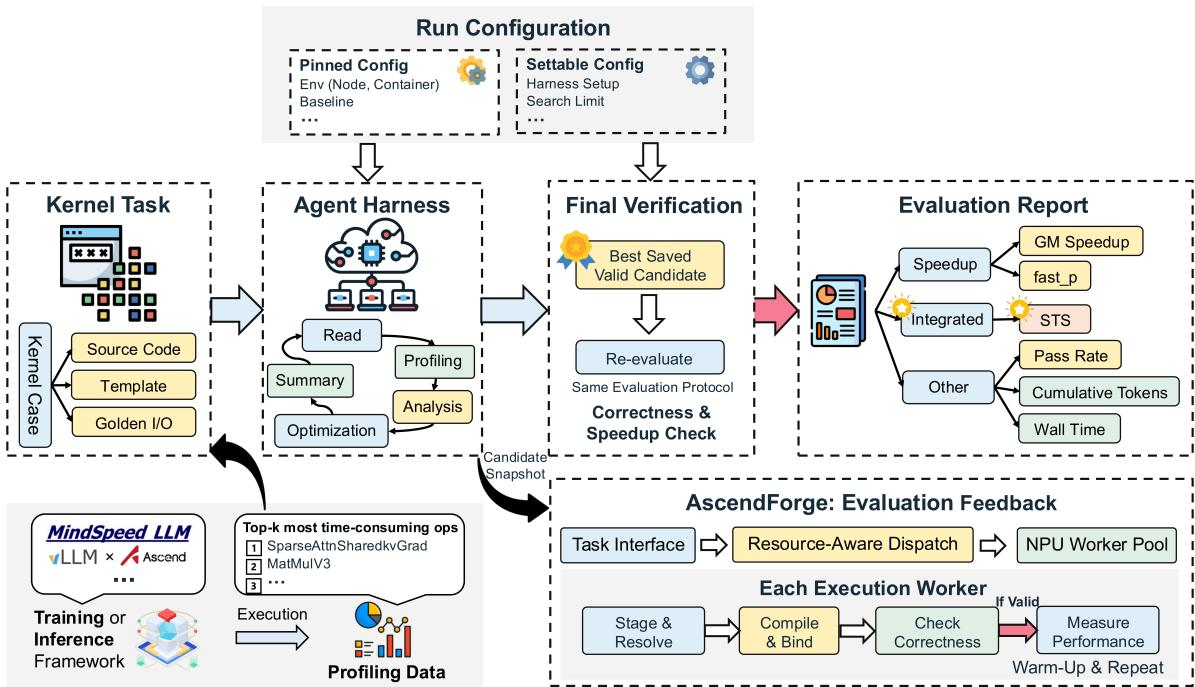
The workflow constructs kernel optimization tasks from real training and inference workloads. Profiling data from workloads running in Ascend frameworks are collected to identify the top-k bottleneck kernels. Each kernel optimization task includes the source code of the baseline, template metadata specifying input and output tensor shapes, test inputs, and reference outputs generated by the corresponding CPU implementation. To launch an evaluation, users configure the execution environment and optimization settings. AscendGYM first measures baseline performance, then enters an iterative loop of bottleneck analysis, code refinement, performance measurement, and experience summarization. Each optimized candidate is submitted to the AscendForge sandbox for compilation, Python interface binding, and correctness checks. Candidates that pass these checks are profiled, and the resulting measurements guide subsequent optimization. Search terminates when the resource budget is exhausted or the maximum iteration count is reached. The system then revalidates the best implementation and uses the performance measurements and optimization traces to compute the defined metrics.
Experiment
AscendGYM evaluates NPU kernel optimization through AscendForge sandbox execution and two modes: model-harness pairs using Claude Code, Codex CLI, and OpenCode, and model-only evaluation with the Default AuraKernel harness. Joint speedup-token and cost-to-gain metrics, along with performance, budget, and reliability measures, are used to compare approaches under 10M, 20M, and 50M token budgets. The experiments show that final speedup alone hides differences in when gains are achieved and at what cost, while pass rates and aggregate speedup can diverge. Current systems mostly achieve modest improvements, with around 70% of model-harness combinations below 1.2x geometric mean speedup, and the warm Default configuration performs best in model evaluation, indicating that both harness configuration and budget constraints materially affect optimization outcomes.