Command Palette
Search for a command to run...
Repenser en impulsions : atténuer les hallucinations dans les MDLM grâce à un décodage sensible aux étapes
Repenser en impulsions : atténuer les hallucinations dans les MDLM grâce à un décodage sensible aux étapes
Résumé
Les avancées récentes dans les modèles de langage multimodaux à diffusion (MDLM) ont montré de fortes capacités de modélisation globale grâce à un raffinement itératif. Nous observons que l'incertitude du masque suit une tendance globale à la baisse au cours du débruitage itératif, tandis que quelques étapes de débruitage présentent des pics d'entropie localisés étroitement associés aux hallucinations. Nous soutenons que les étapes anormales peuvent être identifiées en mesurant l'écart d'entropie de chaque étape de débruitage par rapport à sa fenêtre temporelle voisine. Nous émettons l'hypothèse que l'engagement discret des jetons écarte l'information distributionnelle aux positions masquées, limitant ainsi l'interaction continue entre les sémantiques candidates et le contexte pendant les pics d'entropie. Dans cet objectif, nous présentons StepRefine, une stratégie de décodage prête à l'emploi qui exploite le contexte sémantique pour parvenir à un débruitage fiable. Le cœur de notre méthode repose sur une commutation sensible aux étapes entre le débruitage discret et le raffinement latent. Le modèle utilise des plongements pondérés par les probabilités aux étapes de pic d'entropie afin de préserver des hypothèses de raisonnement diverses et effectue plusieurs cycles de raffinement continu. Parallèlement, un contrôleur de raffinement surveille la stabilité distributionnelle afin de réduire les boucles inutiles et de ramener le modèle au débruitage discret standard. Grâce à des expériences approfondies, StepRefine démontre une atténuation significative des hallucinations sur différents MDLM et sur des bancs d'essai multimodaux.
One-sentence Summary
Researchers from Monash University, Cornell University, UC Santa Cruz, Northeastern University, and the University of Minnesota propose StepRefine, a plug-and-play decoding strategy for multimodal diffusion language models that uses step-aware switching between discrete denoising and probability-weighted latent refinement to preserve diverse reasoning hypotheses, while a refinement controller monitors distributional stability to reduce unnecessary loops and mitigates hallucinations across multimodal benchmarks.
Key Contributions
- The paper identifies that mask uncertainty in multimodal diffusion language models generally decreases during denoising, but localized entropy spikes at specific steps are closely associated with hallucinated tokens.
- StepRefine is introduced as a plug-and-play, training-free decoding strategy that detects entropy spike steps via local trend deviation, switches to probability-weighted embedding-based latent refinement to preserve diverse reasoning hypotheses, and uses a refinement controller to monitor distributional stability and reduce unnecessary refinement loops.
- Experiments across four multimodal diffusion language model backbones and multiple benchmarks covering general reasoning, hallucination, mathematical, and scientific reasoning show that StepRefine improves accuracy, significantly mitigates hallucination, and can be combined with existing acceleration methods.
Introduction
Diffusion language models generate text through iterative denoising instead of left-to-right decoding, and multimodal variants called MDLMs use bidirectional attention over visual and textual inputs to support perception and reasoning. However, MDLMs still produce hallucinations, and existing decoding strategies mostly optimize inference efficiency through cache reuse or scheduling, while quality-oriented methods adjust token commitment but treat uncertainty uniformly across denoising steps. The authors analyze step-wise uncertainty dynamics and find that rare entropy spike steps, where masked-sequence entropy sharply increases locally, are strongly associated with hallucinated final tokens. They propose StepRefine, a plug-and-play decoding method that detects these entropy spikes from local temporal trends and switches to latent probabilistic refinement before discrete decoding, improving reliability across multiple MDLM backbones and reasoning benchmarks.
Method
The authors propose StepRefine, a step-aware decoding strategy designed to mitigate hallucinations in Masked Discrete Language Models. The framework operates by detecting specific instability points during the iterative denoising process and applying targeted refinement to stabilize token commitments.
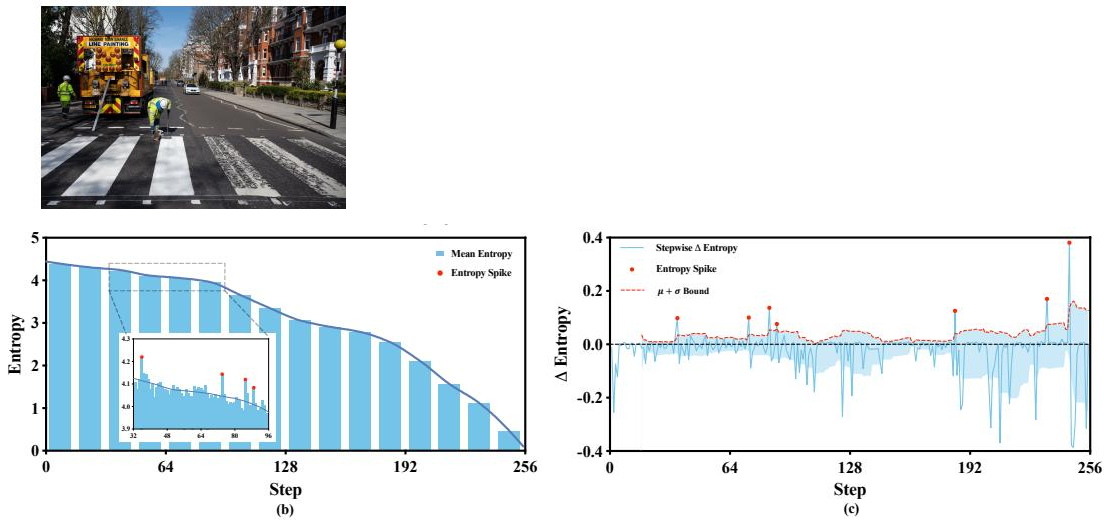
The first core module is entropy spike detection. During iterative denoising, the mean mask entropy over masked positions generally decreases as the model gradually commits tokens. However, this decrease is not strictly monotonic. A small number of steps exhibit sharp local increases that break the overall trend, which the authors identify as entropy spikes. The mean mask entropy at each denoising step t is defined as the expected Shannon entropy of the predictive distribution over masked positions:
Hˉt=Ei∼U(Mt)[−v∈V∑pti(v)logpti(v)]where U(Mt) denotes the uniform distribution over the masked positions Mt. A step is classified as an entropy spike if its entropy change exceeds a local upper bound:
ΔHˉt≜Hˉt−Hˉt+1,Tspike≜{t∣ΔHˉt>μt+σt}where μt and σt represent the mean and standard deviation of the w preceding stepwise entropy changes along the denoising trajectory.
Refer to the figure below for a detailed characterization of these entropy spikes across decoding steps.
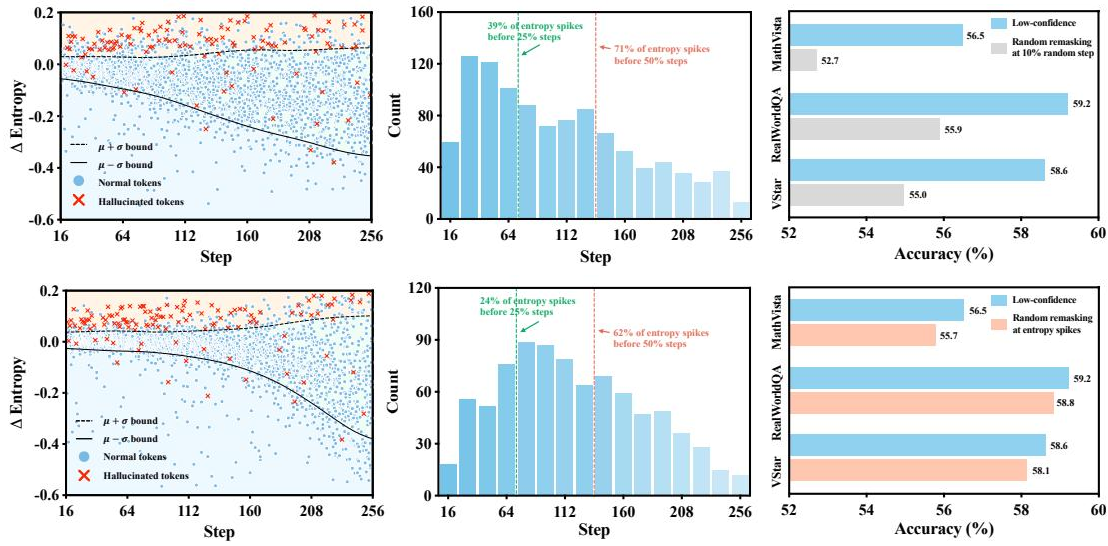
The analysis reveals that while entropy spike steps are relatively rare, approximately 80% of hallucinated tokens are located within these spike regions. Furthermore, these spikes are non-uniformly distributed, concentrating mainly in the early to middle stages of the denoising process when many positions remain masked and the available context is insufficient. At these specific steps, confidence signals become less discriminative, making discrete commitment decisions less reliably grounded in the current contextual information and rendering standard low confidence remasking less effective.
To address this vulnerability, the authors introduce a step-aware mode switch with adaptive termination. This strategy alternates between standard discrete decoding and latent refinement, gated by the previously defined spike detection criterion. At each denoising step t, the model first performs a standard forward pass to obtain the predictive distribution and the corresponding spike indicator. For ordinary steps where t∈/Tspike, the process follows the standard discrete decoding path.
Conversely, at entropy spike steps where t∈Tspike, StepRefine activates latent refinement. This involves performing iterative forward passes within the same denoising step before discrete decoding. Let p~t,0i≜pti denote the initial distribution from the standard forward pass. At each refinement iteration k≥1, the framework constructs a probability-weighted embedding from the previous distribution and replaces the mask embedding as input to the next forward pass:
e~t,ki=Ev∼p~t,k−1i[e(v)],i∈Mt,k=1,2,…Together with the forward pass, this equation forms a recursive refinement loop. It carries distributional information about candidate tokens into subsequent forward passes, allowing the soft embedding to interact with the visual-textual context prior to discrete decoding.
To prevent unnecessary computational overhead, a refinement controller monitors the change between consecutive predictive distributions. At iteration k≥1, the change is computed as the average Kullback-Leibler divergence at masked positions:
DKL(k)=Ei∼U(Mt)[DKL(p~t,ki∥p~t,k−1i)]The iterative refinement terminates once DKL(k)<ϵ, where ϵ>0 is a predefined stability threshold. The final refined distribution is then utilized for standard discrete decoding and remasking to commit tokens. To maintain a fixed inference budget, the additional forward passes required for refinement are counted against the total denoising budget T. If k refinement passes are utilized at step t, the subsequent iteration begins at index t−1−k rather than t−1, ensuring the total number of forward passes remains constant.
Experiment
The authors evaluate StepRefine on four multimodal diffusion language models across diverse reasoning, hallucination, math, and science benchmarks. Main results show that entropy-spike-aware refinement improves over baseline and existing training-free decoding strategies across backbones, while preserving speedups from acceleration methods. Qualitative analysis and ablations confirm that refinement sharpens predictions at unstable steps, and that moderate calibration windows with adaptive scheduling and termination are more effective than fixed alternatives. The method also remains robust across remasking strategies, generation lengths, and step budgets.
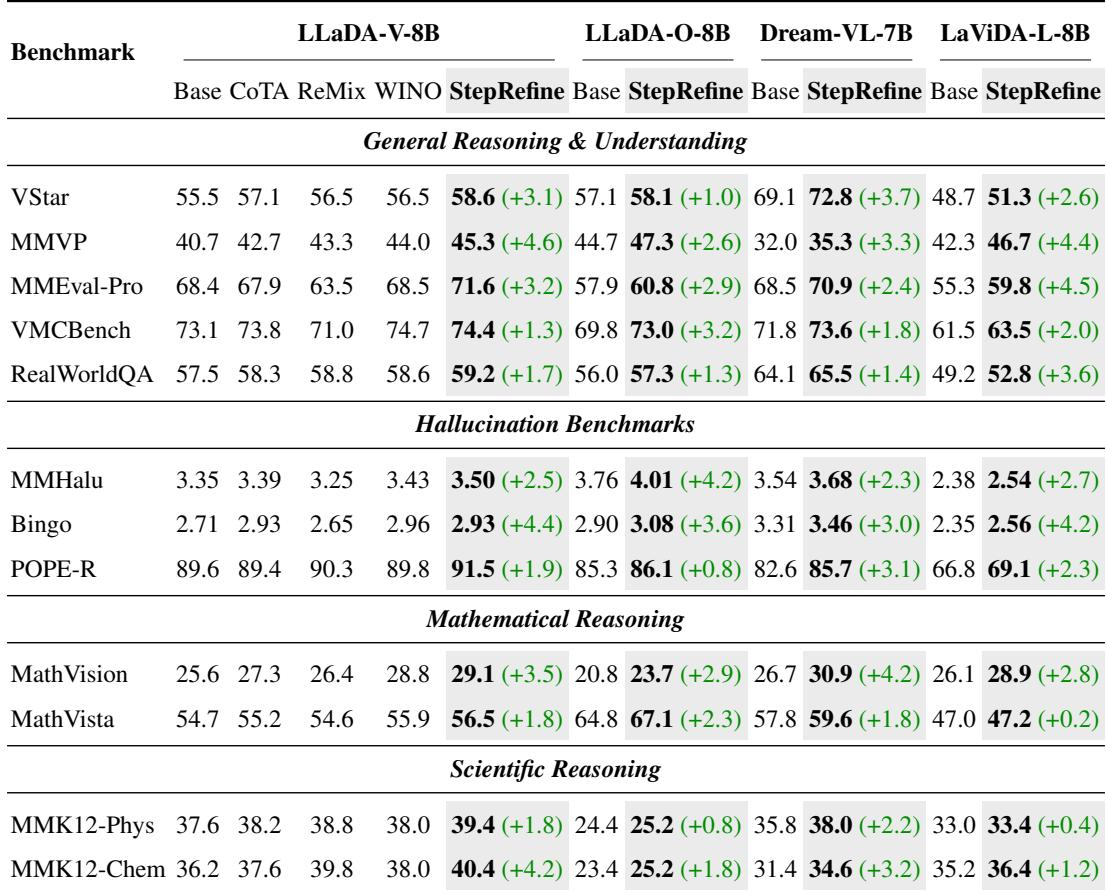
StepRefine consistently improves benchmark performance over the baseline and competing training-free decoding strategies across multiple MDLM backbones. It matches or outperforms CoTA, ReMix, and WINO on general reasoning benchmarks and also yields positive gains on hallucination benchmarks. The similar average improvements across backbones suggest that the entropy-spike-aware refinement is robust across MDLMs rather than specific to any single model. StepRefine improves average general reasoning accuracy over the baseline and matches or outperforms CoTA, ReMix, and WINO on every evaluated general reasoning benchmark. Hallucination benchmarks also benefit, with gains on MMHalu and Bingo, and every backbone shows positive average improvements ranging from 2.3 to 2.8 percentage points.
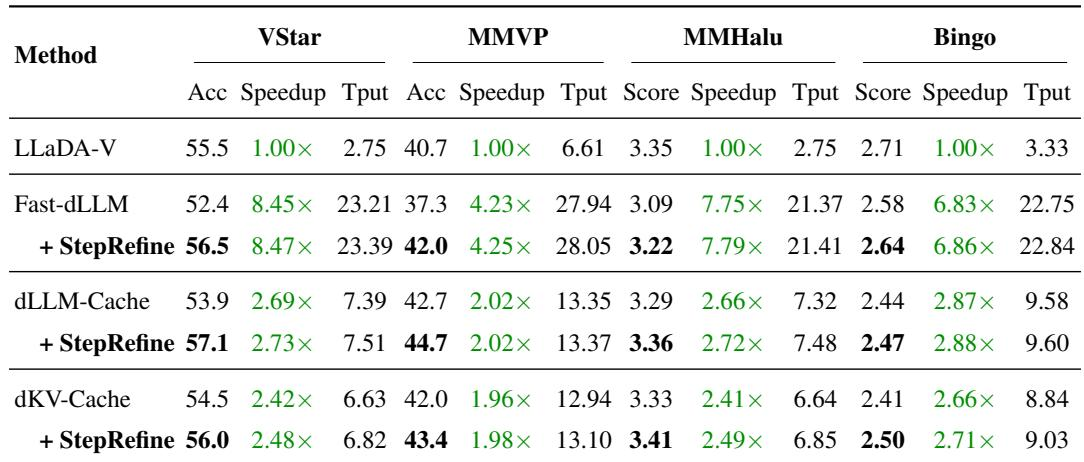
StepRefine integrates with existing diffusion language model acceleration methods while preserving their speedups. Across the reported accelerators, adding StepRefine improves benchmark accuracy and hallucination scores, with throughput preserved or slightly higher. The results show that refinement is broadly compatible with aggressive and cache-based decoding strategies. Adding StepRefine to Fast-dLLM improves VStar and MMVP accuracy and hallucination scores while keeping speedup near its accelerated baseline and throughput slightly higher. For dLLM-Cache, StepRefine improves all reported accuracy and score metrics, with speedup and throughput nearly unchanged. Across acceleration methods, StepRefine maintains or slightly increases throughput and shows gains on VStar and MMHalu, supporting compatibility without hidden latency.
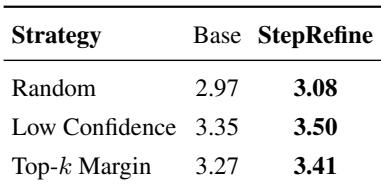
StepRefine consistently improved MMHalu over the baseline under all three evaluated remasking strategies, with the Low Confidence setting showing the largest StepRefine score. Results across two generation lengths and three step budgets also show consistent gains, supporting robustness to decoding settings without per-setting tuning. StepRefine outperformed the baseline under Random, Low Confidence, and Top-k Margin remasking strategies. Low Confidence remasking produced the highest StepRefine score among the reported strategy rows. Reported MMHalu gains across generation lengths and step budgets were positive in all six configurations, ranging from +1.8% to +4.8%.
StepRefine is evaluated across multiple masked diffusion language model backbones, where it consistently improves general reasoning and hallucination benchmarks over the baseline and competing training-free decoding strategies, indicating robustness beyond any single model. Additional experiments show that StepRefine integrates with existing acceleration and cache-based decoding methods, preserving or slightly improving throughput while retaining accuracy gains. Ablations over remasking strategies, generation lengths, and step budgets further confirm consistent improvements without per-setting tuning.