Command Palette
Search for a command to run...
MIRIX-2.0 : Système de mémoire multi-agents
MIRIX-2.0 : Système de mémoire multi-agents
Wei-Chieh Huang Weizhi Zhang Jiayan Nan Peng Xia Yu Wang
Résumé
La mémoire à long terme permet aux agents LLM de se personnaliser, de rester cohérents et de réutiliser ce qui a fonctionné auparavant. Les mémoires paramétriques nécessitent un entraînement, la consolidation peut perdre définitivement des détails, et conserver chaque enregistrement laisse un stock croissant à interroger. Nous présentons MIRIX-2.0, un système de mémoire multi-agents conçu pour être à la fois pratique, précis et efficace. Il est le plus précis des systèmes comparés sur quatre des cinq bancs d'essai de questions-réponses. Il atteint 91,4 % sur LoCoMo et 72,6 % sur LongMemEval-S, où il devance le meilleur modèle de référence de 14,3 points, et avec AutoDream désactivé, il gagne 31,0 et 22,0 points par rapport à HyperMem sur les questions-réponses documentaires à saut unique et à sauts multiples. En tant que mémoire procédurale, il obtient le succès moyen le plus élevé parmi les méthodes de mémoire comparées sur ALFWorld et WebShop, et atteint 49,2 % sur MetaClaw-Bench, contre 44,0 % pour la bibliothèque de compétences de MetaClaw. Six agents de mémoire typés conservent des enregistrements complets en tant que système d'enregistrement, et un hypergraphe de provenance indexe les enregistrements épisodiques et sémantiques avec des cadres n-aires qui citent leurs lignes. La récupération s'exécute sous des budgets explicites, de sorte que les preuves qu'une question inspecte ne croissent pas avec l'historique. AutoDream fusionne les ancres dupliquées hors du chemin d'écriture sans réécrire aucun enregistrement, et distille les sessions de tâches en compétences. Avec AutoDream désactivé, MIRIX-2.0 répond plus rapidement que HyperMem sur les cinq bancs d'essai chronométrés. Il ne nécessite aucun ajustement fin, fonctionne avec des modèles fermés et ouverts, et son code est public.
One-sentence Summary
MIRIX AI researchers introduce MIRIX-2.0, a practical multi-agent memory system whose six typed agents, provenance hypergraph with n-ary frames, budgeted retrieval, and AutoDream consolidation achieve 91.4% on LoCoMo, 72.6% on LongMemEval-S, leading the strongest baseline by 14.3 points, the highest mean success among compared memory methods on ALFWorld and WebShop, and 49.2% on MetaClaw-Bench, all without fine-tuning.
Key Contributions
- MIRIX-2.0 is a multi-agent memory system in which six typed memory agents keep complete records as the system of record, and a provenance hypergraph indexes episodic and semantic records with n-ary frames that cite their source rows; retrieval runs under explicit budgets, so the evidence a question inspects does not grow with history.
- AutoDream consolidates outside the write path by merging duplicate anchors without rewriting any record and distilling task sessions into procedural skills.
- MIRIX-2.0 is the most accurate of the compared systems on four of five QA benchmarks, reaching 91.4% on LoCoMo and 72.6% on LongMemEval-S, where it leads the strongest baseline by 14.3 points. Its procedural memory achieves the highest mean success on ALFWorld and WebShop and reaches 49.2% on MetaClaw-Bench, and with AutoDream disabled it answers faster than HyperMem on all five timed benchmarks.
Introduction
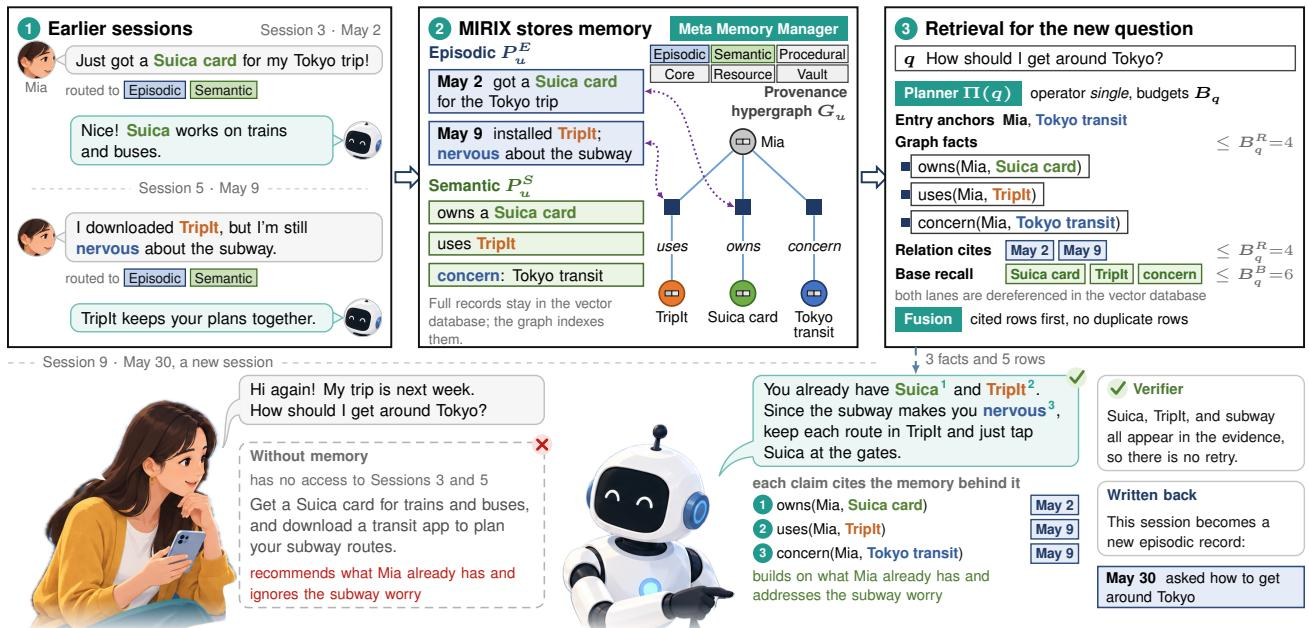
Large language model agents now operate across long sessions, so memory systems must preserve details for personalization, consistency, and reuse. Prior approaches tend to trade off competing requirements: consolidation-based memories are compact but discard details, retrieval-over-everything memories become expensive and noisy, graph and hypergraph memories often weaken n-ary relations or depend on top-down summaries, and parametric memories require training and exclude closed models. The authors introduce MIRIX-2.0, a multi-agent memory system that keeps complete typed records as the system of record and uses a provenance hypergraph only as a bounded index, with deterministic retrieval budgets and offline consolidation that merges duplicate anchors or distills skills without rewriting stored evidence.
Method
The authors design MIRIX-2.0 to separate storage from indexing, ensuring practical deployment, high accuracy, and bounded efficiency. The system operates on two distinct layers. A typed evidence plane stores complete memories and serves as the immutable system of record. A provenance hypergraph indexes the entities, events, relations, roles, and times within those memories, with every fact explicitly citing its source records. Three distinct paths operate on these layers to handle memory formation, retrieval, and consolidation.
As shown in the figure below:
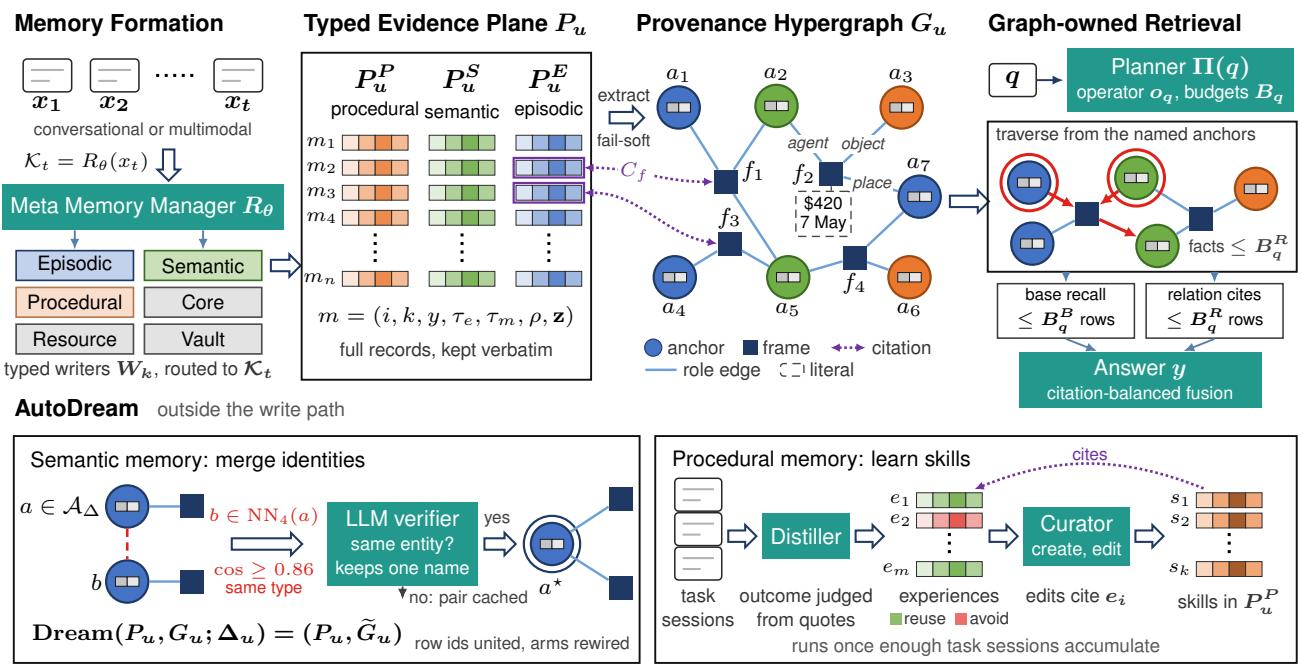
The write path begins with a Meta Memory Manager that routes each conversational or multimodal input to a subset of memory types, including Core, Episodic, Semantic, Procedural, Resource, and Knowledge Vault. Each type has a dedicated writer that produces a structured record. An evidence record is formally represented as:
m=(i,k,y,τe,τm,ρ,z)where i is an immutable row identifier, k is the memory type, y is the stored text, τe and τm are the event and mention times, ρ records source provenance, and z holds search embeddings. The system commits the record to the vector database before graph construction begins, ensuring that a failed graph write never rolls back a stored memory.
The second half of the write path transforms episodic and semantic records into graph structure. For each user, the system maintains a hypergraph defined as:
Gu=(Au,Fu,Eu)This structure consists of entity anchors Au, reified fact frames Fu, and role-typed incidence edges Eu. An anchor stores a canonical name, entity type, name embedding, and the identifiers of the episodic and semantic rows that mention it. To resolve entity identity, the system uses registry-guided canonicalization, where approximate nearest-neighbor search retrieves existing anchors, and a language model makes a conservative same-entity decision.
For each record, an extractor produces n-ary frames:
f=(p,{(rj,aj)}j=1df,ℓf,τe,τm,Cf)where p is a canonical predicate, rj is the open-vocabulary role of anchor aj, ℓf maps literal attributes to their values, and Cf is the set of cited vector-database records. Frame identity rules differ for semantic and episodic memory. A semantic frame is identified by a hash of the user, predicate, and sorted role-anchor keys, allowing repeated support for the same durable claim to accumulate citations. An episodic frame adds an occurrence key to ensure distinct events do not collapse merely because they are worded similarly.
The read path treats retrieval as the construction of a bounded evidence set rather than open-ended similarity search. Episodic and semantic candidates must enter through the graph, and the vector database dereferences only the identifiers selected by graph traversal.
Refer to the framework diagram:
A deterministic planner maps a query to a structured plan:
Π(q)=(oq,Pq,Cq,Yq,Tq,BqB,BqR)where oq is the query operator, Pq holds relation families, Cq holds non-relational constraints, Yq holds expected answer types, Tq holds temporal constraints, and BqB and BqR cap the base-recall and relation-cited rows. The query embedding recalls anchors by name, and the selected anchors open two bounded evidence lanes. The base-recall lane yields identifiers directly associated with the anchors, while the relation-citation lane seeds an indexed adjacency lookup over incident frames. Each relation-lane frame receives an additive fact score evaluating relation, entity, constraint, type, temporal, and role compatibility. Finally, a citation-balanced fusion reranks rows from both lanes, and an answer-time verification step checks the drafted answer against the evidence ledger.
The third path, AutoDream, runs outside the critical write path to consolidate memory without altering the underlying evidence store. It treats semantic and procedural memory in opposite ways.
As shown in the figure below:
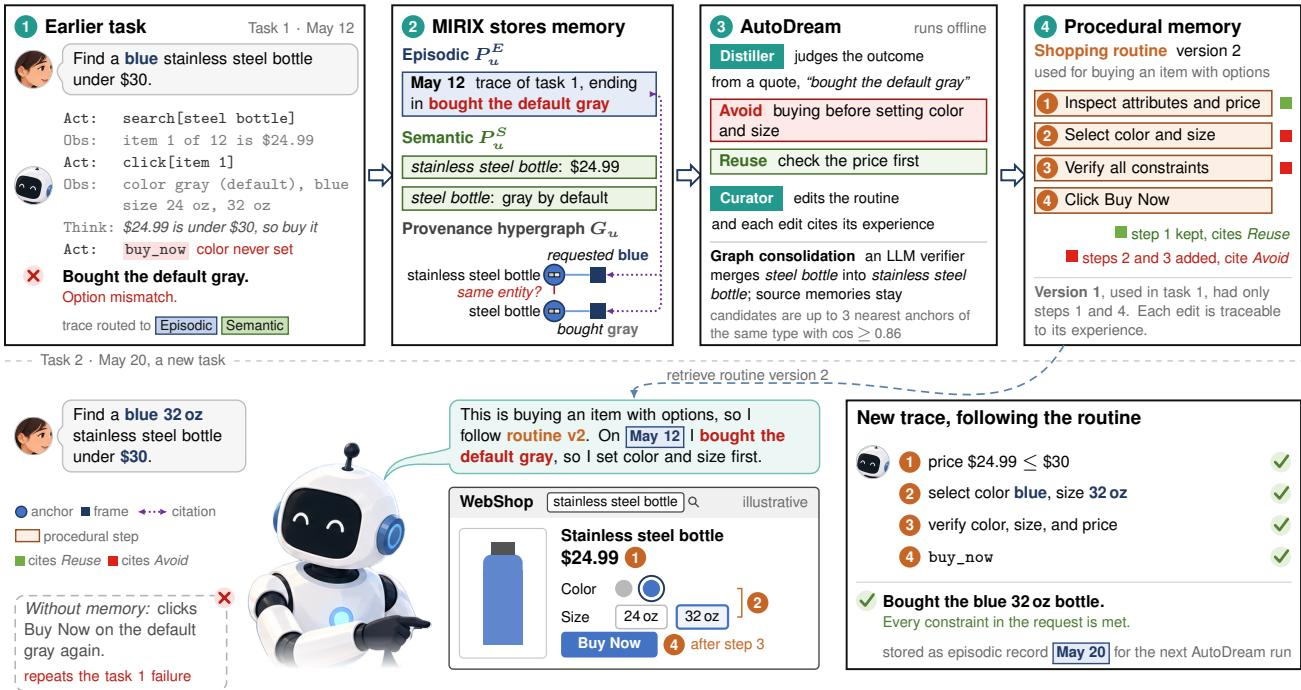
For semantic memory, AutoDream refines identities under the contract:
Dream(Pu,Gu;Δu)=(Pu,G~u)where Δu is the newly written semantic frontier. The system generates candidate anchor pairs based on embedding similarity and type matching, and a language model verifies if they denote the same entity. A confirmed merge unions the row identifiers, sums mention counts, and rewires role-typed frame arms, leaving the original evidence records completely unchanged.
For procedural memory, AutoDream distills task sessions into reusable skills. A distiller judges the outcome of pending sessions from transcript quotes, marking experiences as lessons to reuse or mistakes to avoid. A curator then turns these experiences into skills in the procedural store. The curator can create, edit, or delete a skill, and any edit must cite the specific experiences behind it. This ensures that a cited step in a skill can be traced back through its experiences to the original quoted sessions, maintaining strict source fidelity while refining the operational strategies of the agent.
Experiment
The evaluation compares MIRIX-2.0 variants (flat M0, graph-only M1, and full M2) on user-memory tasks for conversational recall, document QA, and personalized generation, and on agent-memory tasks including ALFWorld, WebShop, and MetaClaw-Bench. Graph indexing and AutoDream consistently improve conversational recall, especially for multi-hop and temporal questions, and MIRIX-2.0 leads most document QA and personalization benchmarks, though it trails baselines on DetectiveQA. For agent memory, learned procedures raise success on held-out interactive tasks and improve MetaClaw-Bench scores with several backbones, but gains vary by task type and backbone, and retrieved procedures can sometimes interfere. Efficiency results show faster answering than HyperMem with graph indexing but slower ingestion than flat memory, while procedural memory can reduce steps without reliably reducing token costs.
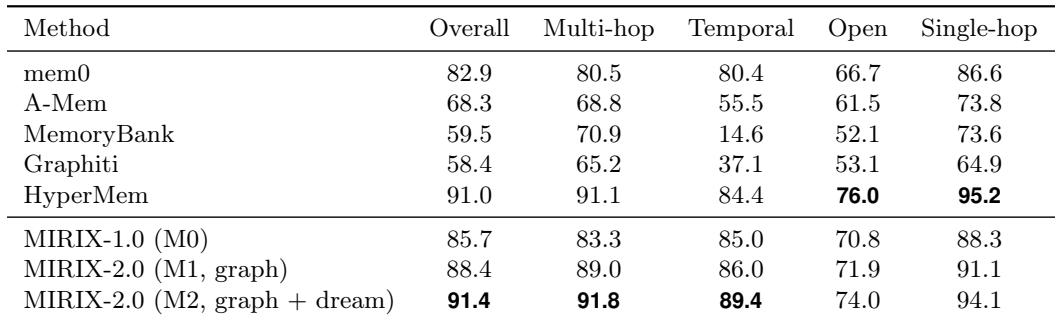
The LoCoMo results show a consistent ordering for the system variants: flat vector memory scores lowest, graph retrieval improves overall accuracy, and semantic AutoDream yields the strongest configuration. Improvements vary by question type; graph retrieval helps multi-hop questions most, while AutoDream adds gains across categories including temporal recall. The full configuration leads overall and in temporal and multi-hop recall, whereas HyperMem remains stronger on open-domain and single-hop questions. Flat vector memory, graph retrieval, and graph plus AutoDream configurations rank in increasing order on overall LoCoMo accuracy. Graph retrieval contributes the largest benefit on multi-hop questions, while semantic AutoDream adds further gains across categories including temporal recall. The full system surpasses HyperMem overall, with its advantage concentrated in temporal and multi-hop recall, while HyperMem retains higher open-domain and single-hop scores. Among external baselines, HyperMem is the strongest, and several other baselines perform particularly poorly on temporal questions.
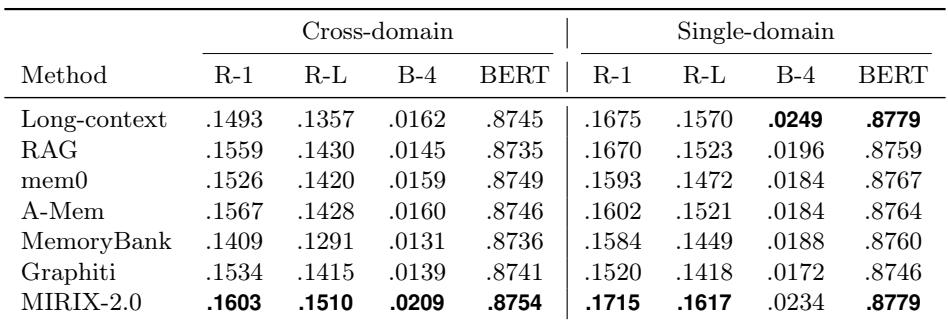
On MemoryCD review summarization, no single method leads every metric. Long-context performs best in single-domain evaluation and also leads cross-domain BLEU-4, while cross-domain ROUGE-1, ROUGE-L, and BERTScore are split among A-Mem, RAG, and mem0 with small differences. MemoryBank and Graphiti are generally weaker, with Graphiti lowest on all single-domain metrics. Long-context ranks first on all single-domain metrics: ROUGE-1, ROUGE-L, BLEU-4, and BERTScore. Cross-domain performance is more mixed, with A-Mem leading ROUGE-1, RAG leading ROUGE-L, Long-context leading BLEU-4, and mem0 leading BERTScore.
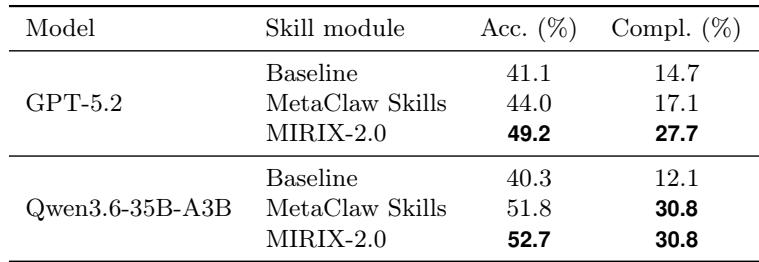
On MetaClaw-Bench Part I, agent memory improves accuracy and completion over a no-memory baseline for both tested backbones. MIRIX-2.0 achieves the highest accuracy with both backbones, while the completion gains are largest with MIRIX-2.0 on GPT-5.2. MetaClaw Skills alone already accounts for much of the gain on Qwen3.6-35B-A3B. MIRIX-2.0 leads accuracy on both backbones, lifting GPT-5.2 from the low forties to just under fifty percent and Qwen3.6-35B-A3B from the low forties to just over fifty percent. Completion improves most strongly with MIRIX-2.0 on GPT-5.2, while Qwen3.6-35B-A3B reaches the same completion level with MetaClaw Skills and MIRIX-2.0.
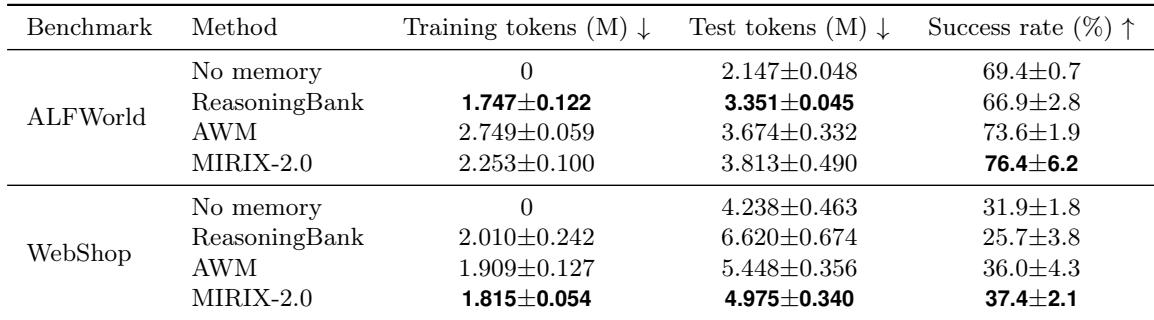
Across ALFWorld and WebShop, procedural memory methods increase test token use relative to no memory. On WebShop, MIRIX-2.0 achieves the highest mean success while using the fewest training and test tokens among the memory methods. On ALFWorld, MIRIX-2.0 records the highest test token use among memory methods even though its mean step count is lower. On WebShop, MIRIX-2.0 has the lowest training and test token use among the memory methods and the highest mean success. On ALFWorld, MIRIX-2.0 uses more test tokens than any other memory method despite requiring fewer interaction steps on average. Compared with no memory, test token use rises on both ALFWorld and WebShop, so procedural memory does not automatically reduce token cost.
Across four evaluations, memory components are assessed on long-form memory QA (LoCoMo), review summarization (MemoryCD), agent task execution (MetaClaw-Bench), and interactive decision-making (ALFWorld/WebShop). The experiments validate that graph retrieval and semantic consolidation improve LoCoMo accuracy, especially for temporal and multi-hop questions, while no single method dominates MemoryCD summarization and long-context is strongest in single-domain evaluation. Agent memory reliably improves task accuracy and completion, with MIRIX-2.0 leading most settings, but procedural memory increases token usage rather than reducing cost.