Command Palette
Search for a command to run...
Avancées en infographie agentique
Avancées en infographie agentique
Résumé
L'infographie repose sur le code. Les agents fondés sur de grands modèles de langage (LLM) peuvent désormais générer du code graphique et l'affiner de manière itérative grâce à divers retours. Cette capacité ouvre la voie à un paradigme potentiellement nouveau de l'infographie, où les algorithmes graphiques sont de plus en plus conçus autour de systèmes agentiques afin d'automatiser des tâches de complexité croissante. Au cours des dernières années, la recherche sur l'infographie agentique s'est rapidement étendue à un large éventail de tâches. Cette croissance rapide rend de plus en plus difficile pour les revues de littérature manuelles de suivre le rythme des nouveaux développements. Parallèlement, des idées similaires sont souvent décrites avec une terminologie différente selon les tâches, ce qui complique encore l'élaboration d'une compréhension systématique du domaine. Dans ce rapport, nous relevons ces défis à travers deux contributions. Premièrement, nous proposons une taxonomie unifiée pour caractériser les systèmes agentiques dans diverses tâches d'infographie. Deuxièmement, nous développons un système de littérature agentique capable d'aider les chercheurs à analyser à grande échelle les articles existants et nouvellement publiés. Sur la base de ces contributions, nous analysons les tendances de recherche émergentes et discutons des défis ouverts concernant la coordination des agents et des outils entre les tâches graphiques, la conception d'interfaces et de représentations pour la collaboration humain-agent, le maintien de la planification et de l'affinement sur de longs horizons, et l'évaluation fiable des systèmes graphiques interactifs.
One-sentence Summary
Researchers from the University of Texas at Austin, Stanford University, Simon Fraser University, University of California, Berkeley, and University of Cambridge introduce a unified taxonomy for characterizing agentic systems across diverse computer graphics tasks and an agentic literature system for analyzing papers at scale, and they examine emerging research trends and open challenges in coordinating agents and tools across graphics tasks, designing interfaces and representations for human-agent collaboration, sustaining long-horizon planning and refinement, and reliably evaluating interactive graphics systems.
Key Contributions
- Introduces a unified taxonomy for agentic computer graphics systems, organizing work along user input, base model, harness, and graphics interface and tooling.
- Develops an agentic literature system that discovers candidate papers, annotates them with the taxonomy, and adaptively retains records to support analysis of existing and newly published papers at scale.
- Uses the taxonomy and system to analyze agentic graphics approaches across 2D graphics, static 3D assets, and dynamic 3D assets, while identifying recurring design patterns, evaluation practices, and open challenges in planning, human-agent collaboration, and reliable evaluation.
Introduction
Recent advances in large language models have enabled agentic graphics systems that use code generation, tool use, and environment feedback to automate complex graphics workflows such as 3D asset creation, animation, and simulation. This matters because it shifts graphics authoring from manual specification of procedures toward language-guided iterative control over visual content. However, the rapidly growing literature spans communities that use different terminology for functionally similar planning and feedback components, making synthesis and comparison difficult. The authors address this by introducing a unified taxonomy across specification, base model, harness, and graphics interface and tooling, and by building an agentic literature survey system that searches, reads, and annotates papers with this taxonomy to support structured comparisons and trend analysis.
Dataset
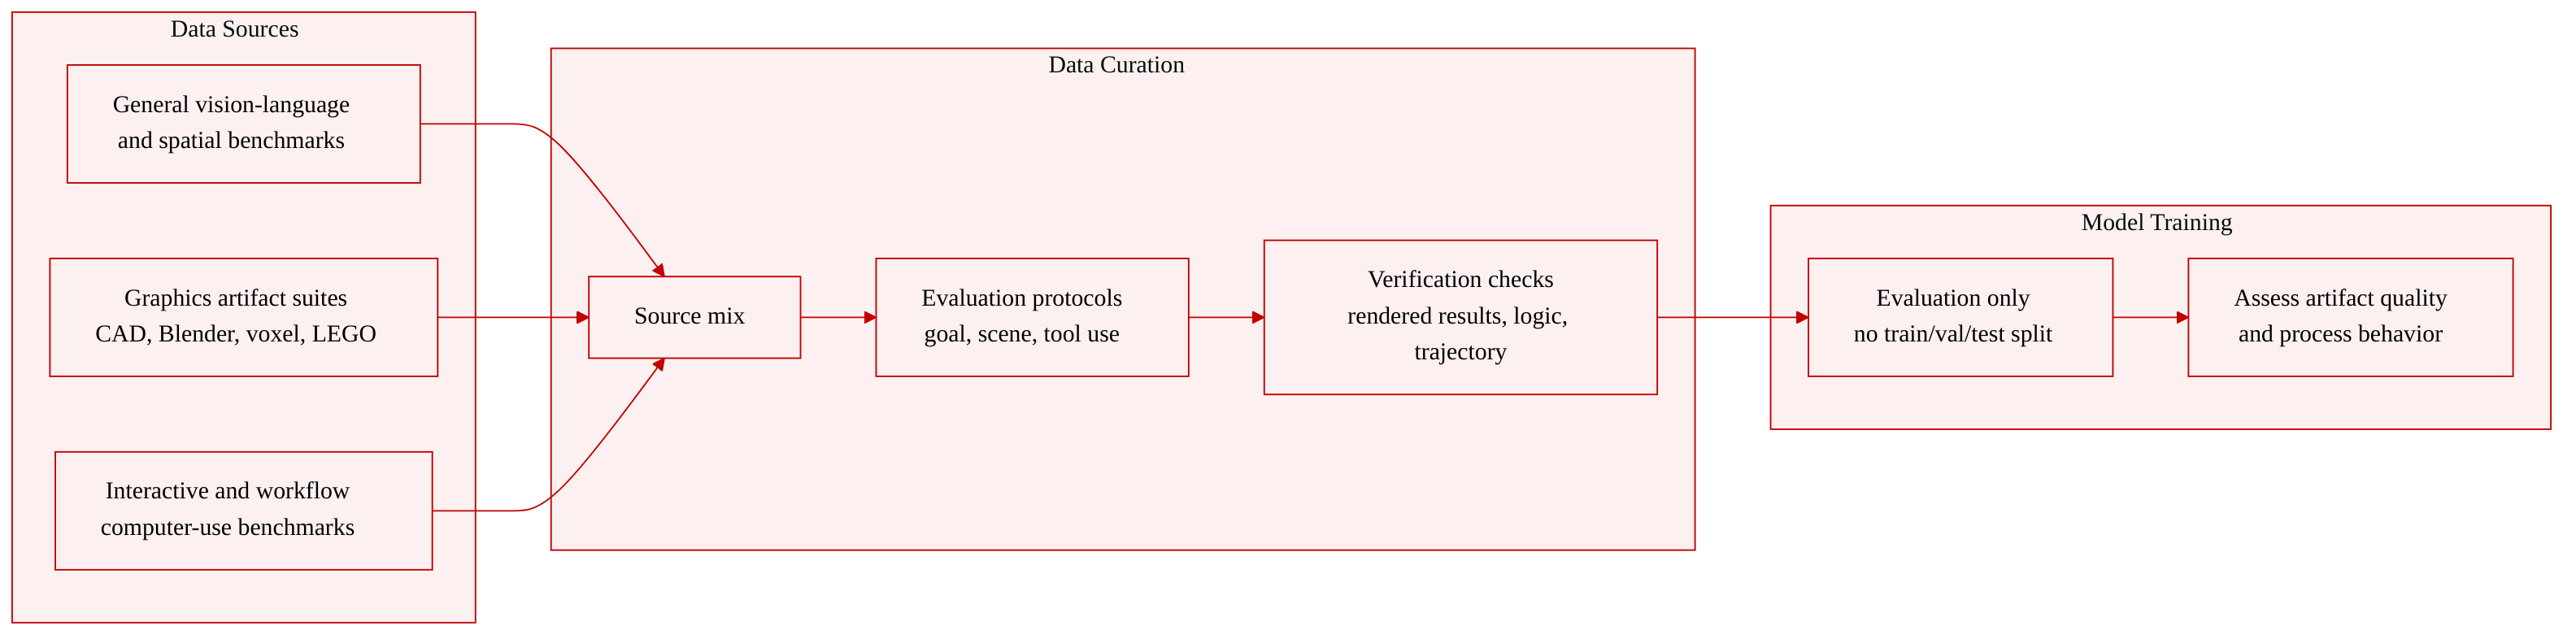
The authors use this section as a survey of evaluation benchmarks for agentic graphics, not as a description of a single new training dataset.
- Composition and sources: The benchmarks come from general-purpose vision-language and spatial understanding datasets; graphics artifact evaluation suites; CAD, program, motion, and reconstruction benchmarks; sequential editing and workflow benchmarks; and interactive computer-use benchmarks.
- Key benchmark groups:
- Spatial understanding: Benchmarks probe relative position, distance and direction, limited-view inference, multi-view integration, 3D grounding, geometric reasoning, semantic understanding, and multi-step action planning in 3D scenes.
- Graphics artifact evaluation: CAD-Assistant evaluates CAD generation from varied inputs; 3DCodeBench, Voxel-CodeBench, and BrickBench evaluate translation of textual and visual specifications into Blender programs, voxel representations, and LEGO assemblies; MoVer verifies motion graphics through spatio-temporal logic predicates; IR3D-Bench evaluates image-to-3D reconstruction for localization, appearance, and semantics.
- Sequential and workflow evaluation: BlenderGym evaluates scene edits such as object placement, lighting, material, and geometry with verification at each stage; Op-CAD evaluates long CAD operation sequences; VIGA evaluates iterative code-render-inspect refinement; BVB and 4DCodeBench evaluate video-to-3D with perceptual similarity and spatio-temporal consistency.
- Agentic interaction and coordination: ALE and OSWorld evaluate computer-use agents on long-horizon GUI and software tasks; 3DHarnessBench and SceneActBench evaluate reconstruction under single-view, multi-view, arbitrary viewpoint, and full 3D interaction settings; CADWorld evaluates computer-use agents on mechanical CAD workflows.
- Processing and format: The authors describe evaluation protocols rather than data preprocessing. Agents interpret a graphics goal, reason about the current scene or state, use graphics-specific tools or programs, and produce an artifact or action sequence. Verification may occur at each edit stage, through rendered results, through logic predicates, or by analyzing the interaction trajectory.
- How the data is used: The benchmarks are used for evaluation only, not as training data. They assess final artifact quality and process-level behavior, including geometric validity, material correctness, artistic quality, semantic understanding, and action planning or coordination.
- Missing dataset statistics: The text does not report dataset sizes, training/validation/test splits, mixture ratios, filtering rules, cropping strategies, or metadata construction details.
Method
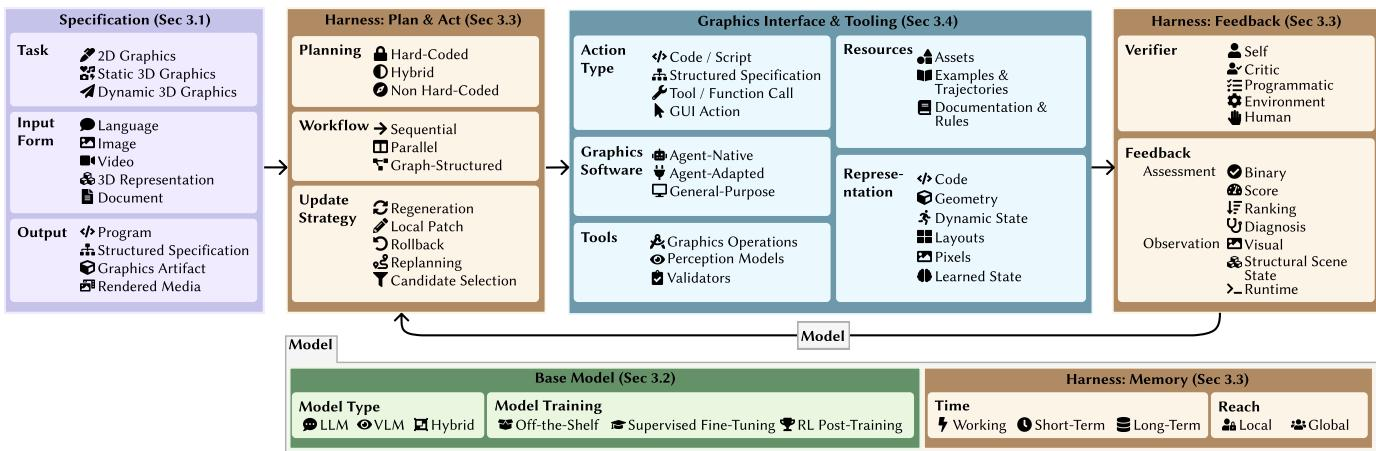
The authors introduce a unified taxonomy that organizes the shared structure of agentic graphics systems into a design space with four dimensions: specification, base model, harness, and graphics interface and tooling.
The specification dimension describes the task requirements, available inputs such as language, images, or 3D representations, and expected outputs like programs or rendered media. Given these requirements, the base model serves as the decision-making component. It can be a large language model, a vision-language model, or a hybrid system, and may be used off-the-shelf or adapted via supervised fine-tuning or reinforcement learning. The harness connects the base model to the graphics interface, coordinating planning, execution, feedback, and memory. It manages the workflow which can be sequential, parallel, or graph-structured, update strategies such as regeneration or local patching, and verification mechanisms including self-verification or programmatic checks. Finally, the graphics interface and tooling dimension provides the necessary operations, resources, and representations. Actions can take the form of code scripts, structured specifications, tool calls, or GUI actions, executed within agent-native, agent-adapted, or general-purpose software environments.
To address the rapid growth of research in this field, the authors also develop an agentic literature survey system that automatically identifies, classifies, and curates relevant papers using the proposed taxonomy.
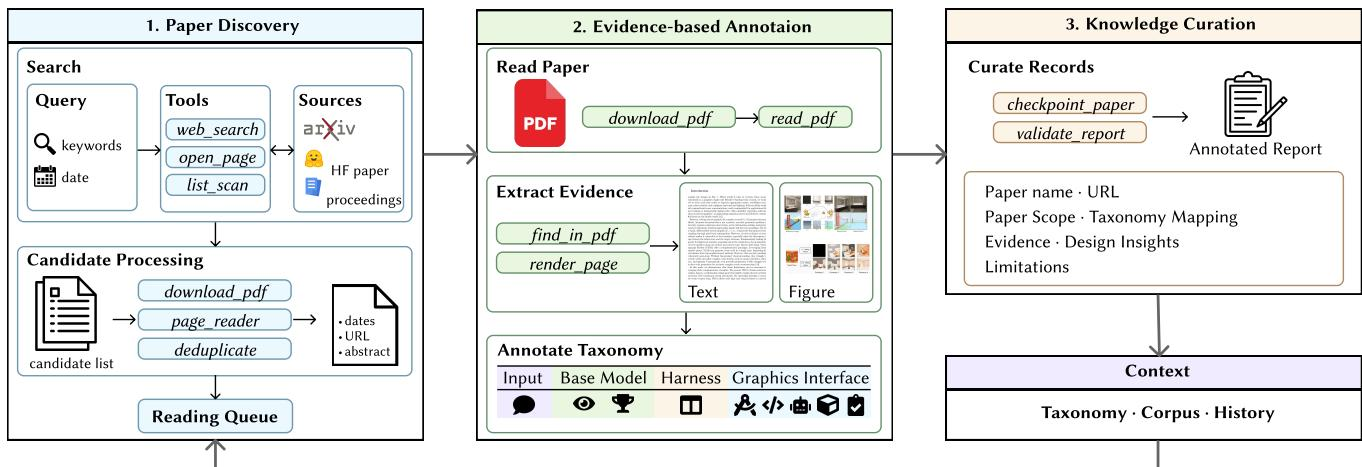
This system operates through three main stages. First, in paper discovery, the agent scans publication listings and searches the web to build a candidate list, iteratively refining queries and prioritizing full-text reading. Second, during evidence-based annotation, the agent reads the text and inspects figures of selected papers to gather supporting evidence before assigning taxonomy labels. Finally, the knowledge curation stage maintains a curated record of paper versions and annotations, verifying that required fields are present and labels adhere to the taxonomy, allowing subsequent runs to resume from unresolved candidates.
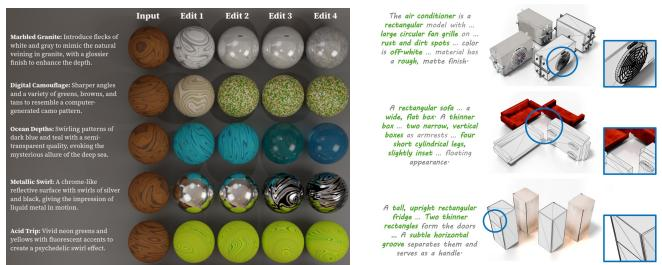
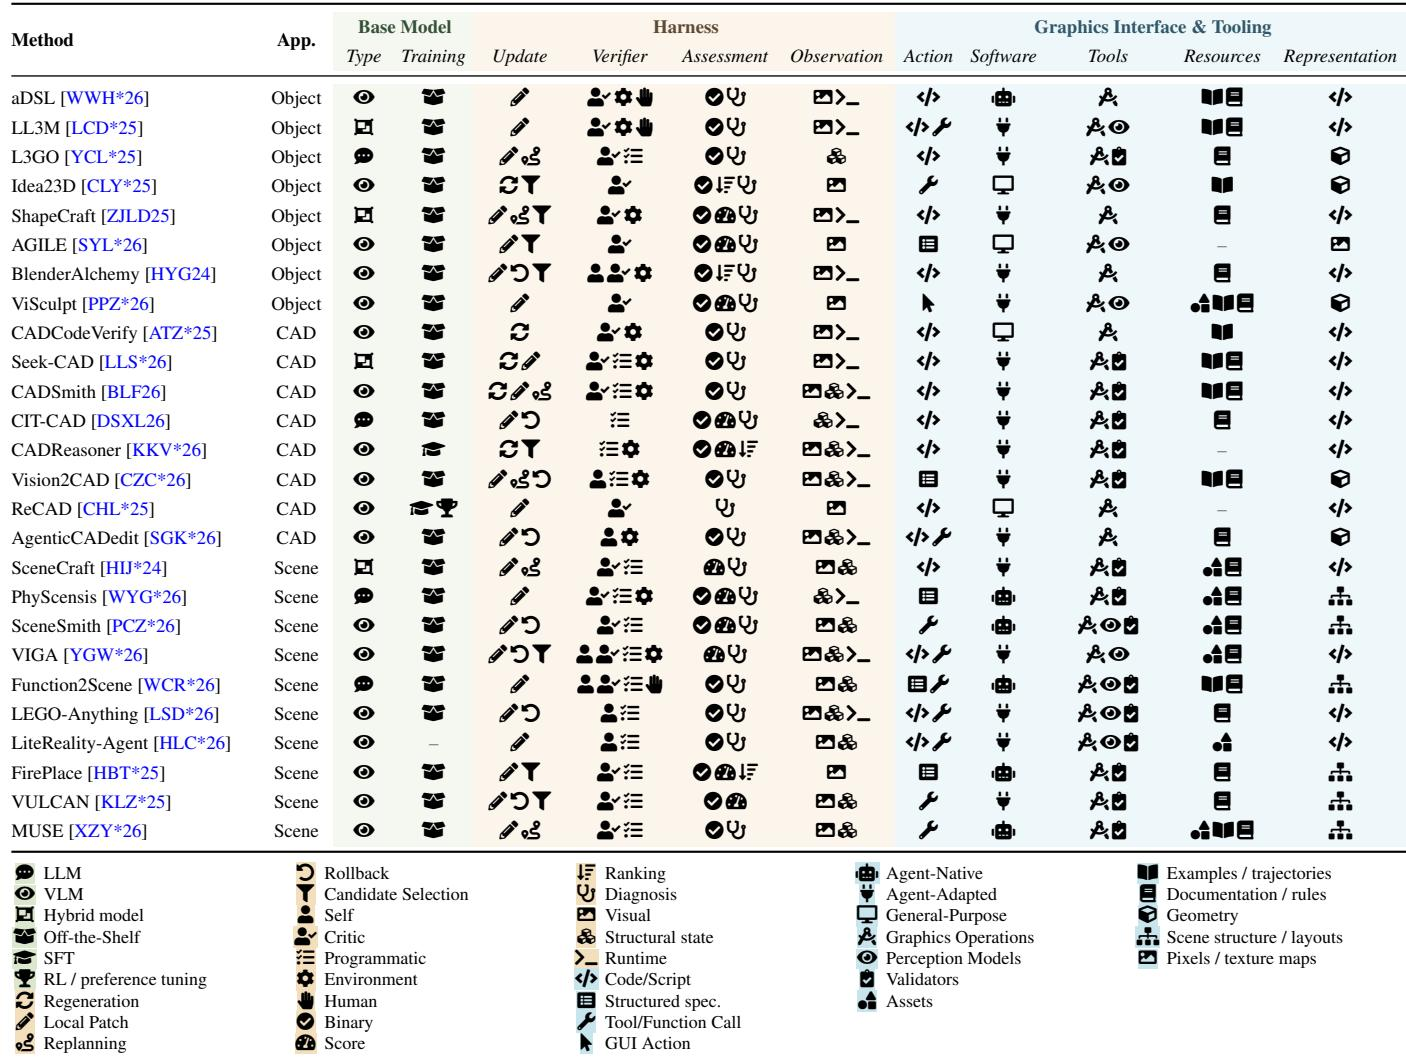
The authors illustrate how these design choices manifest in specific system architectures. For geometry construction, the LL3M method employs an iterative programming workflow where a planner divides requests into subtasks and a coder implements them using retrieved API documentation.
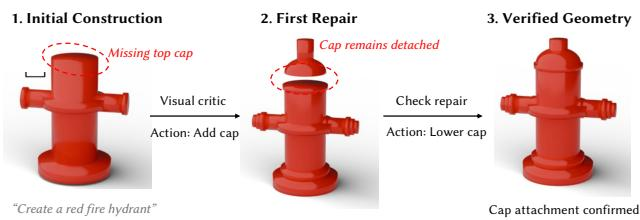
Visual feedback from a multiview critique guides code edits, and a verifier checks if defects are resolved. In texture and material modeling, systems like BlenderAlchemy use visual results to revise material programs through parameter and structural edits, while ShapeCraft utilizes the object component structure to guide texture generation.
For asset editing, the ViSculpt method decomposes language requests into localized edits on existing meshes using sculpting primitives within a GUI.
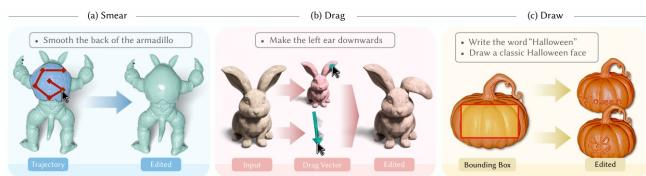
View selection and target masks constrain the operations, and before-and-after visual feedback guides the refinement of localization and brush parameters.
Experiment
The evaluation uses an agentic literature survey system with GPT-6 Astra at medium reasoning effort to compile and manually verify 350 papers from 2024 to September 2026, capturing taxonomy labels, design insights, limitations, and source locations. Case comparisons such as SubDGuide and PLAYGROUND validate how revision strategies relate to editing limits, while the systematic survey finds that visual feedback dominates but is often combined, update strategies and supporting resources differ between CAD and scene generation, and recent work shifts toward local revisions, richer feedback, and documentation. The dataset and benchmark section validates agentic graphics evaluation across spatial understanding, artifact quality, multi-step editing workflows, and interactive coordination, indicating a move from assessing only final artifacts to also analyzing process-level action trajectories.
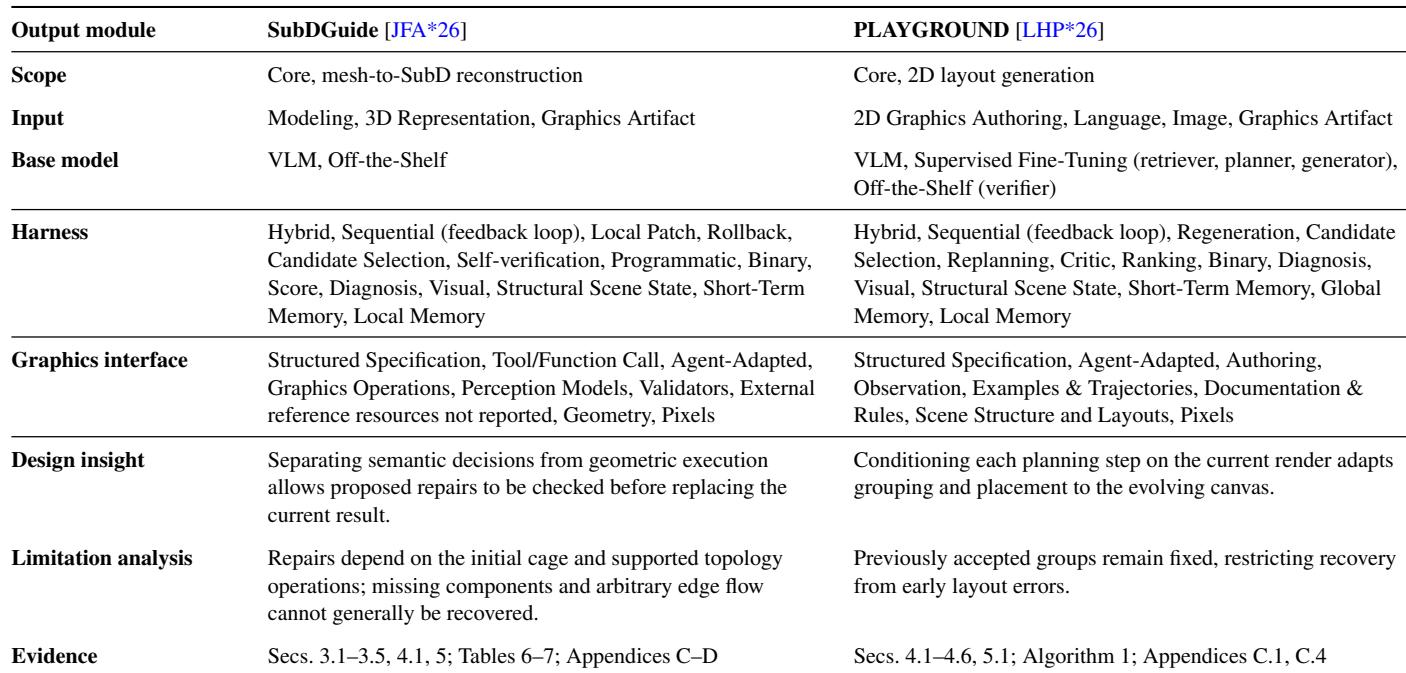
The comparison contrasts two agentic graphics systems, SubDGuide for mesh-to-SubD reconstruction and PLAYGROUND for 2D layout generation. Both use hybrid, sequential feedback loops with visual and structural scene state, but they differ in model adaptation and in how much can be revised after early decisions. Their limitations map directly to these editing scopes, with SubDGuide constrained by its initial control cage and PLAYGROUND constrained by previously accepted groups. SubDGuide separates semantic decisions from geometric execution so proposed repairs can be checked before replacing the current result, while PLAYGROUND conditions each planning step on the current render to adapt grouping and placement to the evolving canvas. The two systems share a hybrid sequential harness with candidate selection and diagnosis, but SubDGuide uses an off-the-shelf VLM whereas PLAYGROUND uses supervised fine-tuned retrieval, planning, and generation modules with an off-the-shelf verifier. Limitation analysis reflects editing behavior: SubDGuide verifies local repairs but cannot generally recover missing components or arbitrary edge flow, and PLAYGROUND revises the current group but cannot revisit previously accepted groups.
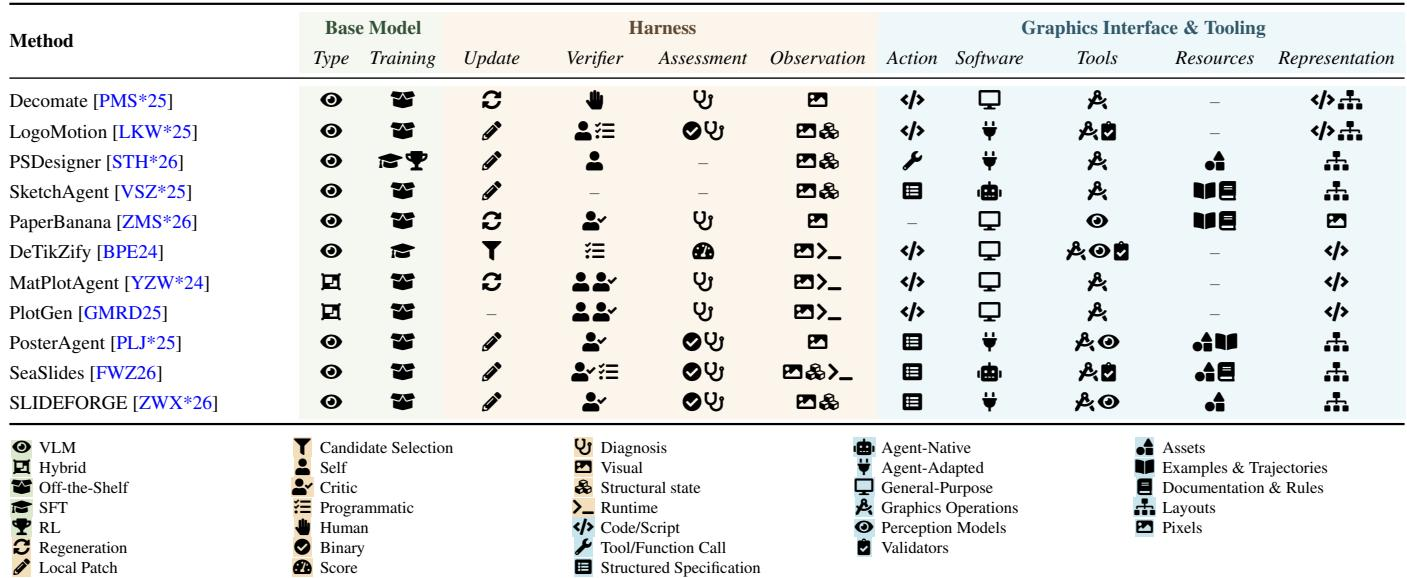
Representative 2D graphics systems cluster around structured vector graphics, interactive visual design, and scientific figure or diagram generation. These systems tend to preserve editable structure and use rendered or interactive feedback for iterative refinement. The set spans semantic vector animation, tool-based design, sequential sketching, and technical diagram workflows. Decomate and LogoMotion organize vector elements into semantic groups and animate them through code synthesis. PSDesigner and SketchAgent support editable visual work through Photoshop tool use and sequential language-driven sketch actions. PaperBanana is cited for generating methodology diagrams and scientific plots through specialized agents.
The survey compares static 3D asset modeling methods across object, CAD, and scene tasks, focusing on how they generate, refine, and verify outputs. Iterative refinement with execution or visual feedback is common, but CAD and scene approaches more often add deterministic checks, constraints, or solvers to preserve geometric validity and spatial coherence. The comparison highlights a shift from purely visual critique toward mixed feedback signals such as bounding-box observations, kernel measurements, and learned critics. Object geometry construction methods vary in grounding: some use multiview visual critique, while others rely on bounding-box observations, connectivity checks, or explicit assembly relations. Material modeling approaches guide graph construction or program edits through rendered outputs, and several refine parameters or textures with optimization after structural decisions are made. CAD and scene modeling methods tend to augment visual inspection with deterministic geometric checks, constraints, or solvers to maintain validity and spatial coherence.
Dynamic 3D asset modeling systems share editable, often programmatic representations but differ mainly in how they ground intent and how feedback drives revision. Articulation methods rely on construction checks, visual motion references, or physical simulation, while animation methods vary in temporal structure and the controls targeted by rendered feedback. Articulation-focused methods construct parts and joints through executable APIs, with evaluation evidence ranging from explicit assembly tests to visual references and physics-based collision feedback. Animation systems use different temporal representations, such as coordinated tracks or persistent object states, and direct rendered feedback toward controls like staging, camera trajectories, or joint motion. Persistent object identity does not by itself ensure continuous physical dynamics; some systems use discrete state substitutions while others add physical attributes and simulation checks.
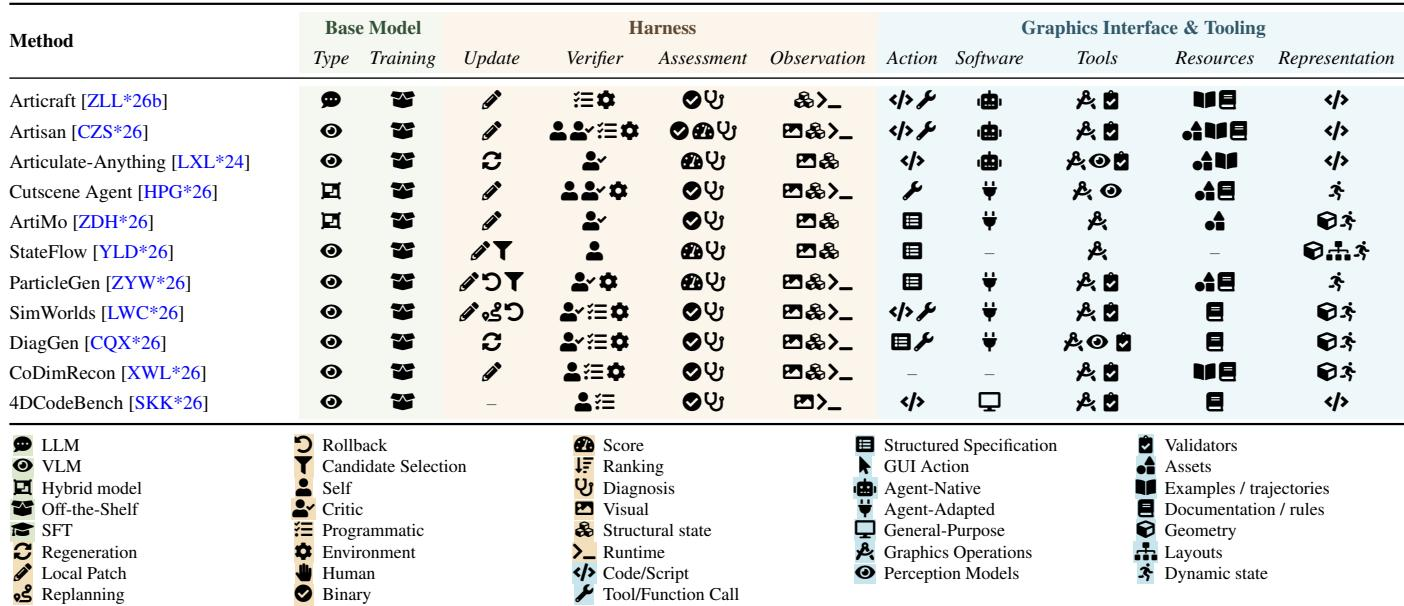
The experiments compare agentic graphics systems across 2D layout generation, static 3D asset modeling, and dynamic 3D asset modeling, focusing on how each system structures feedback, revision, and verification. These systems typically use hybrid sequential loops that combine rendered or visual observations with structural scene state, but they differ in whether they rely on off-the-shelf models or supervised fine-tuned modules and in how much earlier decisions can be revised. The main qualitative finding is that revision limitations map directly to each system's editing scope, such as SubDGuide's fixed initial control cage or PLAYGROUND's previously accepted groups, while CAD, scene, and articulation methods increasingly add deterministic checks, constraints, or solvers to preserve geometric validity and physical coherence.