Command Palette
Search for a command to run...
Wizard : un modèle de monde de jeu agentique
Wizard : un modèle de monde de jeu agentique
Yuzhe Wu Zijun Lin Yeying Jin
Résumé
Les progrès récents des modèles de monde vidéo ont permis de générer des environnements virtuels de plus en plus réalistes et interactifs, ouvrant de nouvelles possibilités de gameplay personnalisable par le joueur. Les cadres agentiques font encore progresser cette direction en découplant la logique de jeu explicite et les représentations contrôlables du monde de la génération visuelle. Cependant, les approches existantes ne prennent en charge que des configurations de jeu simples et des schémas de mouvement prédéfinis, se généralisent mal à des environnements et à des personnages inédits, et offrent une interactivité en temps réel limitée. Dans cet article, nous présentons Wizard, un modèle de monde de jeu agentique qui permet un contrôle précis en temps réel des mouvements des personnages tout en se généralisant de manière zero-shot à de nouvelles scènes, à de nouveaux personnages et à de nouvelles actions. Pour y parvenir, nous construisons un ensemble de données diversifié couvrant 750 scènes et 178 personnages, en y intégrant des informations de squelette et de géométrie comme représentations structurées. Nous exploitons ces représentations comme substituts intermédiaires pour conditionner un modèle de génération vidéo, avec un mécanisme de masquage adaptatif qui améliore l'alignement entre les signaux de conditionnement et les séquences vidéo générées. En outre, nous introduisons un cadre agentique qui maintient et met à jour explicitement les états du jeu, permettant aux joueurs de configurer librement leurs mondes virtuels et d'exercer un contrôle fin sur les mouvements des personnages tout en préservant la qualité visuelle et la cohérence du gameplay. En combinant le contrôle agentique et la génération structurée fondée sur des substituts, notre cadre ouvre de nouvelles possibilités de création de jeux pilotée par le joueur, avec une simulation du monde en temps réel, généralisable et mécaniquement cohérente.
One-sentence Summary
Researchers from Tencent, NUS, and NTU introduce Wizard, an agentic game world model that enables real-time, precise, zero-shot control over character motions across novel scenes, characters, and actions by conditioning video generation on skeleton and geometry proxies derived from a dataset of 750 scenes and 178 characters, using adaptive masking and explicit game-state updates to preserve visual quality and gameplay consistency for player-driven world creation.
Key Contributions
- The paper introduces Wizard, an agentic game world model that conditions generation on articulated skeletons and geometry maps, maintains explicit game state, and enables fine-grained player control over character motion and scene manipulation while preserving gameplay consistency.
- The paper constructs a diverse multi-source dataset covering 750 scenes and 178 characters, with aligned character skeletons and scene geometry, to provide structured visual proxies for character and scene generation.
- The method uses an adaptive attention masking mechanism based on character positions from these proxies during training and inference to improve identity preservation and video-reference alignment, supporting zero-shot generalization to unseen scenes, characters, and motions and real-time generation via causal adaptation and few-step distillation.
Introduction
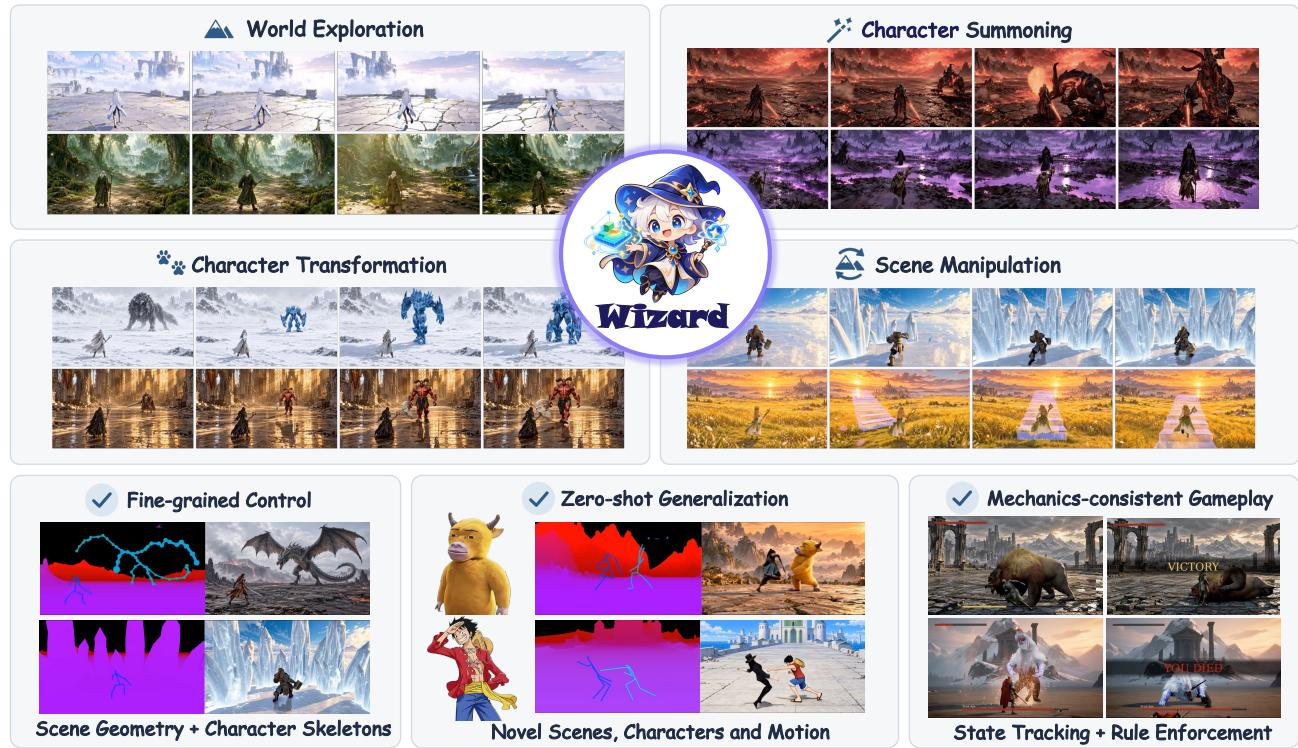
World models predict future observations from visual histories and current actions, and in games they offer a path toward interactive, personalized gameplay conditioned on player inputs. Existing approaches remain constrained in control flexibility, generalization, and real-time interaction: action-conditioned models are limited to predefined action sets, prompt-conditioned models struggle with unseen instructions, and agentic or engine-based methods often emphasize basic vehicle or locomotion control or impose scene and latency constraints. The authors propose Wizard, an agentic game world model that decouples scene construction, character animation, and gameplay logic from visual generation through structured spatial conditioning. Wizard represents scenes with depth and height geometry and characters with articulated skeletons, enabling zero-shot generalization to unseen scenes, characters, and motions while supporting real-time, mechanically consistent gameplay.
Dataset
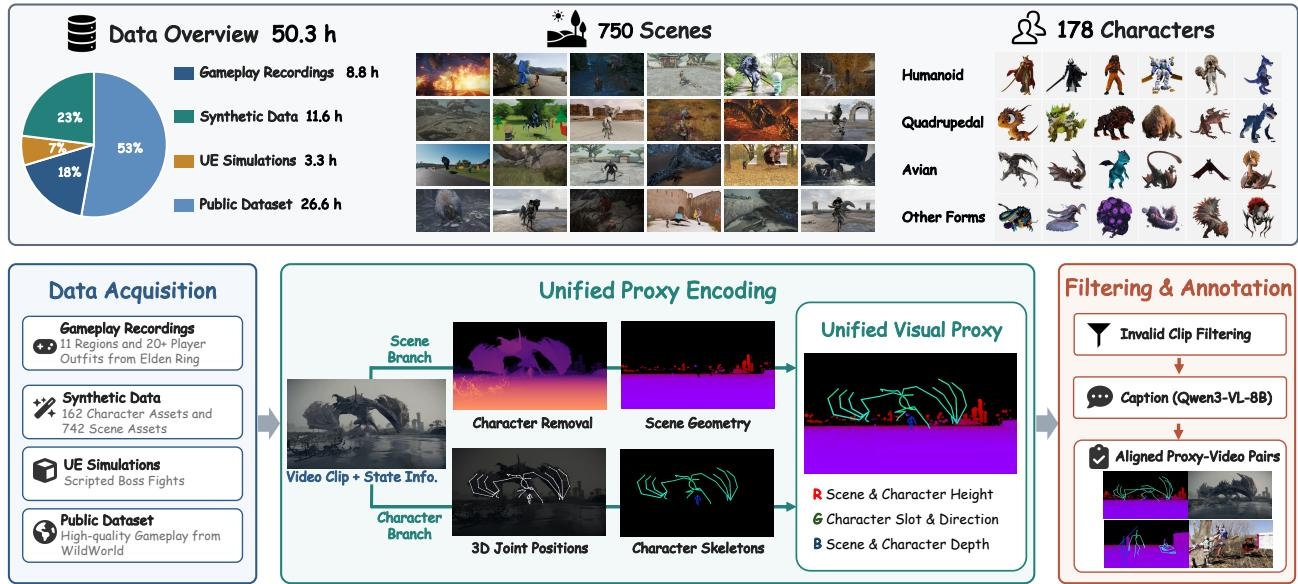
Dataset overview
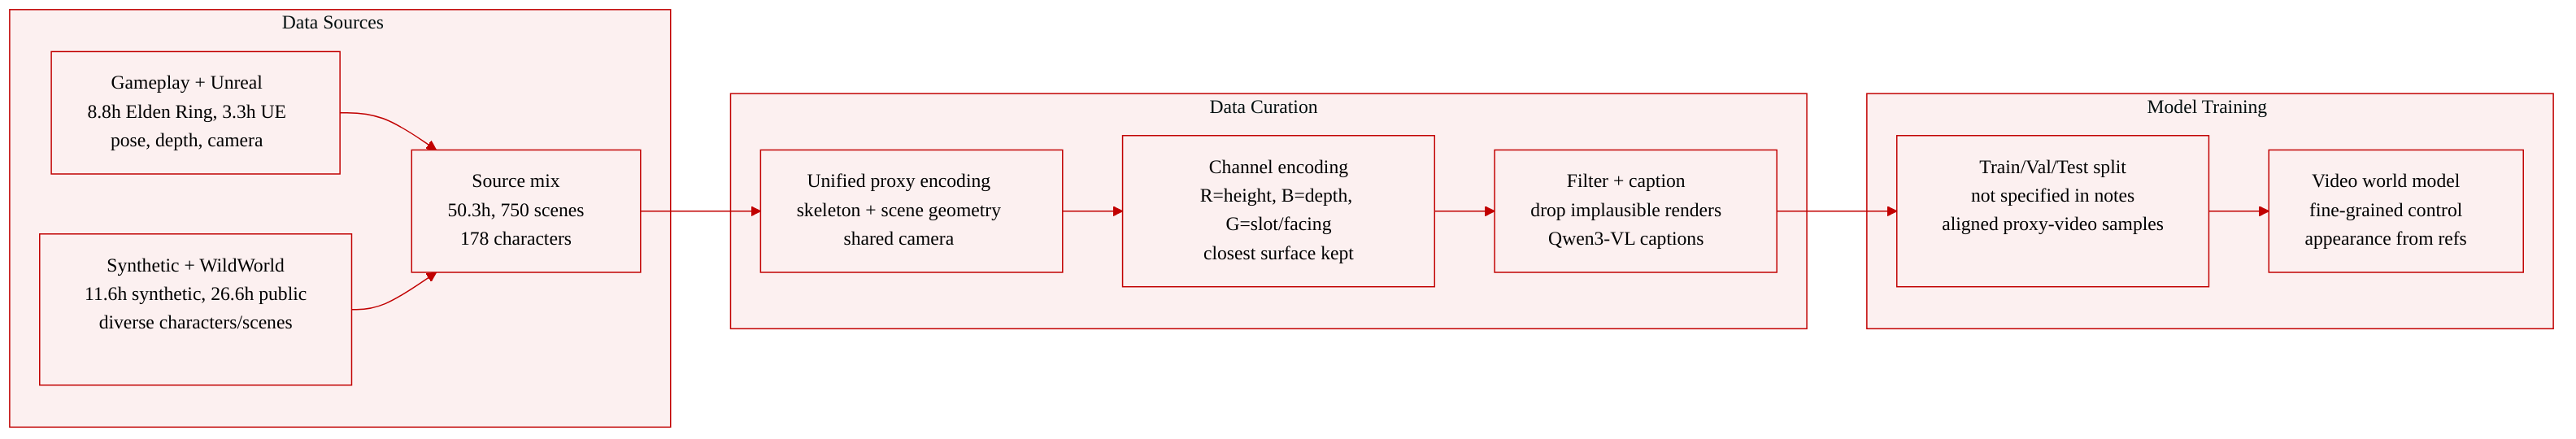
- The authors construct 50.3 hours of aligned proxy-video pairs covering 750 scenes and 178 characters.
- The dataset combines real gameplay recordings, synthetic data, Unreal Engine simulations, and public datasets.
- The goal is to pair RGB video with complementary control signals: articulated skeletons for character motion and geometry maps for scene structure.
Source composition
- Gameplay recordings: 8.8 hours from Elden Ring, covering third-person combat and exploration. Combat data includes six bosses with diverse body structures, while exploration data spans 11 regions and more than 20 player outfits. RGB frames, camera parameters, scene depth, and character skeletons are captured directly from the game.
- Synthetic data: 11.6 hours generated through a procedural rendering pipeline. It uses 133 boss and 29 player assets from Sketchfab, Quaternius, and KayKit, plus 842 Poly Haven environment assets. Each scene includes 15 to 30 randomly placed props and randomized character colors. Four scenarios target robustness: novel character entry, multi-character coexistence, camera-induced disappear/reappear, and rapid turns under a following camera. Camera motion is applied to 95 percent of samples, and a vision-language model filters out invalid renders and physically implausible placements.
- Unreal Engine simulations: 3.3 hours of gameplay footage with reconstructed characters and weapons, scripted opponents, and bot-controlled players. RGB frames and geometric proxies are rendered from the same simulated state for aligned supervision.
- Public datasets: 26.6 hours from WildWorld, selected for diverse creature morphologies and motion patterns. Its synchronized camera, skeletal, and depth annotations are converted into the unified proxy representation.
Processing pipeline
- Data acquisition: Camera poses, intrinsics, skeletons, and scene depth are collected. For real gameplay, camera data and skeletal states are extracted from the game process. Scene depth is captured at one frame per second and used to reconstruct scene geometry, from which depth maps are rendered per frame. Synthetic and Unreal Engine data are obtained directly from assets and simulation states. Public dataset annotations are reused.
- Unified proxy encoding: At each frame, character skeletons and scene geometry are jointly rendered under a shared camera to preserve spatial relationships and occlusion.
- Scene branch: characters and sky are removed from depth maps, temporal observations are fused into 3D scene geometry, and geometry is re-rendered under each frame camera pose.
- Character branch: 3D joints are projected into the camera view and rendered as rounded bone segments with joint markers, with thickness adapted to character scale and camera distance.
- Channel encoding: The RGB channels encode geometric attributes rather than appearance colors.
- R encodes height, with character values mapped to [0, 0.2] and scene values mapped to [0.5, 1].
- B encodes camera-forward depth, where brighter values indicate closer surfaces.
- At each pixel, the renderer keeps the surface closest to the camera.
- G jointly encodes character slot and facing direction, while scene geometry uses G = 0. All parts of a character share the same slot value within a frame, and slots are linked to reference images.
- Filtering and annotation: Synthetic samples with implausible configurations, such as floating players or rendering failures, are filtered out. Qwen3-VL-8B generates structured captions from the first frame and character references, describing conditioning signals, player, boss, and background.
Training sample format
Each training sample consists of:
- An aligned proxy video.
- An RGB clip.
- Character reference images.
- A textual description.
Use in the model
- The unified proxy-video pairs are used to train a video world model for fine-grained control and zero-shot generalization.
- The slot and reference setup is designed so the generator recovers character appearance from reference images rather than relying on fixed visual appearance or screen position.
- The provided sections do not specify an explicit train/validation split, exact source mixture ratios, or cropping strategy. The described processing focuses on constructing unified geometric conditioning signals and aligned video-proxy training samples.
Method
The authors propose Wizard, a system combining an agentic framework for explicit world-state control with a video generator that renders the evolving state through structured visual proxies. Before each gameplay session, an initialization stage reconstructs the scene and characters, rigs character skeletons, and builds a target-specific motion set through motion retrieval and retargeting. Once initialized, the framework supports real-time gameplay by updating character motions, scene geometry, and combat states in response to player inputs and boss decisions, while the video generator renders the corresponding visual observations.
As shown in the figure below:
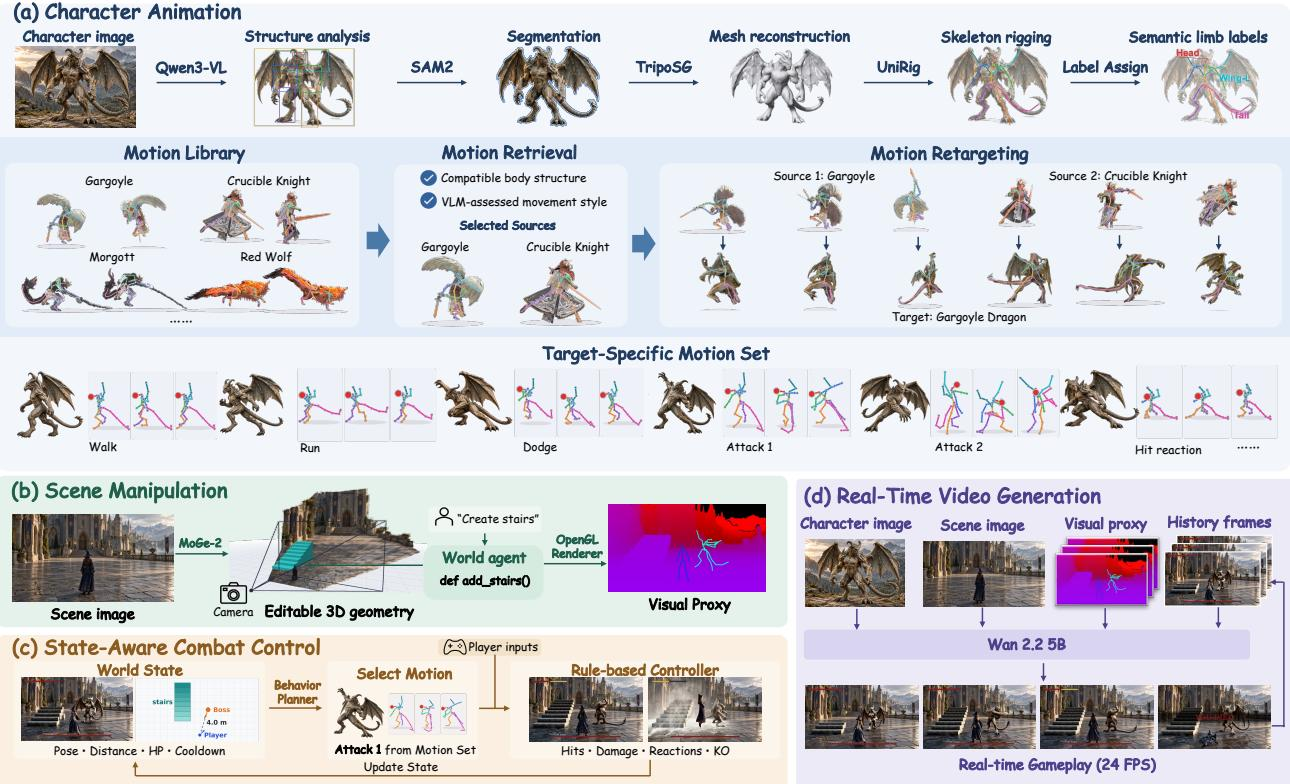
The agentic framework handles character animation, scene manipulation, and state-aware combat control. For character animation, Qwen3-VL infers body structure from a character image, SAM2 segments it, and TripoSG reconstructs the mesh. UniRig and a medial-axis fitting procedure generate skeletons with semantic labels. Motions are retrieved from a library based on compatible body structures and VLM-assessed movement styles, then retargeted using inverse kinematics. For scene manipulation, MoGe-2 recovers 3D point maps and camera parameters to construct an editable background mesh. A world agent translates natural-language instructions into geometric operators to modify the scene geometry, which is re-rendered into visual proxies using OpenGL. For state-aware combat control, a shared world state tracks positions, poses, health, and cooldowns. A behavior planner selects movements and attacks, while a rule-based controller enforces gameplay constraints, detects hits via swept hitboxes, and updates combat outcomes.
To condition the video generator, the system constructs unified geometric conditioning videos. Scene geometry and character skeletons are jointly rendered to preserve spatial relationships and mutual occlusion. The RGB channels encode geometric attributes rather than appearance colors: R encodes height, B encodes camera-forward depth, and G jointly encodes a character's slot and facing direction.
Refer to the framework diagram:
The video generator is built on Wan2.2-TI2V-5B, rendering evolving visual proxies into video conditioned on the initial scene image and character references:
X^t:t+L−1=Gθ(Pt:t+L−1,I0,{Rk}k=1K;H<t)where Pt:t+L−1, I0, and Rk denote the visual proxy sequence, the initial scene image, and the reference image for character k, respectively. H<t denotes the context retained from previously generated frames.
As shown in the figure below:
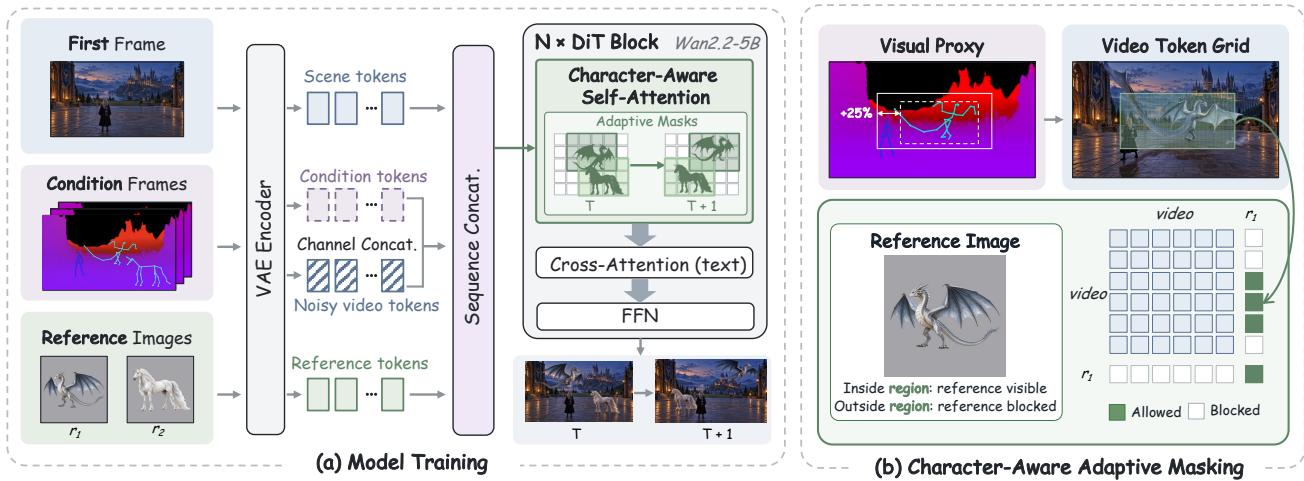
The first frame is encoded as a clean latent prefix to establish scene appearance. Proxy frames are encoded by the same VAE and concatenated with noisy video latents along channels, using a zero-initialized condition embedding. Character references are appended as additional tokens to specify appearance.
To bind reference images to their intended characters, the authors leverage explicit skeleton structures through Character-Aware Adaptive Masking. Bounding regions are derived from skeletons and expanded by 25%. In every DiT self-attention layer, attention from video token i to reference token j is gated using an additive mask:
Aij=Softmaxj(dqi⊤kj+Mij),Mij={0,−∞,ui∈Ωk(j),τ(i),otherwise,where k(j) identifies the character associated with reference token j, ui and τ(i) denote the spatial position and frame index of video token i, and Ωk,τ is the expanded region of character k at frame τ. This spatial masking reduces cross-character appearance leakage and supports flexible summoning, removal, transformation, and multi-character gameplay.
For real-time autoregressive generation, the authors adopt a three-stage training pipeline. First, teacher forcing adapts the bidirectional model to autoregressive generation. Second, consistency distillation uses a guided causal teacher and an exponential moving average target, training the student with a sliding window of 20 latent frames and the first frame as a persistent attention sink. Third, distribution matching distillation is applied to the student's own autoregressive rollouts, using the frozen bidirectional model as the target score network and a learned critic to estimate the student's score. The visual proxy conditions and character-gated reference attention remain active throughout all stages, enabling the model to generate real-time rollouts at 24 FPS with only 2 denoising steps.
Experiment
The experiments evaluate Wizard using user-provided references unseen during training, with agent-controlled visual proxies driving real-time gameplay generation. Zero-shot generalization tests show that the model handles novel scenes, characters, and motions while maintaining visual consistency and enforcing game rules such as health-based combat resolution. Open-ended creative gameplay tests further demonstrate interactive character transformation and scene manipulation, including combining both changes in a single scenario. Overall, the framework supports flexible, user-driven control of characters and environments without additional fine-tuning.