Command Palette
Search for a command to run...
DynaFlow : apprentissage d’une orchestration multi-agents de forme libre
DynaFlow : apprentissage d’une orchestration multi-agents de forme libre
Ruhao Liu Qi Li Shizun Wang Xinchao Wang
Résumé
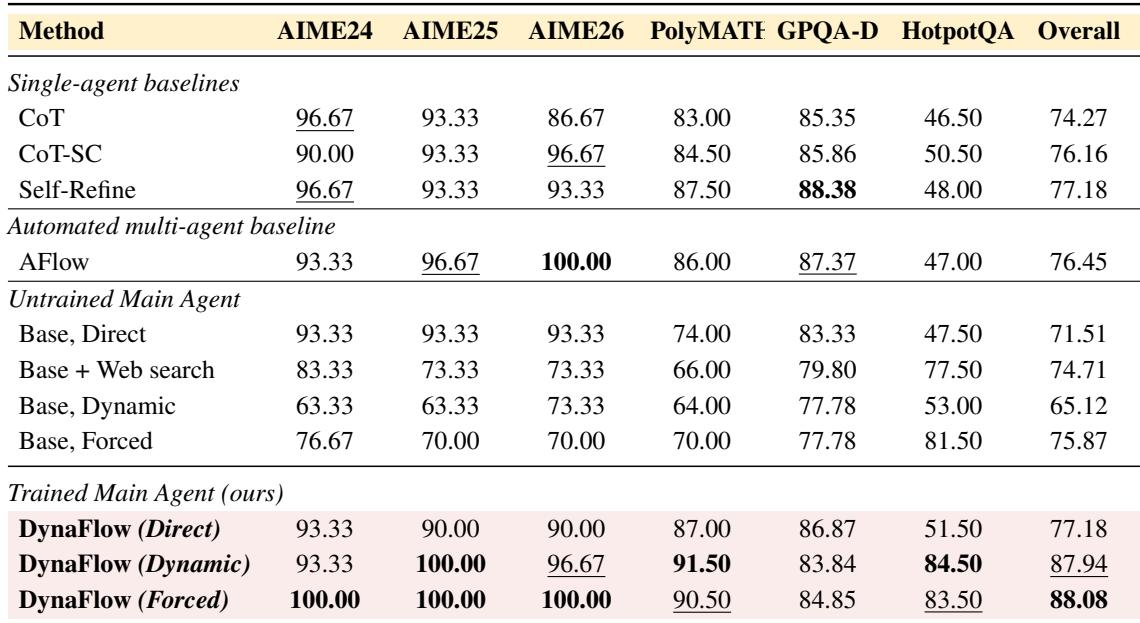
Les systèmes multi-agents reposent souvent sur des structures de collaboration prédéfinies, ce qui limite leur capacité à s’adapter à des exigences de tâches variées. Nous présentons DynaFlow, un cadre qui intègre la synthèse de flux de travail exécutables de forme libre dans l’espace d’action de l’agent principal. L’agent décide quand une collaboration est nécessaire et génère des programmes spécifiques à la tâche qui coordonnent les sous-agents par une exécution séquentielle ou parallèle, un échange structuré d’informations et une vérification. Les résultats d’exécution et les traces informent les actions suivantes, ce qui permet à l’agent d’adapter la collaboration au fur et à mesure du raisonnement. Nous entraînons uniquement l’agent principal par ajustement supervisé sur des trajectoires distillées, suivi d’un raffinement sur des exemples filtrés pour les prémisses non étayées, la vérification biaisée et les défauts de flux d’information. Tous les sous-agents restent fixes, ce qui sépare l’apprentissage de l’orchestration de l’amélioration des capacités des exécutants. Sur six bancs d’essai couvrant le raisonnement mathématique, la réponse à des questions scientifiques et la recherche multi-sauts, DynaFlow atteint une précision globale de 88,08 % en mode Forced, surpassant de 10,90 points de pourcentage la meilleure référence évaluée avec le même backbone Qwen3.5-27B. L’analyse des flux de travail révèle une utilisation, une vérification et un raffinement plus explicites des résultats en amont après l’entraînement, soulignant que le flux d’information entre étapes constitue une dimension clé de l’orchestration multi-agents.
One-sentence Summary
Researchers at the National University of Singapore introduce DynaFlow, a framework that integrates free-form executable workflow synthesis into the main agent’s action space so the agent generates task-specific programs coordinating fixed sub-agents through sequential or parallel execution, structured information exchange, and verification; trained via supervised fine-tuning on distilled trajectories and refinement on examples filtered for unsupported premises, biased verification, and information-flow defects, DynaFlow achieves 88.08% overall accuracy in Forced mode across six benchmarks spanning mathematical reasoning, scientific question answering, and multi-hop retrieval, outperforming the strongest evaluated baseline by 10.90 percentage points with the same Qwen3.5-27B backbone.
Key Contributions
- DynaFlow integrates free-form executable workflow synthesis into the main agent's action space, enabling it to decide when collaboration is needed and to generate task-specific programs that coordinate sub-agents through sequential or parallel execution, structured information exchange, and verification.
- The main agent is trained via supervised fine-tuning on distilled trajectories and then refined on examples filtered for unsupported premises, biased verification, and information-flow defects, making orchestration quality an explicit selection criterion while keeping all sub-agents fixed.
- Across six benchmarks spanning mathematical reasoning, scientific question answering, and multihop retrieval, DynaFlow achieves 88.08% overall accuracy in Forced mode and outperforms the strongest evaluated baseline with the same Qwen3.5-27B backbone by 10.90 percentage points; Dynamic mode also answers 47.1% of questions without invoking workflows while maintaining accuracy close to Forced execution, and workflow analysis shows more explicit use, verification, and refinement of upstream outputs after training.
Introduction
Multi-agent systems built on large language models often rely on fixed collaboration structures, but coordination requirements vary across tasks, and fixed structures can add unnecessary communication, latency, and computation. Prior automated workflow methods reduce some rigidity, yet DyFlow constructs plans from a finite set of operator templates and MAS-Orchestra generates the full coordination structure in a single decision without observing intermediate execution results. The authors introduce DynaFlow, which treats executable workflow synthesis as a native action of a main task-solving agent. The main agent can answer directly, use ordinary tools, or generate task-specific workflow programs that define subagent roles, dependencies, and output handling in code; a budget-constrained runtime returns outputs and traces that inform later orchestration decisions. The training framework updates only the main agent on distilled demonstrations and filters them for orchestration quality, keeping subagents fixed. Across six benchmarks, DynaFlow reports 88.08% overall accuracy in forced mode, exceeding the strongest evaluated baseline using the same backbone by 10.90 percentage points.
Method
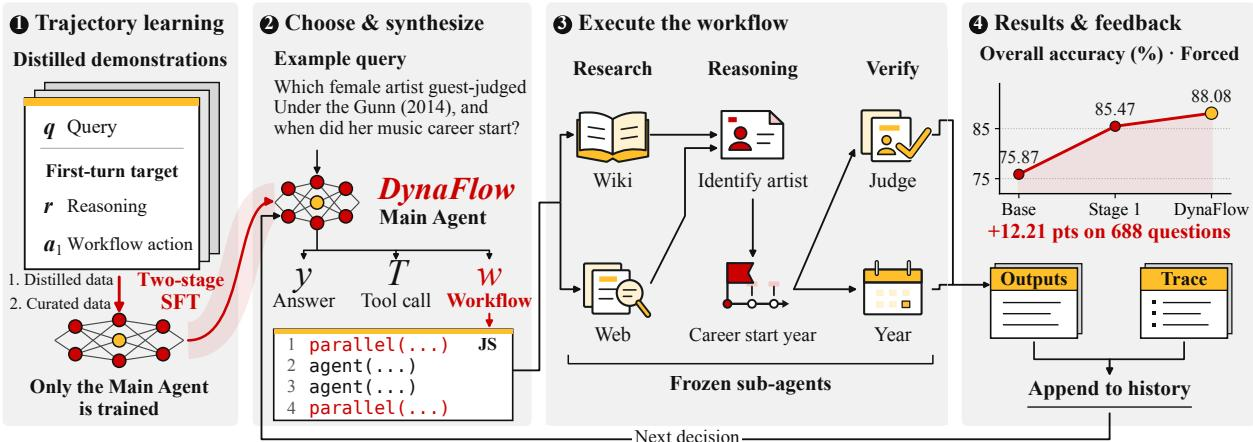
The authors introduce DynaFlow, a framework that integrates free-form executable workflow synthesis directly into the action space of a Main Agent. This design enables the agent to dynamically decide when and how to collaborate with fixed sub-agents, rather than relying on rigid, pre-designed structures. As shown in the figure below, the system operates through a continuous feedback loop where the Main Agent orchestrates tasks, executes workflows, and uses execution traces to guide subsequent decisions.
Given a question q and task instruction I, the Main Agent follows a policy πθ over a unified action space defined as:
A=Atool∪{Aans,(P,W(P))}Here, Atool represents ordinary tool-call actions, Aans denotes the final-answer output action, and (P,W(P)) constitutes a single workflow action. This workflow action comprises both a JavaScript program P synthesized by the Main Agent and its invocation through the workflow tool W. At each turn k, the agent generates an action ak∼πθ(⋅∣I,q,hk−1), where hk−1 is the ordered history of previous actions and observations.
The synthesized program P explicitly defines sub-agent roles, execution stages, and dependencies, allowing independent calls to run concurrently and dependent calls to receive upstream outputs. Once invoked, the workflow tool executes P under resource constraints using frozen sub-agents. It returns an observation ok=W(P) that combines the program output with an execution trace detailing the status and results of each sub-agent call. The Main Agent appends (ak,ok) to its history and determines whether to emit a final answer, invoke another tool, or synthesize a follow-up workflow to refine the results.
To train the orchestration policy πθ, the authors employ a two-stage supervised fine-tuning process that updates only the Main Agent while keeping all sub-agents fixed.
In the first stage, trajectory distillation, a teacher model generates trajectories using the same workflow interface and fixed sub-agents. The authors retain trajectories that yield correct final answers and strictly follow the delegation protocol. The supervised target is the first-turn output s=(r,a1), where r is the reasoning trace and a1=(P,W(P)) is the workflow action. This forms the initial dataset D1. Both training stages minimize the standard supervised fine-tuning loss:
LSFT(θ;D)=−(I,q,s)∈D∑logπθ(r,a1∣I,q)This loss supervises both the reasoning tokens and the action tokens, masking out instructions, questions, and tool definitions to focus on first-turn task analysis and workflow synthesis.
In the second stage, high-quality data selection, the authors filter the initial dataset to address orchestration failures such as poor information transfer and incorrect agent judgments. An LLM judge evaluates the orchestration quality of each trajectory by checking for three specific defects: premise injection, which involves presenting unverified claims as established premises; verification defects, where reviewers are steered toward expected answers; and information-flow defects, characterized by missing context or lossy transfer of upstream outputs. Only examples that pass this evidence-based check are retained, forming the curated subset D2=J(D1). Training then continues from the Stage 1 checkpoint on D2 with a smaller learning rate to refine the orchestration capabilities of the agent.
Experiment
These experiments evaluate a workflow orchestration Main Agent across AIME, PolyMATH, GPQA-Diamond, and HotpotQA, with sub-agents fixed, comparing a Base model, Stage 1 trajectory distillation, and DynaFlow after Stage 2 training on selected high-quality demonstrations. They show that orchestration training converts workflow access into effective collaboration, with DynaFlow achieving the strongest overall results, and that Stage 2 improves workflow design through more connected stages, better information transfer, explicit verification, and task-specific role assignment. Adaptive invocation in Dynamic mode maintains accuracy close to Forced execution while using substantially fewer sub-agents, indicating that the Main Agent learns selective collaboration, though failures on scientific reasoning highlight remaining challenges in independent verification and final-answer selection.
DynaFlow attains the highest overall accuracy in both forced and dynamic execution, exceeding the strongest baseline by more than ten percentage points while training only the main agent and keeping sub-agents fixed. It achieves perfect AIME accuracy in forced mode and the best HotpotQA performance, while on GPQA-Diamond it improves over its base counterparts but remains behind Self-Refine and AFlow. Both DynaFlow execution modes surpass the strongest baseline overall by over ten percentage points. Forced execution solves all AIME questions and both modes beat the strongest PolyMATH baseline by several points. Dynamic and forced modes achieve the highest HotpotQA accuracy, exceeding the search-enabled baseline by six to seven points. On GPQA-Diamond, DynaFlow improves over its base counterparts but does not surpass Self-Refine and AFlow. Workflow training changes the pattern from mostly negative to matching or exceeding direct answering across benchmarks.
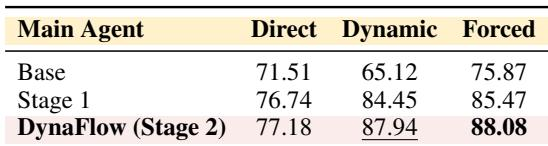
Training changes workflow execution from a mode that initially trails direct answering on many benchmarks into an effective collaboration strategy. After Stage 1, forced workflow execution reaches or exceeds the direct baseline across all six benchmarks, and further training narrows the gap between dynamic and forced modes. The final model performs similarly in dynamic and forced modes while using far fewer sub-agents when it can answer directly. Overall accuracy improves from Base to DynaFlow across all execution modes, with the largest gain in Dynamic mode. After Stage 1, Forced execution surpasses Direct within the same checkpoint by 8.73 points overall and reaches or exceeds the Base Direct reference on all six benchmarks. The Dynamic-Forced accuracy gap narrows from 10.75 percentage points at Base to 0.14 points for DynaFlow. In Dynamic mode, DynaFlow answers 47.1% of questions directly and uses about 41% fewer sub-agents than Forced execution while accuracy remains close to forced accuracy.
The experiments evaluate DynaFlow on AIME, HotpotQA, GPQA-Diamond, and PolyMATH using forced and dynamic workflow execution, where only the main agent is trained and sub-agents remain fixed. Workflow training shifts multi-agent execution from often trailing direct answering to matching or exceeding it, with DynaFlow achieving the highest overall accuracy and surpassing the strongest baseline by more than ten percentage points in both execution modes. DynaFlow reaches perfect AIME accuracy in forced mode and the best HotpotQA accuracy, while on GPQA-Diamond it improves over base counterparts but remains behind Self-Refine and AFlow. After Stage 1, forced execution already exceeds direct answering on all six benchmarks, and the final model closes the dynamic-forced accuracy gap while dynamic mode answers 47.1 percent of questions directly and uses about 41 percent fewer sub-agents.