Command Palette
Search for a command to run...
Sage-A1.5 : de l’exécution à long horizon à l’exploration scientifique par composition de capacités
Sage-A1.5 : de l’exécution à long horizon à l’exploration scientifique par composition de capacités
Résumé
Dans ce rapport, nous présentons Sage-A1.5, un modèle agentique de 35B à mélange d’experts qui s’appuie sur A1 pour faire progresser la résolution de problèmes à long horizon grâce à une composition adaptative de capacités. Par rapport à A1, Sage-A1.5 apprend non seulement à résoudre des tâches individuelles, mais aussi à organiser le travail et à réviser son approche pendant l’exécution. Sage-A1.5 met en avant trois améliorations : l’orchestration agentique, la vérification et la découverte scientifique ouverte. Premièrement, l’orchestration agentique étend l’exécution mono-agent par la délégation de tâches et la collaboration parallèle entre sous-agents dotés de contextes isolés, permettant de décomposer des tâches complexes et de les traiter simultanément, tout en favorisant une exécution efficace et en réduisant les interférences entre sous-agents concurrents. Deuxièmement, la vérification agentique renforce la fiabilité à long horizon grâce au contrôle de la progression, à la validation des preuves et à la révision réflexive de la stratégie, ce qui permet à l’agent de reconnaître des pistes de recherche improductives et d’adopter des approches alternatives. Troisièmement, la découverte scientifique ouverte étend les capacités agentiques au-delà de la réponse à des questions prédéfinies vers la conduite de recherches exploratoires, en reliant l’investigation scientifique à l’analyse interactive et à des artefacts de recherche inspectables. Nous illustrons ces capacités à travers des tâches agentiques complexes et des applications scientifiques multidisciplinaires. En outre, nous espérons que Sage-A1.5 fournira à la communauté une base accessible pour la découverte scientifique ouverte, offrant une voie pratique allant de l’exécution de tâches à long horizon à une exploration scientifique collaborative, vérifiable et inspectable.
One-sentence Summary
The Sage-A1.5 Team at Shanghai Artificial Intelligence Laboratory introduces Sage-A1.5, a 35B Mixture-of-Experts agentic model that extends A1 through adaptive capability composition to advance long-horizon execution via agentic orchestration, verification, and open scientific discovery for verifiable, inspectable, multidisciplinary exploration.
Key Contributions
- Adaptive Agentic Execution integrates Agentic Orchestration and Agentic Verification into Sage-A1.5’s execution policy, enabling task delegation and parallel collaboration among subagents with isolated contexts as well as evidence-driven self-correction during long-horizon problem solving.
- A unified post-training pipeline combines multi-domain supervised fine-tuning with mixed-reward reinforcement learning, fusing capabilities across domains, reasoning modes, and agent harnesses into a single 35B mixture-of-experts agentic model.
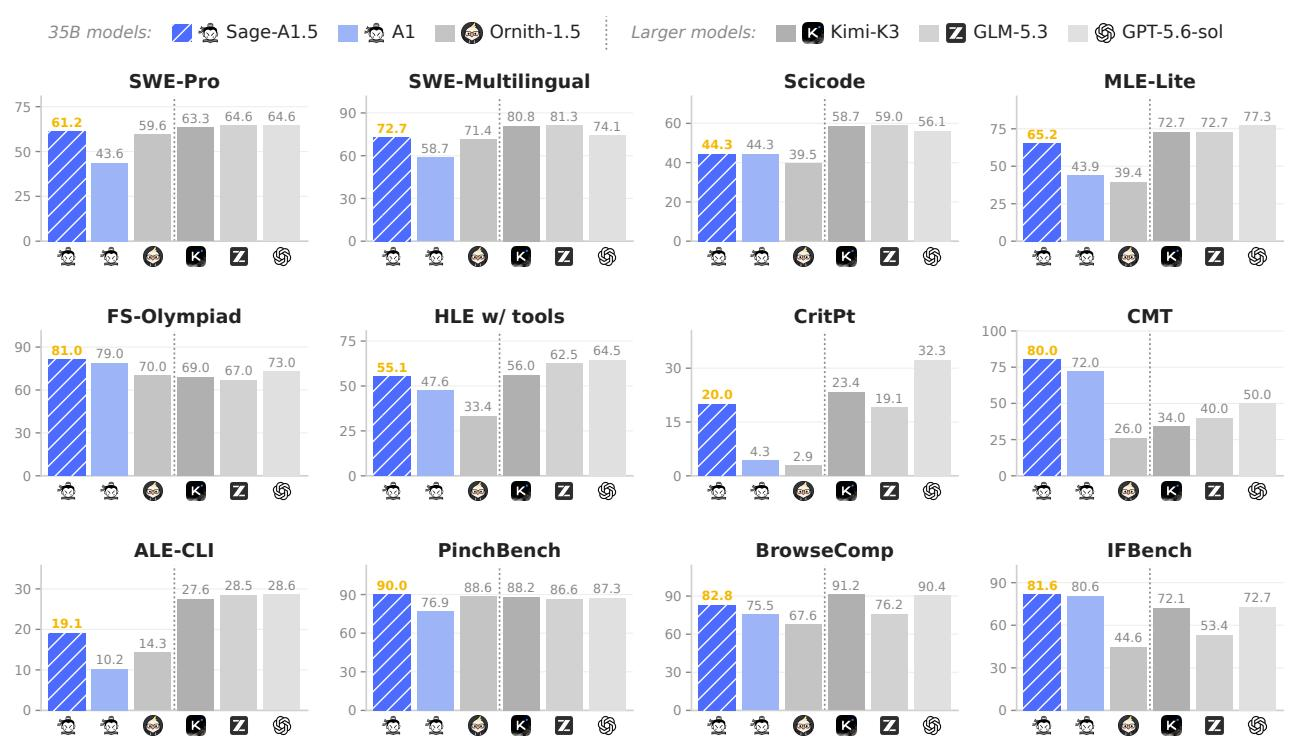
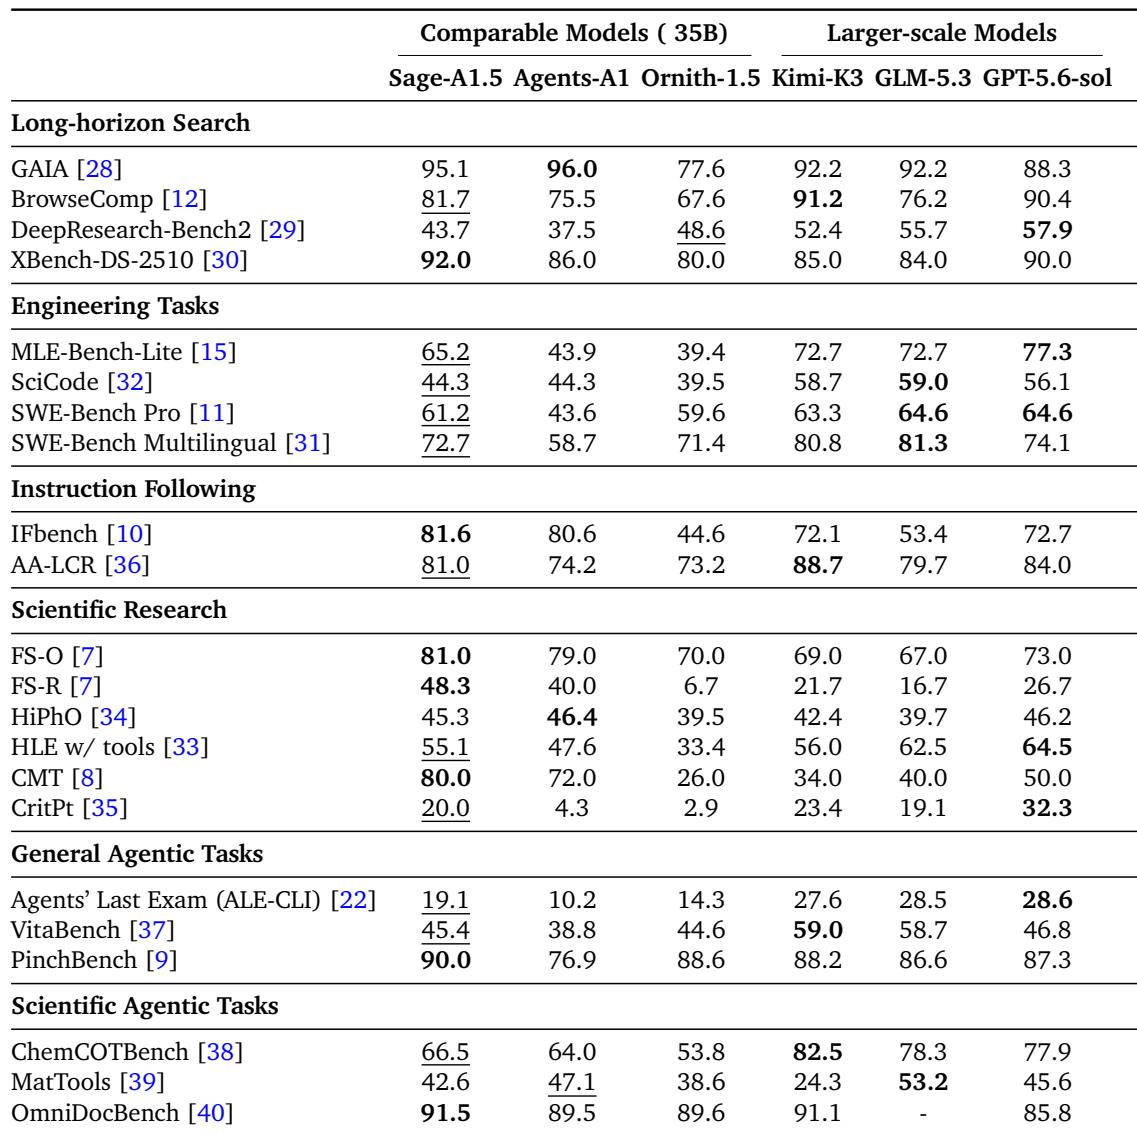
- Benchmark evaluations and scientific case studies demonstrate Sage-A1.5’s capacity for open scientific discovery. Sage-A1.5 outperforms larger models such as Kimi-K3, GLM-5.3, and GPT-5.6-sol on FrontierScience-Olympiad, CMT, PinchBench, and IFBench, remains competitive on SWE-Bench Pro and BrowseComp, and matches or surpasses equally sized Agents-A1 and Ornith-1.5 on all twelve benchmarks.
Introduction
The authors work in long-horizon agentic tasks such as software engineering, machine learning optimization, and scientific research, where success depends on managing related subtasks, comparing approaches, and revising decisions as new evidence appears. Prior agent models, including their earlier Agents-A1 35B MoE system, improved long-horizon performance by scaling context length, but a single agent working step by step still suffers from growing context, slow exploration, and errors that affect later decisions. Moreover, longer execution does not reliably improve results because agents may repeat unproductive searches, build on unsupported assumptions, or accept conclusions too early. To address this, the authors introduce Sage-A1.5, a 35B MoE agent model built on Agents-A1 that learns Agentic Orchestration to divide and delegate parallel subtasks, and Agentic Verification to review evidence and adjust actions without an external supervisor. The contribution includes an Adaptive Agentic Execution policy, a unified supervised fine-tuning and mixed-reward reinforcement learning pipeline, and benchmark evaluations showing that Sage-A1.5 outperforms much larger models on several agentic and scientific reasoning benchmarks.
Dataset
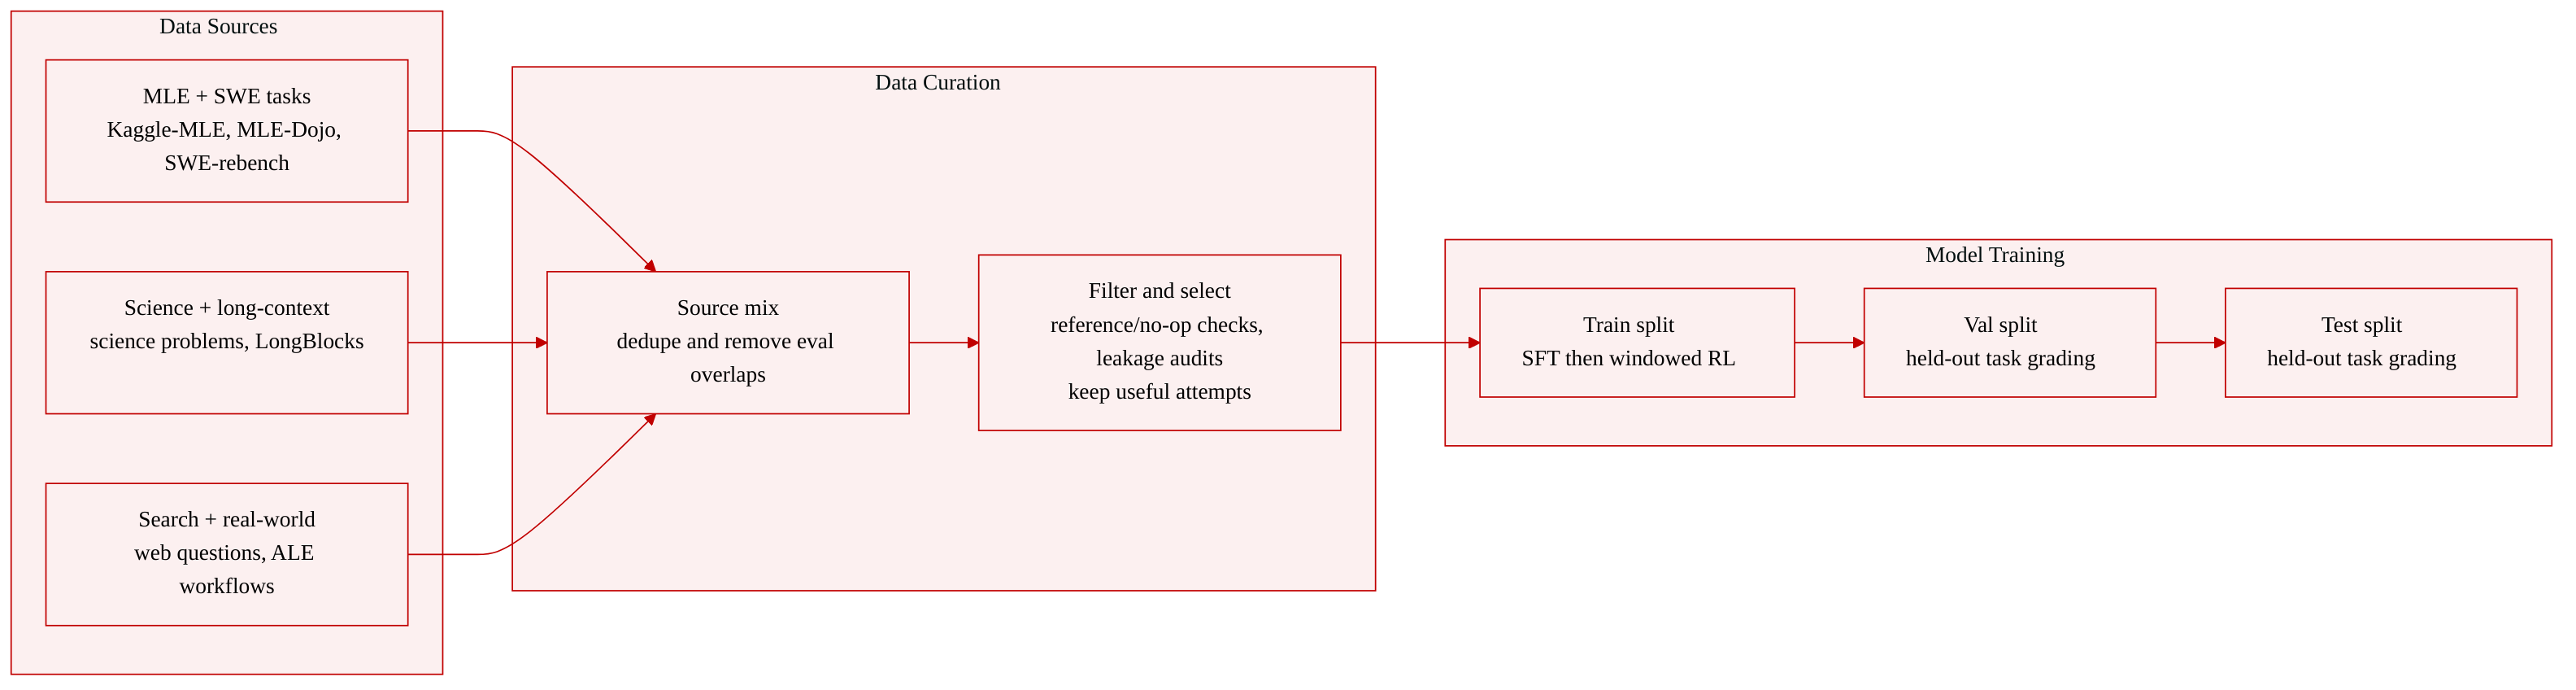
The authors assemble several curated task and trajectory datasets for post-training, each with distinct sources, composition rules, filtering steps, and uses.
-
MLE tasks
- Sources: an automated Kaggle-MLE Factory pipeline that converts historical Kaggle competitions into executable tasks, plus MLE-Dojo. Competitions overlapping the full MLE-Bench task set are excluded.
- Composition: tasks include public workspaces, hidden test sets, task specifications derived from official descriptions and actual data, task-specific evaluators, and human review.
- Processing and selection: collected supervision includes initial-solution prefixes, long-horizon optimization trajectories, and analysis sub-agent trajectories. If performance after the first best submission degrades beyond a threshold, the trajectory is truncated at a complete tool-interaction boundary; otherwise it is kept through the final submission.
- Use: used in the second stage of two-stage supervised fine-tuning, combined with scientific-research trajectories, and later used for reinforcement learning with execution-window rewards.
-
SWE tasks
- Sources: the public SWE-rebench-V2 dataset plus a separate in-house task set.
- Composition: tasks are converted into a common repair-task format modeled on SWE-bench. Each task contains a repository snapshot, a base commit, an issue description, a solution patch derived from non-test changes, and a held-out test patch used for grading.
- Environment and validation: container configurations, installation recipes, and test commands are recovered or constructed. Missing configurations follow a bounded build-and-repair loop. Candidate tasks pass reference-patch and no-op checks, and these outcomes are stored as task metadata.
- Collection and filtering: trajectories are collected using mini-swe-agent and Claude Code. Successful trajectories are retained, along with a filtered subset of unresolved attempts that have non-empty patches, substantive task-directed interaction, well-formed structure, and acceptable leakage and coverage checks. Zero-reward trajectories are re-graded once by replaying the unchanged patch.
- Leakage control: Git objects exposing reference fixes or held-out tests are removed during agent execution. Outbound traffic is blocked through the proxy, and required grading objects are restored only after the agent exits. Audit verdicts are stored and used during selection.
- Use: used for repository-level software-engineering issue-resolution training.
-
Scientific research tasks
- Sources: a diverse pool of scientific problems spanning mathematics, physics, chemistry, biology, and related disciplines.
- Composition and filtering: problems undergo preliminary quality checks and are selected using model-based assessments of difficulty, task type, and tool benefit. Medium-to-high difficulty problems with strong reasoning or research orientation and likely tool benefit are prioritized.
- Trajectory processing: a strong model generates long-horizon trajectories using search, visit, code, and scholar tools. Trajectories are filtered by solution correctness, reasoning depth, and tool-call success rate. Selected trajectories with recoverable tool failures are retained to teach self-correction.
- Use: used for token-level supervised fine-tuning on Qwen3.5-35B-A3B with an extended multi-epoch schedule.
-
Long-context reasoning tasks
- Sources: LongBlocks documents spanning 16K to 128K tokens.
- Composition: tasks are constructed across 24 fine-grained categories such as cross-document factual integration, timeline reconstruction, evidence attribution, multi-source consistency checking, rule induction, state tracking, and version-impact analysis. Each question includes a reference answer and supporting evidence.
- Processing: recursive task evolution uses ten difficulty axes and reference-model feedback. Candidates that pass review and have an empirical success rate of at most 0.75 enter the hard-question pool, producing 3,512 hard QA pairs. Qwen3.5-35B-A3B achieves a mean per-question success rate of 31.57% on this pool.
- Collection and selection: three reasoning trajectories are sampled from DeepSeek-V4-Pro per question. Incorrect answers are discarded, and remaining trajectories are jointly judged for evidence coverage, retrieval quality, reasoning consistency, and redundancy in two order-reversed assessments. One trajectory is selected per question, and sequence-length constraints leave 1,949 LongBlocks trajectories.
- Use: used for supervised fine-tuning on long-context reasoning.
-
Search agent tasks
- Sources: deduplicated questions from open-source search and deep-research datasets, plus newly generated search-grounded research questions.
- Composition: newly generated questions are grounded in web exploration by a proposal agent using search and page-reading tools. Each question includes explicit evaluation criteria covering facts, supporting evidence, comparisons, or conclusions.
- Collection and filtering: agentic search trajectories are collected in the same tool environment with report-style outputs. An LLM evaluator filters trajectories against the question-specific criteria, discarding reports with unsupported claims, missed criteria, or incomplete completion.
- Use: retained trajectories are used for supervised fine-tuning on search-agent tasks.
-
Economically valuable and real-world tasks
- Sources and scale: a manual cold start of a few dozen high-quality tasks is expanded through controlled evolution into more than one thousand professional workflow environments.
- Composition: tasks follow ALE-style professional workflows across 55 subdomains and 13 industry clusters. Each task includes real input data, a hidden reference, a deterministic grader, an isolated sandbox, pinned tool versions, and a per-task time budget. Construction and verification use distinct agents to avoid reward corruption.
- Collection and filtering: trajectories are collected with Claude Code. When context length is exceeded, earlier history is compressed and the task continues from the compressed context, and all segments are kept. The highest-scoring attempt per task is selected, plus a small share of active failed attempts with substantive deliverables. The mixture is balanced with caps per task family, domain, and failed-attempt share.
- Use: contributes several hundred million supervised tokens for generalist real-world agent training.
Method
The authors extend agent capability development along two dimensions: capability coverage, which spans task domains, and capability composition, which concerns how problem-solving capabilities are organized and adapted during execution. To achieve this, they introduce Adaptive Agentic Execution, comprising Agentic Orchestration and Agentic Verification.
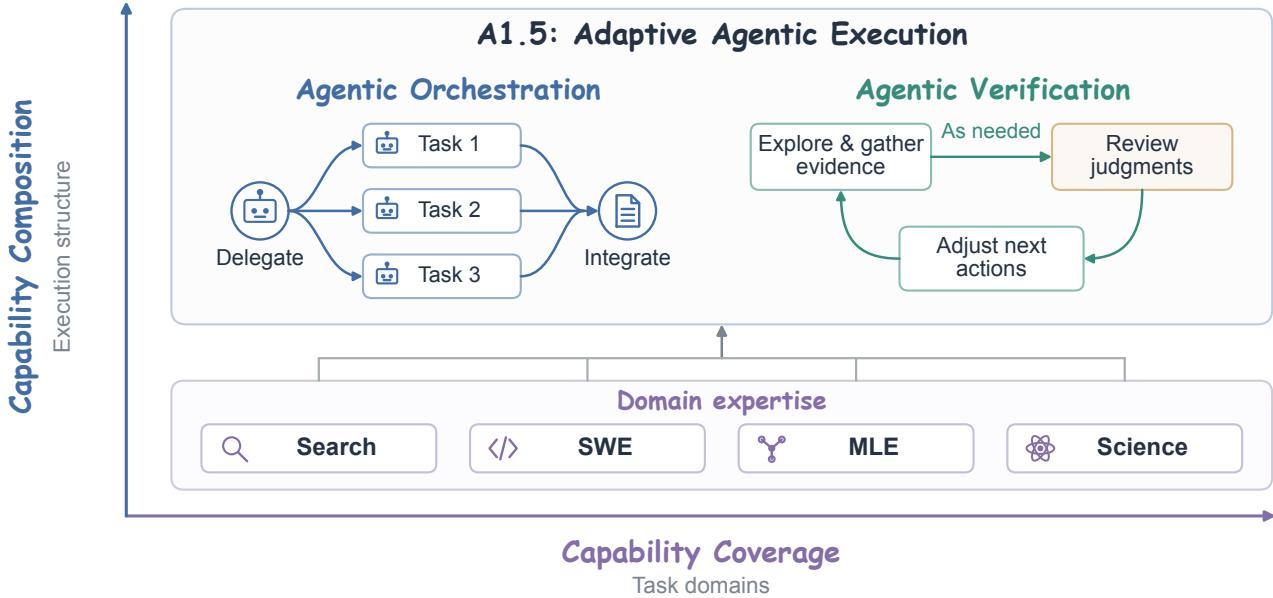
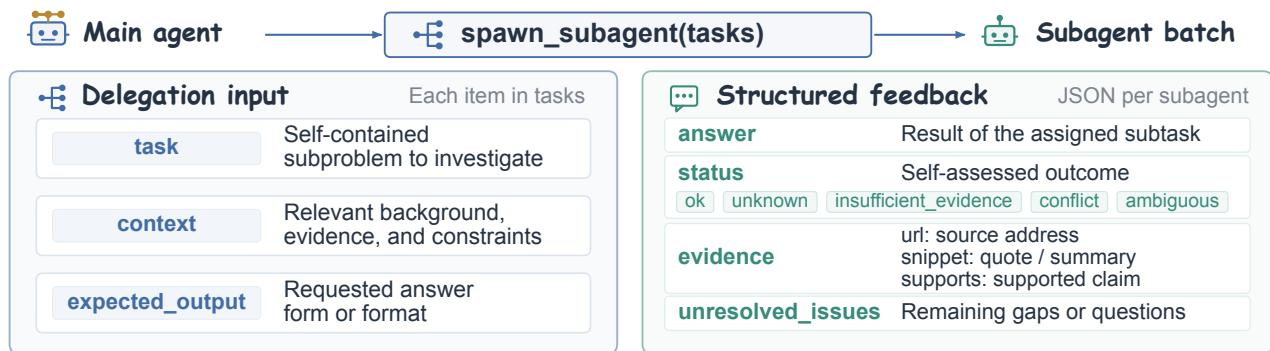
Agentic Orchestration structures, allocates, and coordinates computation during task execution. The model learns to decompose work, delegate subtasks, and integrate results through two complementary patterns: Exploratory Composition, where multiple agents investigate different hypotheses for the same question, and Constructive Composition, where a task is decomposed into complementary subproblems solved in parallel. The main agent delegates subtasks by specifying the scope, context, and expected output format. Subagents then return structured feedback, including their results, self-assessed outcomes, supporting evidence, and unresolved issues. This feedback enables the main agent to identify gaps, resolve conflicts, and guide subsequent investigations.
Agentic Verification addresses the accumulation of errors in long-horizon tasks by enabling the model to adaptively recognize when verification is needed. Instead of relying on external rules, the model examines its own reasoning to review confirmed facts, identify unsupported inferences, and determine ineffective exploration paths. During training, complete research trajectories containing intermediate reflections and subsequent actions are constructed. A supervisor model introduces verification at critical points, and the execution model continues exploring based on these findings. At inference time, adding a specific protocol marker to the system prompt activates this capability, allowing the model to autonomously perform verification and context management without external tools.
To enhance deep scientific reasoning and tool use, the authors develop a science-enhanced teacher model through a three-stage pipeline.
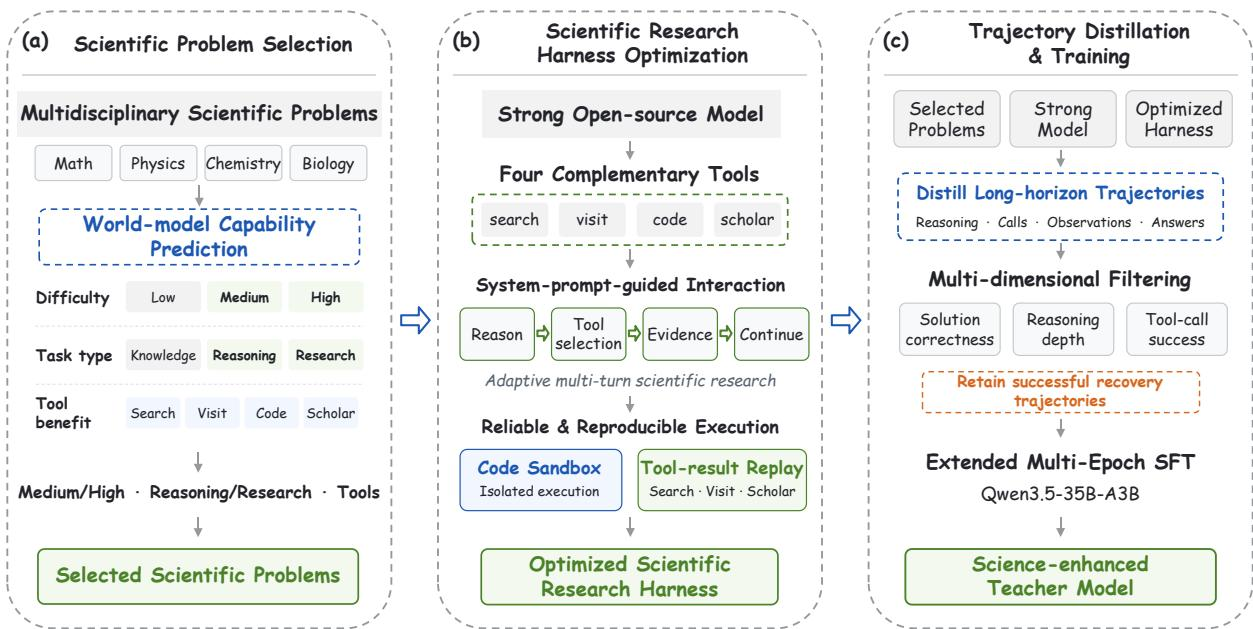
First, scientific problem selection leverages world-model predictive capabilities to evaluate candidate problems across difficulty, task type, and tool benefit, prioritizing medium-to-high difficulty problems that benefit from tool interactions. Second, the scientific research harness is optimized with four complementary tools: search, visit, code, and scholar. An isolated code execution sandbox and a tool-result replay mechanism are introduced to improve reliability and reproducibility. Third, trajectory distillation and training generate long-horizon trajectories using a strong model. These trajectories undergo multi-dimensional filtering based on solution correctness, reasoning depth, and tool-call success rate, retaining even recoverable tool failures to teach self-correction. The filtered data is used for extended multi-epoch supervised fine-tuning.
For unified training across domains, the authors employ a two-stage approach. Stage I involves Multi-Domain Supervised Fine-Tuning (SFT) using task-oriented demonstrations and protocol-focused cold-start examples collected across compatible harnesses. The SFT objective uses a token-normalized negative log-likelihood loss:
ℓθ(τ)=−Nτ1t∑mtlogπθ(yt∣ct)where mt indicates model-generated target tokens. The overall SFT loss combines task-oriented and protocol-focused subsets:
LSFT(θ)=(1−ρ)Eqtask[ℓθ]+ρEqproto[ℓθ]Stage II applies Unified Outcome-Process Post-Training, jointly optimizing outcome-based reinforcement learning and multi-teacher on-policy distillation (OPD). The sample-level objective is:
Lpost(x)=λout(x)LRL(x)+λproc(x)LOPD(x)Outcome-only supervision uses a reward function Rout(x)=Vd(x)−Pfmt(x)−Pproto(x), while process-only supervision targets reverse KL divergence between the student and teacher distributions:
LOPD(x)=Nτ1t∑mtDKL(pt∥ptT)To support flexible deployment and fully on-premise agentic workflows, the system is designed to run on heterogeneous hardware, including domestic NPUs, mainstream GPUs, and Apple Silicon. The model provides multiple quantization variants, such as FP8 and 4-bit formats, to reduce memory requirements.
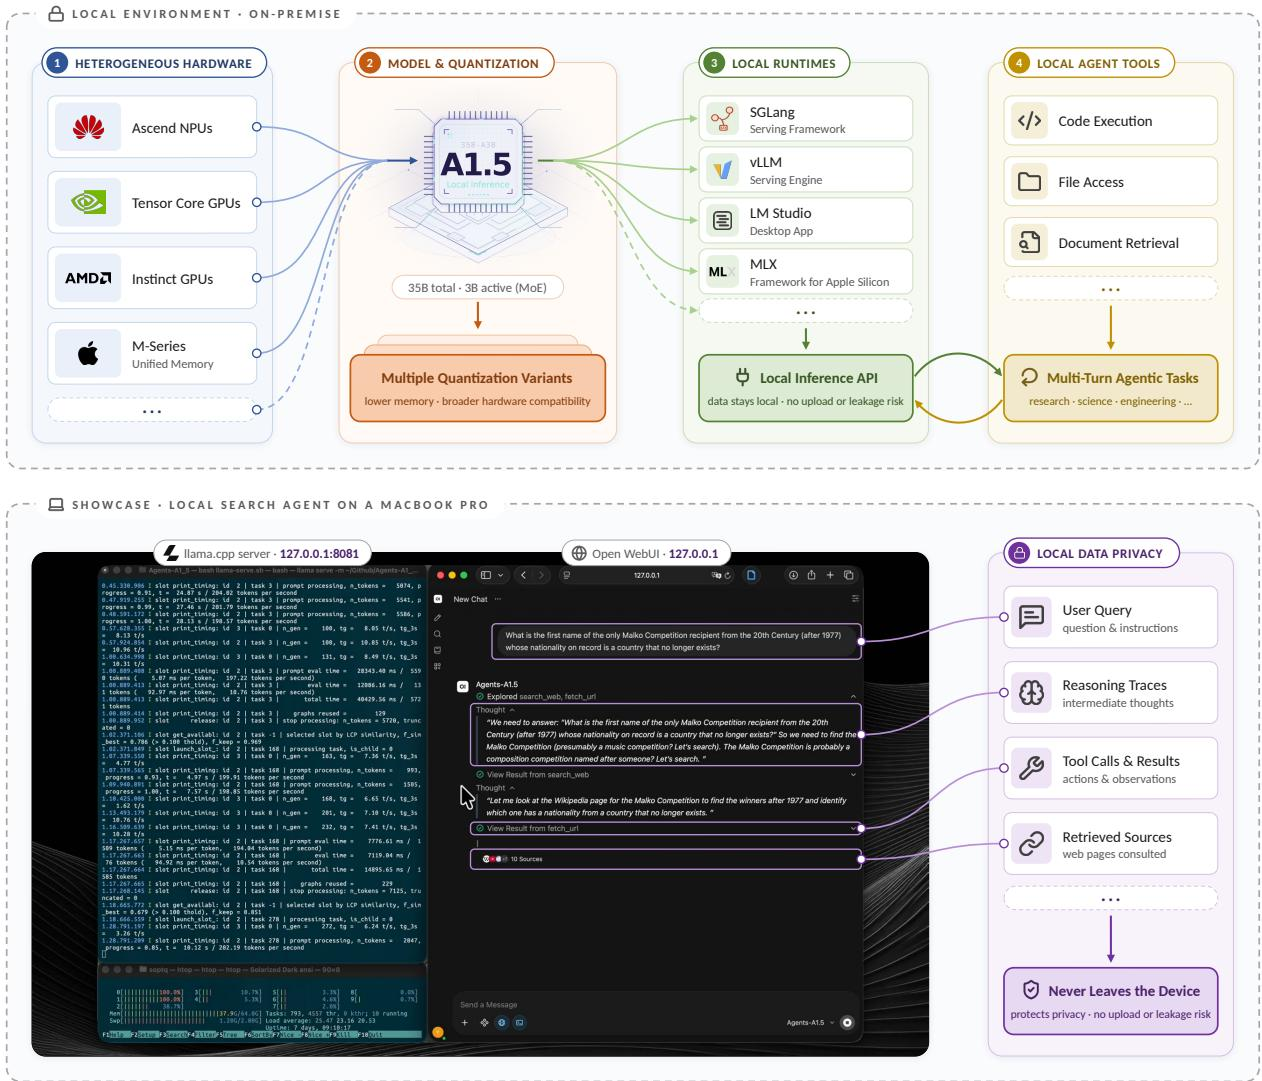
Through local runtimes and inference APIs, the model integrates with local agent tools for code execution, file access, and document retrieval. This architecture ensures that all data and multi-turn agentic tasks remain within the local environment, mitigating data-leakage risks and supporting privacy-sensitive research and enterprise deployment.
Experiment
The evaluation spans search, engineering, scientific research, general agentic, and scientific agentic benchmarks, using web tools, code sandboxes, subagent orchestration, verification, and isolated execution environments. The specialized teachers consistently improve over their Qwen baselines, with especially large gains on research-level scientific reasoning and long-horizon information-seeking tasks, while orchestration and verification further strengthen multi-step browsing and report generation and help reduce unproductive exploration. Sage-A1.5 also performs competitively for its scale on general agentic tasks and instruction following. Case studies show that the model can coordinate multi-agent scientific workflows, self-correct analytical and numerical errors, integrate evidence into structured reports, and complete professional and end-to-end auto-research tasks.
Among comparable 35B models, Sage-A1.5 leads on BrowseComp and XBench-DS-2510, ranks a close second on GAIA, and trails on DeepResearch-Bench2. Against larger-scale models, it posts the best overall result on XBench-DS-2510 and outperforms them on GAIA, while lagging behind the top larger models on BrowseComp and DeepResearch-Bench2. DeepResearch-Bench2 remains a relative weak point for Sage-A1.5. Sage-A1.5 is the strongest 35B model on BrowseComp and XBench-DS-2510, and nearly matches the leading 35B model on GAIA. It scores higher than all listed larger-scale models on both GAIA and XBench-DS-2510. On DeepResearch-Bench2, it trails both the best 35B peer and every larger-scale model.
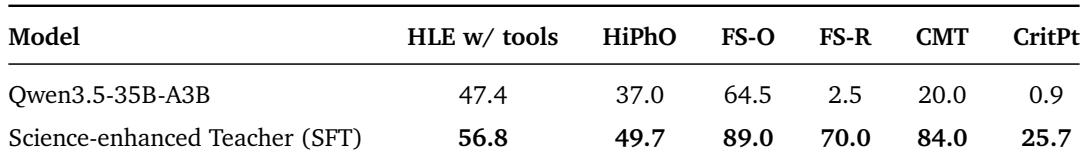
The science-enhanced teacher outperforms Qwen3.5-35B-A3B on every reported scientific benchmark. Gains are largest on complex research-level tasks, where baseline scores were very low, while Olympiad-level and expert tool-based academic tasks also improve clearly. Research-level benchmarks improve dramatically, with FS-R rising from 2.5 to 70.0 and CMT from 20.0 to 84.0. Olympiad-level scientific performance also strengthens, with FS-O increasing from 64.5 to 89.0 and HiPhO from 37.0 to 49.7.
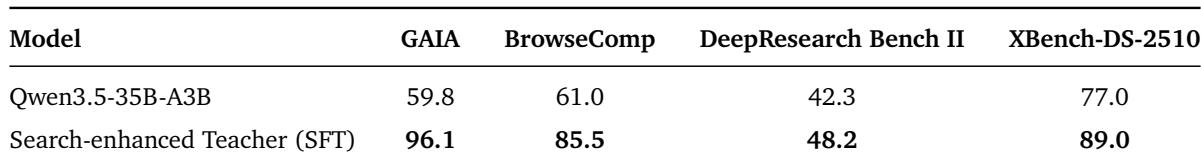
The search-enhanced teacher consistently outperforms the Qwen3.5-35B-A3B baseline across all four search benchmarks. Gains are largest on multi-step browsing and evidence-seeking tasks, while report synthesis and deep search also improve by a smaller but meaningful margin. This indicates stronger sustained search, retrieval, and synthesis capabilities relative to the baseline. Accuracy on GAIA and BrowseComp improves sharply, with GAIA nearly reaching ceiling-level performance. DeepResearch Bench II and XBench-DS-2510 also improve, reflecting better report synthesis and deep search on professional real-world questions.
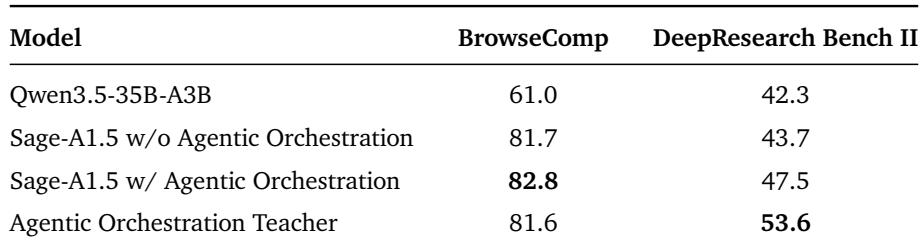
Agentic Orchestration improves performance on both BrowseComp and DeepResearch Bench II. Enabling orchestration on Sage-A1.5 yields a modest BrowseComp gain and a larger DeepResearch Bench II gain, while the orchestration teacher achieves the highest report-generation score. Sage-A1.5 with orchestration records the highest BrowseComp accuracy among the compared configurations. Enabling orchestration on Sage-A1.5 improves BrowseComp accuracy modestly and DeepResearch Bench II more substantially. Sage-A1.5 with orchestration achieves the highest BrowseComp accuracy among the compared configurations. The orchestration teacher achieves the highest DeepResearch Bench II score, with large gains over the Qwen baseline.
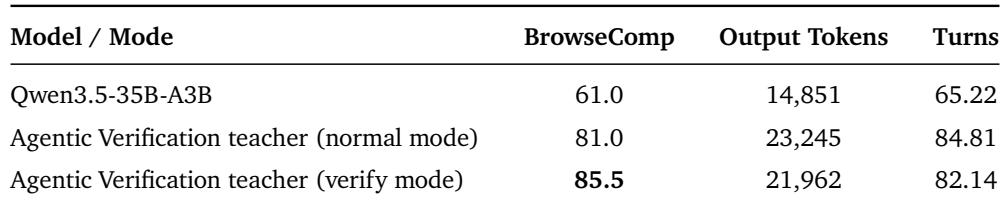
Agentic Verification substantially improves BrowseComp accuracy over the Qwen3.5-35B-A3B baseline, with verify mode reaching the highest accuracy among the compared configurations. In paired comparisons, verify mode also lowers average output token count and interaction turns relative to normal mode, suggesting reduced generation cost despite added verification reasoning. The verification teacher in normal mode reaches 81.0 BrowseComp accuracy, compared with 61.0 for the baseline. Enabling verify mode raises BrowseComp accuracy to 85.5, a 4.5 percentage point gain over normal mode and the highest reported in the comparison. Verify mode reduces average output tokens by about 5.5 percent and interaction turns by about 3.2 percent relative to normal mode in paired attempts.
The experiments evaluate Sage-A1.5 against comparable and larger models on deep research, browsing, and scientific benchmarks, and compare science-enhanced, search-enhanced, orchestration, and verification configurations with the Qwen3.5-35B-A3B baseline. Sage-A1.5 leads among 35B models on BrowseComp and XBench-DS-2510 and surpasses larger models on GAIA and XBench-DS-2510, while DeepResearch-Bench2 remains a relative weakness. The science-enhanced teacher improves research-level scientific benchmarks substantially, and the search-enhanced teacher yields sharp gains on GAIA and BrowseComp. Agentic orchestration improves BrowseComp and DeepResearch Bench II, while agentic verification raises BrowseComp accuracy and reduces output tokens and interaction turns.