Command Palette
Search for a command to run...
R2Orch : auto-amélioration récursive pour l’orchestration d’agents par auto-jeu au sein d’une boucle d’internalisation des compétences
R2Orch : auto-amélioration récursive pour l’orchestration d’agents par auto-jeu au sein d’une boucle d’internalisation des compétences
Mingda Zhang Yun Huang Qiang Huang Yanjin Li Rui Qian Qichao Zhao Tiesunlong Shen Na Zhao Jian Wang Xiaoying Tang
Résumé
Au cours des dernières années, l’orchestration d’agents a été largement appliquée pour résoudre des tâches humaines complexes. Cependant, l’apprentissage de l’orchestration existant se heurte encore à des difficultés majeures : des curriculums conçus manuellement, l’effondrement de l’avantage lorsque toutes les trajectoires d’une tâche atteignent le même résultat, et des signaux d’évaluation peu fiables qui jugent chaque compétence par un unique score bruité. Pour répondre à ces défis, nous proposons R2Orch, un nouveau paradigme d’orchestration par auto-jeu récursif : une boucle interne d’auto-jeu qui améliore l’orchestrateur sur des tâches qu’il choisit lui-même, et une boucle externe qui améliore la manière dont la boucle interne s’améliore. Pour soutenir ce paradigme, nous introduisons l’objectif d’entraînement Recursive Learnability, qui récompense un Proposer pour choisir des tâches dont les trajectoires continuent d’atteindre des résultats différents à mesure que les compétences sont retirées. Sur la base de cet objectif, nous proposons en outre la méthode Skill Withdrawal, dans laquelle la boucle externe retire chaque compétence dès qu’une évaluation contrôlée au sein de l’auto-jeu montre que l’orchestrateur obtient des performances aussi bonnes sans elle. De plus, les deux boucles forment un cycle unique : les échecs sont distillés en compétences, les compétences en paramètres, et les retraits conduisent le Proposer vers de nouveaux échecs, si bien que l’orchestrateur tend vers un déploiement sans compétence. Les résultats expérimentaux sur douze ensembles de données montrent que R2Orch surpasse systématiquement les références dans des tâches de réponse à des questions, de mathématiques, de code et des tâches interactives. Notre code est disponible à l’adresse github.com/beita6969/R2Orch.
One-sentence Summary
Researchers at The Chinese University of Hong Kong, Shenzhen, Fudan University, University of Illinois Urbana-Champaign, Tsinghua University, and National University of Singapore propose R2Orch, a recursive self-play orchestration paradigm whose inner loop improves the orchestrator on self-chosen tasks and whose outer loop improves how the inner loop improves through Recursive Learnability and Skill Withdrawal, driving zero-skill deployment and outperforming baselines on twelve question answering, math, code, and interactive datasets.
Key Contributions
- R2Orch is a recursive self-play orchestration paradigm that combines an inner loop for improving an orchestrator on self-chosen tasks with an outer loop for improving how the inner loop operates, moving the system toward zero-skill deployment.
- Recursive Learnability rewards a task Proposer for selecting problems whose rollouts continue to yield different outcomes as candidate skills are withheld, and Skill Withdrawal removes a skill once controlled self-play evaluation shows the orchestrator performs as well without it.
- Experiments on twelve benchmarks covering question answering, math, code, and interactive tasks show that R2Orch outperforms all baselines on every benchmark, improves six other Worker backbones without retraining, and retains accuracy when tested with zero skills.
Introduction
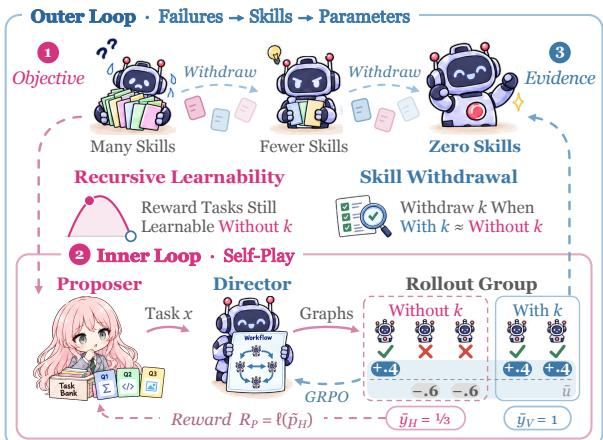
Agentic systems increasingly rely on agent graphs where nodes are roles and edges are hand-offs, giving orchestrators controllable, compositional, and reusable ways to solve tasks. However, existing orchestrators usually learn from human-collected tasks and depend on in-prompt skills, making them costly to scale and hard to improve autonomously. Prior work on learned orchestration, self-improving agents, and skill scaffolds still faces hand-designed curricula, advantage collapse in group-based reinforcement learning, and unreliable evaluation signals. The authors propose R2Orch, a recursive self-play orchestration paradigm with an inner loop that improves a Director on Proposer-chosen tasks and an outer loop that improves the inner loop. It introduces Recursive Learnability to reward tasks whose rollouts remain diverse when a candidate skill is withheld, and Skill Withdrawal to retire skills using controlled evaluation inside randomized rollout groups. The approach outperforms baselines across twelve benchmarks and maintains accuracy at zero-skill deployment.
Method
The authors introduce the R2Orch framework, which orchestrates model improvement through two nested self-play loops built upon a single randomized rollout group. This architecture integrates Recursive Self-Play Orchestration, Recursive Learnability, and Skill Withdrawal to continuously refine both the task selection and the underlying capabilities of the model.
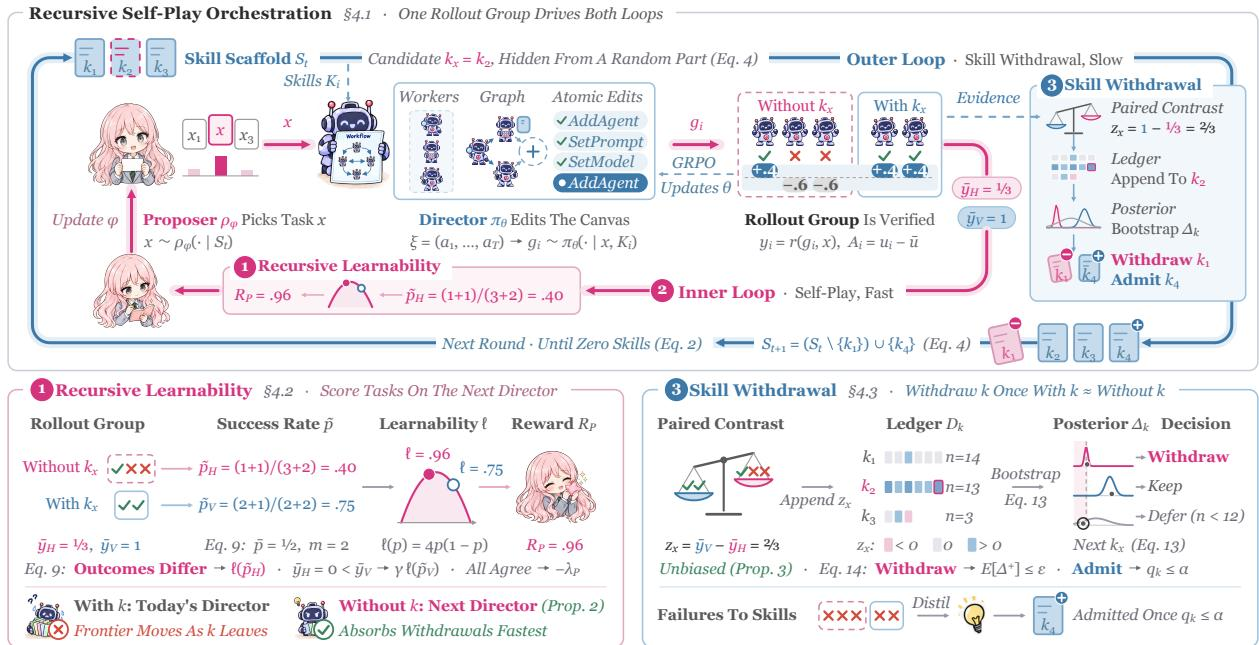
The core mechanism, Recursive Self-Play Orchestration, operates on two distinct time scales. On the fast time scale, the inner loop employs self-play to improve the Director on tasks selected by the Proposer. Both policies execute proximal best responses through clipped steps, formulated as:
θt+1≈argθmaxEvK(x;θ)−β1KL(πθ∥πθt) ϕt+1≈argϕmaxERP(x)−τKL(ρϕ∥ρ0)The Director is trained on the Proposer's picks and evaluated based on the value of the context it reads, while the Proposer is optimized using a specific reward signal. On the slow time scale, the outer loop updates the skill scaffold from the same rollout groups using the rule St+1=Φ(St;{Πk}k∈St,Ft). This scaffold dictates the randomized context for every group, effectively rewriting the objectives of the inner loop at each outer step. By sharing a single randomized rollout group, the framework ensures that the inner loop prepares for each skill withdrawal by training the Director without the candidate skill for the majority of its updates.
To guide the Proposer in selecting the most beneficial tasks, the authors design the Recursive Learnability module. This component serves as the downward channel where the outer loop sets the inner loop's objective. It rewards the Proposer for choosing tasks where rollouts continue to yield diverse outcomes even when the candidate skill is withheld. The learnability of a task is quantified by the curvature of the log-partition function of the proximal step, which corresponds to the outcome variance. Specifically, the recursive target is defined as:
ℓrec(x):=4∂β2logZKx∖kxβ=0=4p−(1−p−)where p− is the success probability when the candidate skill is removed. The Proposer reward is calculated as an empirical-Bayes plug-in estimate of this recursive learnability on the hidden part of the rollout group, discounted when progress is limited to the visible part and penalized upon collapse. This reward mechanism shapes a curriculum that tilts the base model toward tasks exhibiting high recursive learnability.
Complementing this, the Skill Withdrawal module acts as the upward channel, supplying evidence from the inner loop to the outer loop. Its purpose is to minimize the cost of scaffold changes by withdrawing a skill once controlled evaluations demonstrate that the Director performs equally well without it. Because the hidden part of the rollout group is drawn randomly, each group functions as a randomized block. The difference in part means provides an unbiased estimator of the skill's effect:
zx=nv1i∈Vx∑yi−nh1i∈Hx∑yiThese contrasts are accumulated into a Bayesian-bootstrap posterior for each skill. Based on this posterior, the system makes Bayes-optimal decisions to either withdraw or admit skills, ensuring that each withdrawal incurs minimal expected cost. Furthermore, the same posterior mechanism identifies the least helpful skills for revision and distills new skills from groups where both parts fail, seamlessly closing the outer loop.
Experiment
The experiments evaluate R2 Orch on six in-distribution and six held-out benchmarks against six baseline families, testing overall performance, backbone transfer, recursive self-play orchestration, recursive learnability, and skill withdrawal. R2 Orch outperforms all baselines on every benchmark, with gains coming from orchestration rather than backbone training, and its trained Director transfers to other Worker backbones without retraining, especially improving weaker backbones. Ablations confirm that both recursive self-play loops are necessary, that Recursive Learnability selects tasks that continue yielding learning signals as skills are withdrawn, and that Skill Withdrawal removes each skill only once it no longer helps the Director.
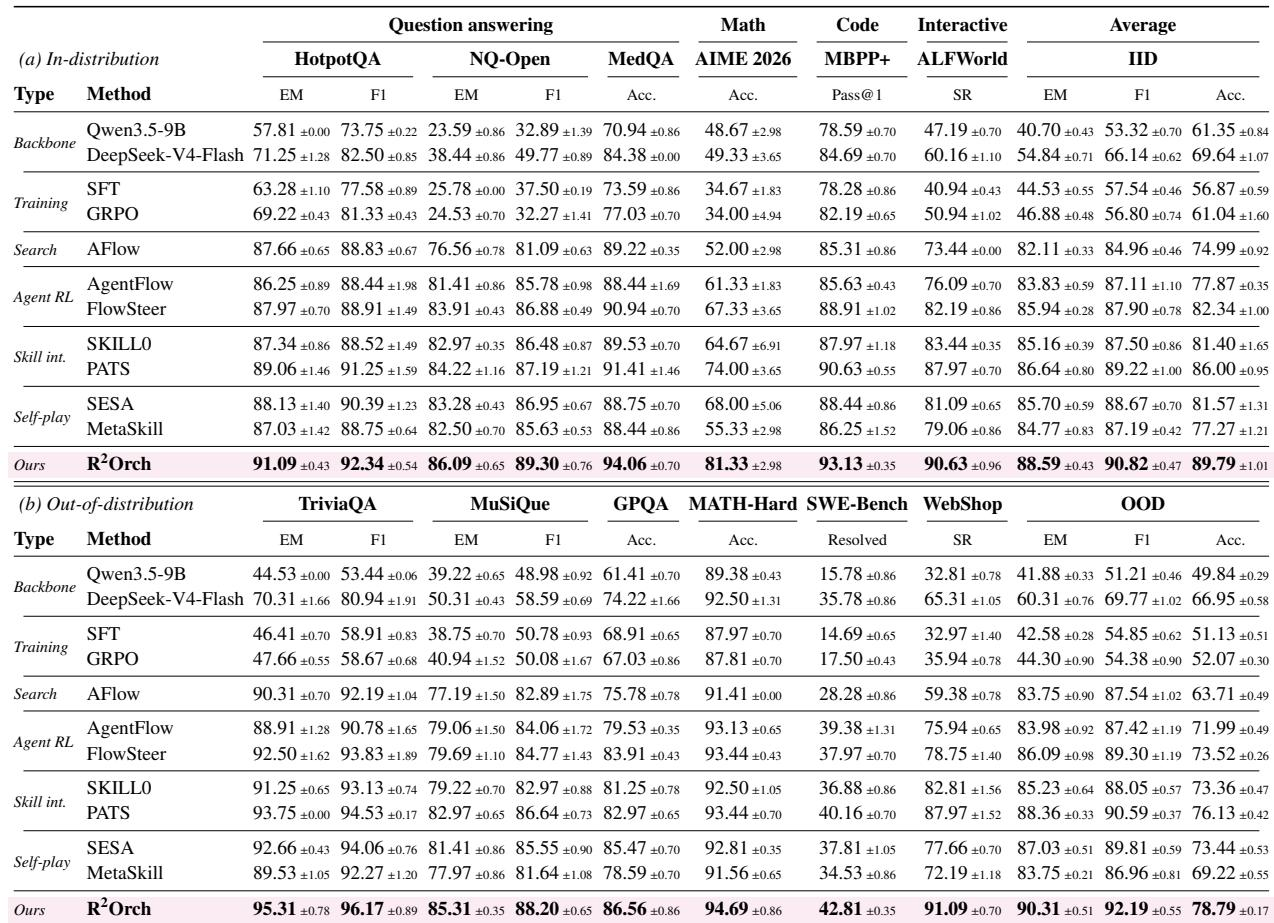
Under a shared protocol with frozen workers and matched compute, R2 Orch outperforms all baselines on every in-distribution and held-out benchmark. The gains come primarily from orchestration rather than backbone training, and the advantage is largest on tasks such as AIME 2026, WebShop, and ALF-World. The trained Director also transfers to other worker backbones without retraining, tightening the performance spread across backbones. R2 Orch is the only method that leads across all twelve benchmarks, with the strongest advantage on tasks where alternative objectives and ablations degrade most. Orchestration of frozen workers contributes more than backbone training alone, and the learned Director transfers across worker backbones without retraining.
The ablation isolates each orchestration component under a zero-skill evaluation. Removing recursive self-play or replacing parts with simpler alternatives reduces accuracy across in-distribution and out-of-distribution benchmarks, while direct prompting of the backbone scores far lower than any orchestration variant. The largest costs appear on interactive tasks such as WebShop and ALF-World, where skill withdrawal and recursive learnability matter most. Direct prompting of the Qwen3.5-9B backbone is much weaker than any orchestration variant, confirming that orchestration drives the gains. Ablations that remove or simplify recursive self-play, recursive learnability, or skill withdrawal reduce zero-skill accuracy, with the largest drops on interactive tasks like WebShop and ALF-World.
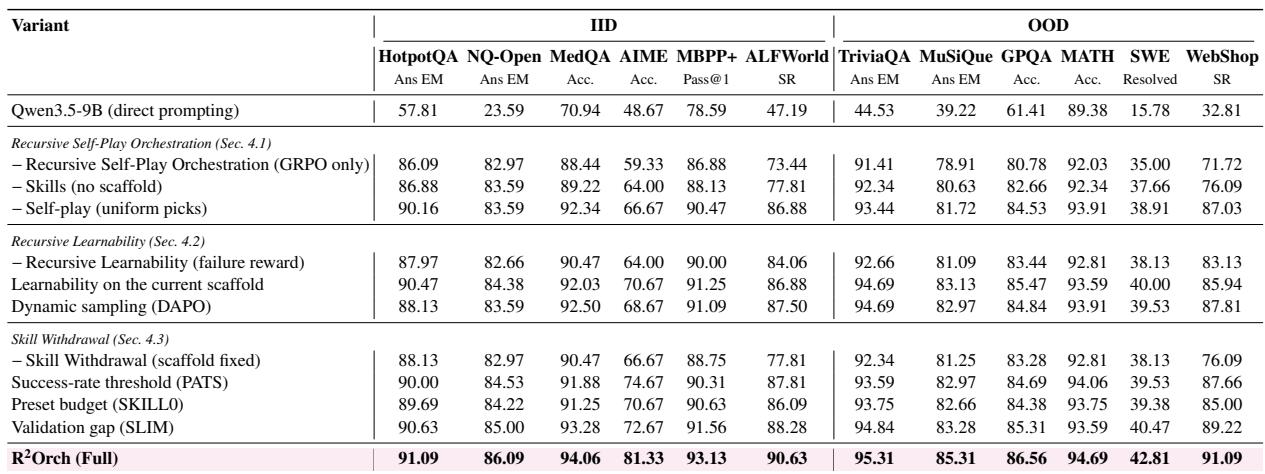
The experiments evaluate R2 Orch against baselines under a shared protocol with frozen workers and matched compute, and separately ablate its orchestration components in a zero-skill setting. The comparison shows that orchestration of frozen workers, rather than backbone training, drives consistent gains, with R2 Orch leading across all twelve benchmarks and its trained Director transferring to other worker backbones without retraining. The ablation confirms that recursive self-play, recursive learnability, and skill withdrawal are important, since removing or simplifying them lowers accuracy across in-distribution and out-of-distribution benchmarks, especially on interactive tasks such as WebShop and ALF-World. Overall, the results attribute R2 Orch's broad advantage primarily to its orchestration mechanism.