Command Palette
Search for a command to run...
Apprendre à penser et à explorer dans un monde 3D
Apprendre à penser et à explorer dans un monde 3D
Yijiang Li Bingyang Wang Nuno Vasconcelos
Résumé
Nous étudions comment les modèles vision-langage (VLM) peuvent apprendre à penser et à explorer activement dans l'espace 3D. Au lieu de fournir au modèle des images multi-vues, des vidéos ou des représentations 3D, nous préservons l'encodage visuel natif des VLM, c'est-à-dire une image unique, une à la fois, tout comme les humains, et traitons la représentation 3D uniquement comme un environnement avec lequel le modèle peut interagir par des actions (par exemple, se déplacer vers la gauche) et des observations (images rendues). Chaque trajectoire débute par une vue initiale à la première personne et une question visuelle. Le modèle peut ensuite raisonner, naviguer et réorienter son point de vue de manière itérative avant de s'engager dans une réponse finale. Après un affinage initial supervisé par trajectoires, nous appliquons un apprentissage par renforcement (RL) dont les récompenses sont principalement déterminées par l'exactitude de la réponse finale. Fait crucial, le RL n'exerce aucune supervision directe sur les points de vue que le modèle devrait visiter ni sur les actions d'exploration qu'il devrait entreprendre. Au lieu de cela, le modèle doit apprendre une politique d'exploration efficace uniquement à partir de la mesure dans laquelle ses interactions améliorent les performances. Sur six référentiels 3D, notre modèle ACT3D atteint une exactitude moyenne de 53,2 %, ce qui améliore son modèle de base Qwen de 22,0 % et surpasse le modèle propriétaire Gemini 3.6 Flash. ACT3D surpasse également les méthodes 3D open source existantes tout en utilisant 50 à 70 % de trames d'entrée en moins, et se généralise à des domaines inédits avec une amélioration moyenne de 5,9 % par rapport à son initialisation supervisée. Une analyse plus poussée révèle une exploration adaptative, conditionnée par la question. Les gains de performance par rapport au modèle de base passent de 0,6 % pour les questions auxquelles il est possible de répondre depuis la vue initiale à 16,3 % pour celles exigeant une exploration approfondie. ACT3D recherche les cibles occultées, évite les explorations inutiles et acquiert des points de vue complémentaires pour les comparaisons spatiales. Ces résultats démontrent que le RL fondé sur le résultat permet aux VLM non seulement de raisonner sur des preuves visuelles, mais aussi d'apprendre quand et comment les acquérir. Notre page de projet est https://williamium3000.github.io/act3d/.
One-sentence Summary
Researchers at University of California San Diego and Georgia Institute of Technology propose ACT3D, which learns to think and actively explore 3D environments from single first-person views through trajectory-supervised finetuning plus outcome-based reinforcement learning without viewpoint supervision, attaining 53.2% average accuracy across six benchmarks, improving its base Qwen model by 22.0%, and surpassing proprietary Gemini 3.6 Flash while using 50−−70% fewer input frames.
Key Contributions
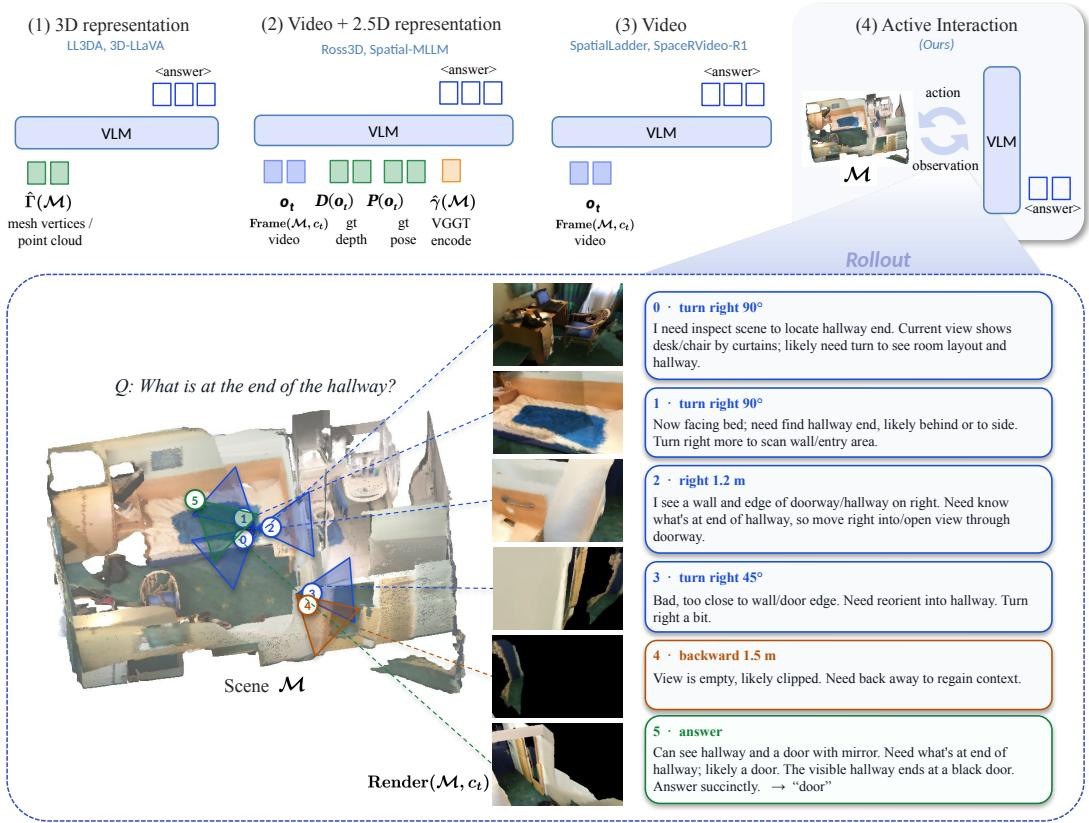
- ACT3D treats 3D scene representations as interactive environments, allowing a vision-language model to answer visual questions from single-image observations by iteratively navigating, reorienting, and acquiring new viewpoints.
- The model is first tuned with trajectory-supervised finetuning, then optimized with reinforcement learning using rewards based mainly on final-answer correctness, without direct supervision over which viewpoints to visit or exploration actions to take.
- Across six 3D benchmarks, ACT3D achieves 53.2% average accuracy, improves its base Qwen model by 22.0%, surpasses proprietary Gemini 3.6 Flash, and outperforms existing open-source 3D methods while using 50-70% fewer input frames; analysis shows adaptive, question-conditioned exploration and larger gains on questions requiring extensive exploration.
Introduction
Most prior 3D vision-language models assume that the visual information needed for spatial reasoning is already provided, such as complete RGB-D scans, multi-view images, videos, point clouds, or meshes. This limits their ability to handle partially observable settings where a model must determine what evidence is missing and how to obtain it. The authors address this gap by framing 3D reasoning as an interactive visual decision process: the scene remains an external environment, and the model collects evidence through sequential navigation and viewpoint actions before answering. Their main contribution is Act3D, a vision-language model that jointly learns evidence acquisition and reasoning, using supervised fine-tuning to establish the interaction protocol and reinforcement learning with final-answer rewards to optimize the full interactive policy.
Method
The authors train a vision-language model to perform interactive 3D reasoning under partial observability. The learning pipeline consists of two stages: trajectory-supervised fine-tuning, which establishes a basic reason-act-observe interaction policy, and outcome-driven reinforcement learning, which optimizes the policy using only final answer rewards without supervising intermediate viewpoints or actions.
Reasoning as a partially observable decision process
The task is formalized as a partially observable Markov decision process. A task instance is
w=(M,q,y⋆)∼D,where M is a reconstructed 3D scene, q is a question, and y⋆=g(M,q) is the ground-truth answer. At step t, the environment state is
st=(M,ct),where the camera configuration ct=(et,ft) consists of a camera position et∈R3 and a viewing direction ft∈S2. The scene remains hidden, while the policy observes the rendered egocentric view
ot=Render(M,ct).The policy selects navigation actions from a relative action space. A navigation action is
at=(ξt,nt)∈Anav=U×{1,…,8},where ξt is a motion primitive and nt is an integer multiplier. The primitive set U contains six translations, forward, backward, left, right, up, and down, and four rotations, turn left, turn right, turn up, and turn down. Each primitive has a unit step δξt, and the resulting camera transition is deterministic:
(et+1,ft+1)={(ΠB(et+ntδξtut),ft),(et,Rotkt(ntδξt)ft),translation,rotation.Here ΠB projects the camera position onto the scene bounding box enlarged by a fixed margin. The authors adopt this relative parameterization because it is camera-centric and scale-invariant, in contrast to an absolute parameterization that requires predicting global coordinates directly.
The action set also includes terminal answer actions
Aˉ=Anav∪Astop,where Astop={STOP(y):y∈V}. Executing STOP(y) ends the episode and returns y as the predicted answer.
The policy conditions on the full interaction history
ht=(q,o0,z0,a0,c1,o1,z1,…,at−1,ct,ot,zt),where zt denotes intermediate reasoning generated by the model. Instead of maintaining an explicit belief state over the hidden scene, the VLM implicitly encodes accumulated evidence through this history.
The optimization objective is the expected finite-horizon, undiscounted return
θmaxJ(θ)=Ew∼DEτ∼πθ⊗E[R(τ)],where E is the deterministic interactive environment and R(τ) is the outcome reward defined below. Policy quality is measured by answer accuracy
Acc(π)=w∼D,τ∼π⊗EPr(y=y⋆).Trajectory-supervised policy initialization
To initialize interaction competence, the authors first perform supervised fine-tuning on curated reason-act-observe trajectories. These trajectories are generated by a large language model interacting with the same environment. The demonstrations are filtered to retain only correct answers, valid interactions, well-formed reasoning, and sufficient visible scene evidence.
For a curated demonstration τ⋆, the supervised objective is
LSFT(θ)=−Eτ⋆∼Dtrajℓ∈I(τ⋆)∑logπθ(τℓ⋆∣τ<ℓ⋆),where I(τ⋆) indexes model-generated tokens. Environment observations and prompt tokens are masked from the loss. This stage initializes the interaction protocol and a useful behavioral prior, but does not prescribe a single exploration strategy.
Outcome-driven reinforcement learning
Starting from the supervised initialization, the authors optimize the full interactive policy with reinforcement learning. For each initial condition
x=(q,o0),they sample a group of G rollouts from the current policy and the deterministic environment. Because actions determine subsequent observations, different rollouts from the same initial condition can acquire substantially different evidence for the same question.
The verifiable reward for a rollout τ with final answer y is
R(τ)=λjudgeRjudge+λEMREM+λintRjudgec(τ)−λfmtRfmt.The first two terms measure answer correctness. Rjudge∈{0,1} is the verdict of an LLM judge that checks whether y is semantically equivalent to the ground-truth answer y⋆, while REM∈{0,1} indicates exact match with an annotated answer. The interaction reward is credited only when the answer is correct. It also includes a grounding shortcut:
c(τ)={Nmax,min{nint,Nmax},Rgnd=1,otherwise.Here nint is the number of interactions in the rollout, and Rgnd∈{0,1} indicates whether the annotated object of interest was visible in some rendered view. A correct rollout that actually observed the asked-about object receives the full interaction credit, while a correct rollout that never observed it still accrues credit per interaction up to the same cap. The reward therefore pays for acquiring useful evidence rather than for looking without grounding. The final term Rfmt∈{0,1} penalizes malformed outputs such as a missing or empty answer.
The policy is optimized with Group Relative Policy Optimization. For each rollout group, the reward is standardized as
A^i=stdjR(τj)R(τi)−meanjR(τj).The same trajectory-level advantage is assigned to all model-generated tokens in τi, while environment observations are excluded from optimization. The GRPO objective is
JGRPO(θ)=Ew,{τi}G1i=1∑G∣I(τi)∣1ℓ∈I(τi)∑min(πθold(τi,ℓ∣τi,<ℓ)πθ(τi,ℓ∣τi,<ℓ)A^i,clip(πθold(τi,ℓ∣τi,<ℓ)πθ(τi,ℓ∣τi,<ℓ),1−ϵ,1+ϵ)A^i)−βDKL(πθ∥πref).Because reasoning and interaction are generated by the same autoregressive policy, the episode-level reward assigns credit across the entire rollout. This allows the model to learn not only how to reason over acquired observations, but also which observations to acquire in the first place.
Experiment
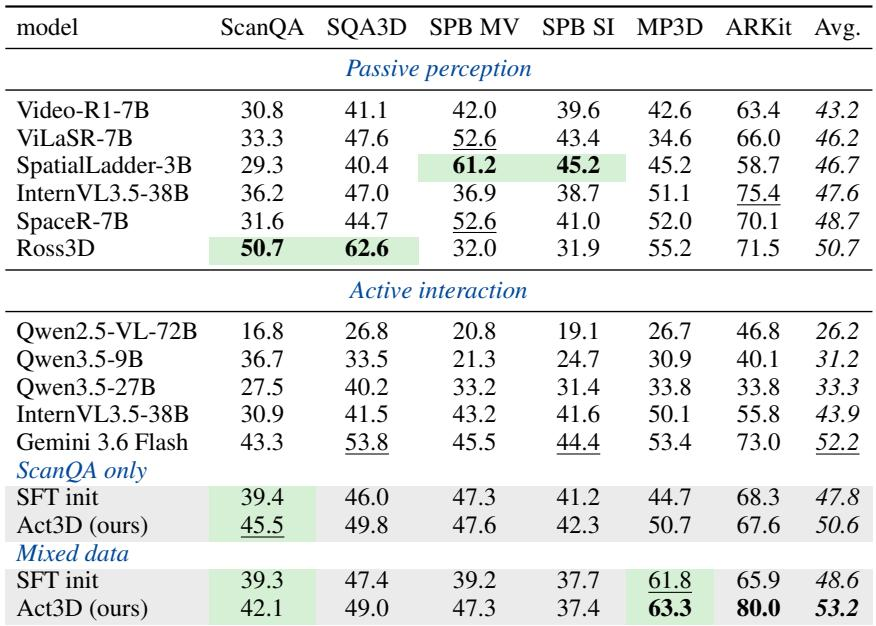
Act3D is evaluated with Qwen3.5-9B as the base model under SFT followed by GRPO, using both ScanQA-only and mixed-data training, and is assessed on six benchmarks with a unified interactive protocol against active and passive baselines. The main results validate that RL after supervised initialization improves reasoning and transfers beyond the training domain, with mixed-data training providing the strongest overall performance. Analyses show that RL reshapes exploration behavior, adaptive viewpoint selection emerges, and gains are largest for questions requiring more visual evidence. Ablations indicate that single-view initialization, rendered observations, relative camera actions, and supervised warm-start are beneficial, while the interaction reward mainly encourages broader exploration and can aid cross-domain generalization without uniformly improving accuracy.
Act3D trained on mixed data attains the highest average accuracy across six 3D reasoning benchmarks, surpassing evaluated open-source passive and active methods as well as the Gemini 3.6 Flash baseline under the same interaction protocol. It operates from a single initial view and autonomously acquires additional visual evidence through interaction. Reinforcement learning after supervised initialization improves overall accuracy, with especially large gains on ARKit and SPBench-MV, and ScanQA-only reinforcement learning transfers improvements to several other benchmarks. Mixed-data Act3D outperforms all compared open-source 3D reasoning methods and exceeds Gemini 3.6 Flash under the same interaction protocol. Reinforcement learning over supervised initialization improves average accuracy, with the largest gains on ARKit and SPBench-MV. Reinforcement learning trained only on ScanQA also improves held-out benchmarks such as MP3D and SQA3D, indicating transferable capabilities.
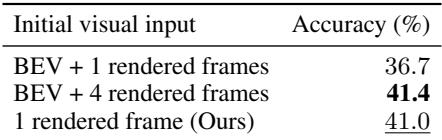
On ScanQA, initial visual input meaningfully impacts accuracy. A single rendered view performs comparably to a bird's-eye view combined with four rendered views, while a bird's-eye view plus one rendered view is less effective. The results suggest that additional initial views do not necessarily improve performance and support single-view initialization. A single rendered initial view matches the accuracy of a bird's-eye view with four rendered views. Combining a bird's-eye view with one rendered view reduces accuracy relative to the other configurations. More initial visual context does not guarantee better interactive reasoning performance.
The experiments evaluate Act3D across six 3D reasoning benchmarks under an interactive protocol, where mixed-data training achieves the highest average accuracy among open-source methods and the Gemini 3.6 Flash baseline while starting from a single initial view. Reinforcement learning after supervised initialization improves overall performance, especially on ARKit and SPBench-MV, and ScanQA-only reinforcement learning transfers gains to held-out benchmarks such as MP3D and SQA3D. Ablations on initial visual input show that a single rendered view performs comparably to a bird's-eye view combined with four rendered views, while adding only one rendered view to the bird's-eye view reduces accuracy, suggesting that more initial views do not necessarily improve interactive reasoning.