Command Palette
Search for a command to run...
Récupérer une supervision fiable via une distillation on-policy guidée par la critique
Récupérer une supervision fiable via une distillation on-policy guidée par la critique
Kaixiang Zhao Tianrun Yu Shangzhe Li Yuxiao Yang Amanda Hughes Weitong Zhang Taylor W. Killian
Résumé
La distillation on-policy (OPD) entraîne un modèle élève sur ses propres trajectoires avec une supervision au niveau du jeton fournie par un enseignant, en supposant que l'enseignant peut atteindre une réponse correcte à partir de n'importe quel préfixe écrit par l'élève. Nous appelons cette propriété la récupérabilité de l'enseignant et montrons qu'elle échoue sur les trajectoires incorrectes : l'enseignant suit les erreurs de l'élève, bien qu'il les reconnaisse. Nous proposons CriticOPD, qui utilise la reconnaissance d'erreur pour restaurer la récupérabilité. L'enseignant critique une trajectoire incorrecte, ce qui permet à l'élève de réécrire sa solution après l'erreur. La sortie obtenue, qui inclut la critique comme information privilégiée, est notée par l'enseignant, tandis que l'élève utilise la révision sans la critique pour l'entraînement. Sur deux modèles étudiants Qwen3 et six bancs d'essai de raisonnement mathématique, CriticOPD améliore l'OPD, les gains les plus importants étant observés sur les problèmes de compétition. Le code est disponible à l'adresse github.com/kzhao5/CriticOPD.
One-sentence Summary
Researchers from Brigham Young University and the University of North Carolina at Chapel Hill propose CriticOPD, a critique-guided on-policy distillation method that restores teacher recoverability by having the teacher identify errors, letting the student rewrite its solution, and scoring the revision with the critique as privileged information while the student trains on the revision without it; CriticOPD improves on-policy distillation on two Qwen3 students and six mathematical reasoning benchmarks, with the largest gains on competition problems.
Key Contributions
- The paper introduces teacher recoverability in on-policy distillation and shows empirically that recoverability drops sharply on incorrect student rollouts, leaving many training tokens supervised from prefixes where the teacher rarely recovers correctly.
- The paper proposes CriticOPD, in which the teacher critiques an incorrect rollout, the student rewrites from the last error using that feedback, and the critique serves only as privileged scoring context rather than as part of the student training signal.
- Experiments on two Qwen3 student models and six mathematical reasoning benchmarks show that CriticOPD improves on-policy distillation, with the largest gains on competition problems, and code is available.
Introduction
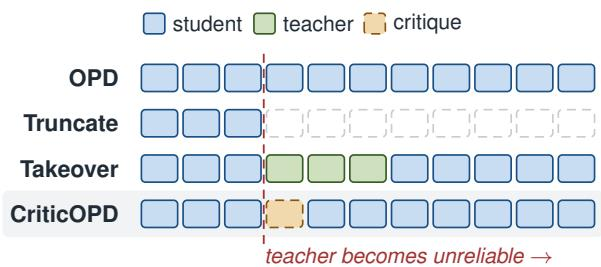
On-policy distillation (OPD) trains a student on its own rollouts with token-level teacher supervision, reducing the occupancy mismatch that hurts offline distillation when inference prefixes differ from training prefixes. However, teacher supervision becomes unreliable after the student makes an error because the teacher often follows the student’s mistake rather than correcting it, and prior remedies either truncate supervision or let the teacher take over generation, which reintroduces occupancy mismatch. The authors propose Critic-OPD, where the teacher critiques an incorrect rollout and the student rewrites from the last error, while the critique is used only as privileged context for scoring during training. This improves teacher recoverability on revised trajectories, keeps every supervised token student-generated, and requires no feedback at inference.
Method
The authors introduce CriticOPD to address the issue where a teacher model fails to continue correctly after a student makes an error, even though the teacher can still recognize those errors. The method constructs training sequences based on the states the student reaches during inference, minimizing occupancy mismatch while ensuring reliable teacher supervision. The process involves a critique and rewrite mechanism followed by a specific training objective.
The process begins with the student generating a rollout y for a given problem x using a training prompt. If the rollout is incorrect or reaches the length limit without an answer, it is sent for critique and rewriting. Correct rollouts are trained using standard Online Policy Distillation (OPD).
The teacher acts as the critic. It receives the problem, the reference answer, and the student's solution formatted in numbered paragraphs. The teacher identifies errors in the solution, listing the paragraph index, the erroneous sentence, and a short fix for each. These errors are combined with the reference answer to form a critique c. The inclusion of the reference answer allows the teacher to critique problems it cannot solve itself. If no complete error is found in the critique, the rollout is trained with standard OPD.
To determine the cut point, the student retains its prefix up to the paragraph containing the last error identified in the critique and discards the remainder. The discarded part starts at position τ, so the retained prefix is hτ=(x,y<τ). This prefix contains all errors from the critique, ensuring the rewrite starts from the erroneous states where teacher recoverability typically declines.
The student then appends the critique c to the retained prefix using a feedback prompt and generates a new suffix, resulting in the revised rollout y~. The tokens before τ remain unchanged (y~<τ=y<τ), and the student samples the suffix with the critique in its context. Unlike teacher takeover, the student writes every token of the training sequence.
As shown in the figure below:
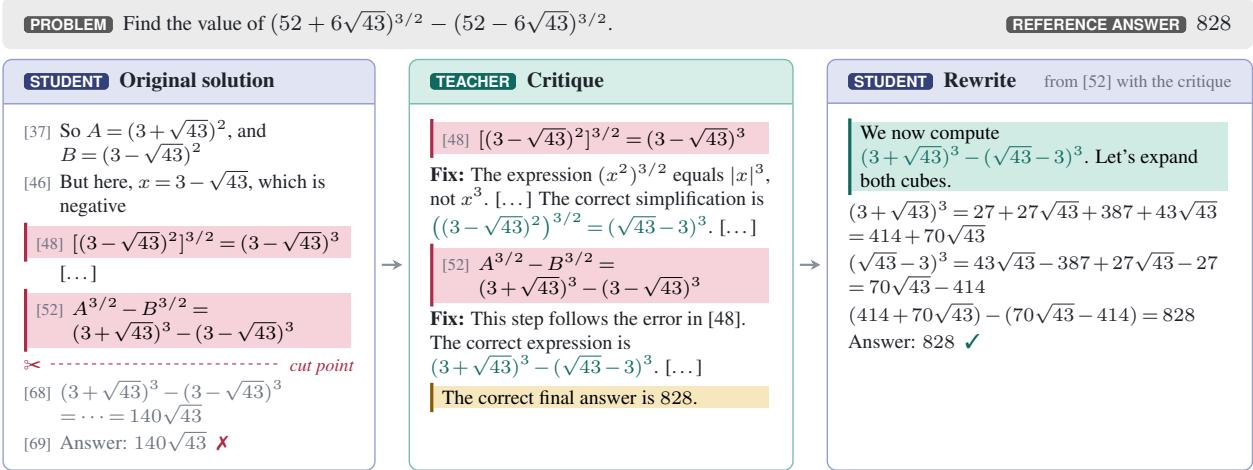
The critique identifies errors in the original solution, and the student rewrites from the last error to reach the correct answer. The authors also evaluate the recoverability of the teacher on these rewrites compared to the original rollouts. Recoverability is estimated as the fraction of correct answers among eight continuations from each prefix.
As shown in the figure below:
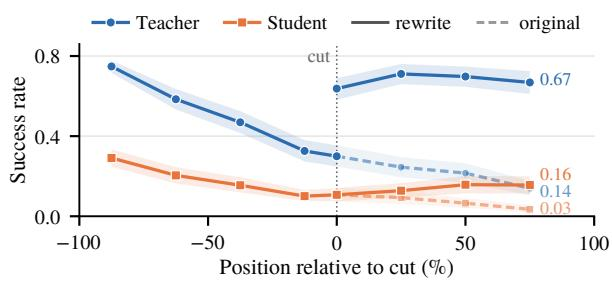
The figure illustrates that the teacher is significantly more reliable on the rewrite than on the original rollout. At 75% of the continuation, the recoverability of the teacher is 0.14 on the original rollout and 0.67 on the rewrite. Similarly, the success rate of the student without the critique rises from 0.03 to 0.16.
The training objective combines standard OPD for correct rollouts and feedback distillation for rollouts with a valid critique.
For correct rollouts and those without a valid critique, the authors minimize the reverse KL divergence at each student-generated prefix ht:
LOPD(y)=t=1∑∣y∣KL(πθ(⋅∣ht)∥πT(⋅∣ht))This uses the sampled-token advantage.
For rollouts with a valid critique, the training focuses on the revised sequence y~. Let h~t=(x,y~<t) denote its prefix without the critique. The teacher scores the rewrite with the critique c in its context, while the student does not see it. The feedback distillation loss is defined as:
Lfb(y~;c)=t=τ∑∣y~∣KL(πθ(⋅∣h~t)∥πT(⋅∣h~t,c))Only the rewritten suffix receives supervision because the retained prefix contains errors at states where the teacher has low recoverability. Each suffix token receives the sampled-token advantage:
Atfb=logπT(y~t∣h~t,c)−logπθ(y~t∣h~t)Since the suffix is sampled with the critique but the student's log-probabilities are computed without it, this update serves as a surrogate rather than an unbiased gradient.
The overall objective minimizes Lours=LOPD+Lfb, where each loss sums over its respective rollouts in the batch. Compared with standard OPD, the teacher target changes from πT(⋅∣ht) to πT(⋅∣h~t,c), under which the teacher is much more recoverable. The student learns without the critique and requires no feedback at inference.
Experiment
The study evaluates critique-guided on-policy distillation using Qwen3-1.7B and Qwen3-0.6B students distilled from a Qwen3-4B teacher on DAPO-Math-17k, with assessment on AIME, AMC, MATH500, OlympiadBench, and Minerva Math, plus ablations and reliability analyses. Teacher continuation accuracy drops after student errors because the teacher tends to follow incorrect prefixes, but its ability to flag valid errors remains stable. CriticOPD improves over OPD and related baselines, with the critique being the most important component, and it helps the teacher assign token-level credit to corrections; gains concentrate on post-error states where the student learns to recover from its own mistakes, while outside mathematics performance is largely preserved.
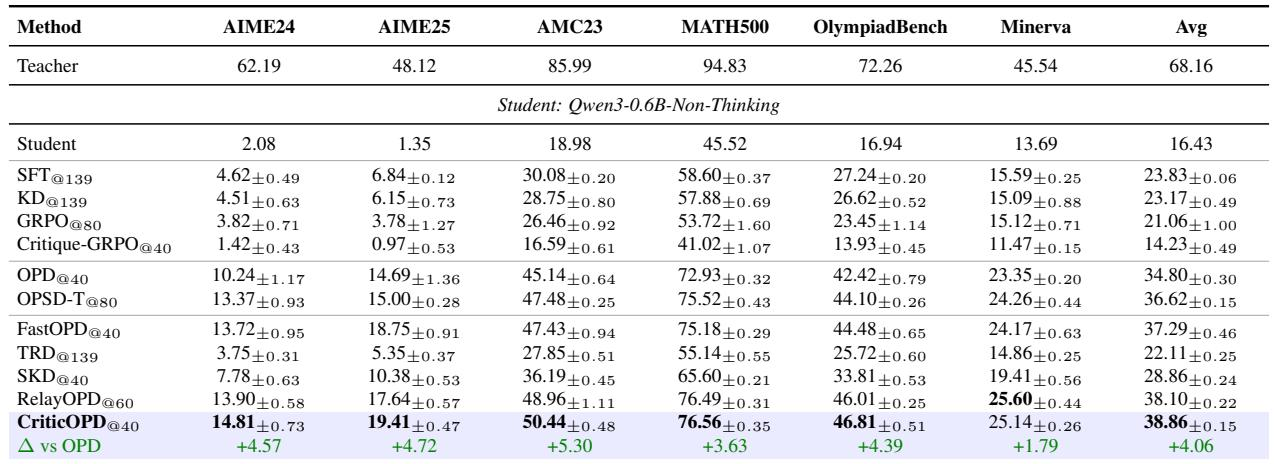
CriticOPD improves average mathematical reasoning accuracy over the OPD baseline at both tested Qwen3 scales, with the largest gains on competition-style benchmarks including AIME and AMC. It outperforms FastOPD and RelayOPD and is the best student method on most mathematical benchmarks at both scales. Ablations show that answer-only or generic feedback is less effective, and removing the critique causes the largest performance drop. CriticOPD achieves the best student accuracy on most mathematical benchmarks at both tested scales and improves over OPD at both scales. The largest gains appear on AIME 2024, AIME 2025, and AMC 2023, indicating stronger improvements on competition-style reasoning. Feedback ablations show the critique is essential; removing it causes a large accuracy drop, while answer-only guidance falls below the OPD baseline.
The ablation isolates the main components of the feedback and training setup. The critique is the most important feedback element, while removing the reference answer or using generic feedback causes smaller average declines. The feedback also matters more for scoring the suffix than for which model writes the suffix, indicating the critique improves both the rewritten suffix and the reliability of teacher scoring. Removing the critique produces the largest average drop among the feedback changes. Removing the reference answer or replacing the feedback with generic text leads to smaller average declines than removing the critique. Using a teacher-written suffix instead of a student-written suffix has a smaller effect than scoring the suffix without feedback. Scoring the suffix without the feedback causes a larger average drop, indicating that the critique supports reliable teacher scoring.
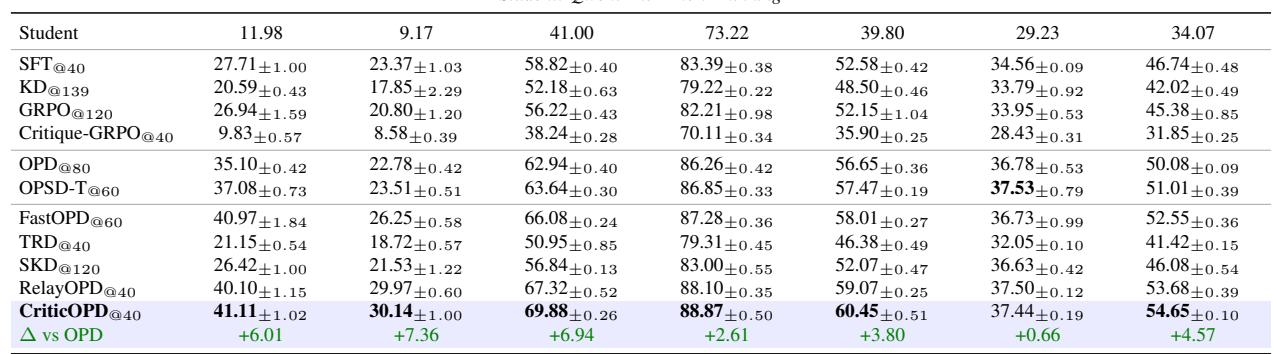
CriticOPD improves mathematical reasoning accuracy over the OPD baseline at both tested Qwen3 scales, with the largest gains on competition style benchmarks such as AIME and AMC, and it outperforms FastOPD and RelayOPD as the best student method on most mathematical benchmarks. Ablations show that the critique is the most important feedback component, since removing it causes the largest performance drop, while answer only or generic feedback and teacher written suffixes have smaller effects. Feedback also matters more for scoring the suffix than for which model writes it, indicating that the critique improves both the rewritten suffix quality and the reliability of teacher scoring.