Command Palette
Search for a command to run...
Résidus d’attention multi-flux (Multi-Stream Attention Residuals)
Résidus d’attention multi-flux (Multi-Stream Attention Residuals)
Xiaohan Qin Xiangdong Zhang Tuo Dai Sunan Zou Huaijin Wu Yebin Yang Zhuo Xia Lin Yao Yuliang Liu Junchi Yan
Résumé
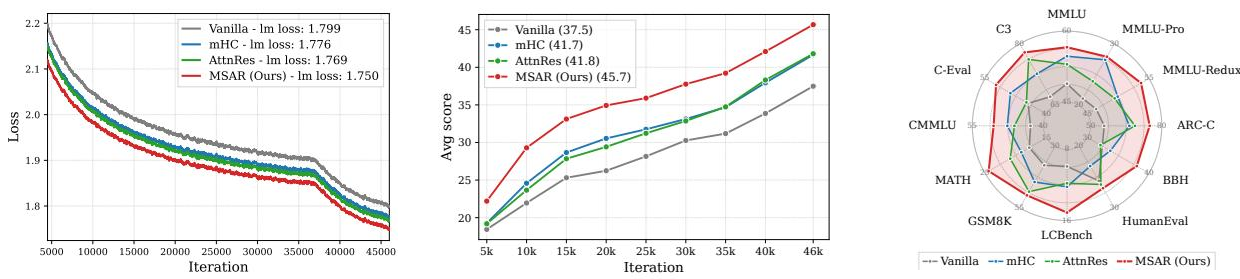
Les résidus d’attention (AttnRes) permettent une récupération dépendante du contenu sur la profondeur du réseau, ce qui peut être vu comme une attention softmax à flux unique le long de l’axe de profondeur. Inspirés par le succès de l’attention multi-têtes le long de l’axe de séquence, nous introduisons les résidus d’attention multi-flux (Multi-Stream Attention Residuals, MSAR), une extension d’AttnRes qui généralise ce mécanisme à une attention de profondeur multi-têtes, offrant des gains de performance substantiels avec un surcoût supplémentaire minimal. MSAR tire la diversité des flux du contexte de séquence au moyen de convolutions causales multi-échelles, permettant à différentes têtes de récupérer des représentations historiques à travers des vues contextuelles distinctes tout en préservant l’intégrité de la représentation cachée. Les flux récupérés sont combinés par un mélange adaptatif léger pour générer l’entrée de couche à flux unique. En conservant des sources à flux unique et en les étendant à la demande, MSAR prend en charge le calcul multi-flux sans nécessiter de stockage ni de communication multi-flux persistants. Sur l’ensemble des 12 bancs d’essai en aval aux échelles MoE de 18B et 28B, MSAR surpasse systématiquement les variantes résiduelles antérieures, y compris les connexions résiduelles standard, les hyper-connexions sous contrainte de variété (mHC) et AttnRes. Les expériences de lois d’échelle donnent une accélération de calcul à perte égale de 1,58× par rapport à la base résiduelle standard, contre 1,35× pour AttnRes et 1,30× pour mHC. Ces résultats font de MSAR une architecture résiduelle prometteuse pour le pré-entraînement à grande échelle.
One-sentence Summary
Researchers from Shanghai Jiao Tong University and collaborators propose Multi-Stream Attention Residuals (MSAR), an extension of Attention Residuals that generalizes single-stream depth attention to multi-head depth attention via multi-scale causal convolutions and lightweight adaptive mixing, outperforming standard residual connections, manifold-constrained Hyper-Connections (mHC), and Attention Residuals across all 12 downstream benchmarks at the 18B and 28B MoE scales and yielding a 1.58× iso-loss compute speedup over the standard residual baseline.
Key Contributions
- Multi-Stream Attention Residuals (MSAR) extends single-stream Attention Residuals to multi-head depth attention by using multi-scale causal convolutions for stream diversity and lightweight adaptive scalar mixing to combine retrieved streams.
- The method preserves single-stream persistent source storage and pipeline communication costs by expanding to multiple streams only during computation, while remaining compatible with AttnRes cross-stage caching and two-phase inference with minimal parameter and training FLOPs overhead.
- At 18B and 28B MoE scales, MSAR consistently outperforms standard residual connections, manifold-constrained Hyper-Connections (mHC), and Attention Residuals (AttnRes) across all 12 downstream benchmarks, and scaling-law experiments show a 1.58× iso-loss compute speedup over the standard residual baseline versus 1.35× for AttnRes and 1.30× for mHC.
Introduction
Scaling Transformer-based LLMs by depth often produces diminishing returns in modern PreNorm architectures because a single residual stream accumulates fixed additive updates, causing early-layer features to become diluted and harder for later layers to retrieve. Recent residual redesigns address this by introducing multiple streams, such as Hyper-Connections and mHC, or by replacing fixed accumulation with depth-wise softmax retrieval, as in Attention Residuals (AttnRes). These methods can be interpreted as attention-like mechanisms along the depth axis, but extending AttnRes-style depth attention to multi-head retrieval has been difficult: channel-splitting the hidden state breaks its coherence, and HC-style full-dimensional candidate streams tend to collapse to nearly identical keys after normalization. The authors propose Multi-Stream Attention Residuals (MSAR), which uses low-cost multi-scale causal depthwise convolutions to create diverse full-dimensional streams from sequence context, performs per-stream depth attention, and fuses retrieved states with lightweight mixing. This turns residual retrieval into a multi-head depth-attention primitive while keeping training FLOPs and parameter overhead minimal.
Method
The authors formalize residual connectivity as a depth-mixing problem. In a standard Transformer stack, each residual branch receives a hidden state hl∈Rd and produces an update fl(hl). The standard residual recurrence is
hl+1=hl+fl(hl).By defining v0=h1 and vi=fi(hi) for i≥1, unrolling this recurrence gives
hl=i=0∑l−1vi.Thus, conventional residuals perform depth mixing with fixed unit coefficients over all previous sources. Building on this view, the authors propose Multi-Stream Attention Residuals, or MSAR, which expands residual sources into multiple streams and applies learned depth attention to each stream.
In MSAR, each residual source vi is expanded into m streams. The first stream is the identity stream, vi(0)=vi. For the remaining streams, the authors use lightweight causal depthwise 1D convolutions over neighboring tokens. Restoring the token index t, the expansion is
\mathbf{v}_{i,t}^{(r)}=\sum_{\delta=0}^{\kappa_r-1}\mathbf{c}_{i,r,\delta}\odot\mathbf{v}_{i,t-\delta},\quad r=1,\dots,m-1,$$ where $\mathbf{c}_{i,r,\delta}\in\mathbb{R}^d$ contains channel-wise convolution weights and $\kappa_r$ controls the local receptive field. In the main configuration, the authors retain the original stream and add three causal convolutions with kernel sizes $\{4,8,12\}$, yielding $m=4$ streams. This construction provides multiple contextual views of each residual source without introducing dense projection layers. Each expanded stream is treated as an independent depth-attention head. A target layer $l$ has one learned pseudo-query per stream, $\mathbf{q}_l^{(r)}=\mathbf{w}_l^{(r)}$. The keys are the expanded sources, $\mathbf{k}_i^{(r)}=\mathbf{v}_i^{(r)}$. Within each stream, attention weights are computed by a softmax over all previous depth sources: $$\alpha_{i\to l}^{(r)}= \frac{\phi(\mathbf{q}_l^{(r)},\mathbf{k}_i^{(r)})} {\sum_{j=0}^{l-1}\phi(\mathbf{q}_l^{(r)},\mathbf{k}_j^{(r)})},$$ where\phi(\mathbf{q},\mathbf{k})=\exp\left(\mathbf{q}^{\top}\operatorname{RMSNorm}(\mathbf{k})\right).
The retrieved state for stream $r$ is\mathbf{z}l^{(r)}=\sum{i=0}^{l-1}\alpha_{i\to l}^{(r)}\mathbf{v}_i^{(r)}.
The resulting multi-stream states are collected as $\mathbf{Z}_l=[\mathbf{z}_l^{(0)},\dots,\mathbf{z}_l^{(m-1)}]^{\top}\in\mathbb{R}^{m\times d}$. Because these streams must be merged into a single layer input, the authors use a lightweight manifold-constrained hyper-connection style mixer: $$\mathcal{H}_l^{\mathrm{pre}}= \sigma\left(\alpha_l^{\mathrm{pre}} \operatorname{RMSNorm}\left(\operatorname{Flatten}(\mathbf{Z}_l)\right) \mathbf{W}_l^{\mathrm{pre}}+\mathbf{b}_l^{\mathrm{pre}}\right) \in\mathbb{R}^{1\times m}.$$ Here $\mathbf{W}_l^{\mathrm{pre}}\in\mathbb{R}^{md\times m}$, $\alpha_l^{\mathrm{pre}}$ is a learnable scaling factor, $\mathbf{b}_l^{\mathrm{pre}}\in\mathbb{R}^{1\times m}$ is a per-stream bias, and $\sigma$ is the sigmoid function. The final target layer input is a weighted sum of the retrieved streams: $$\mathbf{h}_l=\left(\mathcal{H}_l^{\mathrm{pre}}\mathbf{Z}_l\right)^{\top} =\sum_{r=0}^{m-1}\left[\mathcal{H}_l^{\mathrm{pre}}\right]_r\mathbf{z}_l^{(r)}.$$ Directly applying MSAR at every residual branch would require storing every layer output. To reduce memory and pipeline communication overhead, the authors introduce Block MSAR. The $L$ residual branches are partitioned into $N$ contiguous blocks. Inside each block, updates accumulate in a single stream. The completed summary of block $n$ is\mathbf{b}n=\sum{j\in\mathcal{B}_n}f_j(\mathbf{h}_j),
with the embedding retained as the initial source $\mathbf{b}_0=\mathbf{h}_1$. For a target layer $l$ inside block $n$, the current block contributes a partial summary of its preceding outputs:\mathbf{b}n^{<l}=\sum{\substack{j\in\mathcal{B}_n\ j<l}}f_j(\mathbf{h}_j).
Depth attention is then performed over the embedding, completed block summaries, and the current partial summary. For each stream $r$, $$\mathbf{z}_l^{(r)}= \sum_{j=0}^{n-1}\alpha_{j\to l}^{(r)}\mathcal{E}_r[\mathbf{b}_j] +\alpha_{n\to l}^{(r)}\mathcal{E}_r[\mathbf{b}_n^{<l}],$$ where $\mathcal{E}_r$ denotes the causal convolutional expansion for stream $r$. At the first layer of a block, the current partial source is absent and is omitted from both the retrieval sum and the softmax denominator. The resulting design is compared with standard residual accumulation and Block AttnRes below. 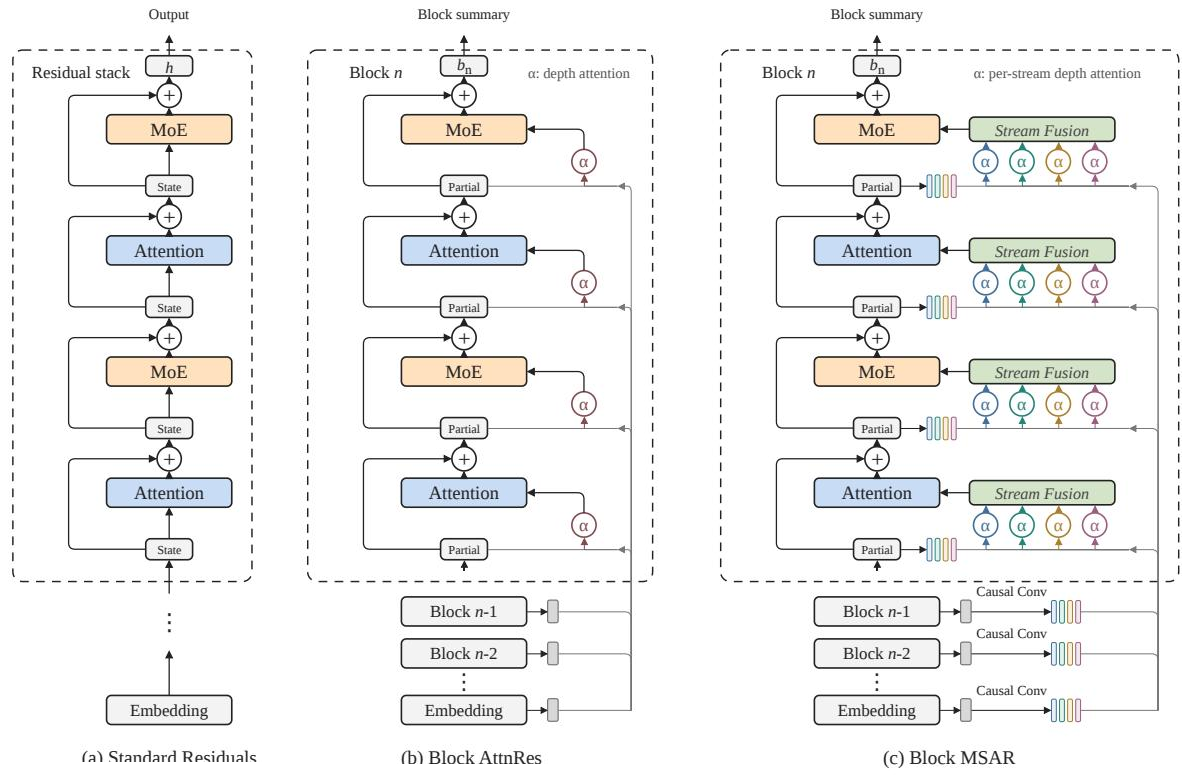 Standard residual connections maintain a single accumulated residual stream. Block AttnRes attends over block-level summaries but uses single-stream sources. Block MSAR instead expands each block-level source into multiple context-dependent streams before applying per-stream depth attention, then fuses the retrieved streams into the target layer input. The authors further design the method for efficient large-scale training. Since the expanded streams are deterministic functions of single-stream block summaries, Block MSAR stores and communicates only the single-stream summaries. This reduces persistent source storage and pipeline communication compared with storing all expanded streams. Because all target layers in a block share the same completed summaries, the computation is split into two phases. First, the learned pseudo-queries for all target layers in a block are batched against the completed sources to compute per-stream retrieval results and softmax statistics. Second, each layer merges its current partial contribution through online softmax. The causal convolutional expansion and the subsequent depth attention are fused into a single kernel, avoiding intermediate writes of the expanded source streams. Only the final multi-stream retrieved states are materialized for stream fusion. # Experiment The experiments pre-train DeepSeekMoE-style Transformers at 18B and 28B scales, comparing MSAR against mHC, AttnRes, and a vanilla residual baseline, while 10B ablations test key design choices. MSAR consistently outperforms all baselines across general, code/math, and Chinese benchmarks at both main scales, and scaling-law analysis shows a better loss-compute trade-off. Ablations indicate that MSAR's advantage comes from its specific residual design, with contextual source expansion and adaptive fusion both contributing, and that two to four streams with around eight blocks capture most of the benefit. Across the evaluated 18B and 28B MoE settings, MSAR achieves the best downstream score on every benchmark, surpassing Vanilla, mHC, and AttnRes. The largest gains are over the Vanilla residual baseline, while meaningful improvements over mHC and AttnRes also persist at both scales. The downstream advantage remains consistent as model size increases. MSAR records the top performance on all evaluated benchmarks at both 18B and 28B scales. Relative to Vanilla, MSAR improves the average downstream score by about 8 points at 18B and nearly 8 points at 28B. MSAR extends gains over AttnRes on representative tasks such as MMLU, ARC-C, and BBH. The margin over AttnRes is larger in the 18B setting than in the 28B setting, but the overall trend of outperformance is consistent. 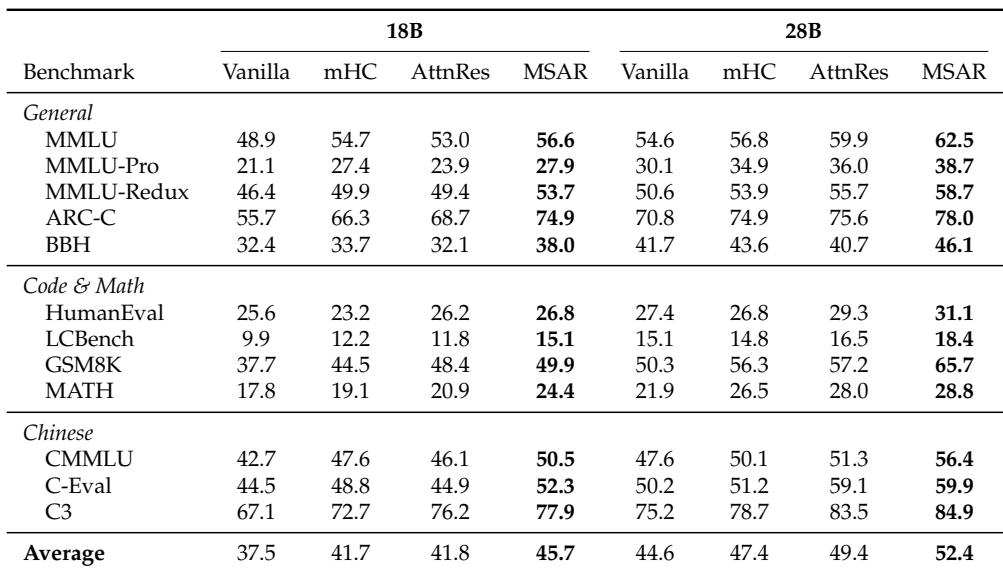 Ablations on a 10B MoE model show that MSAR reaches the lowest Pile loss among the tested residual architectures, improving over vanilla, mHC, AttnRes, and a direct AttnRes plus mHC hybrid. Its advantage is not simply from combining prior methods, and both contextual source expansion and adaptive fusion contribute, with source expansion having a larger effect. Two streams capture most of the gain, while finer depth partitioning beyond about eight blocks gives diminishing returns. MSAR achieves the lowest loss among all compared variants, outperforming both standalone and hybrid baselines. Removing convolutional source expansion degrades loss more than replacing adaptive fusion with mean aggregation. Four streams strike a practical default, since two streams already capture most of the improvement and eight add little. 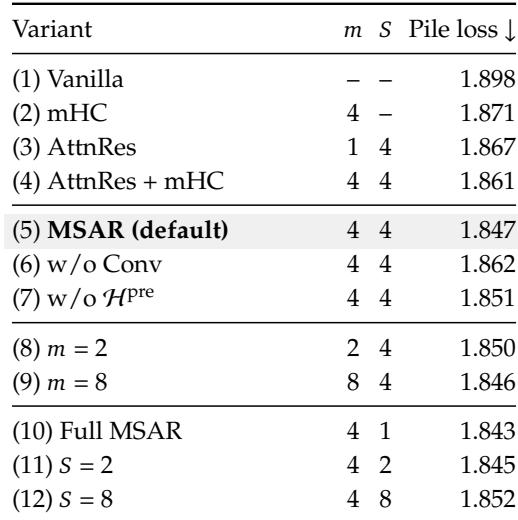 The experiments evaluate MSAR against Vanilla, mHC, and AttnRes residual architectures in 18B and 28B MoE settings on downstream benchmarks, and further ablate the design using a 10B MoE model on Pile loss. MSAR achieves the best downstream performance across all benchmarks at both scales, with consistent gains over baselines and a larger margin over AttnRes at 18B. Ablations show that MSAR attains the lowest Pile loss among standalone and hybrid baselines, and that its benefits are not merely a combination of prior methods: contextual source expansion contributes more than adaptive fusion, two streams capture most of the gain, and deeper partitioning beyond about eight blocks yields diminishing returns.