Command Palette
Search for a command to run...
S-Space : explorer l’espace de travail spatial dans les modèles de langage multimodaux
S-Space : explorer l’espace de travail spatial dans les modèles de langage multimodaux
Résumé
Les modèles de langage multimodaux (MLLM) présentent des capacités prometteuses de raisonnement spatial, mais les mécanismes internes qui les sous-tendent restent mal compris. Nous mettons au jour S-Space, un sous-espace de représentation linéaire dans lequel les représentations des jetons d’objets encodent des coordonnées continues selon des axes horizontal, vertical et de distance. Bien que nous identifiions ces axes en différenciant les scores des réponses spatiales par rapport aux activations des jetons d’objets, S-Space est intrinsèque plutôt qu’induit par des données ou des invites particulières, et reste lisible pour des questions non spatiales. Nous montrons que S-Space fonctionne comme un espace de travail spatial interne des MLLM. La perception y encode les localisations des objets, formant des représentations spatiales qui peuvent être directement lues pour soutenir des jugements spatiaux précis. Le raisonnement interne le transforme lors des changements de point de vue. Les réponses verbales y accèdent de manière sélective, comme en témoignent des interventions causales qui modifient les jugements spatiaux tout en préservant largement les réponses non spatiales. Des études de cas montrent en outre que S-Space attribue des localisations à des entités non vues et à l’observateur, et relie des directions physiques à des significations linguistiques abstraites, ce qui suggère à la fois les capacités et les limites de l’entraînement linguistique à grande échelle. Enfin, nous utilisons S-Space comme outil de diagnostic des défaillances du raisonnement spatial. Le décodage des mots de direction révèle un couplage systématique entre les cadres de référence cardinaux et ceux relatifs à l’image. Plus important encore, une décomposition perception-calcul met en évidence un goulot d’étranglement clé : les MLLM peuvent former des représentations spatiales performantes, mais restent insuffisants dans les transformations spatiales nécessaires pour raisonner de manière fiable face aux changements de point de vue.
One-sentence Summary
Researchers from MirroS, Tsinghua University, and Peking University uncover S-Space, an intrinsic linear representation subspace in multimodal language models where object-token activations encode continuous horizontal, vertical, and distance coordinates, and they demonstrate through activation gradients that this subspace serves as an internal spatial workspace and diagnostic tool, revealing that the models can form capable spatial representations but struggle with viewpoint transformations.
Key Contributions
- The paper identifies and characterizes S-Space, a three-dimensional linear subspace of intermediate multimodal language model representations that acts as an internal spatial workspace, explaining how spatial information is encoded, updated, and causally used.
- A gradient-based readout method is introduced to recover fixed left-right, above-below, and close-far axes, enabling accurate continuous coordinate readouts that generalize across datasets, tasks, and prompts and remain readable under non-spatial questions.
- S-Space is established as a diagnostic tool for spatial reasoning failures: causal interventions alter spatial judgments while largely preserving non-spatial responses, and perception-computation decomposition reveals that models can form capable spatial representations but struggle with the spatial transformations required for reliable viewpoint reasoning.
Introduction
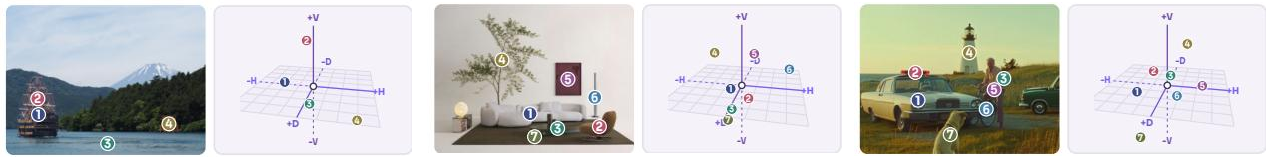
Multimodal large language models are increasingly used for spatial intelligence tasks such as reconstruction, planning, navigation, and manipulation, but robust spatial reasoning remains a major weakness. End-to-end accuracy alone offers little insight into where these failures arise, and prior work on spatial encodings and representational biases has not provided a unified explanation of how spatial information is internally encoded, transformed, and used. The authors uncover S-Space, a three-dimensional linear subspace of intermediate representations that functions as an internal spatial workspace, with fixed axes for left-right, above-below, and close-far directions. They show that this subspace supports generalizable coordinate readouts, causally shapes spatial judgments, and can serve as a diagnostic tool by separating spatial perception from downstream reasoning failures.
Method
S-Space: Formulation, Identification, and Readout
The authors introduce S-Space, a three-dimensional linear subspace of intermediate representations in multimodal large language models (MLLMs) in which object locations are linearly encoded and can be directly read out. The approach has three stages: formulating the subspace, identifying its axes, and reading out spatial coordinates through projection.
S-Space Formulation
Large language models are widely hypothesized to represent concepts linearly in their internal representations. The authors extend this idea to spatial reasoning by hypothesizing that an object’s spatial coordinates, defined in a viewer-centered or egocentric reference frame, are linearly encoded in the hidden representation of its object-name token.
For a given model and layer ℓ, S-Space is defined as a three-dimensional linear subspace of hidden representations
hℓ,t∈Rdmodel.S-Space is specific to the model and layer, but shared across all token positions t within that layer. The authors search for S-Space in the model’s middle layers because early layers remain relatively anchored to input representations, while later layers become increasingly aligned with next-token prediction for verbal response generation. For simplicity, the layer index is omitted in subsequent notation.
Identifying S-Space
The authors identify three S-Space directions corresponding to the horizontal, vertical, and distance axes by differentiating the model’s responses to relative spatial questions with respect to object-token activations.
Each relative spatial question example consists of an image and a prompt comparing a query object with a reference object along one axis g∈{x,y,z}, for example, “Is the apple to the left or right of the cup?” Let q and r denote the respective token positions of the query and reference object names. The answer contrast for each axis is defined as the corresponding logit difference:
sp,x=logit(right)−logit(left), sp,y=logit(above)−logit(below), sp,z=logit(close)−logit(far).The gradient ∇htsp,g indicates the direction along which perturbing the object representation would most increase the corresponding answer contrast. The authors then form a role-antisymmetric gradient difference and average it across prompt templates, original and swapped object orders, and examples:
ap,g=2∇hqsp,g−∇hrsp,g,vg=unit(Ep[ap,g]).The resulting unit vectors define the three S-Space directions:
S=span{vx,vy,vz}.The role-antisymmetric difference is motivated by the fact that relative spatial judgments treat the query and reference oppositely. A change that makes the query more to the right should favor the answer “right,” while the same change applied to the reference should favor “left.” Subtracting the reference gradient from the query gradient therefore reinforces oppositely acting spatial signals. Averaging across prompt templates, object orders, and examples further suppresses effects from object identity, prompt phrasing, token roles, and scene context that are not consistently associated with the queried spatial relation.
Reading Out S-Space
Once the three axes are identified, reading out S-Space requires only a forward pass. The readout is not restricted to the spatial question-answering prompts used for identification; the same fixed directions can be applied to object-token representations elicited by other prompts and tasks.
The authors stack the three direction vectors into a matrix V and project each object token t to obtain its coordinate in S-Space:
V=[vx,vy,vz]∈Rdmodel×3,ct=V⊤ht∈R3.For relative spatial judgments, the query and reference coordinates are compared along the queried axis:
mg=vg⊤(hq−hr)=cq,g−cr,g.The sign of the margin mg directly selects the predicted endpoint. A positive value indicates right, above, or close, while a negative value indicates left, below, or far.
Experiment
Using relative spatial questions constructed from COCO and readouts evaluated on CV-Bench, EmbSpatial, and Spatial-Tunnel, the experiments establish S-Space as an accurate, persistent internal spatial workspace in multimodal language models; editing its coordinates causally alters spatial judgments while largely preserving non-spatial answers. Case studies suggest that S-Space emerges from spatial language prediction and can reflect relations implied by visual evidence, language, and abstract concepts. Further diagnosis with SpinBench and MMSI-Bench shows that spatial reasoning failures often stem from imperfect viewpoint transformations and coupling between cardinal and image-relative directions rather than from missing perceptual information.
Direct answer generation on SpinBench perspective-taking remains limited across all evaluated models, and providing the correct source-view relation gives only selective improvement. Chain-of-thought reasoning improves accuracy but still leaves substantial errors, especially for smaller models. Reading spatial coordinates from S-Space followed by an explicit rotation yields consistently large gains and near-perfect accuracy when the source-view relation is provided. Across models and premise settings, the S-Space plus rotation pipeline outperforms direct answering and chain-of-thought reasoning by large margins. With the correct source-view relation supplied, the S-Space pipeline reaches near-perfect accuracy, while direct and reasoning modes still leave notable errors. Larger models benefit more from chain-of-thought reasoning, but even the strongest reasoning result falls short of the explicit S-Space transformation.
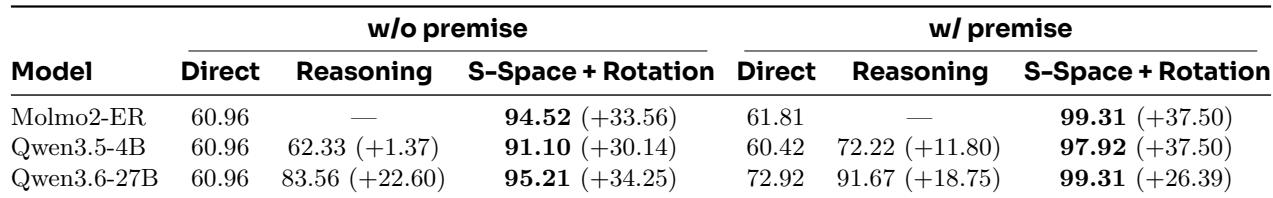
The evaluation on SpinBench perspective-taking compares direct answer generation, chain-of-thought reasoning, and an S-Space pipeline that reads spatial coordinates and applies an explicit rotation. Direct answering remains limited across all models and improves only selectively when the correct source-view relation is provided, while chain-of-thought reasoning reduces errors but still leaves substantial gaps, especially for smaller models. The S-Space plus rotation approach consistently yields large gains and near-perfect accuracy when the source-view relation is available, outperforming the other modes by wide margins across models and premise settings. Even the strongest chain-of-thought results from larger models fall short of the explicit S-Space transformation.