Command Palette
Search for a command to run...
Mise à l’échelle des données agentiques pour l’intelligence terminale à long horizon
Mise à l’échelle des données agentiques pour l’intelligence terminale à long horizon
Shun Zou Ziyu Ma Yi Zou Yong Wang Lin Chen Zehui Chen Guanhua Chen Xiangxiang Chu Feng Zhao
Résumé
Les agents terminaux dépassent désormais les opérations locales pour accomplir des tâches professionnelles réelles. Des trajectoires courtes peuvent illustrer des commandes et des appels d’outils, mais elles ne montrent pas pleinement comment les agents accumulent des preuves par l’exploration, les utilisent pour éclairer leurs jugements, ajustent continuellement leurs stratégies en fonction des retours et transforment des résultats intermédiaires en livrables finaux. Des trajectoires longues de haute qualité capturent ces schémas comportementaux agentiques et leurs connexions au sein d’un même processus de résolution de problème, offrant une expérience plus riche pour un travail autonome soutenu. Cependant, la synthèse d’environnements peut accomplir ou simplifier à l’avance le travail clé sous-jacent à ces schémas et supprimer ainsi le besoin d’exploration, d’implémentation et de vérification que l’agent était censé effectuer. Pour y remédier, nous présentons TerminalHorizon, un moteur de synthèse de données entièrement automatisé pour les agents terminaux à long horizon. Partant de travaux professionnels réels, il utilise une exécution indépendante pour identifier le travail clé omis lors de la construction, puis s’appuie sur les preuves obtenues pour guider la reconstruction de l’environnement. Afin d’étendre ces schémas à travers les étapes, il élargit progressivement les tâches sous le même objectif, en introduisant de nouvelles exigences qui s’appuient sur les résultats antérieurs et appellent à une exploration et à une amélioration supplémentaires. Grâce à ce moteur, nous construisons 1,5 K environnements de tâches et effectuons un ajustement supervisé de Qwen3.5-27B sur le jeu de données résultant pour obtenir TerminalHorizon-27B. Nous obtenons des gains de performance substantiels sur les 12 référentiels couvrant des tâches d’agents de codage, des tâches agentiques dans des cadres de production réels et le raisonnement général. De multiples études de cas RSI, chacune avec un budget de recherche de 12 heures, démontrent en outre la capacité du modèle à continuer d’expérimenter au-delà d’une solution initiale, à améliorer ses méthodes en fonction des retours et à conserver des améliorations efficaces dans ses livrables finaux.
One-sentence Summary
Researchers from the University of Science and Technology of China, AMAP, Alibaba Group, and Southern University of Science and Technology introduce TerminalHorizon, a fully automated data synthesis engine for long-horizon terminal agents that uses independent execution to identify omitted key work, guides environment reconstruction with the resulting evidence, and progressively expands tasks under the same goal; fine-tuning Qwen3.5-27B on the resulting 1.5K task environments yields TerminalHorizon-27B, which achieves substantial performance gains across all 12 benchmarks spanning coding-agent tasks, real-world production agentic tasks, and general reasoning, and demonstrates iterative improvement in multiple 12-hour RSI case studies.
Key Contributions
- The paper introduces a perspective on high-quality long-horizon terminal-agent data that centers on agentic behavioral patterns and their cross-stage connections, emphasizing that environments must preserve substantive exploration, implementation, and verification work.
- A fully automated data synthesis engine, TerminalHorizon, combines challenge-guided environment reconstruction with progressive task expansion to build TerminalHorizon-3K, which contains 1,535 task environments and 2,852 training trajectories.
- Supervised fine-tuning of Qwen3.5-27B on these trajectories yields TerminalHorizon-27B, which improves performance on all 12 benchmarks across coding, real-world productivity, and general reasoning, while multiple 12-hour RSI case studies show continued experimentation, feedback-driven method refinement, and retention of improvements in final deliverables.
Introduction
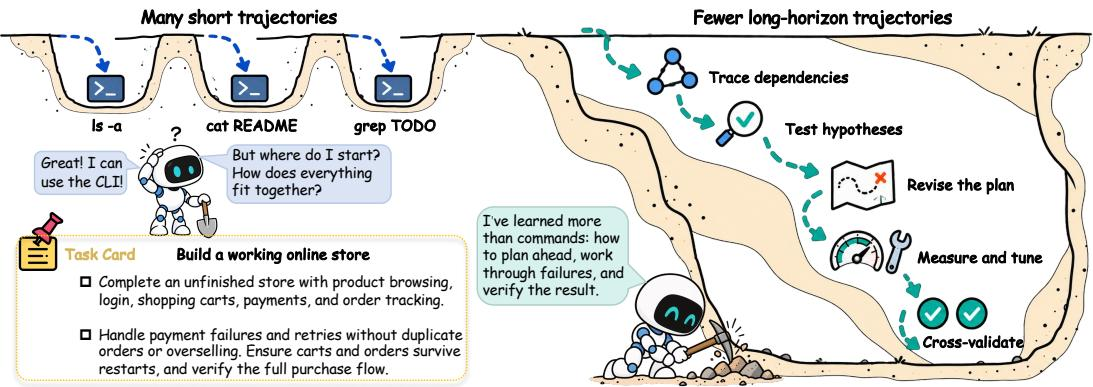
LLM agents are moving beyond short dialogue interactions toward autonomous, long-horizon work in terminal environments that combine code, data, tools, and execution feedback. High-quality terminal training data remains scarce, and existing environment synthesis methods tend to produce relatively short trajectories, limiting exposure to sustained problem-solving behaviors such as iterative planning, dependent execution, and revision after verification failures. The authors identify two further challenges: complex tasks may accidentally simplify or skip work that agents should perform, and adding difficulty does not reliably extend useful agentic behavioral patterns across stages. To address this, they introduce TerminalHorizon, a fully automated synthesis engine with challenge-guided long-horizon construction and progressive horizon expansion. This engine creates task environments where exploration, implementation, and verification remain connected across long trajectories. The authors build TerminalHorizon-3K, containing 1,535 task environments and 2,852 training trajectories averaging 52.8 interaction turns, and show that supervised fine-tuning on this data improves performance across coding, real-world productivity, and general reasoning benchmarks.
Dataset
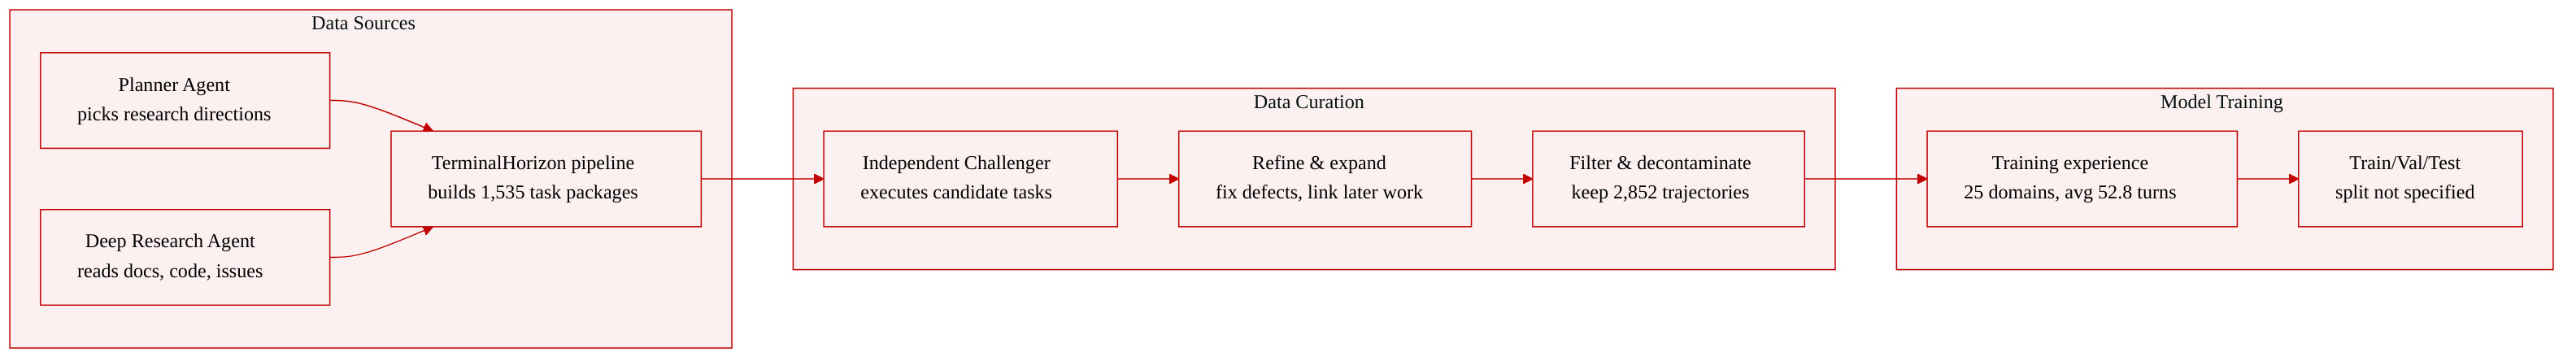
Dataset composition and sources
- The authors build TerminalHorizon-3K through the TerminalHorizon automated pipeline, which synthesizes terminal-task packages from research briefs.
- The Planner Agent selects research directions, while the Deep Research Agent investigates documentation, code repositories, issue reports, and professional materials to create task seeds.
- Each task package includes a public instruction, environment, controlled initial state, reference solution, verifier, and execution configuration. Scoring requirements must be supported by public or discoverable evidence, even when private tests are used.
- The data covers 25 professional domains, including chips, physics, and astronomy, unified into a terminal interaction format.
Generation, expansion, and filtering
- The authors generate 1,535 task environment packages and collect two trajectories per task using DeepSeek-V4-Pro-0813 as the teacher model and Terminus2 as the execution harness.
- An Independent Challenger executes candidate tasks, and tasks are then refined based on runtime defects, information leakage, scoring inconsistencies, and whether the intended work is preserved.
- Accepted tasks can be expanded through progressive horizon expansion using broader roles, deeper mechanisms, richer evidence, and method upgrades. Interaction dependencies link later work to earlier evidence, artifacts, states, or instance-specific variation.
- After collection, the authors apply three filtering criteria from Appendix F and retain 2,852 trajectories to form TerminalHorizon-3K. Benchmark decontamination is performed before training.
Scale and statistics
- The final dataset covers 25 professional domains.
- Trajectories have a mean interaction length of 52.8 turns and a 90th percentile of 98 turns, with a median continuous action chain of 25 turns.
- The authors identify 27 behavioral patterns grouped into five categories: information exploration and judgment, diagnosis and error correction, construction and work progress, verification and assurance, and strategy and execution coordination. Trajectories contain an average of 8.6 core patterns.
How the paper uses the data
- The authors use TerminalHorizon-3K as training experience for the model.
- The data is intended to teach not only terminal command execution but also how to organize sustained goal-directed work, observe feedback, revise strategies, and deliver final results.
- The selected text does not specify a train/validation split or mixture ratio for TerminalHorizon-3K.
Method
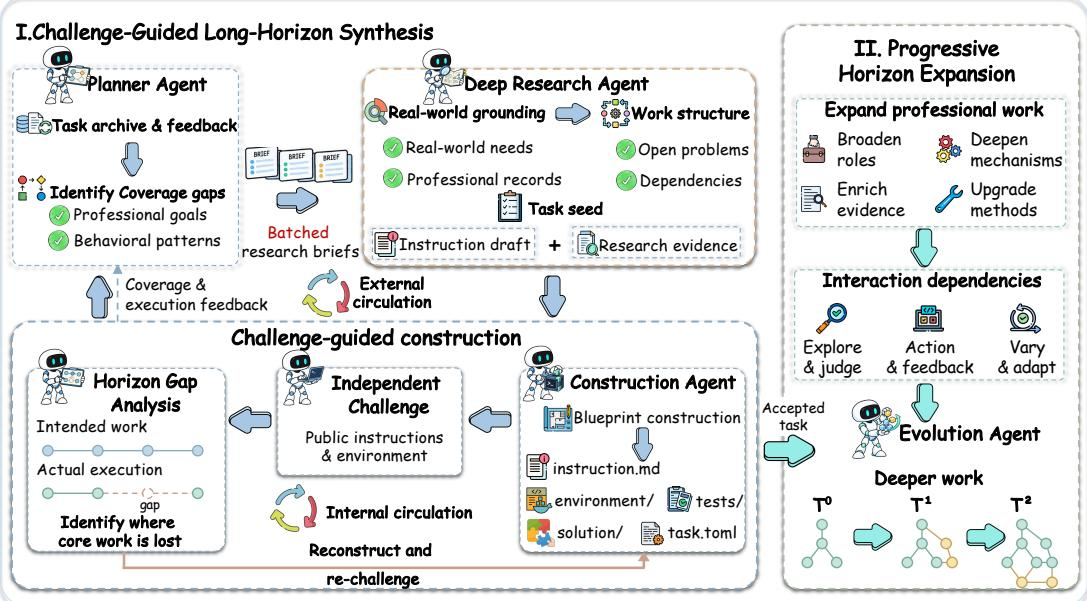
TerminalHorizon builds executable environments from real-world professional problems to elicit agentic behavioral patterns. The method has two coupled stages. The first stage performs challenge-guided long-horizon synthesis, in which independent execution reveals work that construction has simplified, removed, or already completed, and that evidence then guides reconstruction. The second stage performs progressive horizon expansion, extending accepted tasks under the same goal so that added work depends on earlier results and feedback.
As shown in the framework diagram below:
Task Formulation and Design Objective
Each executable terminal task package is defined as
T=(I,E,S,V,M),P(T)=(I,E).The public instruction I specifies the goal and constraints, while the executable environment E provides the initial state, tools, and execution mechanisms. The reference solution S, private verifier V, and execution configuration M support task construction and evaluation. During execution, the agent receives only the public task package P(T) and gathers information through interaction with the environment.
The authors aim to preserve work that connects exploration, diagnosis, construction, verification, and strategic coordination. These processes are described through 27 agentic behavioral patterns across five families. Thus, environment design should retain evidence to explore, leave analysis and implementation to be completed, and provide feedback that helps agents revise earlier judgments.
Challenge-Guided Long-Horizon Synthesis
The synthesis stage uses an inner loop and an outer loop. The inner loop uses independent execution to guide task reconstruction. The outer loop uses accepted tasks and review evidence to plan subsequent research batches.
Autonomous Batch Planning
Each batch begins by identifying professional work that would broaden coverage of agentic behavioral patterns. For batch b, let Db be the accepted task set, Fb the accumulated records, and nb the number of available research slots. The Planner Agent produces research briefs:
Qb=Plan(Db,Fb;nb),Qb={qb,i}i=1nb.Each brief qb,i specifies a scope of work, requirements not yet covered by existing tasks, and real-world sources to investigate.
Evidence-Grounded Deep Research
Following a research brief, the Deep Research Agent investigates documentation, code repositories, issue reports, and professional materials. The goal is to establish real-world needs, technical constraints, and evidence required to assess completion. This research identifies what the agent must discover, which problems require further analysis or implementation, and how one result supports subsequent work. The findings form a task seed zb,i, which contains a draft public instruction and supporting evidence.
Joint Environment Construction
From the task seed, the Construction Agent synthesizes a concrete instance with a controlled initial state and verification conditions. It specifies available materials and tools, the work left to the agent, and the completion criteria. The Construction Agent then jointly builds the instruction, environment, reference solution, verifier, and execution configuration, producing a candidate task package T.
Evaluation must follow the public task requirements:
Csem(V)⊆Sem(I,Opub(E)).Here, the left-hand side denotes the completion requirements checked by the verifier, and the right-hand side denotes the requirements supported by the public instruction and discoverable evidence from the environment. Test data may remain private, but scoring cannot introduce requirements that the agent cannot discover. The reference solution provides one feasible approach, while the verifier accepts other implementations that satisfy the public requirements.
Independent Challenge
An executable package does not by itself establish that the intended work remains necessary during task solving. Therefore, an Independent Challenger, uninvolved in construction, attempts the candidate task Tr. Its policy πB accesses only the public task package P(Tr), without research records, the reference solution, or private tests.
At each step, the policy selects an action given the public instruction and history ht=(o0,a0,…,ot):
at∼πB(⋅∣I,ht),(st+1,ot+1)∼PE(⋅∣st,at).The resulting trajectory
τr∼Rollout(πB;P(Tr))records the full interaction history. The verifier evaluates the final state and artifacts to compute ρr=Vr(sHr). A synthesis review then produces a diagnosis:
dr=Asyn(Tr,τr,ρr).The diagnosis records runtime defects, information leakage, scoring inconsistencies, and whether the intended work was actually preserved.
Horizon Gap Analysis and Reconstruction
Horizon Gap Analysis compares the work specified in the task seed with the challenger trajectory. It traces omitted work to initial materials, object relationships, or tool behavior. For example, if the environment already provides a core function that the task asks the agent to implement, the remaining work may reduce to changing a single constant. Reconstruction restores the need to implement and debug the function while retaining the public specifications needed to do so.
Using the seed z=zb,i, the trajectory, and the diagnosis, the Construction Agent revises the task:
Tr+1=Refine(Tr;z,τr,dr).This refinement preserves the goal while revising the initial state, object relationships, implementation requirements, or tool feedback. The instruction, reference solution, and verifier are updated accordingly. The revised task returns to independent execution to check whether the restored requirements enter the actual solving process.
Tasks that pass review and runtime checks form the accepted set Ab. Research, execution, review, and reconstruction records provide new feedback ΔFb:
Db+1=Db∪Ab,Fb+1=Fb∪ΔFb.The Planner uses the updated collection and records in the next batch to identify repeated work and decide which behavioral patterns to target next.
Progressive Horizon Expansion
A solvable task is not the endpoint of environment construction. The authors extend accepted tasks with new requirements under the same goal, linking added work to earlier judgments, actions, and results.
Progressive Content Expansion
The Evolution Agent examines an accepted parent task T(g) and forms an expansion proposal δ(g). It checks whether the parent solution can directly satisfy the new requirements, identifying the further analysis, implementation, or verification needed. Content expansion proceeds in four directions: broader roles, deeper mechanisms, richer evidence, and method upgrades. Broader roles use existing artifacts or states to support related responsibilities. Deeper mechanisms make previously simplified relationships, dependencies, or uncertainties part of the work. Richer evidence adds records, observations, and professional materials. Method upgrades require substantial extension or redesign of the original approach.
Implementing Interaction Dependencies
The Evolution Agent selects from three interaction designs to connect added requirements to earlier evidence, artifacts, and states. To support exploration and judgment, later decisions depend on evidence gathered through public queries, probes, and observations. In action and feedback, observable tool or system effects link earlier operations to subsequent diagnosis, correction, and verification. With instance variation and adaptation, objects or states vary across runs under a fixed public specification, requiring the agent to inspect the current instance, adapt its actions, and verify the results.
These designs are selected to serve the extension rather than to impose a fixed sequence. The expansion produces a new candidate:
T(g+1)=Expand(T(g);δ(g)).The candidate public specification combines the original and added requirements. The environment, reference solution, and verifier are updated accordingly, and new scoring conditions continue to follow the public completion contract. An accepted candidate becomes the parent task for the next expansion.
Experiment
The study evaluates TerminalHorizon-27B, an SFT model trained on long-horizon terminal trajectories, across 12 benchmarks covering terminal task solving, real-world productivity, and general reasoning, with additional analyses on teacher behavior, model size, data scaling, and a long-horizon autonomous research case. The model outperforms its base model on all benchmarks, transfers gains to agentic productivity tasks, and preserves general reasoning while using far fewer trajectories than an earlier trajectory-trained model. Ablations show that longer teacher feedback chains improve task completion, gains generalize across model sizes, and scaling has not plateaued. In a 12-hour autonomous research task, the model continues to diagnose and revise its approach instead of stopping early, leading to a substantially higher final evaluation score.
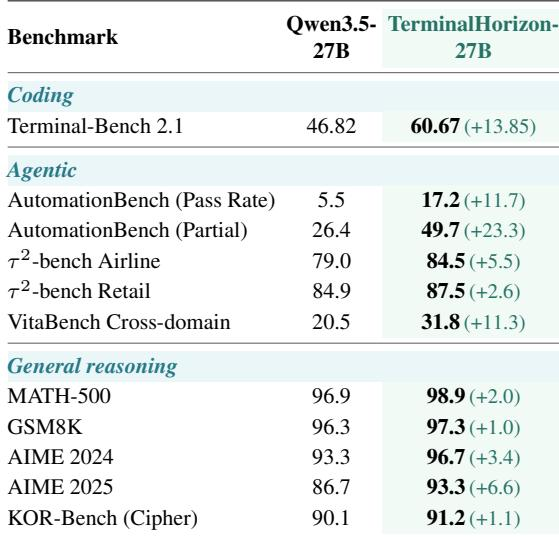
TerminalHorizon-27B outperforms its Qwen3.5-27B base model across all twelve benchmarks spanning terminal tasks, real-world agentic tasks, and general reasoning. Gains are especially strong on Terminal-Bench variants, with double-digit percentage-point improvements on two versions, and the model also surpasses a comparable model while using far fewer training trajectories. Benefits transfer to real-world productivity tasks and general reasoning remains preserved. TerminalHorizon-27B improves over its base model on Terminal-Bench 1.0, 2.0, and 2.1, with larger gains on the later benchmarks. It outperforms a comparable Terminal-Universe model by 3.0 percentage points while using less than one-tenth as many training trajectories. Real-world agentic benchmarks also improve, including AutomationBench pass and partial scores, VitaBench, and tau2-bench airline and retail tasks. General reasoning remains preserved or improved, with MATH-500 and AIME results reaching strong scores.
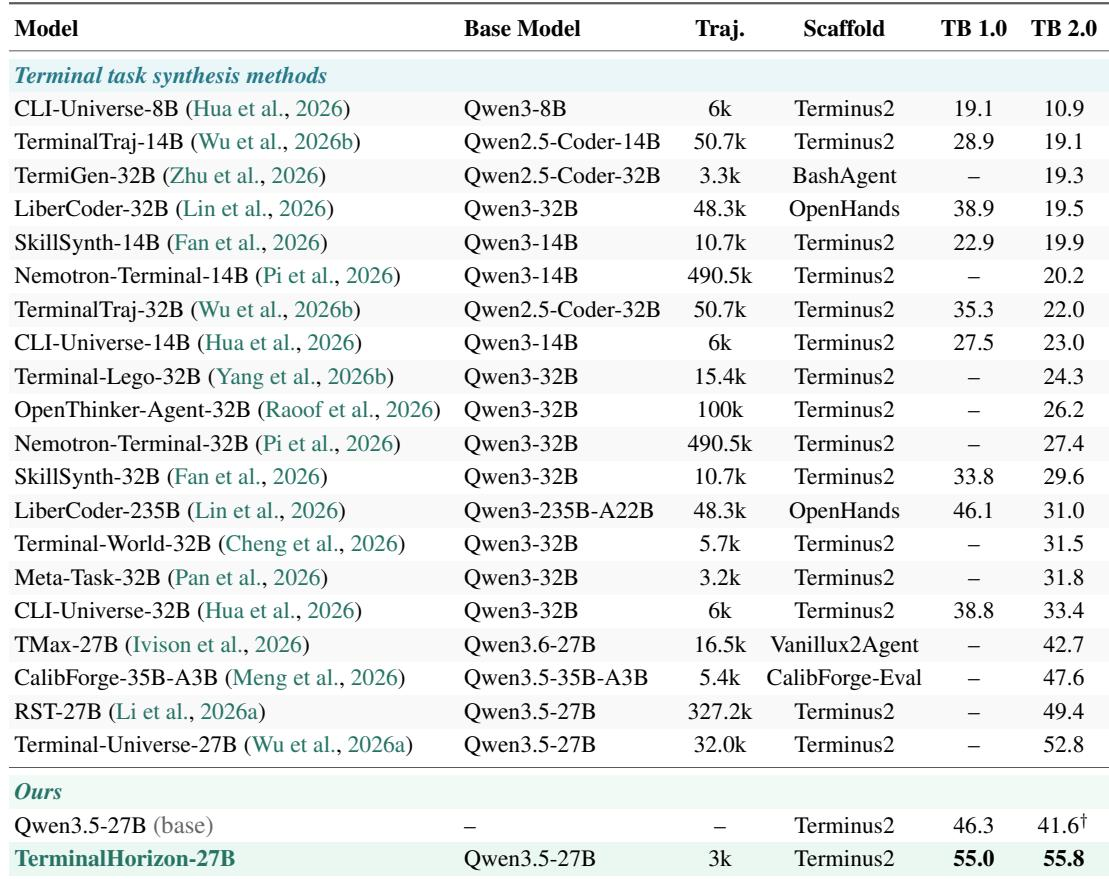
TerminalHorizon-27B consistently outperforms its Qwen3.5-27B base model across coding, agentic, and general reasoning benchmarks. Gains are especially strong in coding and real-world automation tasks, while general reasoning is preserved and further improved. The model also shows data efficiency by surpassing a prior model trained with far more trajectories. TerminalHorizon-27B improves over the base model on all evaluated benchmarks, with a double-digit coding gain on Terminal-Bench 2.1. Agentic transfer is broad: AutomationBench pass rate and partial score increase substantially, and airline and retail task scores also improve. General reasoning remains strong, with near-saturated scores on MATH-500 and AIME 2024 and 2025.
On a sampled set of tasks, both teacher models generate long trajectories, indicating long-horizon problem-solving experience. DeepSeek-V4-Pro sustains longer interactions and has a lower exact action repetition rate than GLM-5.2, and its more sustained interactions are associated with a higher task completion rate. DeepSeek-V4-Pro produces longer feedback chains and repeats exact actions less often than GLM-5.2. The more sustained interaction pattern is associated with a higher task completion rate, supporting DeepSeek-V4-Pro as the teacher for long-horizon trajectory collection.
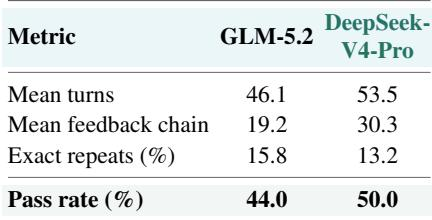
The evaluation compares TerminalHorizon-27B with its Qwen3.5-27B base model and prior terminal-focused models across Terminal-Bench variants, real-world agentic benchmarks such as AutomationBench, VitaBench, and tau2-bench, and general reasoning tasks. Results show consistent gains across all benchmarks, with the largest improvements in long-horizon terminal and automation tasks, while reasoning ability remains strong. The model also demonstrates data efficiency by outperforming a comparable model using far fewer training trajectories. A separate trajectory analysis validates the choice of DeepSeek-V4-Pro as teacher, since it sustains longer interactions, repeats exact actions less often, and achieves higher task completion than GLM-5.2.