Command Palette
Search for a command to run...
VISIONWEAVE : TISSER DES REPRÉSENTATIONS VISUELLES ÉLASTIQUES EN TANT QUE CAPACITÉ NATIVE DES MLLM
VISIONWEAVE : TISSER DES REPRÉSENTATIONS VISUELLES ÉLASTIQUES EN TANT QUE CAPACITÉ NATIVE DES MLLM
Résumé
Les grands modèles de langage multimodaux sont devenus le paradigme dominant de la compréhension visuelle, mais induisent des coûts substantiels en encodant les entrées en jetons de patch denses et de taille fixe. Pourtant, l'information visuelle est inégalement répartie : certaines régions exigent un détail fin, tandis que d'autres se prêtent à des représentations compactes. Le sous-échantillonnage sacrifie ce détail, tandis que les approches existantes d'élagage de jetons et adaptatives restent limitées en matière de granularité adaptée au contenu, de généralisation aux tâches et d'intégration avec les MLLM modernes et les infrastructures d'inférence. Surmonter ces limites exige des modèles de fondation qui apprennent, de bout en bout, où — et à quelle granularité — allouer les représentations visuelles, une capacité native que nous appelons tissage élastique des représentations visuelles. Nous présentons VisionWeave, qui établit cette capacité dans des MLLM de pointe grâce à un entraînement à grande échelle. Elle combine deux composants : un pooler spatial à portes construit des représentations à gros grain aux côtés des représentations fines natives dans un système de coordonnées MRoPE partagé, tandis qu'un routeur de granularité apprend leur allocation adaptée au contenu. Par auto-distillation seule, nous validons cette capacité sur Qwen3.5-4B et la mettons à l'échelle sur Qwen3.8-27B avec plus de 30 000 heures GPU A100. Reposant sur Qwen3.8-27B, Vision-Weave ajuste de façon adaptative les économies de jetons au contenu visuel, économisant en moyenne 43,0 % de jetons tout en conservant 98,9 % des performances natives sur huit jeux de référence, contre seulement 88 % de performances préservées pour les méthodes de référence par élagage de jetons avec un objectif d'économie fixe de 50 %. Des évaluations approfondies confirment des compromis robustes entre efficacité et qualité à travers diverses tâches, résolutions et trames vidéo. Lorsqu'elle est déployée sur le moteur de service SGLang, notre méthode atteint un gain de débit de bout en bout de 2,30× tout en réduisant le TTFT moyen de 54,4 % et le TPOT moyen de 60,6 %. Dans l'ensemble, nous pensons que ces résultats font du tissage élastique des représentations visuelles une capacité prometteuse pour la prochaine génération de modèles de fondation multimodaux, modulant nativement l'effort de calcul en fonction du contenu informationnel. Notre code SGLang et d'autres détails seront disponibles à l'adresse https://github.com/FFY0/VisionWeave.
One-sentence Summary
Researchers at the University of Science and Technology of China, Alibaba Token Hub, and other affiliated institutions introduce VisionWeave, which learns elastic visual representation weaving as a native MLLM capability through a gated spatial pooler and a granularity router trained by self-distillation, achieving 43.0% token savings while retaining 98.9% native performance on Qwen3.8-27B and a 2.30× end-to-end throughput gain on the SGLang serving engine.
Key Contributions
- VisionWeave establishes elastic visual representation weaving as a native MLLM capability by combining a gated spatial pooler for coarse-grained representations with a granularity router for content-adaptive allocation within a shared MRoPE coordinate.
- The method learns adaptive visual token allocation end to end through self-distillation alone, validating on Qwen3.5-4B and scaling to Qwen3.8-27B with over 30K A100 GPU-hours.
- On Qwen3.8-27B, VisionWeave saves 43.0% of visual tokens on average while retaining 98.9% native performance across eight benchmarks, and in SGLang serving it achieves a 2.30× end-to-end throughput gain, with mean TTFT reduced by 54.4% and mean TPOT by 60.6%.
Introduction
Multimodal large language models (MLLMs) are now the dominant approach for visual understanding tasks, but processing high-resolution images and long video sequences generates very long visual token sequences that increase computational and memory costs. Prior work on visual downsampling sacrifices fine-grained detail, while visual token pruning and merging methods often suffer from training-inference mismatch, lose task-specific information, degrade on information-dense or grounding tasks, and are difficult to integrate with modern serving engines such as SGLang and vLLM. Existing content-adaptive methods such as ViCO use tile-level resolution assignment, which is too coarse for interleaved detail-rich and low-information regions and is not aligned with native-resolution MLLM architectures like Qwen and Kimi. The authors introduce VisionWeave, a method that enables MLLMs to natively use elastic visual representations by adaptively weaving fine-grained and learned coarse-grained tokens through a gated spatial pooler and a granularity router. Trained via self-distillation on Qwen3.5-4B and scaled to Qwen3.8-27B, VisionWeave achieves content-adaptive token savings while preserving near-native performance and translates these savings into about 2x serving throughput in SGLang.
Method
The authors realize elastic visual representation weaving through two complementary components: a gated spatial pooler and a granularity router, which together enable native elastic visual processing in multimodal large language models.
The gated spatial pooler constructs learned coarse-grained representations that complement native fine-grained tokens. It maps each 2×2 neighborhood of Vision Transformer (ViT) patch features to a single pooled feature. For each neighborhood, the four patch features are normalized using learnable layer normalization and aggregated into a shared global context. A gating mechanism then computes channel-wise scores from the patch feature and its context, followed by a value network that refines each feature. The final pooled output is the gated sum of these refined features. This design offers a favorable starting point, as zero-initializing the final layers reduces the pooler to mean pooling over normalized patch features.
To determine the granularity for each spatial block, the granularity router probes intermediate ViT features at multiple depths. It employs a learnable query state for each spatial block, initialized from a shared learnable vector. Each query sequentially probes specific depths of the ViT, utilizing a local cross-attention block to attend to the spatial block's own patch features, followed by a global cross-attention block to incorporate information from the entire frame. Both attention mechanisms use residual connections and layer normalization. Finally, a linear head maps the normalized query state to logits, yielding the probability of using the coarse-grained representation. During inference, if this probability exceeds a threshold, the coarse-grained token is used; otherwise, the native fine-grained tokens are retained.
The authors develop this elastic visual weaving capability through a three-stage self-distillation process. In the first stage, coarse-grained self-distillation, the pooler is trained with routing bypassed, using the coarse-grained representation for every block. The native forward pass of the model serves as the teacher, providing output-distribution supervision via a Kullback-Leibler divergence objective.
In the second stage, soft-mixing self-distillation, the granularity router is trained using a differentiable soft-mixing surrogate for hard routing. The authors interpolate feature directions and magnitudes separately to prevent norm differences from biasing the mixture. A per-sample balance loss is added to encourage a target coarse-routing fraction, preventing larger inputs from dominating the estimate.
The third stage performs mixed-granularity self-distillation on the hard-routed mixed-granularity sequences used at inference. The router head includes an offline-calibrated scalar coarse-routing bias, and the student gathers visual tokens using the same selection and positional embedding coordinates as during inference.
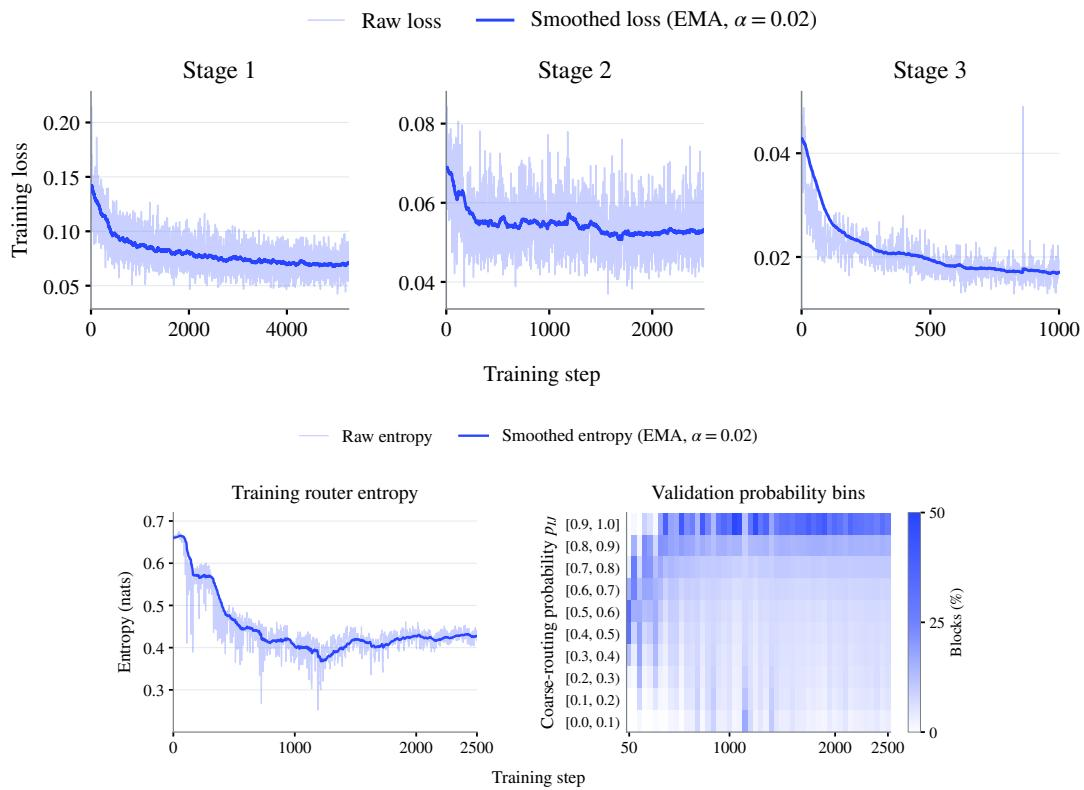
The training dynamics of this three-stage process reveal how granularity decisions develop over time. As shown in the figure below, the training losses steadily decrease across all three stages. During the soft-mixing stage, the mean router entropy falls significantly, indicating increasingly decisive allocation. Furthermore, the validation probability distributions show a clear shift, with the share of blocks having high coarse-routing probability reaching substantial levels, demonstrating the model's ability to learn content-adaptive granularity allocation effectively.
Experiment
The evaluation validates VisionWeave on two open-source Qwen MLLMs across eight benchmarks spanning natural images, documents, GUI grounding, hallucination, and video understanding, comparing against heuristic token merging and pruning baselines and using SGLang for serving tests. VisionWeave maintains near-native quality through content-adaptive token savings and shows stable efficiency-quality tradeoffs across spatial resolutions and video frame budgets, unlike fixed-saving baselines that degrade sharply on grounding and information-dense tasks. Serving experiments demonstrate higher end-to-end throughput and lower latency, while inference-time thresholding allows quality-cost control without retraining. Ablations confirm the gated spatial pooler and learned granularity allocation matter, and visual analysis shows the approach preserves spatial coverage rather than dropping task-critical tokens.
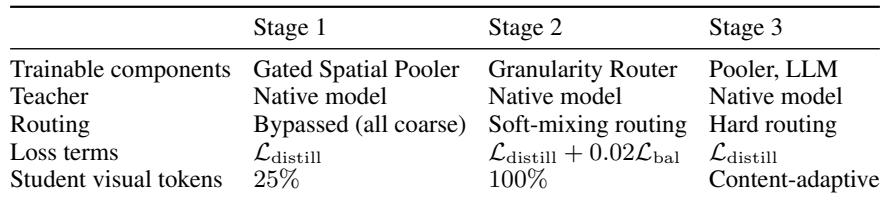
Elastic visual processing is trained in three stages: first a gated spatial pooler learns coarse representations with all routing bypassed, then a granularity router is trained with soft-mixing and a balance loss, and finally the pooler and LLM are trained with hard content-adaptive routing. This curriculum moves student visual tokens from a fixed 25% through full tokens to content-adaptive allocation. Ablations show the learned pooler outperforms a pixel-unshuffle projector at high token savings, and shuffling routing scores reduces performance, indicating that content-dependent granularity allocation is important. The three-stage procedure moves from coarse-only pooling to soft-mixed routing and finally hard content-adaptive routing with trainable pooler, router, and LLM components. Ablations show the gated spatial pooler outperforms a pixel-unshuffle projector at high token savings, and shuffling learned routing scores reduces performance, indicating content-dependent allocation matters.
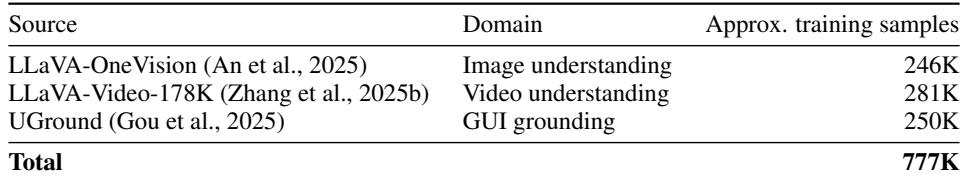
The training mixture for Qwen3.8-27B contains about 0.78 million samples spanning image understanding, video understanding, and GUI grounding. The three domain contributions are nearly balanced, with video understanding as the largest source and image understanding as the smallest. All three training stages use this same mixture before sequence packing. Image understanding, video understanding, and GUI grounding each account for roughly one third of the total training samples. Video understanding contributes the largest share, while image understanding contributes the smallest. The same data composition is shared across all three training stages.
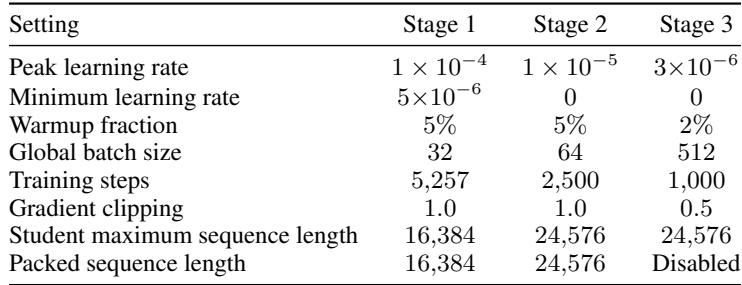
Qwen3.8-27B training moves through three stages with progressively lower peak learning rates, zero minimum learning rates after the first stage, and larger global batch sizes. The first stage uses the most training steps and a shorter student maximum sequence length, while later stages use longer sequences and fewer steps. Later stages use lower peak learning rates and zero minimum learning rates, indicating more conservative optimization. The global batch size increases across stages while training steps decrease, shifting from many small-batch updates to fewer large-batch updates.
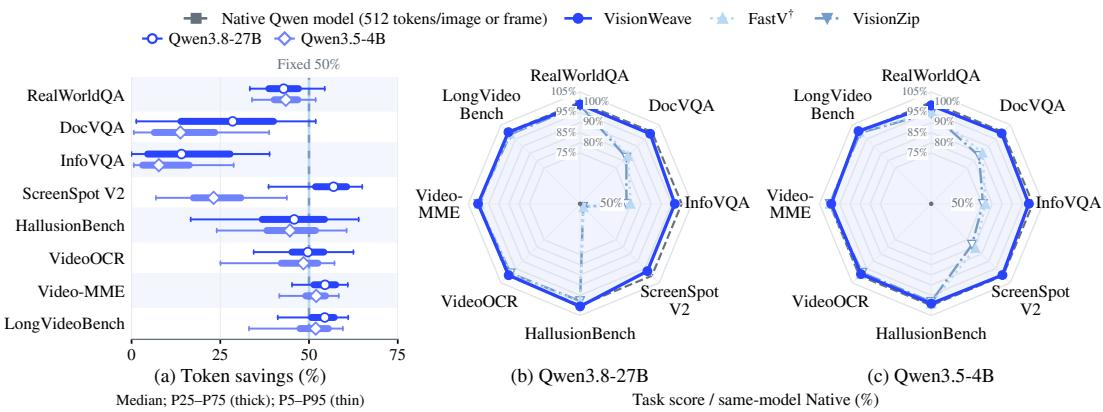
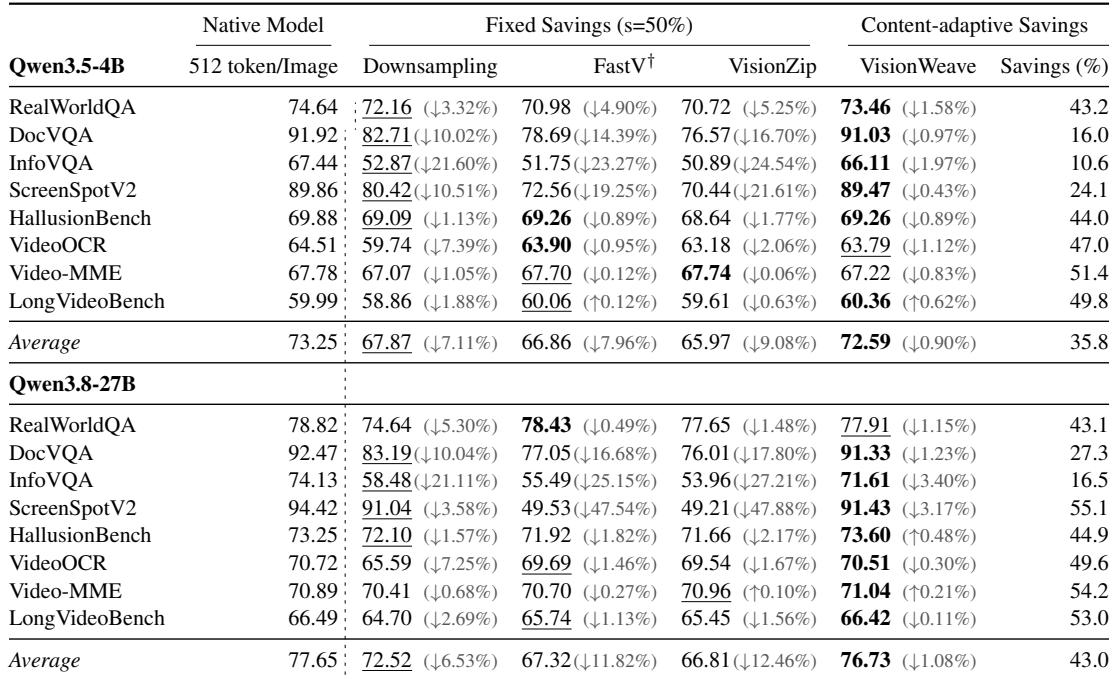
VisionWeave provides content-adaptive token savings while keeping quality close to native models. Document and grounding tasks receive more conservative savings with only small accuracy drops, while video tasks allow much higher savings with minimal loss. Fixed-savings baselines degrade more sharply on information-dense and grounding benchmarks even when matched for dataset-level savings. VisionWeave limits average performance loss to roughly one percent across benchmarks on both model scales. Token savings are content-adaptive, with much higher reduction on video benchmarks and more conservative reduction on document and grounding tasks. FastV and VisionZip show sharp drops on ScreenSpotV2 and DocVQA, while VisionWeave preserves quality by adapting token allocation to input demands.
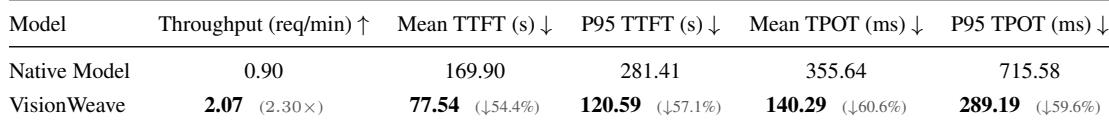
Under the long-video serving workload, VisionWeave more than doubles throughput relative to the native model while reducing latency across mean and tail metrics. The improvements are especially strong for per-token generation time, and tail latency also falls substantially, indicating higher serving capacity and better responsiveness. VisionWeave delivers a 2.30x end-to-end throughput speedup over the native model on the same two-GPU serving setup. P95 time to first token falls by 57.1%, and P95 time per output token falls by 59.6%. Mean TTFT and mean TPOT also drop by over half, with mean TPOT improving by 60.6%.
The experiments evaluate VisionWeave's three-stage training procedure, which progresses from coarse pooling through soft-mixed routing to hard content-adaptive routing, with ablations showing that learned content-dependent token allocation outperforms fixed projectors and shuffled routing baselines. They further document a balanced multimodal training mixture spanning image, video, and GUI grounding, and a progressive optimization schedule with lower learning rates and larger batches in later stages. Benchmark results indicate that content-adaptive token savings preserve quality across document, grounding, and video tasks, while fixed-savings baselines degrade more sharply on information-dense inputs. Serving evaluations also show substantial throughput and latency improvements for long-video workloads.