Command Palette
Search for a command to run...
EVODUET : co-évolution bi-niveau de la recherche sur le web et de la résolution de tâches pour la découverte scientifique
EVODUET : co-évolution bi-niveau de la recherche sur le web et de la résolution de tâches pour la découverte scientifique
Young-Jun Lee Jinheon Baek Soyeong Jeong Minki Kang Seungyeon Jwa Jonghyun Choi Seungho Han Dongyeop Kang
Résumé
La recherche évolutionnaire avec de grands modèles de langue (LLM) peut stagner lorsque les progrès nécessitent des connaissances externes dont le modèle ne dispose pas. Fournir des documents pertinents aide, mais le simple ajout d'un outil de recherche sur le web peut continuer à renvoyer les mêmes pages à mesure que les solutions changent. Nous introduisons EVODUET, une méthode d'optimisation bi-niveau qui fait co-évoluer les solutions et les requêtes de recherche à paramètres de modèle fixes. À chaque itération, une porte de récupération permet au LLM d'évaluer ses lacunes de connaissances et de choisir de récupérer de nouveaux documents, de réutiliser les documents stockés ou de continuer sans eux. Une boucle interne affine les requêtes et classe les documents selon les scores de solution qu'ils sont censés produire ; une boucle externe génère des candidats en parallèle à partir de ces documents et enregistre les résultats évalués pour les recherches ultérieures. Sur 21 tâches d'optimisation avec un candidat par itération, EVODUET fait passer le gain de découverte normalisé d'OpenEvolve de 74,1 % à 78,0 % avec GPT-5.6-Luna et de 61,3 % à 82,3 % avec Gemini-3.8-Flash, tandis que Qwen3.5-9B n'en tire pas profit. Nos meilleures exécutions dépassent les meilleurs scores précédemment rapportés sur huit tâches, notamment Swap Reduction sur Q20 et Rosetta, et les égalent sur trois autres. EVODUET apporte également des améliorations avec d'autres échafaudages (par ex., Top-K, EvoX) sur Sums/Diffs et Denoising, ce qui démontre son applicabilité à différents échafaudages de recherche évolutionnaire.
One-sentence Summary
University of Minnesota et al. propose EVODUET, a bi-level co-evolution method that interleaves solution and search-query evolution under fixed model parameters, using a retrieval gate for knowledge-gap assessment and inner and outer loops for query refinement, document ranking, candidate generation, and outcome recording; EVODUET improves OpenEvolve normalized discovery gain from 74.1% to 78.0% on GPT-5.6-Luna and from 61.3% to 82.3% on Gemini-3.8-Flash.
Key Contributions
- Introduces EVODUET, a bi-level optimization method that co-evolves solutions in an outer loop and web search queries in an inner loop with fixed LLM parameters.
- Across 21 optimization tasks with one candidate per iteration, EVODUET raises OpenEvolve's normalized discovery gain from 74.1% to 78.0% with GPT-5.6-Luna and from 61.3% to 82.3% with Gemini-3.8-Flash; Qwen3.5-9B does not benefit, and the best runs surpass previously reported best scores on eight tasks and match them on three more.
- EVODUET also improves Top-K and EvoX scaffolds on Sums/Diffs and Denoising, and analysis shows that method transfer is the most common use of retrieved documents while predicted document gains still require evaluator validation.
Introduction
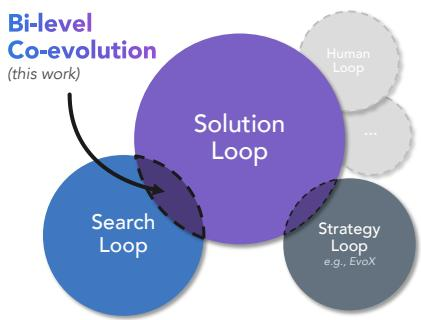
LLM-driven evolutionary search scaffolds are increasingly used for optimization tasks where candidates can be scored but optimal solutions cannot be computed directly, such as the Erdos minimum-overlap problem, GPU kernel design, and single-cell RNA-seq denoising. Existing scaffolds typically operate as a closed solution loop or add strategy loops, drawing only on the run’s evolutionary history and the LLM’s parametric knowledge. As a result, they stall when improvement requires external information that neither source contains. The authors introduce EVODUET, a bi-level method that co-evolves candidate solutions in an outer loop and web search queries in an inner loop, using a knowledge-gap retrieval gate to decide when to search and hypothetical evidence scoring to rank retrieved documents before evaluation. Across 21 optimization tasks, EVODUET improves OpenEvolve and surpasses previously reported best scores on eight tasks.
Method
The authors formulate scientific discovery as a bi-level optimization problem, introducing EVODUET to co-evolve solutions and web search queries. The framework consists of three primary components: an outer loop for solution optimization, an inner loop for query optimization, and a knowledge-gap-based retrieval gating mechanism that connects the two. The ideal bi-level optimization is formulated as:
outer: solution optimizationx⋆=argoptx∈XE(x)s.t.inner: query optimizationqt⋆=argoptq∈QtE(xt+1(q))As shown in the figure below:
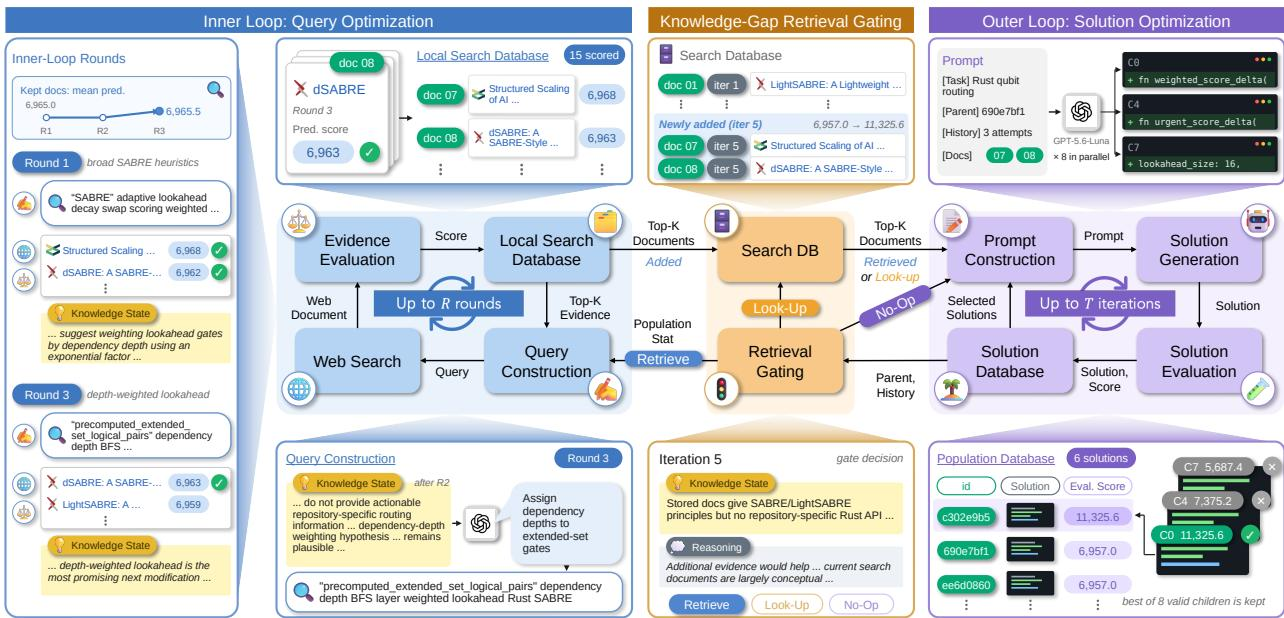
The outer loop follows an evolutionary search scaffold to evolve solutions. At each iteration t, a selection policy ϕ selects a parent solution xt and its evolutionary history Ht from the population De. The LLM Mθ then generates a candidate solution xt+1∼Mθ(I,ct,St), where St is a set of retrieved web documents or empty. To enable diverse exploration, the authors employ gated parallel candidate solution generation, producing Nt candidates in parallel from the same input prompt. The best valid candidate is selected based on the evaluator E and passed to the selection policy.
The knowledge-gap-based retrieval gating mechanism determines whether the model needs external knowledge to improve the current solution. Given the context ct and the search database Ds, the LLM outputs its current knowledge state Kt and a retrieval decision gt:
(Kt,gt)=GATEMθ(ct,Ds),gt∈{NO-OP,LOOK-UP,RETRIEVE}.If the model's internal knowledge suffices, it selects NO-OP. If stored documents provide the missing knowledge, it selects LOOK-UP, reusing existing evidence without a new web search. If neither source is sufficient, it selects RETRIEVE to invoke the inner loop.
When gt=RETRIEVE, the inner loop approximates query optimization over R rounds without generating or evaluating candidate solutions. It first computes a population state descriptor and summarizes it into factual observations At to form the initial context c~t0=(ct,Kt,At). In each round r, the loop performs four operations. First, the LLM constructs J queries targeting remaining knowledge gaps. Second, it executes a web search and combines the returned documents with previously retained ones to form a pool Pr. Third, it performs hypothetical evidence scoring, where the LLM predicts the evaluator score s^t(d) for each unscored document d∈Pr to provide a surrogate signal for the inner objective. Finally, it updates the knowledge state Ktr and retains the top D documents with the highest predicted scores as Str. After R rounds, the final retained documents St=StR are passed back to the outer loop to guide the generation of an improved candidate solution.
Experiment
The experiments evaluate web search for scientific discovery on 31 optimization tasks using OpenEvolve and EVODUET across several LLMs, with normalized discovery gain as the metric. Oracle documents improve average progress, especially with more parallel candidates and for the smaller model, though benefits vary by task and model. EVODUET's bi-level query evolution and knowledge-gap-based retrieval gate sustain broader document discovery and improve results over joint-level search, with the largest gains on partially solved and mathematics tasks, but only for models capable of using retrieved evidence; weaker Qwen3.5-9B declines. Retrieved documents mainly contribute methods and performance targets, and the approach integrates with existing scaffolds while reducing cost on Denoising.
EVODUET matches or slightly improves on previous state-of-the-art metrics across the evaluated tasks, with modest reported run costs. Additional analyses show that a knowledge-gap-based retrieval gate outperforms random and stagnation-based gating, while the bi-level search design surpasses no-web-search, joint-level, and sequential alternatives. The method also improves normalized downstream gain across existing scaffolds and achieves strong cost efficiency on Denoising. The knowledge-gap-based gate yields the highest normalized downstream gain among retrieval gating strategies, with a particularly large improvement on Denoising over the stagnation heuristic. EVODUET outperforms no-web-search, joint-level in-loop search, and sequential search variants across three tasks and improves results across OpenEvolve, Top-K, and EvoX scaffolds. On Denoising, EVODUET reaches slightly above 100% normalized downstream gain while reducing estimated API cost by about 6.9x compared with SimpleTES.
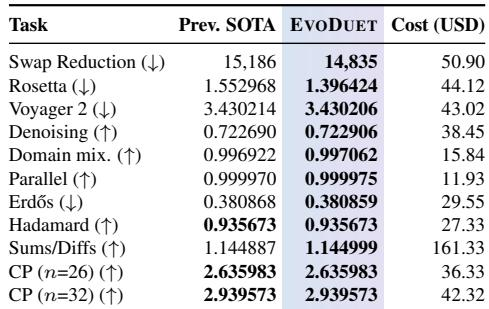
The experiments evaluate EVODUET on multiple downstream tasks and scaffolds, comparing it with prior state-of-the-art methods and ablating its retrieval and search components. EVODUET matches or slightly improves previous state-of-the-art metrics with modest run costs, and its knowledge-gap-based retrieval gate outperforms random and stagnation-based gating, particularly on Denoising. The bi-level search design also surpasses no-web-search, joint-level, and sequential alternatives while improving normalized downstream gain across OpenEvolve, Top-K, and EvoX scaffolds. On Denoising, the method reaches slightly above 100% normalized downstream gain and reduces estimated API cost by about 6.9x compared with SimpleTES.