Command Palette
Search for a command to run...
Évaluation agentique par groupes et redistribution des avantages pour le RL des agents de code
Évaluation agentique par groupes et redistribution des avantages pour le RL des agents de code
Jinhao Dong Liang Zhao Zihao Yue Wenhan Ma Linghao Zhang Lei Li Shicheng Li Yifan Song Bowen Ye Fuli Luo
Résumé
L'apprentissage par renforcement (RL) pour les agents de code utilise souvent des tests exécutables pour fournir des récompenses binaires. Avec ces récompenses, Group Relative Policy Optimization (GRPO) attribue des avantages identiques aux trajectoires qui réussissent les tests au sein de chaque groupe de rollouts, en négligeant les différences de qualité d'implémentation et de respect des exigences de la tâche. La politique se retrouve ainsi privée d'un signal d'apprentissage favorisant les implémentations propres et ciblées par rapport à celles contenant des modifications inutiles ou hors périmètre. Nous introduisons Gagar, un cadre de redistribution du crédit sensible à la qualité pour le RL des agents de code. Reposant sur un échantillonnage dynamique qui conserve les groupes contenant à la fois des trajectoires réussissant et échouant les tests, Gagar place toutes les trajectoires de chaque groupe dans un espace de travail partagé, où un évaluateur agentique entraîné par SFT les inspecte conjointement et classe les candidates ayant réussi les tests. Sur la base de ce classement, nous réduisons le poids des trajectoires les moins bien classées et redimensionnons proportionnellement les avantages de toutes les trajectoires ayant réussi les tests afin de restaurer leur somme d'origine. Cette redistribution à somme préservée conserve les poids relatifs établis par la pondération à la baisse fondée sur la qualité tout en déplaçant le crédit vers les implémentations de meilleure qualité. Nous évaluons Gagar à l'échelle industrielle en utilisant des points de contrôle SFT pré-RL de MiMo-V2.6-Flash (310 milliards de paramètres au total) et de MiMo-V2.6-Pro (1,02 billion de paramètres au total). Des expériences contrôlées portant uniquement sur le code avec Flash montrent une amélioration des performances des agents de code, une croissance réduite de la longueur des trajectoires et un entraînement plus stable. Nous appliquons en outre Gagar dans un cadre de RL multitâche à grande échelle avec Flash et Pro. Nos résultats soutiennent la combinaison de la vérification fondée sur les tests et de l'évaluation agentique par groupes pour améliorer la qualité et la stabilité du RL des agents de code.
One-sentence Summary
Researchers from Xiaomi, Renmin University of China, Peking University, and other institutions propose Gagar, a quality-aware credit redistribution framework for code agent RL that uses dynamic sampling and an SFT-trained agentic grader to rank test-passing trajectories, downweights lower-ranked trajectories, and applies sum-preserving advantage rescaling; industrial-scale experiments with MiMo-V2.6-Flash (310B total parameters) and MiMo-V2.6-Pro (1.02T total parameters) show improved code agent performance, reduced trajectory-length growth, and more stable training.
Key Contributions
- Gagar is a quality-aware credit redistribution framework for code agent RL that uses dynamic sampling to retain groups with both passing and failing trajectories, then uses an SFT-trained agentic grader to inspect and rank test-passing trajectories in a shared workspace.
- Gagar downweights lower-ranked passing trajectories and proportionally rescales the advantages of all passing trajectories, preserving the original total positive advantage while shifting credit toward higher-quality implementations.
- Controlled code-only experiments with MiMo-V2.6-Flash show improved code agent performance, reduced trajectory-length growth, and more stable training; mixed-task RL with MiMo-V2.6-Flash and MiMo-V2.6-Pro reaches DeepSWE v1.1 avg@3 scores of 67.9 and 71.9.
Introduction
Reinforcement learning with executable feedback is a scalable way to train code agents that inspect repositories, modify code, and validate changes over long interactions. In common group-relative setups such as GRPO, all test-passing trajectories receive the same positive outcome advantage, so the training signal cannot distinguish cleaner, more focused patches from overly complex or risky implementations. Static text-based assessment also tends to miss repository context and execution evidence. The authors introduce Gagar, a quality-aware framework that uses an agentic grader to inspect code, run targeted checks, and rank test-passing candidates within each rollout group, then redistributes credit among successful trajectories while preserving their total positive advantage. This approach is designed to reinforce precise, minimally invasive, merge-ready solutions and is validated at industrial scale with MiMo models.
Method
The authors leverage groupwise quality supervision to augment reinforcement learning for code agents, moving beyond binary task outcomes. As shown in the figure below, the framework integrates groupwise agentic grading into the RL training loop to evaluate and rank valid passing implementations.
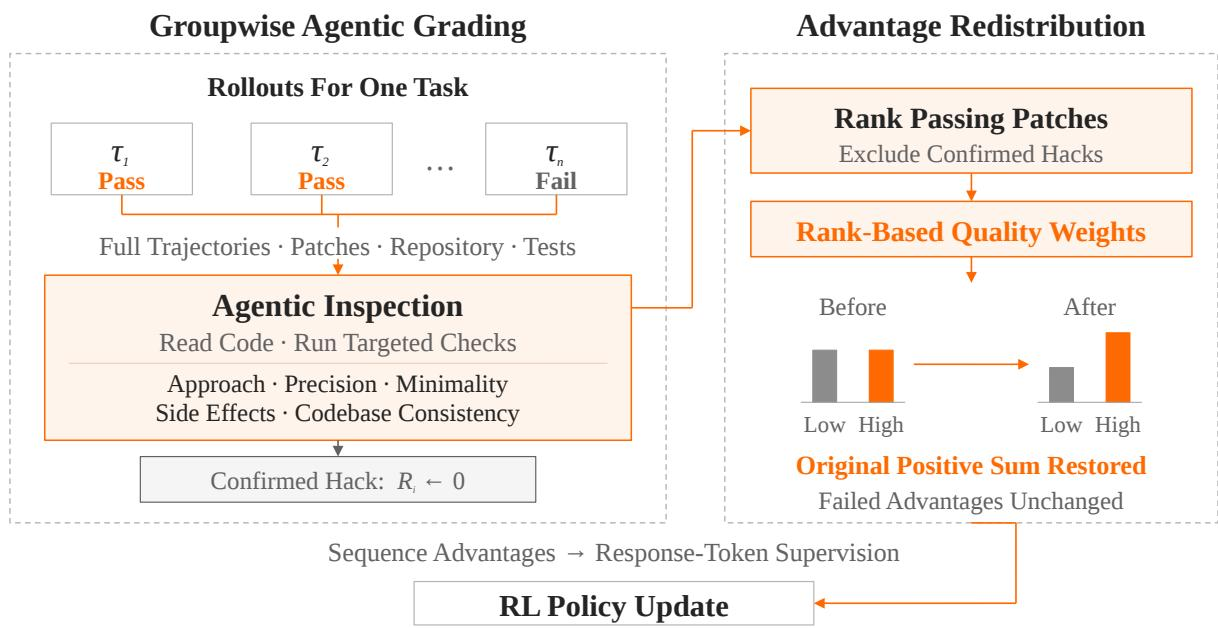
In the training setup, for each coding task, the rollout policy generates multiple trajectories. The final patch from each trajectory is evaluated using executable tests to yield a binary outcome reward. Let Gx={τi}i=1n denote the group of valid trajectories. The authors use the mean-centered outcome advantage Ai=Ri−Rˉ, where Rˉ=n−1∑j=1nRj. To ensure both successful and failed trajectories are present, dynamic sampling is adopted so that 0<Rˉ<1. All passing trajectories initially receive the same positive advantage 1−Rˉ, which fails to differentiate implementation quality.
To address this, the authors introduce groupwise agentic grading. The grader jointly examines all rollouts in a shared workspace containing the task specification, repository, complete trajectories, submitted patches, and test outputs. This comparison helps identify the strongest solutions and exposes ineffective strategies. The agentic grader gathers evidence iteratively, reviewing turn-by-turn summaries, reading relevant trajectory portions, and cross-checking patches against repository code and test logs. It can also run targeted checks. Quality is assessed across five criteria: approach suitability, precision, minimality, side effects, and codebase consistency. Passing solutions are checked for leaked or external answers, and confirmed hacks receive zero reward. The remaining candidates are scored and mapped to three quality tiers, which determine a discount factor fi∈(0,1] on their positive advantage.
Following grading, sum-preserving advantage redistribution is applied. Simply applying the discount factors would yield A~i=fiAi for passing trajectories, removing positive credit without a corresponding change on the negative side. This deficit weakens the reinforcement of successful trajectories. To preserve the total positive advantage S+=∑i∈PAi assigned to passing trajectories, the authors apply a common rescaling factor:
λ=∑j∈PfjAjS+The redistributed advantage is then:
Ai⋆={λfiAi,Ai,i∈P,i∈F.This ensures the total positive advantage is restored and the change is zero-sum over the passing subset, preserving both the ordering and relative strength of quality preferences.
During online training integration, grading runs asynchronously with rollout collection. The system checks the validity of grading results, falling back to original outcome advantages if necessary. Confirmed reliance on external solutions resets the affected reward to zero before group statistics are recomputed. The resulting sequence-level advantages are broadcast to the model-generated response tokens to supervise the RL policy update.
Experiment
These experiments evaluate Gagar on code-only reinforcement learning with MiMo-V2.6-Flash and on industrial-scale mixed-task RL with Flash and Pro, using DeepSWE v1.1 and SWE-bench Pro as benchmarks. The main comparisons show that Gagar improves long-horizon code agent performance, keeps trajectories shorter and more efficient, and yields higher implementation quality in external model review. An ablation confirms that sum-preserving redistribution is important for training stability, since downweighting passing trajectories without restoring credit leads to unstable dynamics and degraded downstream behavior. Industrial-scale runs further demonstrate competitive code agent performance relative to larger frontier models.
After industrial-scale mixed-task RL with Gagar, MiMo-V2.6-Flash and MiMo-V2.6-Pro achieve coding benchmark results competitive with strong external baselines. MiMo-V2.6-Pro outperforms Kimi K3 on DeepSWE despite having substantially fewer total parameters and surpasses GPT-5.6 Sol on SWE-bench Pro. Its DeepSWE score approaches GPT-5.6 Sol and Claude Opus 5, while it trails Claude Opus 5 on SWE-bench Pro. MiMo-V2.6-Pro outperforms Kimi K3 on DeepSWE despite using substantially fewer total parameters. MiMo-V2.6-Pro surpasses GPT-5.6 Sol on SWE-bench Pro. MiMo-V2.6-Pro approaches GPT-5.6 Sol and Claude Opus 5 on DeepSWE but remains below Claude Opus 5 on SWE-bench Pro. MiMo-V2.6-Flash achieves DeepSWE and SWE-bench Pro scores close to larger external models.
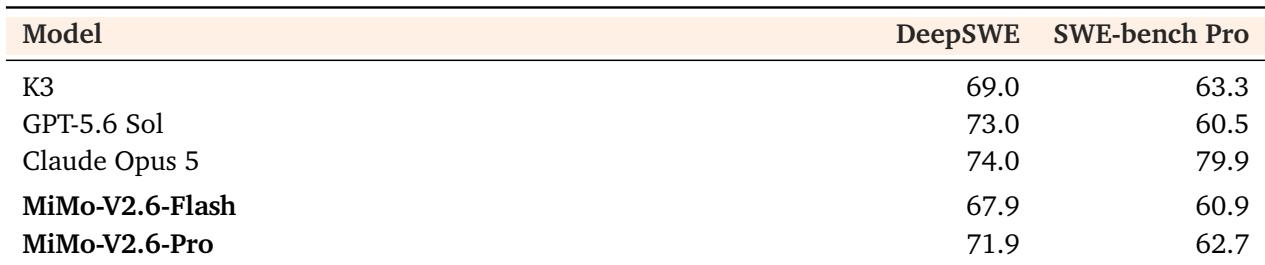
This experiment evaluates MiMo-V2.6-Flash and MiMo-V2.6-Pro after industrial-scale mixed-task RL with Gagar on coding benchmarks. The results show that MiMo-V2.6-Pro is competitive with strong external models, outperforming Kimi K3 on DeepSWE despite using substantially fewer parameters and surpassing GPT-5.6 Sol on SWE-bench Pro, while approaching GPT-5.6 Sol and Claude Opus 5 on DeepSWE but remaining below Claude Opus 5 on SWE-bench Pro. MiMo-V2.6-Flash also achieves DeepSWE and SWE-bench Pro scores close to larger external models.