Command Palette
Search for a command to run...
L'agent au bon goût : mesurer et améliorer le goût dans les tâches à long horizon
L'agent au bon goût : mesurer et améliorer le goût dans les tâches à long horizon
Wenbo Pan Zhichao Liu Shujie Liu Jingying Zeng Chin-Yew Lin Xianfeng Tang Yan Lu Qi He Xiaohua Jia
Résumé
Les agents LLM travaillent de plus en plus sur des tâches à long horizon, et les décisions qu'ils prennent en cours de route, comme l'hypothèse à tester ou l'implémentation sur laquelle s'appuyer, déterminent l'issue de l'ensemble de l'exécution. Bien prendre ces décisions devient une compétence clé pour les agents d'ingénierie comme de recherche. Nous appelons « goût » (taste) d'un agent la capacité à prendre de bonnes décisions à long horizon. Alors que les benchmarks existants mesurent le succès de bout en bout des agents sur des tâches à long horizon, aucun ne mesure le goût d'un agent. Pour remédier à ce problème, nous construisons Taste-Bench, un benchmark de questions de goût construites automatiquement à partir de trajectoires produites par des agents dans des tâches d'ingénierie et de recherche. Chaque question présente une bifurcation de décision, c'est-à-dire un point d'une trajectoire où plusieurs directions sont possibles et où l'une d'elles conduit à un meilleur résultat ; le modèle évalué choisit parmi ces directions sans voir ce qui se passe après la bifurcation. Nous extrayons automatiquement ces bifurcations à partir de tentatives parallèles sur la même tâche et de détours au sein d'une même trajectoire, sans nécessiter d'annotation humaine. Nous évaluons des modèles de pointe sur Taste-Bench et constatons que le meilleur modèle ne répond correctement qu'à 59,7 % des questions. Nous constatons en outre que les bifurcations dont l'élément décisif apparaît plus tard dans la trajectoire sont beaucoup plus difficiles pour tous les modèles, et qu'un budget de raisonnement plus important n'améliore pas la précision. Enfin, nous montrons que le goût peut être entraîné. Nous distillons le jugement d'un modèle enseignant ayant vu l'issue dans un modèle élève, et l'élève prend de meilleures décisions sur des tâches inédites et améliore le succès de bout en bout sur des tâches SWE-bench Pro mises de côté.
One-sentence Summary
Researchers from City University of Hong Kong and Microsoft introduce Taste-Bench, a benchmark that automatically mines decision forks from agent trajectories to measure long-horizon taste, and they find that frontier models answer only 59.7% of the questions correctly, that forks whose deciding evidence appears later in the trajectory are much harder while a larger reasoning budget does not improve accuracy, and that distilling outcome-aware teacher judgment into a student improves decisions and end-to-end success on held-out SWE-bench Pro tasks.
Key Contributions
- The paper formalizes taste as an agent's ability to choose the better direction at a decision fork and shows that this ability can be measured from hindsight over existing trajectories without human annotation.
- The paper constructs and releases Taste-Bench, a benchmark of 502 taste questions mined automatically from parallel attempts and detours in software engineering and machine learning research tasks; the best frontier model answers 59.7% of the questions correctly, and forks whose deciding evidence appears later are much harder.
- The paper shows that taste is trainable by distilling the reasoning of an outcome-informed teacher into a student, which improves decision quality on unseen tasks and yields end-to-end gains on held-out SWE-bench Pro tasks.
Introduction
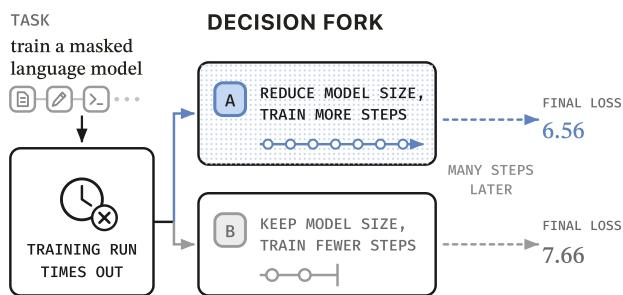
The authors study taste in LLM agents: the ability to make good long-horizon decisions whose impact appears only later, such as choosing a research hypothesis or implementation direction. Prior benchmarks measure end-to-end task completion but do not assess the quality of intermediate decisions, and expert annotation is expensive and hard to scale across domains. The authors leverage hindsight from existing trajectories, identifying decision forks where attempts diverge and later recorded outcomes label the better direction. They build Taste-Bench, a benchmark of 502 such questions from software engineering and machine-learning research, and show that taste can be measured automatically and improved by distilling a teacher’s reasoning, which also produces end-to-end gains on held-out tasks.
Dataset
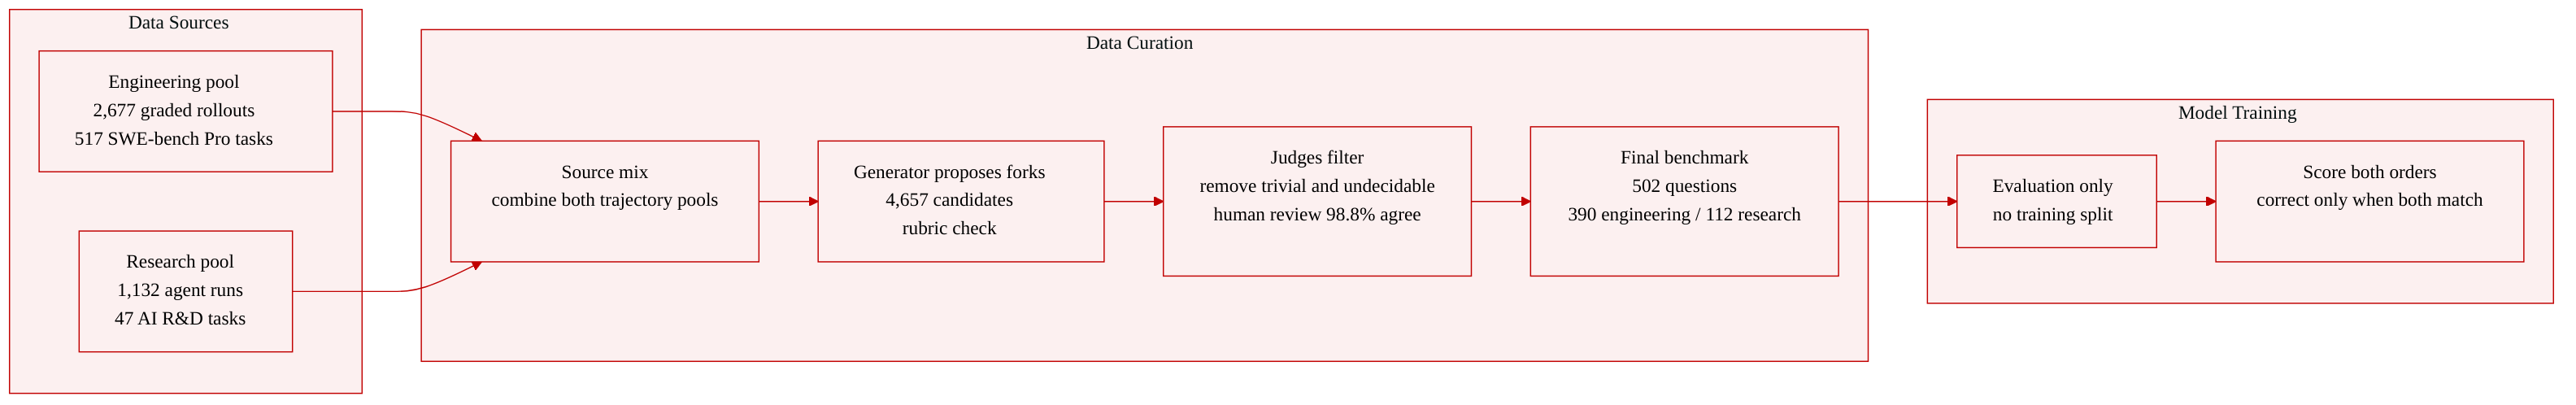
The authors introduce Taste-Bench, a benchmark of 502 taste questions derived from real agent trajectories. Each question is built by recovering a task, a trajectory prefix before a decision fork, two candidate directions, and a label from an unstructured record.
Sources and composition
- The benchmark uses two trajectory pools:
- Engineering pool: 2,677 graded rollouts from GPT-5.4 and GPT-5.5 agents on 517 SWE-bench Pro tasks.
- Research pool: 1,132 agent runs on 47 AI R&D tasks from RE-Bench and the research subset of HCAST, downloaded from MALT, METR's public transcript release.
- Questions are constructed from two complementary fork types:
- Parallel trajectories: pairs of attempts on the same task diverge at the same fork with opposite outcomes. The shared prefix becomes the question prefix, the two diverging directions become the candidates, and the branch that passes the tests or achieves the objective determines the label.
- Detour trajectories: a single trajectory where the agent takes a wrong direction, observes a failure, and later corrects itself. The abandoned direction and the later recovery become the candidates. The fork is placed right before the abandoned direction, and the prefix must not reveal the failure or the later fix.
Processing and filtering
- A generator model reads the trajectories, proposes candidate forks, applies a rubric, and keeps only candidates that can form valid questions.
- Judge models, distinct from the generator, remove two failure types:
- Trivial questions: every judge answers correctly from the two candidates alone without the trajectory.
- Undecidable questions: the recorded outcome is not clearly consistent with the label.
- A question is included only when every judge agrees with the label after reading the full task record, trajectory, and outcome.
- The generator proposes 4,657 candidate forks; 10.8% pass all filters, yielding 502 questions.
- The final benchmark follows a 2 × 2 design crossing construction type, parallel or detour, with domain, engineering or research. Engineering provides 390 questions and research provides 112.
Human validation
- In a review of 100 sampled questions, two reviewers separately chose a direction and then judged which decision was better after seeing summaries of the recorded continuations and outcomes.
- Of 172 explicit A/B judgments, 170 agree with the mined label, a 98.8% agreement rate.
- On the 74 questions where both reviewers chose A or B, inter-reviewer agreement is 98.6%, with Cohen's κ = 0.973.
Usage
- Taste-Bench is used only for evaluation, not for training. There is no training split or mixture ratio.
- Each question is presented to the evaluated model as a two-choice decision over the trajectory prefix and two candidate directions.
- To reduce position bias, each question is evaluated twice: once in a deterministic seeded order and once in the exact reverse order.
- In the main accuracy metric, a question counts as correct only when both orders are answered correctly. The paper also reports mean accuracy over the two orders.
Method
The authors view taste as a form of long-horizon judgment, where the advantage of a chosen direction only becomes apparent in later work. To measure this without expert annotation, they mine hindsight from existing agent trajectories. They identify decision forks where attempts at the same task share an equivalent prefix but diverge into different candidate directions. The outcomes of these branches estimate the quality of the judgments. Formally, for a task q with trajectory prefix ht and two candidate directions c1 and c2, the supported candidate is labeled based on the outcome measure U:
y=argi∈{1,2}maxU(Ei)The evaluated model π receives the question x=(q,ht,c1,c2) and its taste is estimated as the fraction of correct choices. To construct the Taste-Bench benchmark, the authors extract these forks from two types of trajectories: parallel trajectories, where an agent tries the same task multiple times and diverges, and detour trajectories, where an agent corrects itself within a single run.
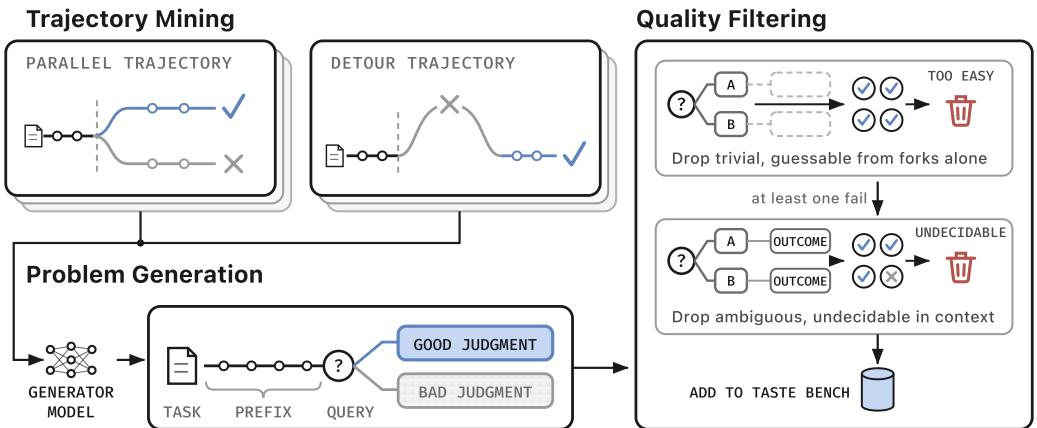
As shown in the figure above, the pipeline involves trajectory mining, problem generation, and quality filtering. A generator model reads trajectories from engineering and research pools to propose candidate forks. During the filtering stage, judge models remove trivial questions, where the answer can be guessed from candidate wording alone, and undecidable questions, where the recorded outcome is not clearly consistent with the label. This ensures that every released question requires genuine judgment over the trajectory context.
To improve model taste, the authors distill judgment capabilities into a base model using the constructed questions. The training pool consists of task-disjoint folds to prevent data leakage. Instead of fine-tuning directly on binary labels, which risks memorization, they distill complete reasoning sequences generated by a privileged teacher.
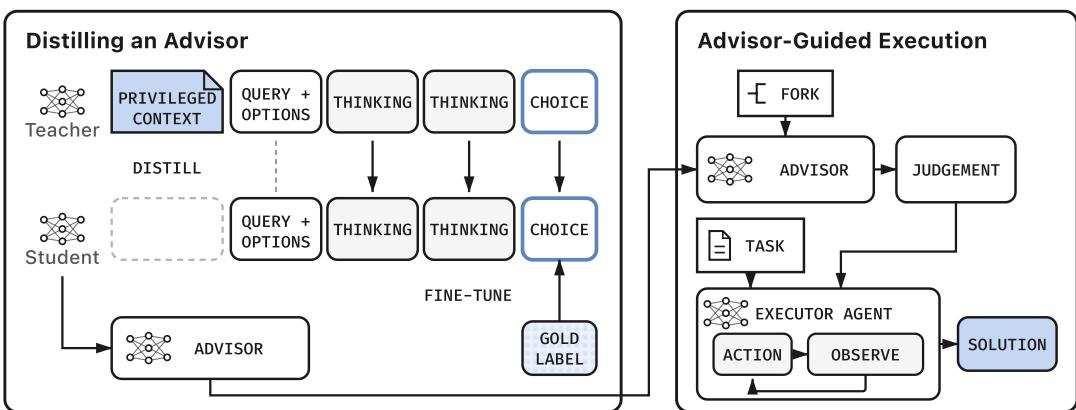
As illustrated in the figure above, the distillation process involves a teacher model that receives the question along with a demonstration of the supported candidate. The teacher generates a reasoning sequence and the final choice. The student model, which only sees the task, trajectory prefix, and shuffled candidates, is trained to align with the teacher's generated tokens. The loss is a token-level forward KL divergence computed over the reasoning tokens and the final choice. At evaluation time, the distilled advisor model provides judgments at each fork, which are injected as advice into the task context for an executor agent to complete the task independently.
Experiment
The evaluation uses two-choice taste questions presented in both orders, requiring a model to answer correctly in both orders to count as a correct judgment. Across 14 frontier models, no model approaches solving the benchmark, accuracy declines as the time horizon of a fork grows, and larger reasoning budgets do not improve taste, while comparison with SWE-bench Verified shows only partial correlation. Distillation demonstrates that taste can generalize to unseen tasks, and the distilled student's advice raises a downstream executor's success rate from 14.6% to 33.7%, near the 39.0% upper bound achieved with correct advice.