Command Palette
Search for a command to run...
RRSI : auto-amélioration récursive régularisée des harnais d’agents
RRSI : auto-amélioration récursive régularisée des harnais d’agents
Résumé
La capacité d’un agent LLM est largement amplifiée par son harnais, c’est-à-dire les invites, le flux de contrôle, l’outillage, la mémoire et la gestion du contexte qui entourent le modèle dorsal gelé. Des méthodes récentes automatisent de plus en plus ce processus en proposant et en sélectionnant de manière itérative des modifications composant par composant d’un harnais d’agent, établissant en pratique une forme d’auto-amélioration récursive (RSI) au niveau du système agent. Cependant, une telle évolution récursive peut surapprendre en mémorisant les tâches d’entraînement, montrant des gains importants en distribution qui se réduisent, voire disparaissent, sur des benchmarks hors distribution. Nous introduisons l’auto-amélioration récursive régularisée des harnais d’agents (RRSI), qui intègre les principes de régularisation dans l’auto-amélioration du harnais en contraignant la proposition et la sélection des candidats d’évolution. Le proposeur fonctionne avec un budget à recuit temporel, limitant le nombre de modifications qu’un candidat peut regrouper, et encourage les trajectoires inexplorées en fonction de l’historique d’évolution. Le sélecteur est doté d’un critique et d’un élagueur : le critique filtre les propositions spécifiques à un benchmark, tandis que l’élagueur supprime les modifications trop petites, trop coûteuses ou devenues inutiles. Ensemble, ces contraintes favorisent les mécanismes d’agent réutilisables plutôt que ceux spécifiques à un benchmark, voire le bruit. Sur huit benchmarks couvrant des tâches de codage, d’espaces de travail agentiques et de conception technique, RRSI gagne jusqu’à 14,1 points sur la partition sur laquelle il évolue et jusqu’à 4,7 points sur les cinq benchmarks hors distribution, tout en produisant un harnais qui consomme 30 % de jetons de politique de moins que l’évolution non régularisée.
One-sentence Summary
Researchers from Google Cloud AI Research, UNC-Chapel Hill, Stanford University, and Washington University in St. Louis propose Regularized Recursive Self-Improvement of Agent Harnesses (RRSI), which applies temporally annealed proposal budgets and critic-pruner selection to constrain harness evolution so that reusable mechanisms are favored over benchmark-specific overfitting; across eight benchmarks spanning coding, agentic workspace, and engineering design tasks, RRSI gains up to 14.1 in-distribution and 4.7 out-of-distribution points while using 30% fewer policy tokens than unregularized evolution.
Key Contributions
- Regularized Recursive Self-Improvement of Agent Harnesses (RRSI) constrains candidate proposal and selection during iterative harness evolution while leaving the harness edit space open.
- The proposal stage uses a temporally annealed editing budget and history-informed exploration to encourage unexplored trajectories, and the selection stage uses a critic to screen benchmark-specific proposals and a pruner to remove changes that are too small, too costly, or no longer useful, favoring reusable agent mechanisms over benchmark-specific ones.
- Across eight benchmarks spanning coding, agentic workspace, and engineering design tasks, RRSI improves the evolved split by up to 14.1 points and five out-of-distribution benchmarks by up to 4.7 points, while producing a harness that uses 30% fewer policy tokens than unregularized evolution.
Introduction
Modern LLM agents are systems in which a frozen backbone model is wrapped in a harness of prompts, control flow, tool interfaces, memory, and context management. Much recent agent progress has come from harness engineering, but this work is largely manual and limited by how many failed trajectories human engineers can inspect. Automated harness evolution using LLMs enables recursive self-improvement, yet it adaptively reuses a finite evolve set, creating overfitting risks from benchmark-specific fitting, evaluation noise, and complexity accumulation that do not transfer to unseen tasks. The authors propose RRSI, a framework that regularizes both proposal and selection during harness evolution while keeping all harness components editable, favoring simpler and more reusable edits and applying robust selection criteria against noisy feedback.
Method
The authors propose Regularized Recursive Self-Improvement (RRSI), a recursive harness evolution procedure that keeps the space of possible harness edits open while regularizing the search trajectory through that space. The harness may contain prompts, control flow, configuration, context management, tools, skills, memory, and subagents, and any of these may be modified, added, or removed. Rather than restricting this hypothesis space directly, RRSI constrains how the evolution moves through it.
At each round t, a proposer uses feedback from the finite evolve set to generate candidate edits to the current harness Ht, and a selector determines whether any candidate should replace the incumbent. Regularization operates on two sides. On the proposal side, RRSI limits how much adaptive capacity can be exercised in a single round and where that capacity is spent. On the selection side, RRSI constrains which empirical improvements are strong enough, efficient enough, and sufficiently free of leakage to survive.
The method draws three analogies to classical regularization. The annealed edit budget behaves like an L0-style cardinality constraint on the update. Structural pruning behaves like Lasso or L1-style sparsification. Complexity-aware acceptance behaves like Ridge or L2-style shrinkage, suppressing unchecked growth of the aggregate resource footprint without forcing any particular component to be removed.
Regularizing the proposal distribution
The proposer is regularized in three main ways: annealed update sparsity, evidence-aware credit assignment, and structured exploration.
L0-style annealed update sparsity
Unconstrained proposals can bundle many unrelated modifications into a single candidate, making it difficult to attribute any measured change to a particular mechanism. RRSI therefore caps the number of independently attributable edits in a proposal. For a run of T rounds, the edit budget at round t is
bt=⌈bmin+(bmax−bmin)⋅21(1+cos(πt/T))⌉.This schedule decreases from bmax to bmin. Early rounds may combine several coordinated changes to discover new mechanisms, while later rounds become increasingly sparse and attributable. If independently attributable edits are represented as binary activity indicators, this budget bounds their cardinality in an L0-style manner.
Evidence-aware credit assignment
Because evaluations repeatedly observe the same finite evolve set, re-testing hypotheses that earlier rounds already falsified wastes search capacity. RRSI records, for every evaluated candidate, the component it modifies, the hypothesis it tests, the source diff, the resulting score and cost changes, and whether the candidate was accepted. The proposer conditions on this history in later rounds. Rejected mechanisms remain negative evidence, while successful mechanisms retain explicit credit. As later rounds allow fewer edits per candidate, it becomes easier to attribute an observed improvement to a specific change.
Structured exploration
The same history reveals when the search has collapsed onto a narrow edit family, such as repeatedly rewriting prompts while leaving structural agent mechanisms untouched. RRSI treats the search as stalled when progress over the previous k rounds remains within the empirical noise band δ. During a stall, a small portion of the proposal budget is reserved for components that have not yet been exercised in the run. This acts like diversity or entropy regularization, redirecting limited proposal capacity toward underexplored mechanisms without changing which mechanisms the harness is allowed to contain.
Regularizing candidate selection
Standard harness evolution can promote the candidate with the largest measured score even when that score reflects leakage, stochastic variation, or costly growth. RRSI retains the same empirical objective but requires candidates to pass several non-compensatory checks before replacing the incumbent.
Leakage screening
Before full evaluation, a critic reads each candidate diff and rejects edits that explicitly encode task names, entity names, task-specific values, answers, or other logic specific to the evolve benchmark. It also rejects edits that add inert machinery. The screen targets benchmark-specific content rather than particular harness components, so generic prompt or tool-description improvements remain valid candidates. Screening before evaluation is important because a leaking candidate never receives the inflated evolve-set score that could make it attractive to later rounds.
Stability-aware acceptance
Repeatedly selecting among noisy evaluations can convert stochastic winners into permanent search state. Before evolution, RRSI repeatedly evaluates the unchanged base harness and estimates an empirical noise band δ. Let S⋆ denote the best evolve-set score observed so far. A candidate must satisfy the noise-adjusted floor
S^(H′)≥S⋆−δ.This floor prevents the search from walking downhill through a sequence of regressions that are individually small enough to be mistaken for noise.
Ridge or L2-style complexity-aware acceptance
For a candidate H′ relative to the current harness Ht, define
ΔS=S^(H′)−S^(Ht),ΔC=C^(Ht)C^(H′)−C^(Ht).For a candidate whose measured gain exceeds the noise band, ΔS>δ, RRSI requires
ΔC≤β0+β1ΔS.Here, β0 sets the cost increase tolerated for a negligible score gain, while β1 controls how much additional cost is allowed as the measured improvement increases. These values are selected on the evolve set and kept fixed. Thus additional inference cost must be justified by measurable performance improvement. The procedure uses policy-token cost as a common measurable proxy for aggregate resource footprint, producing a Ridge-like shrinkage effect against unconstrained growth.
Lasso or L1-style structural pruning
The annealed budget in Equation (4) sparsifies each update, while pruning sparsifies the retained harness. RRSI tracks whether recently exercised components have produced a strictly positive measured gain over a fixed pruning window. Components that remain unproductive are reported to the proposer as deletion targets in subsequent rounds. This is analogous to Lasso-style sparsification: mechanisms with insufficient evidence of utility are removed entirely, so the retained harness becomes structurally sparser rather than merely cheaper in aggregate. A mechanism must continue to earn its place instead of persisting simply because score-only evolution has no incentive to remove it.
Experiment
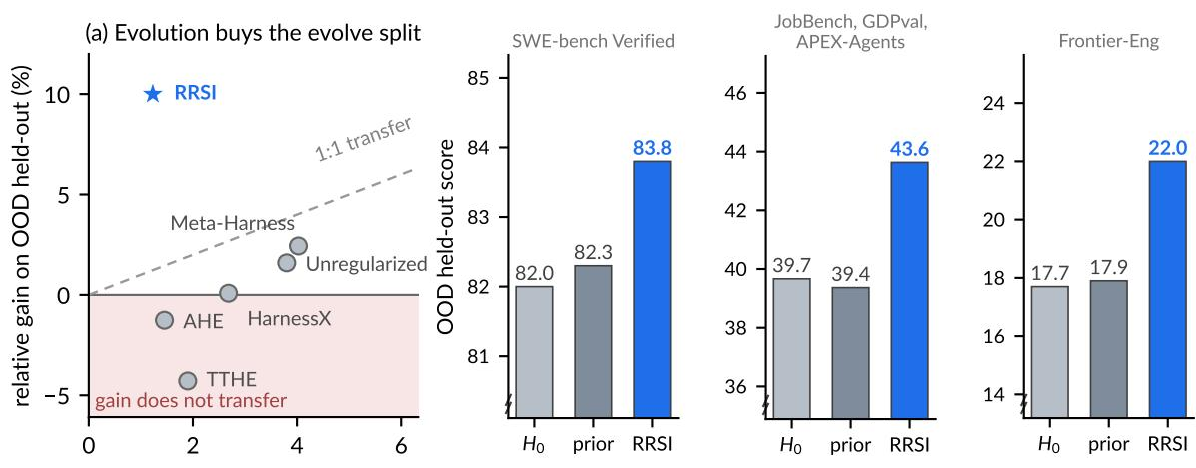
RRSI is evaluated across eight benchmarks spanning coding, agentic workspace, and engineering design tasks, with evolved harnesses tested on in-distribution held-out splits and on out-of-distribution benchmarks never seen during search. Compared with unevolved and prior harness evolution baselines under the same base harness, policy, and candidate budget, RRSI is the only method that consistently improves held-out and out-of-distribution performance without regressions, and its gains persist under deterministic simulator grading. Ablations show that both proposal-side and acceptance-side regularizers are important for transfer and cost control, while further analyses demonstrate that RRSI generalizes across different policy families and to a smaller backbone never used during search while producing the lightest evolved harness.
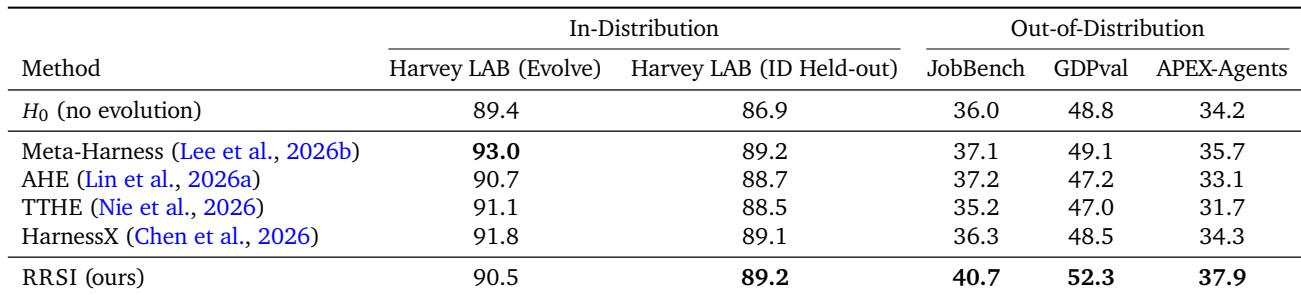
Across agentic workspace tasks, prior harness evolution methods improve the evolve split but their gains largely do not transfer out of distribution. RRSI records the smallest evolve-set gain among evolved methods yet produces the clearest out-of-distribution improvement over the unevolved harness, with no held-out regression. In-distribution held-out performance is similar across methods, while out-of-distribution results invert the evolve-set ranking. All prior methods improve on the evolve split, but only RRSI clears the base harness by more than a point on the out-of-distribution average. Meta-Harness, the strongest baseline on the evolve split, adds less than one point out of distribution, while HarnessX matches the base and AHE and TTHE fall below it. In-distribution held-out scores stay tightly clustered across methods, so evolve-set gains do not predict transfer.
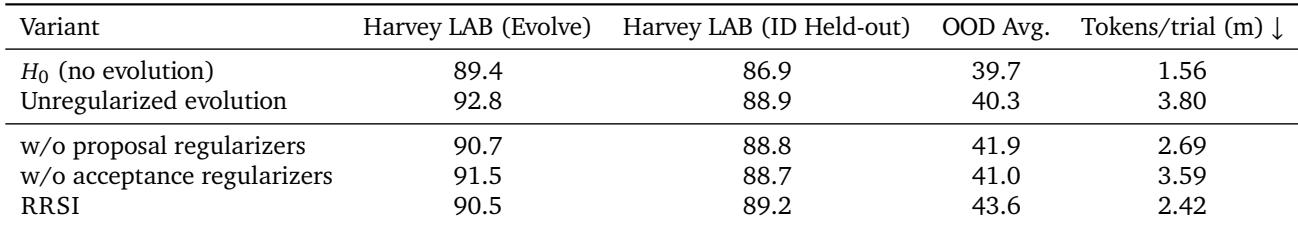
Ablating either group of regularizers improves the evolve-set score but reduces out-of-distribution performance, and removing the acceptance-side constraints also sharply increases token cost. Removing both constraints yields the highest evolve-set score but leaves transfer near the no-evolution baseline. The complete RRSI setup achieves the best out-of-distribution and held-out results among evolved variants with lower token use than any ablated or unregularized evolved harness. Removing proposal-side or acceptance-side regularizers trades transfer for evolve-set gains; acceptance-side removal additionally raises token cost substantially. The full RRSI configuration attains the highest out-of-distribution average and held-out score among evolved harnesses while using fewer tokens per trial than every ablated or unregularized evolved variant.
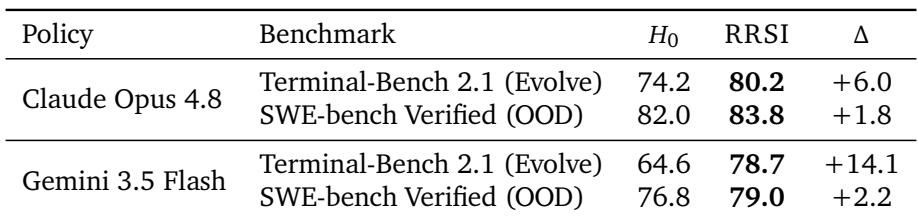
Regularized harness evolution improves coding performance for both Claude Opus 4.8 and Gemini 3.5 Flash on Terminal-Bench and transfers gains to unseen SWE-bench Verified. The lower-scoring Gemini policy receives the larger in-domain gain, while the stronger Claude policy improves less because it starts closer to the ceiling. Both policies show similar modest transferred gains, indicating the benefit is not tied to one policy family. RRSI improves Terminal-Bench 2.1 under both policies, with a larger gain for Gemini 3.5 Flash than for Claude Opus 4.8. Both policies improve on SWE-bench Verified, with similar modest transferred gains. The stronger Claude policy starts from a higher base and gains less overall, consistent with less remaining headroom.
The evolved harness improves Terminal-Bench 2.1 accuracy for both the Gemini 3.5 Flash search policy and the unseen Gemini 3.1 Flash Lite backbone. The weaker unseen model shows a smaller absolute gain but a strong relative improvement, indicating the harness mechanism transfers across capability levels. The search policy gains 14.1 points on Terminal-Bench 2.1 under the evolved harness. The unseen weaker policy gains 3.4 points, a 30.4% relative improvement over its base score, despite never participating in search.
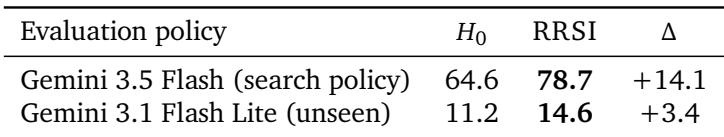
The experiments evaluate regularized harness evolution on agentic workspace and coding benchmarks, comparing RRSI against prior harness evolution methods and ablations. RRSI produces only modest evolve-split gains but the clearest out-of-distribution and held-out transfer, with lower token cost than ablated or unregularized variants; removing either regularizer trades transfer for evolve-set gains, and removing acceptance-side constraints sharply increases token use. The evolved harness also improves Terminal-Bench for multiple policies and transfers to SWE-bench Verified, with weaker models showing larger relative gains, including a 30.4% relative improvement for an unseen weaker backbone.