Command Palette
Search for a command to run...
Atria Dawn : l'aube de la superintelligence agentique sur les rôles évolutifs de la collaboration humain-IA
Atria Dawn : l'aube de la superintelligence agentique sur les rôles évolutifs de la collaboration humain-IA
Résumé
Alors que les agents IA deviennent des participants au développement de leurs successeurs, ils redéfinissent à la fois la production de l'intelligence et le rôle des chercheurs humains. Nous présentons Atria Dawn Preview, un modèle de langage agentique fondamental conçu pour les flux de travail de recherche scientifique et d'ingénierie, avec pour objectif d'élargir la frontière de la productivité des agents dans le monde réel. Ce modèle est entraîné via un pipeline d'expérience vérifiable qui relie les interactions médiées par des outils à des environnements exécutables et à des résultats vérifiés en externe. Sur 16 références couvrant la recherche réelle, l'ingénierie et le travail numérique, Atria Dawn Preview est compétitif avec les agents de pointe et atteint le score le plus élevé rapporté sur cinq d'entre elles. Au-delà de la performance autonome, nous examinons le processus réel de recherche et développement derrière ce modèle comme étude de cas de collaboration humain-IA, en analysant 769 enregistrements de tâches provenant de 56 participants ainsi que les journaux des agents. Lorsqu'on leur demande d'évaluer les tâches terminées dans des conditions comparables, les participants ont jugé environ un tiers des tâches assistées par IA comme irréalisables sans IA. Plus frappant encore, les agents proposent fréquemment des méthodes et mettent en œuvre des révisions, tandis que les humains conservent la plupart des décisions finales et guident l'exploration par le jugement et les retours. Ces observations indiquent un passage de l'exécution au niveau de la tâche à un partenariat au niveau du projet, où l'effort humain se concentre sur ce qui mérite d'être poursuivi et sur la manière dont les preuves devraient guider la recherche. Le progrès vers une recherche IA plus autonome doit donc faire avancer à la fois la capacité de découverte et la capacité de supervision humaine significative, préservant une autorité humaine responsable sur les risques et la direction du développement continu.
One-sentence Summary
Researchers at Fudan University introduce Atria Dawn Preview, a foundation agentic language model for scientific research and engineering, trained via a Verifiable Experience Pipeline that links tool-mediated interactions to executable environments and externally verified outcomes, which matches frontier agents across 16 benchmarks, achieves the highest reported score on five, and, in a case study of 769 task records from 56 participants, reveals that agents frequently propose methods and implement revisions while humans retain final decisions and guide exploration, signaling a shift from task-level execution to project-level partnership that demands both enhanced discovery capacity and meaningful human oversight.
Key Contributions
- Introduces Atria Dawn Preview, a 744-billion-parameter mixture-of-experts agentic language model trained via a Verifiable Experience Pipeline that grounds tasks in executable environments and checks outcomes against external signals, achieving competitive performance across 16 benchmarks and the highest reported score on five.
- Presents a case study of human–AI collaboration during the model’s development, analyzing 769 task records and agent logs from 56 participants, finding that AI proposed 64.6% of methods and decisions while humans made the final choice in 85.5% of cases, and that human intervention advanced 76.0% of difficult tasks.
- Reports empirical evidence on oversight dynamics, showing that participants rated about one-third of completed AI-assisted tasks as infeasible without AI, and that the daily median agent actions per human prompt rose from 11.0 to 28.5 over four weeks, indicating a shift from task-level execution to project-level partnership with humans retaining final authority.
Introduction
As language-model agents take on sustained tool use in software engineering and research, a key question emerges: who decides what problems are worth solving, which methods to pursue, and how to interpret results in a real model-development project? Prior work focuses on task-level competence but does not clarify the division of responsibility between agents and humans, nor whether agents can strengthen the research process itself, not just execute tasks.
The authors introduce Atria Dawn Preview, a 744-billion-parameter mixture-of-experts agentic language model trained for scientific research and engineering workflows. It uses a Verifiable Experience Pipeline that links tasks and agent trajectories to externally checked outcomes. Evaluated on 16 benchmarks, the model achieves top scores on five, though performance varies. The authors also analyze the development of Atria Dawn itself as a case study, drawing on 769 task records from 56 participants. They find that agents proposed 64.6% of methods and decisions, while humans made the final choice in 85.5% of cases, and 76.0% of tasks advanced due to human intervention. This reveals a shift where agents initiate approaches and execute changes, while humans focus on evaluation, selection, and steering direction. The authors argue that sustained recursive self-improvement requires more than task-level competence, including identifying worthwhile directions, designing informative experiments, and deciding when to redirect effort, areas where human judgment remains consequential.
Method
The authors introduce Atria Dawn Preview, a 744-billion-parameter mixture-of-experts foundation model engineered for complex research and engineering tasks. The architecture emphasizes sustained reasoning, tool utilization, and dynamic interaction with external environments.
The core training methodology relies on a Verifiable Experience Pipeline. This framework tightly couples task objectives with tool-mediated reasoning and externally verified outcomes to foster generalizable behaviors. During a rollout, the agent observes the environment state, selects and invokes tools, inspects the resulting outputs, and iteratively revises its actions based on feedback.
Final outcomes are rigorously checked using domain-specific signals, including executable tests, experiment metrics, file and application states, geometric checks, and source support. Following execution, trajectory curation filters the data by removing incomplete, contradictory, duplicate, or behaviorally invalid examples. This ensures that only high-quality experiences linking tasks to their trajectories, artifacts, and verification evidence are integrated into the model's reusable capabilities.
The system employs continuous failure analysis to drive subsequent task construction and environment refinement. Recurring issues such as ineffective tool selection, incomplete verification, missing evidence, and unsuccessful recovery prompt the generation of additional tasks and quality checks. Failed runs are repurposed as diagnostic cases when their outcomes are independently established, teaching the model reusable behaviors for state inspection, feedback interpretation, and error recovery.
In practical deployment, the system design delineates a clear division of labor between human researchers and the AI agent. Humans retain responsibility for defining goals, supplying missing context for failed runs, and specifying necessary changes, while the agent generates options and produces the bulk of the code, text, and revisions. This collaborative dynamic is reflected in the operational metrics, where the ratio of agent actions to human prompts increases significantly as researchers delegate more execution tasks.
As illustrated in the figure below:
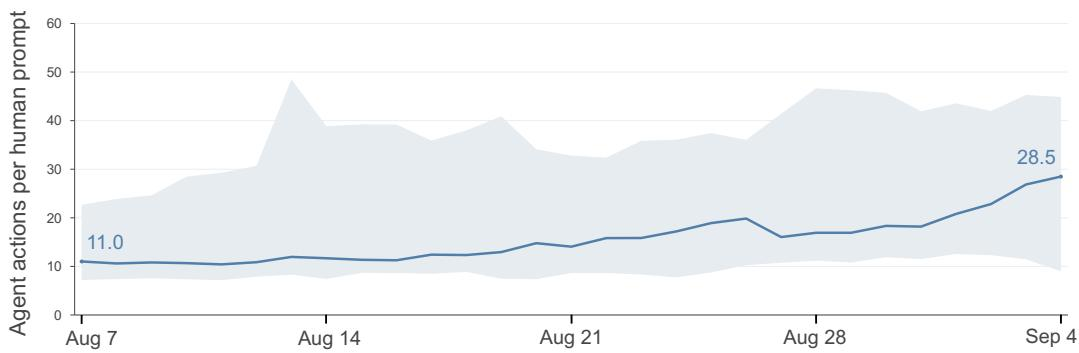
The rising ratio indicates that each act of human judgment now propagates through more agent actions, demonstrating a shift toward deeper execution delegation rather than growing autonomy.
Experiment
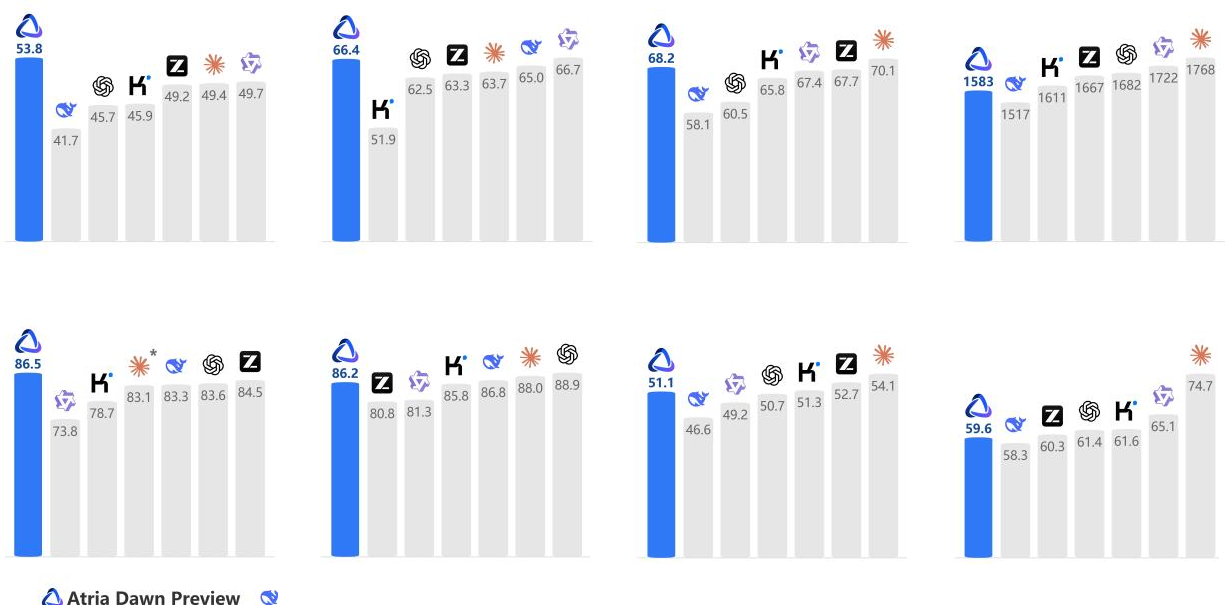
Atria Dawn Preview is evaluated across 16 benchmarks spanning tool use, search, research, workspace productivity, software engineering, and cybersecurity, achieving the highest reported score on five benchmarks and second-highest on three, with particular strength in general agentic tasks and security-related coding. Case studies demonstrate concrete capabilities across scientific research, software creation, report delivery, and vulnerability remediation, including building a MiniOS from scratch and training a large weather forecasting model. Analysis of human-AI collaboration during development shows that 96.5% of tasks involved AI, with 33.2% of AI-assisted tasks deemed infeasible without AI, while humans retained final decision authority in 85.5% of method or parameter choices and 95.4% of goals for the most AI-dependent tasks. When difficulties arose, human intervention was primarily informational, providing context or diagnosis rather than direct edits, and AI revised outputs after human feedback in 75.4% of substantively revised tasks.
Atria Dawn Preview leads or closely trails the best available models across a broad set of agentic benchmarks, with top scores in tool use, search, and cybersecurity. Its strengths are consistent across general agentic tasks, while in coding it shows particular security capability and competitive performance on software engineering and terminal tasks. Atria Dawn Preview achieves the highest reported score on five benchmarks, including AutomationBench, BFCL v4, DeepSearchQA, BrowseComp, and CyberGym. On three general agentic benchmarks (SkillsBench, Workspace-Bench, Workspace-Bench-Lite), it ranks second with gaps of less than two points to the leader. In cybersecurity (CyberGym), it leads by 2.0 points over the runner-up, indicating notable strength in vulnerability analysis and security tasks. On coding benchmarks, it is comparable to top models on SWE-bench Pro and Terminal-Bench 2.1, while leading on MLE-bench Lite among reported scores. Across remaining general tasks, it stays within the leading tier, often matching or surpassing several comparison models on search and professional benchmarks.
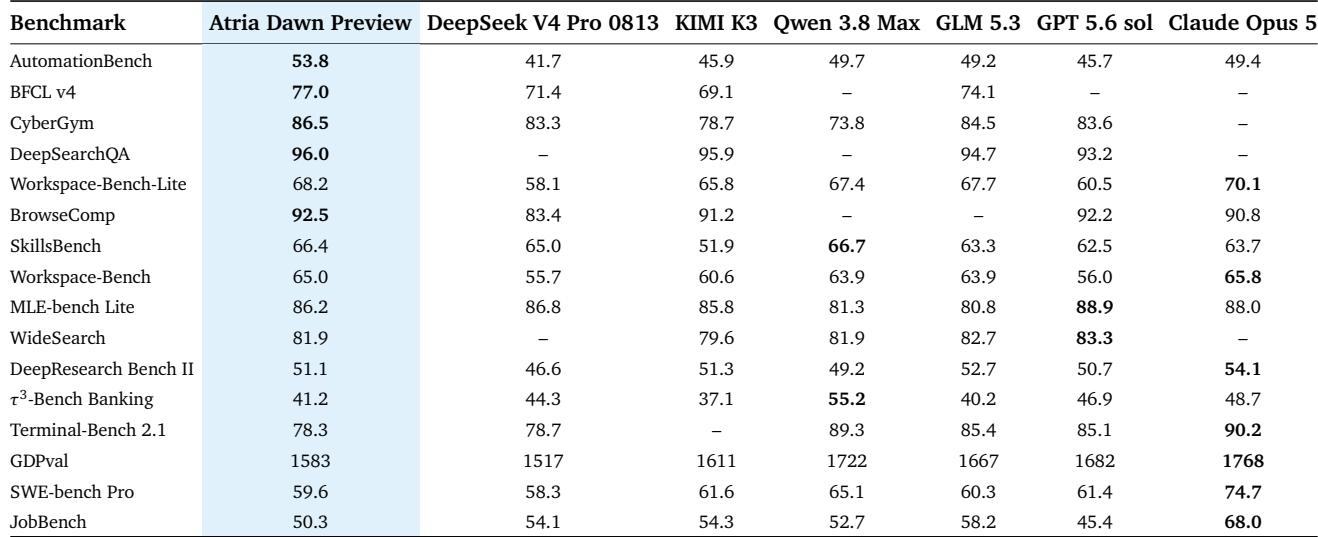
Atria Dawn Preview consistently matches or outperforms leading models across a wide range of agentic benchmarks, achieving top scores in tool use, search, and cybersecurity, and ranking first on five benchmarks including AutomationBench, BFCL v4, DeepSearchQA, BrowseComp, and CyberGym. It holds second place on three general agentic benchmarks with gaps under two points, and shows notable strength in vulnerability analysis. In coding, it is competitive on software engineering and terminal tasks, while leading MLE-bench Lite among reported scores, and remains in the leading tier across remaining general tasks.