Command Palette
Search for a command to run...
SAS : Sparsification d'attention simple par optimisation de bout en bout du classement contextuel
SAS : Sparsification d'attention simple par optimisation de bout en bout du classement contextuel
Zhiwei Li Lei Zhu Hao Gu Xiang Hu Yan Wang Haitao Mi Sirui Han Leowei Liang Zhijiang Guo
Résumé
La sparsification de l'attention après entraînement réduit le coût attentionnel quadratique cumulatif des Transformers pré-entraînés en sélectionnant un petit ensemble d'unités contextuelles (tokens ou blocs) pour chaque requête. Les méthodes entraînables existantes s'appuient généralement sur un sélecteur léger pour attribuer un score aux unités contextuelles, suivi d'une sélection stricte des Top-K, ce qui bloque les gradients provenant de la perte de modélisation du langage. De ce fait, ces méthodes recourent souvent à la distillation des distributions d'attention denses couche par couche. Bien que cette approche encourage le sélecteur à classer les unités contextuelles en fonction des poids d'attention denses du modèle original, un tel classement n'est pas directement aligné sur leur impact sur les prédictions finales du modèle sous une contrainte de budget attentionnel fixe (c'est-à-dire le nombre d'unités contextuelles prises en compte par requête), ce qui peut gaspiller le budget attentionnel limité sur des unités moins utiles. Pour remédier à ce désalignement du classement, nous proposons Simple Attention Sparsification (SAS), un mécanisme d'attention sparse à porte qui optimise le classement contextuel de bout en bout avec la perte de modélisation du langage. L'idée clé est d'injecter les scores continus du sélecteur dans les logits d'attention pendant l'entraînement, permettant à la perte de modélisation du langage de mettre à jour le sélecteur par rétropropagation standard. Nous identifions plusieurs choix cruciaux pour que cette conception simple fonctionne bien en pratique : placer la porte à l'intérieur du softmax d'attention sous forme logarithmique, utiliser des portes softmax normalisées pour calibrer le contexte historique par rapport au bloc courant toujours conservé, et préserver les scores continus du sélecteur afin que le modèle apprenne des priorités relatives plutôt que de simples sélections strictes. Pour prendre en charge l'entraînement sur de longues séquences, nous implémentons un noyau Triton efficace en mémoire qui intègre notre méthode dans un calcul de type FlashAttention. Sur des tâches de raisonnement, de compréhension de contexte long et agentiques, SAS surpasse systématiquement les bases de référence d'attention sparse entraînables pour différents budgets attentionnels, avec des gains particulièrement importants sous des budgets serrés, démontrant un classement contextuel plus efficace pour les tâches aval.
One-sentence Summary
Researchers from Tencent HY LLM Frontier and Hong Kong University of Science and Technology (Guangzhou & HK) propose Simple Attention Sparsification (SAS), a gated sparse attention mechanism that optimizes context ranking end-to-end by injecting continuous selector scores into attention logits and placing the gate inside the softmax in log-space, consistently outperforming trainable baselines on reasoning, long-context understanding, and agentic tasks, especially under tight budgets.
Key Contributions
- Simple Attention Sparsification (SAS) injects continuous log-space gates inside the attention softmax, enabling the context selector to be trained end-to-end with the language modeling loss instead of layer-wise attention distillation.
- The design relies on three critical choices: log-form gate placement inside the softmax, normalized softmax gates that calibrate historical context against the always-retained current block, and preserved continuous selector scores to learn relative priorities rather than only hard selections.
- A memory-efficient Triton kernel integrates SAS into FlashAttention-style computation for long-context training; SAS outperforms trainable sparse attention baselines on reasoning, long-conext understanding, and agentic tasks, with the largest gains under tight attention budgets.
Introduction
Long-context autoregressive inference incurs a quadratic attention cost that becomes a critical efficiency bottleneck for deployed large language models. Post-training attention sparsification addresses this by restricting each query to a subset of context blocks without architectural changes or retraining. Prior methods either use fixed heuristic rules that fail to adapt to prediction behavior, or train learnable selectors via layer-wise distillation of dense attention distributions. This distillation creates a ranking misalignment: it teaches selectors to mimic where dense attention focuses, not which context units actually improve final predictions, while ignoring cross-layer complementarity and value-matrix effects. The authors introduce SAS, an end-to-end optimization paradigm that makes selector scores differentiable inside the attention softmax, enabling direct training with the language modeling loss. They identify key design choices—log-space gate injection, softmax-normalized gating, continuous score preservation, and efficient sparse updates—that yield stable, informative gradients. SAS consistently surpasses prior post-training sparsification approaches, with pronounced gains under tight attention budgets on reasoning, long-context understanding, and agentic tasks.
Method
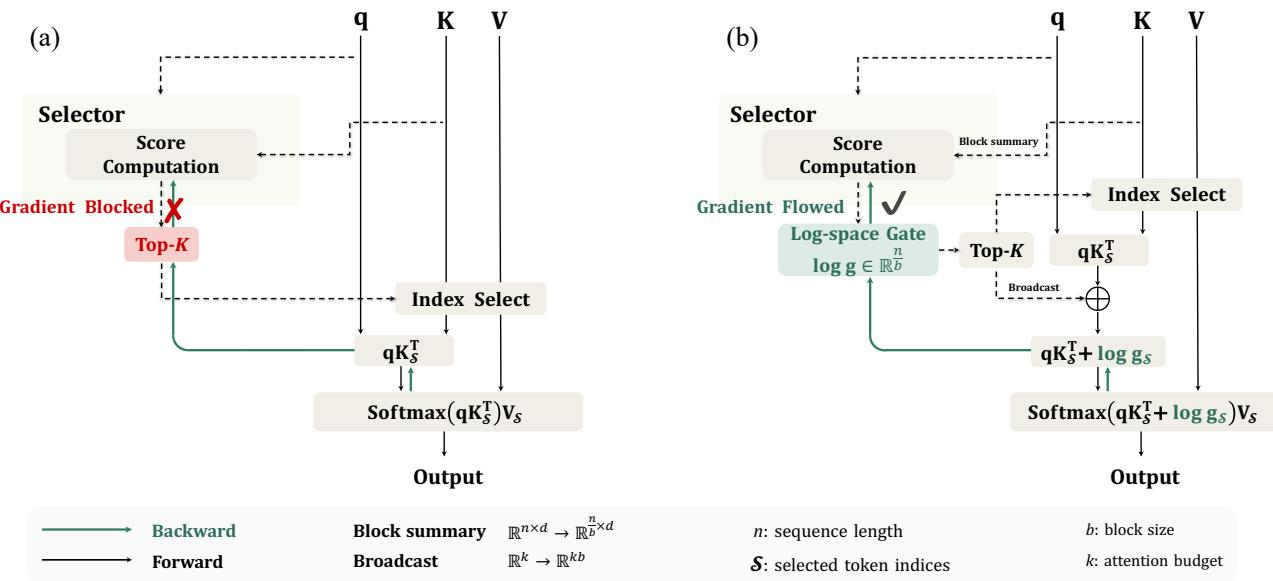
The authors present SAS (Simple Attention Sparsification), a method that trains a lightweight selector to rank context blocks based on the language modeling loss. The core idea is to reformulate sparse block selection as a differentiable context ranking problem. Instead of directly producing a discrete Top-K set, the selector learns a continuous ordering over candidate historical blocks, which then serves as the basis for sparse selection.
To make this block ranking learnable, the selector scores must influence the attention computation during training. The authors partition the context into an always-retained current block B0 and a set of C candidate historical blocks H={B1,…,BC}. The selector generates relevance scores s∈RC for the historical blocks, which are transformed into positive gates g=ϕ(s)∈R+C, while the current block retains a unit gate g0=1. These gates modulate the attention computation, allowing gradients from the language modeling loss to flow back to the selector.
The effectiveness of this differentiable ranking depends on four key design elements: gate position, gate activation, ranking preservation, and training scope.
As shown in the figure below:
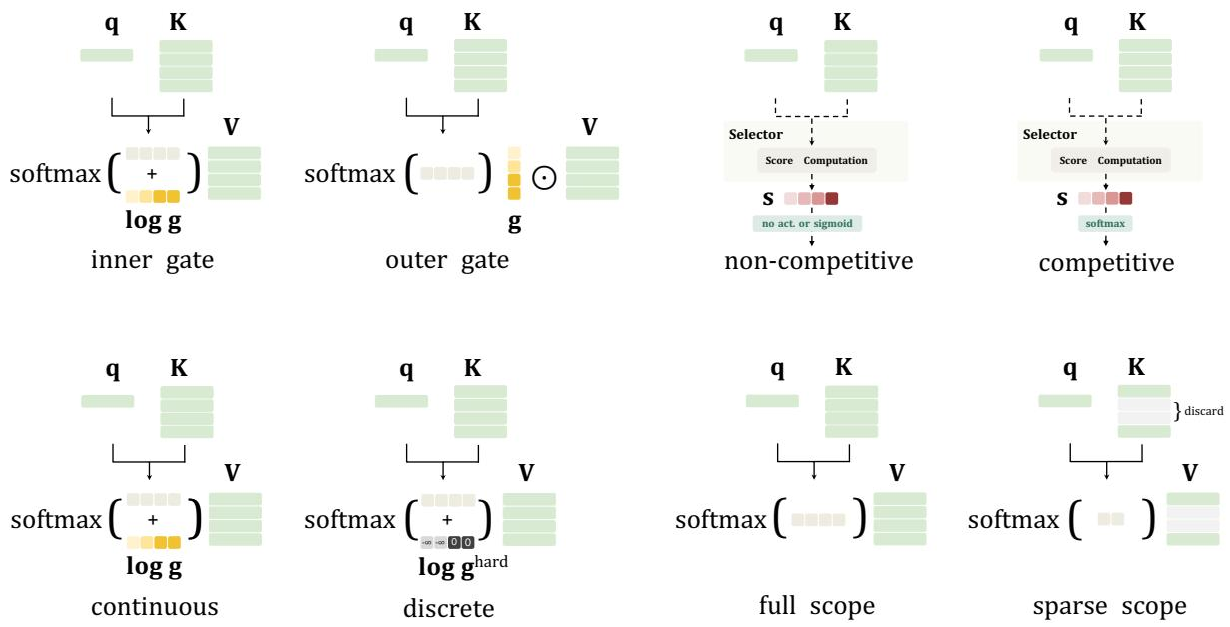
First, gate position determines whether the gates are injected inside the softmax, oinner=softmax(qK⊤+logg)V, or applied outside the softmax, oouter=softmax(qK⊤)(g⊙V). Second, gate activation defines how block scores are transformed, comparing normalized softmax gates, independent sigmoid gates, and unnormalized logit injection. Third, ranking preservation dictates whether training uses continuous soft gates or collapses them into discrete hard Top-K gates using the Straight-Through Estimator. Finally, training scope controls whether the model receives gradients from all context blocks or only the selected sparse subset.
Based on controlled ablations of these elements, the authors instantiate SAS with four specific choices: inner softmax gate injection, softmax gate activation, soft gates to preserve ranking information, and a sparse training scope. During training, the selector computes scores s=Rθ(q,{KBm}m=1C), which are converted into normalized gates g=softmax(s). The Top-K historical blocks are selected, and their gates are broadcast to the token level. The resulting attention computation is formulated as:
oSAS=softmax(qKS⊤+loggS)VSwhere the selected historical blocks receive normalized log-gate biases and the current block remains unbiased. At inference time, this learned continuous ranking is discretized into Top-K block indices.
To implement this efficiently, the authors design a specialized FlashAttention-style Triton kernel. This kernel fuses the block gate into the tile-level qKS⊤ computation during the streaming scan. It adds the normalized log gate to the attention logits of selected historical blocks, masks out non-selected blocks, and performs standard online softmax updates without materializing the full attention matrix. The backward pass accumulates block-level log-gate gradients by summing the attention-logit gradients within each selected historical block, maintaining memory efficiency while supporting the sparse training scope.
Experiment
SAS trains a lightweight block selector end-to-end from the language modeling loss, in both post-training sparsification (frozen LLM, math-only training) and continued pretraining (joint backbone and selector training), and is evaluated across reasoning, long-context understanding, and agentic tasks. The method consistently outperforms distillation-based sparse attention, often recovering full attention accuracy at modest block budgets, while transferring robustly to long-context and tool-use scenarios even when trained solely on math data. Analysis reveals that SAS’s selection is more complementary across layers, yielding shorter generation traces and fewer truncations, and its decode efficiency scales to large speedups (e.g., over 10× at batch 8) as context length grows.
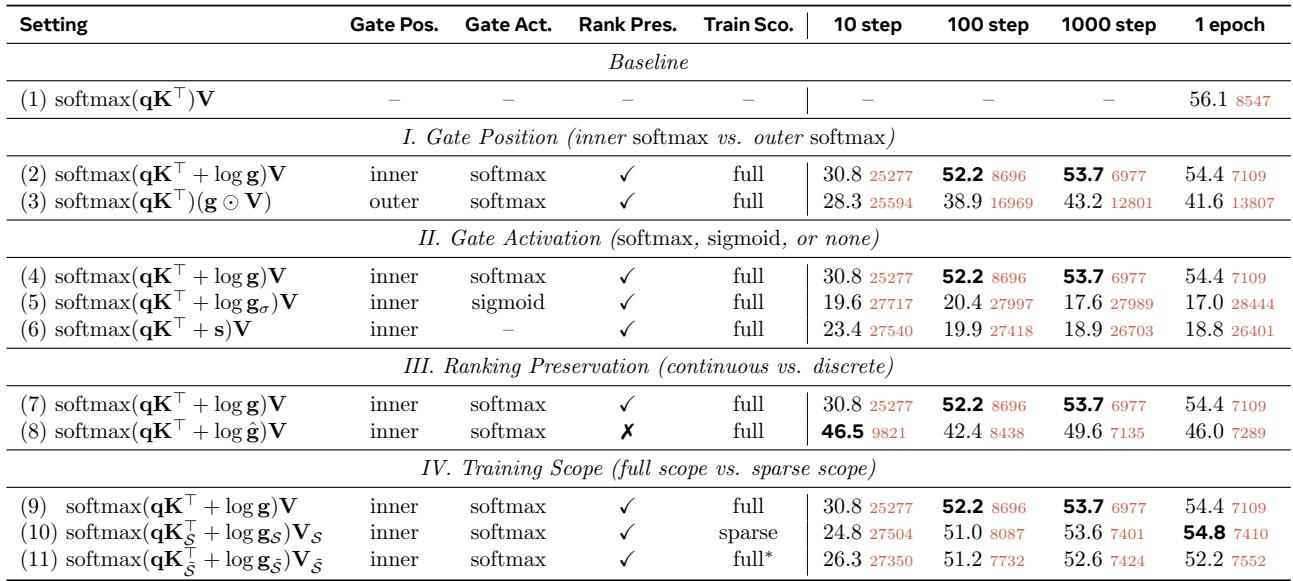
Placing the gate inside the attention softmax significantly outperforms applying it after the softmax, achieving accuracy close to the ungated baseline while shortening generation length. Softmax-normalized gating is essential for calibrating historical context against the current block, leading to better performance and training stability. Inner softmax gating reaches 54.4% accuracy at one epoch with a generation length of 7,109 tokens, nearly matching the baseline's 56.1% and greatly surpassing outer gating's 41.6% and longer 13,807-token output. Softmax gate activation outperforms sigmoid and unnormalized logit injection because it normalizes historical context against the unit-gated current block, enabling stable training and higher final accuracy.
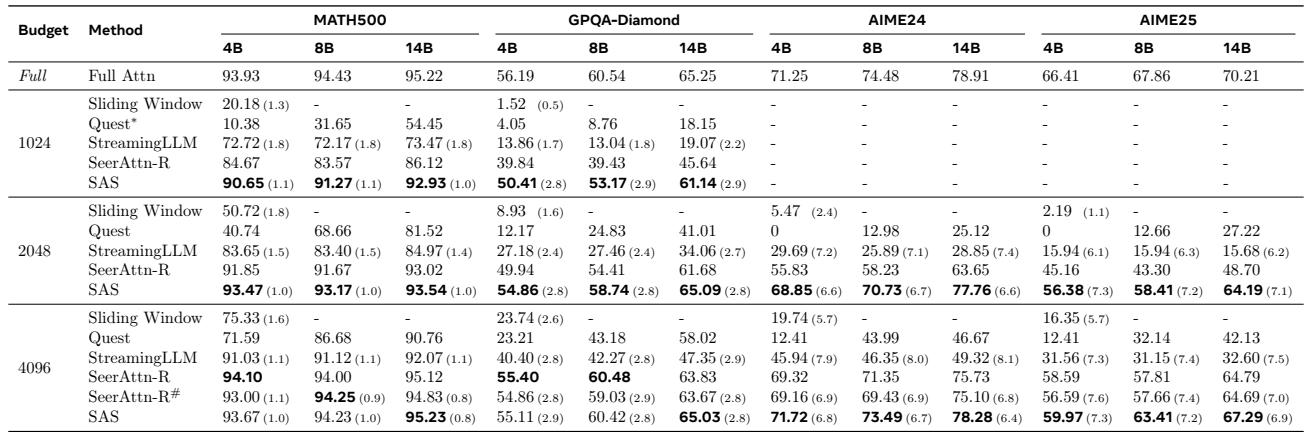
SAS substantially outperforms all sparse attention baselines on reasoning benchmarks, especially at tight token budgets. The language modeling loss used to train the selector proves more effective than the attention distillation used by SeerAttention-R, and at moderate budgets SAS can match or surpass full attention accuracy. At a budget of only 1024 tokens, SAS keeps reasoning accuracy close to full attention, while static sparsity methods like Sliding Window and query-aware Quest collapse. SAS consistently beats SeerAttention-R, which uses the same gate architecture but is trained with attention distillation, confirming the superiority of the language modeling objective for sparse selection. With a 4096 token budget, SAS recovers full attention reasoning, e.g., on AIME24 it exceeds full attention (71.72 vs. 71.25) for Qwen3-4B.
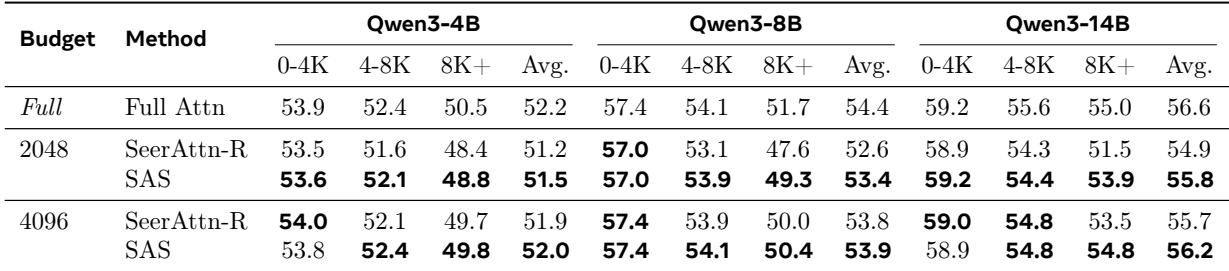
SAS outperforms SeerAttention-R on LongBench across all budgets and model sizes, with gains widening on longer inputs. At a 4096 token budget, SAS nearly matches full attention, showing that a selector trained solely on math data transfers effectively to long-context understanding. SAS improves the 8K+ token bucket over SeerAttention-R, most notably by +2.4 points for Qwen3-14B at budget 2048. At budget 4096, SAS recovers full attention performance on Qwen3-14B (56.2 vs 56.6 average), despite the distribution shift from math training.
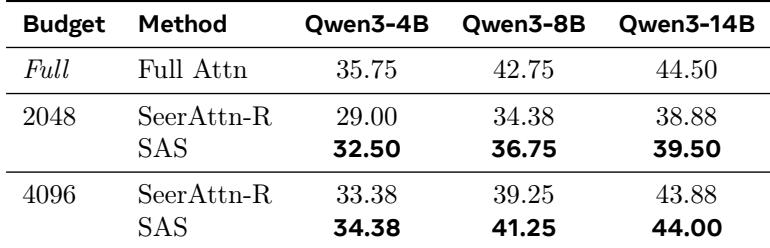
On multi-turn agentic benchmarks, SAS consistently outperforms the SeerAttention-R sparse method across all tested model sizes and token budgets. At a 4096-token budget, SAS nearly matches the accuracy of full attention, and at a tighter 2048 budget it delivers clear improvements, demonstrating the effectiveness of end-to-end selector training for complex interactive tasks. SAS beats SeerAttention-R on every backbone and budget, with a +3.5 point gain on Qwen3-4B at a 2048-token budget. At a 4096-token budget, SAS recovers full attention performance almost completely (44.00 vs. 44.50 on Qwen3-14B).
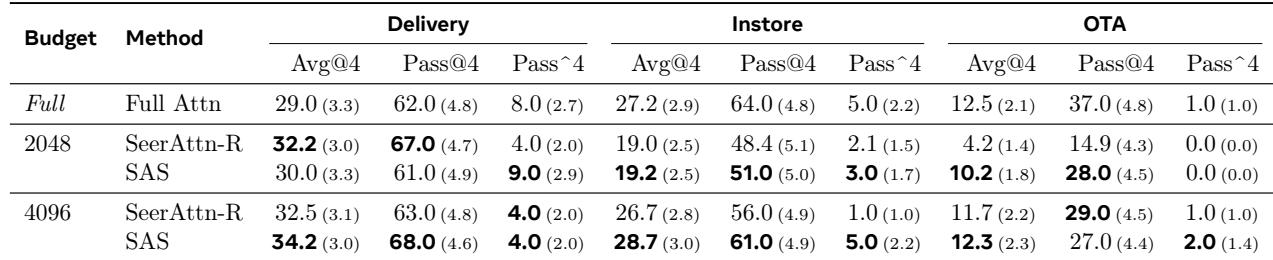
On VitaBench with Qwen3-14B, SAS outperforms SeerAttention-R on most metrics across Delivery, Instore, and OTA scenarios at both budget 2048 and 4096. At budget 4096, SAS closely approaches full attention performance, demonstrating that end-to-end sparse selection remains reliable in realistic long-horizon tool-use settings. At budget 4096, SAS attains a Delivery Pass@4 of 68.0, exceeding both SeerAttention-R (63.0) and full attention (62.0). In the OTA scenario at budget 2048, SAS more than doubles SeerAttention-R on Pass@4 (28.0 vs. 14.9) and raises Avg@4 from 4.2 to 10.2.
The evaluation first establishes that placing the gate inside the attention softmax and using softmax activation are essential for stable training and for maintaining accuracy close to an ungated baseline while producing compact outputs. Across reasoning, long‑context understanding, multi‑turn agentic tasks, and realistic tool‑use benchmarks, SAS, whose selector is trained end‑to‑end with a language modeling objective, consistently outperforms sparse attention methods trained with attention distillation. At moderate token budgets SAS recovers full‑attention performance or nearly matches it, demonstrating that the language‑modeling–trained selector transfers effectively from math data to diverse long‑context and interactive settings.