Command Palette
Search for a command to run...
OpenWAM : une exploration ouverte et modulaire vers le pré-entraînement systématique de modèles monde-action
OpenWAM : une exploration ouverte et modulaire vers le pré-entraînement systématique de modèles monde-action
Résumé
Les modèles monde-action héritent des connaissances du monde à partir de modèles génératifs vidéo et les transforment en signaux de contrôle exécutables grâce à l'expérience incarnée. Cependant, les systèmes existants sont monolithiques : le backbone génératif, la représentation visuelle, l'architecture, le flux d'information, la procédure d'inférence et les données d'entraînement sont étroitement couplés, ce qui obscurcit les choix de conception qui comptent et pourquoi. Nous introduisons OpenWAM, une pile de recherche ouverte qui transforme le pré-entraînement monde-action en un programme expérimental contrôlé. OpenWAM-Infra factorise l'espace de conception des WAM en modules composables avec un entraînement, une inférence, un déploiement et une évaluation unifiés. Sur ce substrat, OpenWAM-Study examine trois questions à travers des expériences contrôlées : quoi hériter, comment l'apprentissage du monde et de l'action interagissent, et comment leur synergie évolue ; et distille trois principes : le transfert de connaissances en amont passe par un backbone génératif suffisamment capable et un espace latent compact et riche en informations ; la synergie monde-action nécessite une capacité d'action dédiée, un flux d'information explicite du monde vers l'action, et un débruitage conjoint synchronisé ; et le pré-entraînement incarné améliore principalement la généralisation hors domaine, avec un co-entraînement en une étape sur des données égocentriques et robotiques intégrant la couverture du monde et l'ancrage de l'action. En composant ces principes, nous construisons OpenWAM-α, un WAM ouvert pré-entraîné sur environ 6 400 heures de données humaines égocentriques et robotiques, et évalué sur des benchmarks de simulation et du monde réel. Sur les huit benchmarks de simulation et les expériences robotiques réelles, qui couvrent ensemble des embodiments allant de la manipulation à un seul bras et à deux bras jusqu'aux mains dextres, OpenWAM-α offre des performances constamment excellentes, maintenant son statut de premier plan de la simulation au monde physique. Nous publions la pile complète, y compris l'infrastructure, les protocoles d'évaluation, les modèles pré-entraînés et les recettes de données, pour faciliter la recherche future.
One-sentence Summary
Researchers from National University of Singapore, Tsinghua University, Peking University, and The University of Hong Kong et al. introduce OpenWAM, an open modular stack that factorizes world–action model pretraining into composable modules, distills three design principles, and builds OpenWAM-α pretrained on 6400 hours of egocentric and robot data, achieving top-tier performance across eight simulation benchmarks and real-robot tasks spanning single-arm, bimanual, and dexterous manipulation.
Key Contributions
- Introduces OpenWAM, an open research stack that factorizes world–action pretraining into composable modules (OpenWAM-Infra), enabling controlled experiments across architecture families, training, inference, deployment, and evaluation on eight simulation benchmarks and real robots.
- OpenWAM-Study derives three design principles from controlled experiments: knowledge transfer requires a capable generative backbone with a compact latent space, world–action synergy needs dedicated action capacity with explicit information flow and synchronized joint denoising, and embodied pretraining mainly improves out-of-domain generalization via one-stage co-training on egocentric and robot data.
- OpenWAM-α, pretrained on roughly 6,400 hours of egocentric human and robot data, delivers consistently strong performance across eight simulation benchmarks and real-world single-arm, bimanual, and dexterous-hand tasks, with the full stack, evaluation protocols, pretrained weights, and data recipes released publicly.
Introduction
Embodied intelligence requires more than perception; an agent must predict how the world changes and act to influence it. While video generation models capture rich visual dynamics from abundant data, robot trajectories with executable action labels are scarce, creating a fundamental data asymmetry. Prior approaches either learn control solely from demonstrations, like ACT and Diffusion Policy, or inherit semantic knowledge from vision language models, but they do not leverage the temporal evolution priors inherent in video generation. World Action Models (WAMs) address this by inheriting a generative prior over visual dynamics and adapting it through embodied experience, yet existing systems are monolithic, tightly coupling architecture, data, and training, which obscures which components drive success.
The authors introduce OpenWAM, an open research stack that factorizes the WAM design space into modular components, enabling controlled experiments. Through OpenWAM-Study, they identify three key principles: effective world knowledge transfer requires a capable generative backbone and a compact visual latent space; world action synergy demands sufficient action specific capacity, explicit information flow, and a joint denoising schedule rather than just joint prediction; and embodied pretraining mainly boosts out of domain generalization, with joint training on human egocentric video and robot trajectories offering the strongest integration. They instantiate these findings in OpenWAM-α, a pretrained model scaled to 518M frames of heterogeneous data across a unified 80 D action space, demonstrating consistent performance on eight simulation benchmarks and real robot platforms. The full stack, including infrastructure, evaluation protocols, and weights, is released to support reproducible research.
Dataset
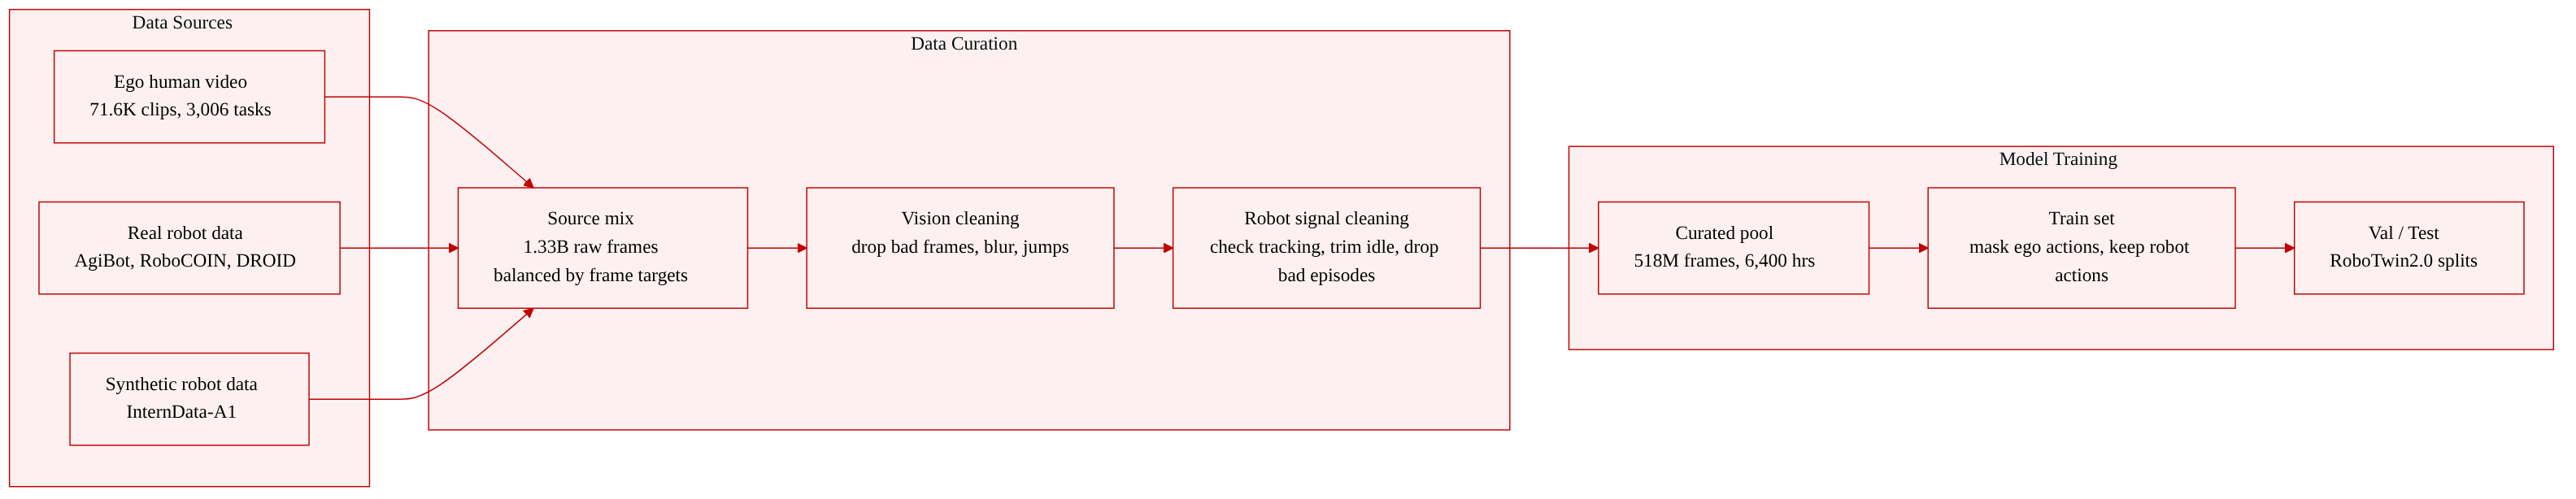
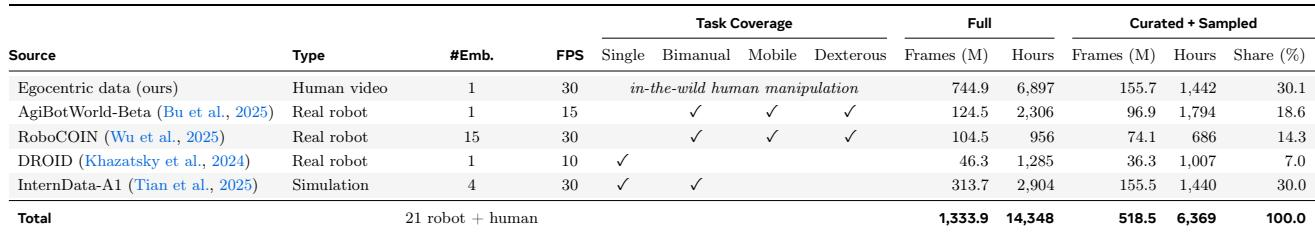
The authors construct the pretraining dataset for OpenWAM-α from five sources spanning three data types: egocentric human video, real-world robot data, and synthetic robot data. From a raw pool of approximately 1.33 billion frames (about 14,300 hours), they curate a training set of 518 million frames (about 6,400 hours) through a combination of cleaning and per-source subsampling.
Dataset Composition and Sources
- Egocentric human data: A custom-built dataset of 71.6K long-form first-person recordings, each 0.25 to 6 minutes long, covering 3,006 everyday manipulation tasks. This source provides broad visual and interaction diversity but carries no robot action labels.
- Real-world robot data: Sourced from AgiBotWorld-Beta, RoboCOIN, and DROID, this data grounds the action stream with executable trajectories across 17 physical platforms and provides faithful visual observations of robots in physical environments.
- Synthetic robot data: From InternData-A1, this source broadens coverage of single-arm and bimanual manipulation skills under diverse environmental variations.
Data Budget and Sampling
- The authors allocate per-source hour budgets based on frame-based targets: egocentric and synthetic sources each contribute 30% of total training frames, while the remaining 40% is divided among the three real-robot sources in proportion to their curated valid-frame counts.
- This balancing accounts for different native frame rates across sources.
- Within each source, the hour budget is water-filled across constituent sub-datasets, and whole episodes are subsampled from the curated pool under a fixed seed until the budget is met.
- Training draws samples proportionally to actual per-source counts, so every retained sample is visited exactly once per epoch.
Data Curation
The cleaning protocol operates at two levels: vision-level cleaning for all sources, and signal-level cleaning specific to robot data.
Vision-Level Cleaning
- Removes undecodable video, frozen or duplicated frames, black, white, and solid-color frames, over- and under-exposure and exposure flicker, blurred frames, and abrupt visual jumps.
- For egocentric data specifically, segments where hands leave the field of view are removed, and recordings with empty or invalid language annotations are discarded.
Signal-Level Cleaning (Robot Data Only)
- Signal integrity: An episode is discarded if the end-effector state fails to track commanded actions (amplitude ratio at least 3x with per-axis correlation below 0.5), or if video-signal misalignment affects more than 2% of frames.
- State-first idle detection: Leading and trailing segments with static state are trimmed using per-robot motion thresholds calibrated from the p99.5 of single-frame deltas, confirmed when average end-effector translation and geodesic rotation rates fall below 2 cm/s and 5 degrees/s. Mid-episode pauses are never cut. State discontinuities such as jerk and spike outliers are screened with robust median-MAD thresholds.
- Visual cross-checking: When state moves but all camera views remain visually static, the motion is attributed to sensor jitter and trimmed. A genuinely moving arm observed by a frozen camera marks a capture defect, and the episode is removed.
- Episode-level deletion: An episode losing more than 70% of its frames to the above steps, or whose video is frozen for 90% or more of its length, is dropped entirely.
How the Data Is Used in the Model
- The egocentric human data has its action and proprioception channels fully masked, so it supervises only the world stream.
- Real-world robot data grounds the action stream with executable trajectories.
- The authors compare supervised fine-tuning from scratch with three pretraining strategies under an identical 600-hour data budget: robot-only (full budget on robot data), and two mixed variants combining 350 hours of egocentric data with 250 hours of robot data, either in two stages (ego then robot) or jointly in one stage (ego + robot co-train).
- All variants undergo identical downstream fine-tuning, with the dual-system joint self-attention architecture and synchronized denoising kept fixed.
- Evaluation uses two protocols: RoboTwin2.0-Clean2Random fine-tunes on Clean and evaluates on Clean (in-domain) and Randomized (out-of-domain); RoboTwin2.0-Full fine-tunes on the full training set and reports mean success rate over both conditions.
Method
The authors leverage a modular infrastructure, OpenWAM-Infra, to factor world-action modeling into decoupled components with explicit interfaces. This design addresses the tight coupling and idiosyncratic implementations common in existing systems. The core of this infrastructure is a composable model architecture, a unified training runtime, a flexible deployment runtime, and a standardized evaluation protocol.
Composable Model Architecture OpenWAM-Infra organizes a World-Action Model (WAM) as three classes of interchangeable modules assembled by a composition rule C(E,S,M). The Visual Encoder E maps observations into the latent sequences predicted by the world stream and remains frozen during training. The Stream Backbones S process the model's token streams, including a world stream for visual state prediction, an action stream for action chunk prediction, and an optional understanding stream. The Visibility Attention Mask M specifies the attention relations among streams and tokens, governing information flow through intra-modality and cross-modality blocks.
Refer to the framework diagram.
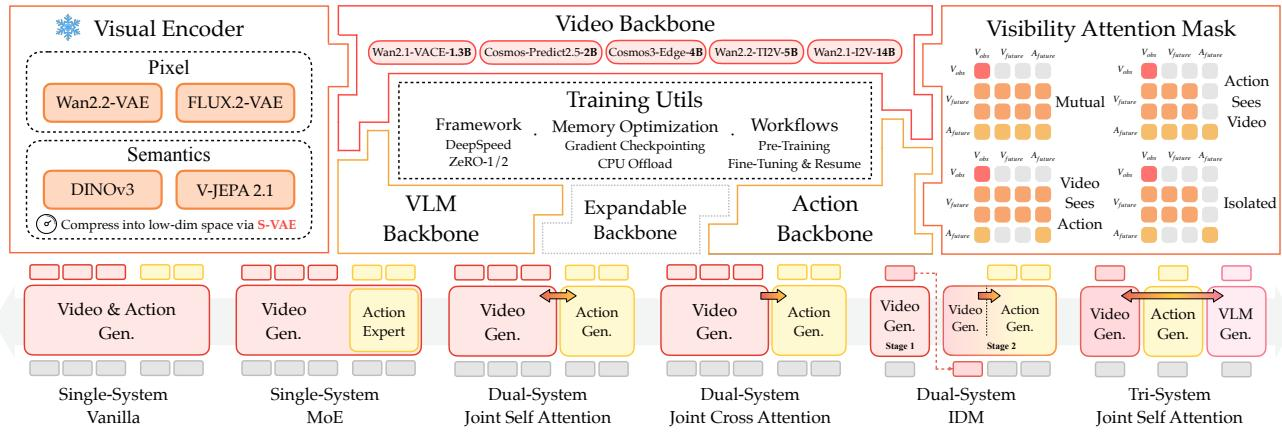
The composition rule C sequences the prepare, per-layer block, and finalize stages of the participating backbones. It creates three architecture families: Single-System, where video and action tokens share a transformer; Dual-System, which uses independent video and action backbones connected via self- or cross-attention; and Tri-System, which extends the dual layout with a frozen vision-language model feeding a separate trainable understanding stream.
Training Runtime The authors train every architecture under a single trainer using a joint flow-matching objective. A sample consists of a language instruction, a video window, an action chunk, an optional proprioceptive state, and a validity mask. The visual encoder encodes the video into latents, and each stream is noised to its own timestep. The architecture performs a joint forward pass to predict velocities for both streams. The objective minimizes the weighted difference between predicted and target velocities, with the validity mask restricting the action term to populated coordinates. Because timesteps are sampled independently, training covers the entire joint noise plane, ensuring any inference schedule remains in-distribution. The training runtime integrates DeepSpeed ZeRO, mixed precision, and memory optimization utilities like gradient checkpointing.
Deployment Runtime Every checkpoint is served by a policy server that rebuilds the architecture from a self-contained record. The server decouples the inference mode from the denoising schedule.
As shown in the figure below:
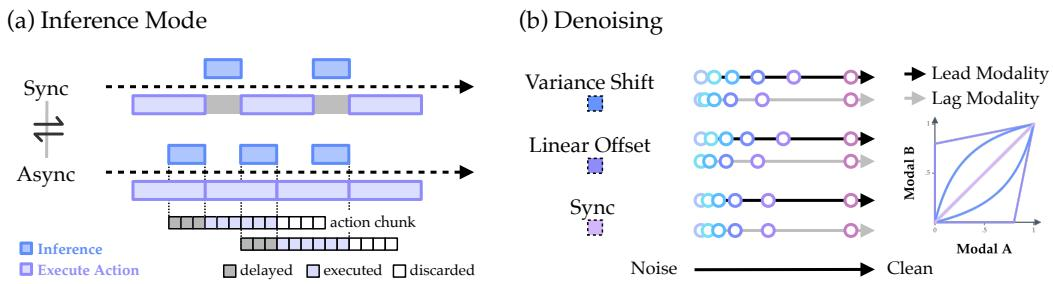
The inference mode determines when inference runs. In synchronous mode, the server blocks on a fresh inference whenever the action buffer empties. In asynchronous mode, a background worker prefetches the next chunk while the current buffer executes, splitting the chunk into a delayed prefix, an executed window, and a discarded tail. The denoising schedule defines the path through the joint noise plane. The synchronized schedule advances both streams in lockstep. Asynchronous schedules use variance shift or linear offset functions to let one stream lead, allowing the model to trace different paths through the noise plane covered during training.
Evaluation Protocol OpenWAM-Infra evaluates trained checkpoints through a client-server pipeline. Benchmarks connect as thin clients over a persistent WebSocket connection, sending observations and receiving actions in native physical units.
Refer to the figure below.
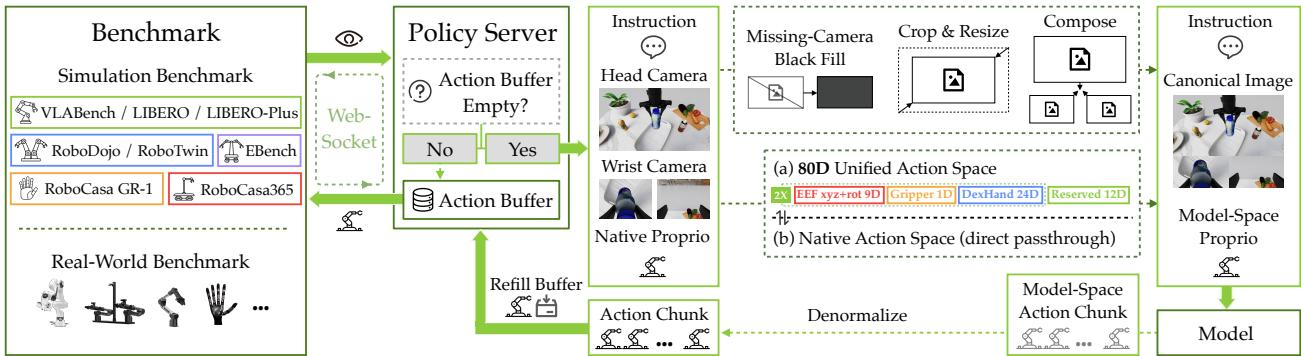
The policy server handles all model-facing conversions. It canonicalizes camera views, normalizes proprioceptive states, and maps them into the model's action representation. To support cross-embodiment training, the authors define a unified 80-dimensional action space with fixed slot semantics for end-effector position, rotation, gripper, and dexterous hand, plus reserved slots for embodiment-specific channels. Each dataset declares an index map to scatter its native actions into this unified space, and the validity mask ensures unmapped coordinates receive no gradient. The predicted action chunk is mapped back and denormalized before returning to the robot.
OpenWAM-α Instantiation Building on the design principles derived from controlled studies, the authors instantiate OpenWAM-α. The architecture adopts a Dual-System with joint self-attention, using a frozen Wan2.2-VAE as the visual encoder, a pretrained Wan2.2-TI2V-5B DiT for the world stream, and a dedicated 1B-parameter ActionDiT for the action stream. The visibility mask uses a mutual mode with first-frame-causal intra-video attention. The model is trained end-to-end in a single stage on a mixture of egocentric human, real-world robot, and synthetic robot data, using the joint flow-matching objective with independently sampled timesteps. At deployment, OpenWAM-α follows a synchronized denoising schedule, advancing both streams in lockstep along the diagonal of the joint noise plane, and utilizes acceleration techniques like prompt-embedding caching and compiled joint denoising loops to achieve real-time control speeds.
Experiment
The evaluation protocol serves checkpoints through a client-server pipeline across eight simulation benchmarks, with a unified action space enabling cross-embodiment training. Controlled studies on RoboTwin2.0 show that stronger generative backbones and compact representation encoders improve performance, that explicit world-to-action information flow during training with synchronized denoising is necessary, and that embodied pretraining primarily boosts out-of-domain generalization while shifting the preferred attention mask to mutual visibility. On the eight benchmark suite, OpenWAM-α ranks top-tier on most tasks and sets a state of the art on EBench, though it trails VLAs on out-of-distribution splits like LIBERO-Plus due to limited single-arm pretraining data and pixel-level prediction sensitivity. Real-robot tests across single-arm, bimanual, and dexterous-hand embodiments confirm strong performance, including on an entirely unseen dexterous platform, while the VLA versus WAM comparison shows WAMs fit in-distribution tasks better but VLAs generalize better under distribution shift.
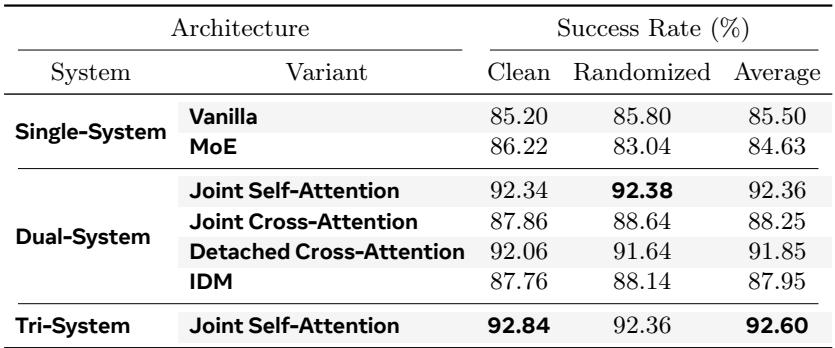
The architecture ablation study evaluates single-, dual-, and tri-system variants, showing that performance improves with increasing architectural capacity. Among dual-system variants, joint self-attention performs best, while the tri-system model achieves the highest overall success rate. The dual-system joint self-attention is selected for subsequent experiments to balance performance and complexity. Performance improves consistently from single- to dual- to tri-system architectures. Joint self-attention is the strongest dual-system variant, outperforming joint cross-attention and detached cross-attention. The tri-system model achieves the best overall success rate, but dual-system joint self-attention is chosen for further experiments.
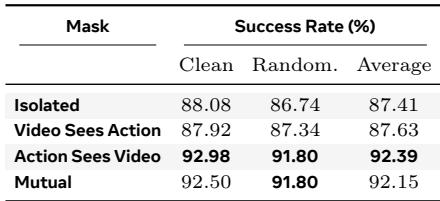
The table compares four attention masking strategies for information flow between world and action streams during training. Strategies that allow the action stream to access world features achieve notably higher success rates than those that do not, while the reverse flow has little additional impact. Isolated and Video Sees Action masks underperform by roughly five percentage points compared to masks that expose world features to the action stream. Action Sees Video and Mutual masks yield similar strong success rates, with Action Sees Video slightly ahead on clean and average metrics. Adding the action-to-world path (Mutual) provides only a marginal change over Action Sees Video, indicating world-to-action flow is the critical direction.
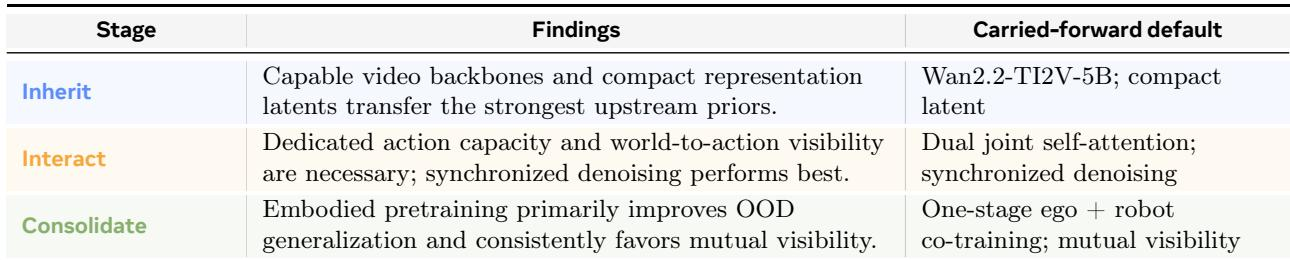
The table outlines the design choices for OpenWAM-α, derived from a systematic study. It shows that inheriting a capable video backbone with a compact latent representation, using a dedicated action stream with synchronized denoising, and adopting mutual visibility during co-training are the key components that lead to strong performance. A capable video backbone with compact latent representation is the preferred starting point. A dedicated action stream with world-to-action visibility and synchronized denoising is necessary. Embodied pretraining with mutual visibility improves out-of-distribution generalization.
OpenWAM-α is pretrained on a curated multi-domain dataset combining egocentric human video, real robot data, and synthetic robot data, reducing a raw pool of about 1.33 billion frames to 518 million frames through cleaning and subsampling. The mixture balances sources with proportional sampling, with the largest shares coming from egocentric human video and simulation data, while real robot sources contribute smaller but meaningful portions. The pretraining data spans three data types: egocentric human video, real robot demonstrations, and synthetic robot data. Curation and per-source subsampling reduce the raw dataset from roughly 14,300 hours to about 6,400 hours. Egocentric human video and simulation data each account for about 30% of the final training share, while real robot sources together contribute the remaining 40%. The data covers single-arm, bimanual, mobile, and dexterous manipulation settings across different sources. The final training set includes 21 distinct embodiments, combining human and robot embodiments.
OpenWAM-α achieves top-tier performance across most benchmarks, setting a new state of the art on the mobile bimanual EBench while remaining competitive with leading VLAs on single-arm and bimanual tasks. It also demonstrates strong generalization to unseen embodiments, such as dexterous hands, outperforming a representative VLA baseline. OpenWAM-α leads the runner-up by roughly 4 points on both success rate and score on the mobile bimanual benchmark. On bimanual benchmarks with clean-to-random and real-robot settings, OpenWAM-α is the strongest world-action model, though VLAs still hold the top spots. On dexterous-hand tasks with an unseen embodiment, OpenWAM-α outperforms a representative VLA by a clear margin across all tasks and setups.
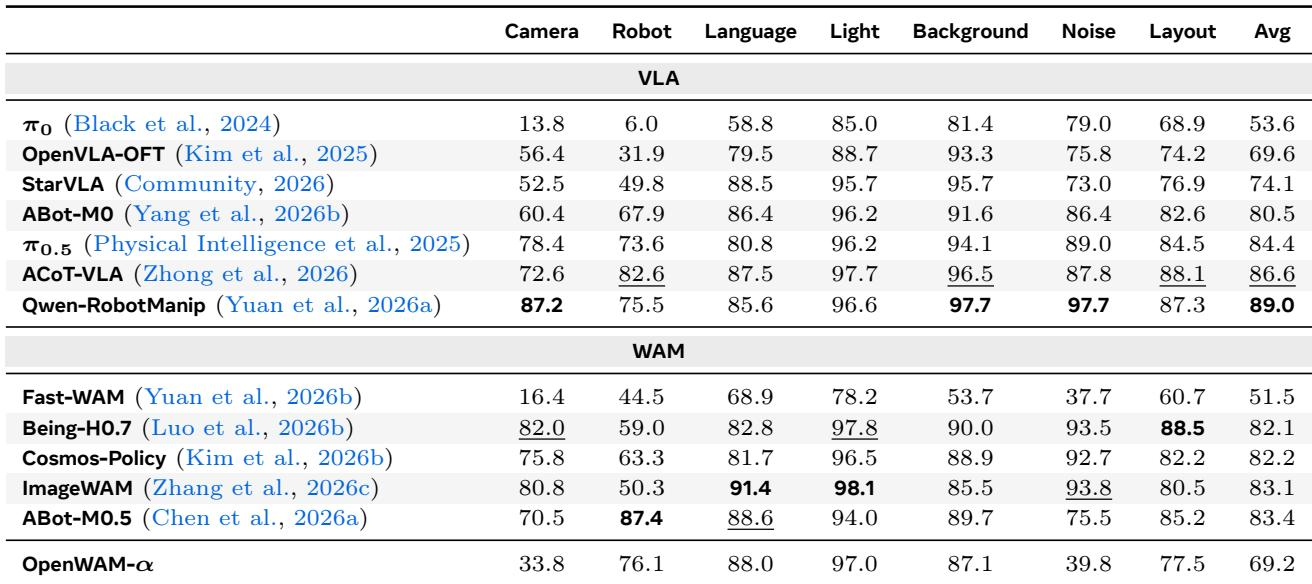
Ablation studies show that performance improves consistently from single- to dual- to tri-system architectures, with joint self-attention as the strongest dual-system variant, though the tri-system model is ultimately traded for dual-system joint self-attention to balance complexity. Masking experiments reveal that allowing the action stream to access world features is the critical information flow, with Action Sees Video and Mutual masks performing similarly and far better than strategies that block this direction. The final OpenWAM-α design combines a capable video backbone with compact latent representation, a dedicated action stream with synchronized denoising, and mutual visibility during co-training, pretrained on a curated multi-domain dataset of egocentric human video, real robot, and synthetic data. Across benchmarks, OpenWAM-α sets a new state of the art on mobile bimanual tasks, remains competitive with leading VLAs on single-arm and bimanual settings, and demonstrates strong generalization to unseen embodiments like dexterous hands.