Command Palette
Search for a command to run...
TeleOCR : Analyse de documents numériques et capturés par caméra
TeleOCR : Analyse de documents numériques et capturés par caméra
Peng Cai Zhaofan Zou Shifa Liu Yikun Wang Jiawei Tang Kaicheng Yang Meng Tong MingKun Jiang Zhongjiang He Hao Sun
TeleOCR : Analyse documentaire unifiée pour documents numériques et documents photographiés par caméra
Résumé
L’analyse de documents vise à transformer des documents non structurés en représentations structurées et lisibles par machine. Les progrès récents des modèles vision-langage (VLMs) ont considérablement fait progresser l’analyse de documents. Toutefois, les approches existantes restent confrontées à deux défis majeurs. Premièrement, les méthodes découplées basées sur les VLMs dépendent fortement d’une analyse précise de la mise en page, tandis que les distorsions géométriques présentes dans les documents capturés par caméra peuvent engendrer des erreurs en cascade. Deuxièmement, bien que les méthodes basées sur les VLMs de bout en bout atténuent la dépendance à une détection explicite de la mise en page, elles souffrent souvent de génération redondante, d’hallucinations et d’un raisonnement structurel insuffisant dans les scénarios à haute résolution. Pour répondre à ces défis, nous proposons TeleOCR, un cadre unifié pour l’analyse de documents. TeleOCR introduit un apprentissage sensible aux déformations afin d’intégrer la perception géométrique dans les VLMs et propose un mécanisme d’échantillonnage adaptatif pour la représentation de mises en page complexes. De plus, une stratégie d’apprentissage découplant le contenu et la structure est développée pour modéliser explicitement la grammaire des formules et les structures des tableaux, permettant un apprentissage plus efficace de représentations structurées. Les expériences approfondies montrent que TeleOCR atteint des performances à l’état de l’art sur divers bancs d’essai d’analyse de documents. Il obtient des scores globaux de 96.87, 88.53 et 78.41 sur OmniDocBench v1.6, Wild-OmniDocBench et PureDocBench, respectivement, et se classe premier dans le ICDAR 2026 Sci-ImageMiner Challenge. Ces résultats valident l’efficacité et la capacité de généralisation de TeleOCR dans des scénarios complexes d’analyse de documents.
One-sentence Summary
China Telecom Artificial Intelligence Technology (Beijing) Co., Ltd. proposes TeleOCR, a unified document-parsing vision-language model framework that incorporates deformation-aware learning, adaptive sampling, and content-structure decoupled modeling of formula grammars and table structures to address cascading layout errors in camera-captured documents and hallucinations in high-resolution end-to-end generation, achieving state-of-the-art performance with overall scores of 96.87, 88.53, and 78.41 on OmniDocBench v1.6, Wild-OmniDocBench, and PureDocBench, respectively, and first place in the ICDAR 2026 Sci-ImageMiner Challenge.
Key Contributions
-
TeleOCR is presented as a unified VLM-based document parsing framework that incorporates deformation-aware learning, including region-level and global point-level mechanisms, to model geometric perception and document rectification inside the VLM. This design reduces cascading errors from geometric distortions in camera-captured documents.
-
The framework adds curvature-guided adaptive sampling for complex layout representation and content-structure decoupled learning for formula grammars and table structures. Large-scale document data engineering and structure-aware progressive training support parsing of text, tables, formulas, code, seals, and scientific figures.
-
On OmniDocBench v1.6, Wild-OmniDocBench, and PureDocBench, TeleOCR obtains overall scores of 96.87, 88.53, and 78.41, respectively, and ranks first in the ICDAR 2026 Sci-ImageMiner Challenge. These results demonstrate its effectiveness in complex digital and camera-captured document parsing scenarios.
Introduction
Document parsing converts unstructured document images into structured outputs such as Markdown, supporting training data construction and retrieval-augmented generation. The task matters because accurate text recognition, layout understanding, and structural reconstruction directly affect downstream system quality. Prior methods face a trade-off: end-to-end approaches are more robust to camera-induced geometric distortion but can be computationally expensive and couple structure reasoning with content generation, while decoupled approaches perform well on clean digital documents but suffer when layout errors propagate. The authors propose TeleOCR, a unified parsing framework that embeds deformation-aware learning into a VLM and replaces conventional detection with adaptive layout segmentation. It further introduces a content-structure decoupled learning strategy, first predicting structures for tasks such as tables and formulas and then generating content, which reduces optimization complexity and improves robustness across digital, camera-captured, and highly structured documents.
Dataset
-
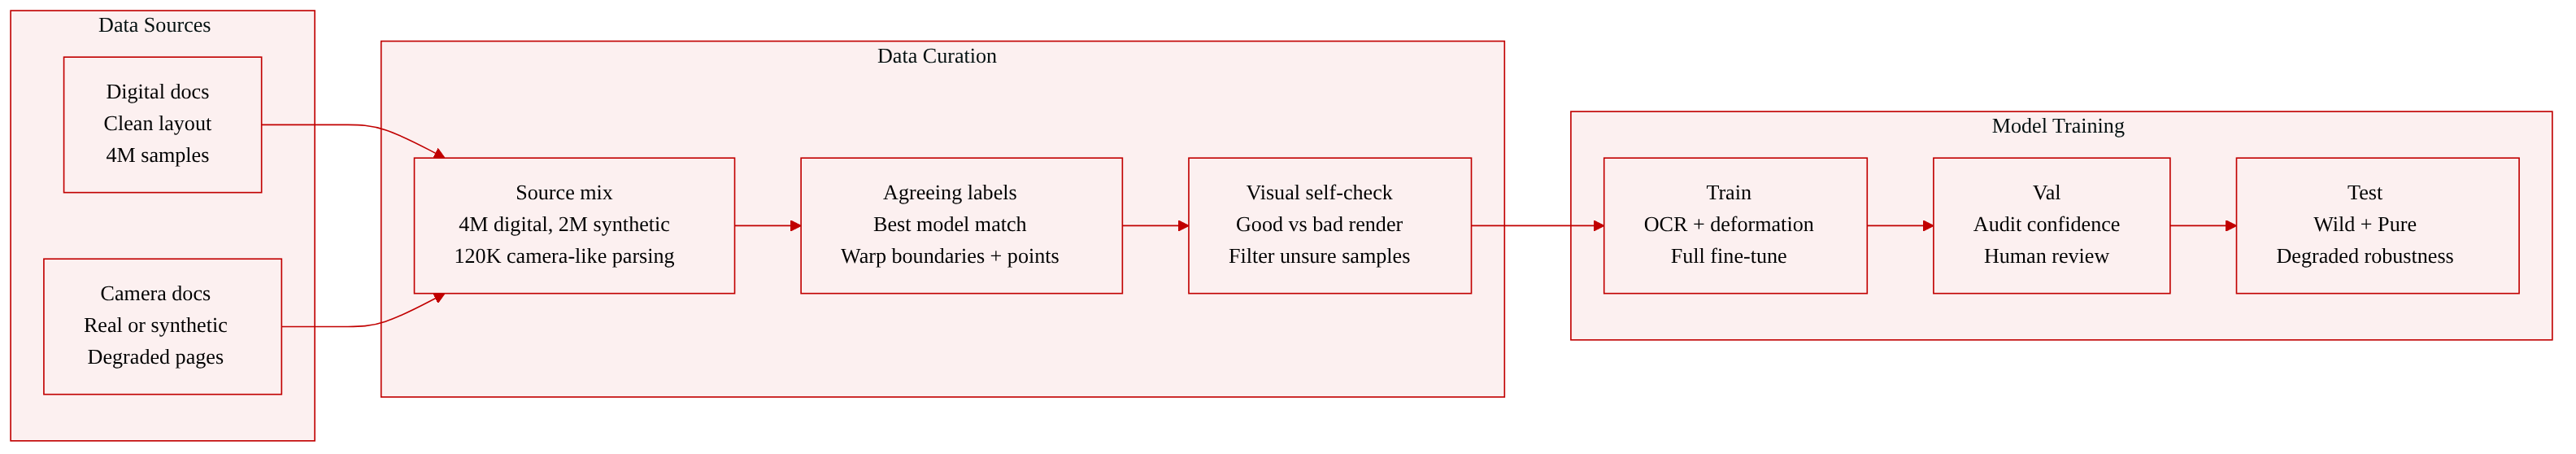
The authors build the dataset with an automated data-engineering pipeline instead of relying on large-scale manual annotation. The pipeline has three main purposes: generate reliable pseudo-labels, create deformation-aware training samples, and validate filtered data with a model-based reviewer.
-
High-confidence pseudo-labels come from Multi-node Consensus Voting, or MCV.
- Multiple heterogeneous models predict the same document sample.
- Agreement is scored by task: IoU for layout, Edit Distance for text, TEDS for tables, and CDM for formulas.
- The prediction with the highest average agreement is selected as the pseudo-label.
- If the best score does not pass a consensus threshold, the sample is routed to automatic correction or human verification.
-
The training data unifies digital documents and camera-captured documents.
- Digital documents provide clean layout and parsing supervision.
- Camera-captured documents are represented through synthetic deformation, not by collecting only real photographed documents.
- The authors apply document deformation generation to digital layouts, producing distorted images and corresponding warped geometry annotations.
-
Geometry metadata is constructed at two levels.
- Region-level supervision: N boundary points are sampled clockwise along the undistorted layout boundary and serialized as coordinate pairs.
- Point-level supervision: M by M control points are sampled uniformly on the undistorted document plane.
- The same deformation field is applied to the image, boundary points, and control points, producing warped boundaries and warped control points as training targets.
-
The boundary-point sampling uses a curvature-guided Douglas–Peucker strategy.
- Uniform sampling can over-sample flat regions and under-sample folds, corners, and creases.
- The authors adapt standard Douglas–Peucker distance with a local curvature term.
- Higher-curvature regions receive higher sampling priority, preserving sharp folds and local structural details under a limited sampling budget.
-
The Stage 2 deformation-aware training set is described as a mixture of digital and synthetic camera-captured data.
- 4 million digital document layout samples.
- 2 million synthetic camera-captured document samples.
- The synthetic set is split into 1.2 million region-level deformation samples and 0.8 million global point-level deformation samples.
- These samples use layout coordinates, global deformation control points, and region boundary points selected through MCV.
- About 120 thousand high-quality parsing samples are further augmented with camera-like degradations, including distortion, shadows, and blur.
-
An auxiliary image-to-image validation dataset is built to train the self-judgment model.
- Correct predictions are rendered back into visual canvases that preserve layout, text structure, tables as HTML-rendered images, and formulas rendered from LaTeX.
- Incorrect predictions are created using rule-based and LLM-guided perturbations, such as missing layout regions, merged or split layout blocks, text corruption, table structure errors, and formula syntax errors.
- The original image paired with a correct rendering forms a positive example, while the original image paired with a perturbed rendering forms a negative example.
- The paper does not report an exact total size for this auxiliary verification dataset.
- This data is used to filter pseudo-labels, identify error types, and route low-confidence samples to human review.
-
The evaluation datasets focus on degraded and camera-captured document parsing.
- Wild-OmniDocBench is built from OmniDocBench v1.5 and transforms digital documents into realistically captured images through printing, deformation, and image acquisition under diverse illumination. It includes geometric distortions, illumination variations, screen-capture artifacts, and environmental noise.
- PureDocBench-Degraded is constructed from PureDocBench-Clean electronic PDFs by simulating digital degradation and real-world acquisition conditions. It is used to test robustness on degraded, highly structured document layouts.
-
The paper does not describe an explicit image cropping strategy. Instead, processing and metadata construction are centered on geometry-aware sampling, deformation supervision, consensus-based pseudo-label selection, and rendered visual validation.
Method
The authors leverage a unified pipeline that couples high-quality data construction with a compact, progressively trained vision-language parsing model. The system is designed to handle diverse document structures such as text, layout, tables, and formulas while reducing dependence on manual annotation. On the data side, the pipeline first generates reliable pseudo-labels through multi-node consensus, then constructs deformation-aware samples for camera-captured documents, and finally uses a self-judgement model to verify and filter parsed results. On the model side, a multi-stage training process moves the model from basic visual-language alignment to explicit geometric perception, structured content parsing, and reinforcement-learning-based refinement.
The pseudo-label generation module avoids reliance on a single parser or detector. Instead, the authors define a set of heterogeneous models M={M1,M2,…,MN}, where each model produces a prediction yi=Mi(x) for the same input document sample x. The agreement between two predictions is measured by a task-specific consistency function S(yi,yj), such as Intersection-over-Union for layout detection, edit distance for text recognition, TEDS for table parsing, and CDM for formula parsing. Refer to the figure below.
Based on this consistency measure, each prediction receives a consensus score representing its average agreement with the other models:
Ci=N−11j=i∑S(yi,yj)The prediction with the strongest agreement is selected as the pseudo-label:
y^=yk,k=argimaxCiIf the highest consensus score exceeds a threshold τ, the sample is accepted as a high-confidence training instance. Otherwise, the disagreement among models is treated as an uncertainty signal, and the sample is routed to automatic correction or human verification. This mechanism reduces single-model bias and prevents systematic parsing errors from being repeatedly propagated into the training corpus.
The next stage addresses the domain gap between digital documents and camera-captured documents. Camera images often contain geometric distortions, shadows, blur, and curved boundaries, which can break the rectangular region assumption used by many layout detection systems. To introduce deformation awareness, the pipeline constructs two kinds of supervision from high-consistency samples. For region-level geometry, N boundary points are sampled along an undistorted layout boundary in clockwise order and serialized as a point sequence. For global geometric modeling, M×M control points are uniformly sampled on the flat document plane. Synthetic camera-like images are then generated by applying a deformation mapping to the original image, boundary points, and control points, producing distorted images together with corresponding warped boundaries Rw and warped control points Pw.
During early training, the model learns to predict the warped control points Pw, which gives it explicit access to document deformation patterns. The warped region boundaries Rw are later used to replace conventional rectangular boxes, reformulating layout detection as boundary point prediction. This removes the dependency on regular rectangular layout regions and enables the model to represent curved, folded, or irregularly shaped document elements.
To improve boundary representation under a limited point budget, the authors also introduce curvature-guided Douglas–Peucker sampling. Standard uniform boundary sampling can oversample flat regions while undersampling corners, creases, and folds. The method uses Douglas–Peucker distance to preserve global contour shape and modulates point importance using normalized local curvature:
Si=di(1+λκ^i)Here di denotes the Douglas–Peucker relevance of a point, and κ^i is the normalized local curvature. When curvature is low, the strategy behaves like ordinary Douglas–Peucker sampling. When curvature is high, points near sharp folds, corners, or local discontinuities receive higher priority. A selected point becomes a recursive sampling node when its score exceeds a threshold, preserving critical geometry without introducing excessive supervision noise.
After consensus voting and deformation-aware construction, the pipeline introduces a self-judgement model to improve pseudo-label reliability. Instead of comparing raw text, table, or formula outputs directly with the original document, the system converts predictions into visual renderings. Layout predictions are projected onto a page canvas, text is reorganized into paragraphs, tables are rendered through HTML-style structural representations, and formulas are converted into image renderings. This turns cross-modal image-text verification into a more stable image-to-image consistency check between the original document and its reconstructed output.
The self-judgement model is trained using positive and negative image pairs. A high-confidence prediction is rendered as a correct candidate, while rule-based and language-model-guided perturbations generate incorrect candidates. Perturbations cover missing, displaced, overlapping, merged, split, or reordered layout regions; text corruption, omission, or misclassification; table structure errors; and formula syntax or type errors. Given the original image I(x) and a rendered prediction I^y, the model evaluates consistency under checking criteria E={ek}k=1K:
rk=M(I(x),I^y,ek)The individual analyses are aggregated into a structured reasoning sequence R=(r1,…,rK), which produces a final consistency decision. This enables automatic filtering of pseudo-labels, identification of error types, and generation of error explanations. Low-confidence samples can then be transferred to human verification.
For the parsing model itself, the authors use a compact vision-language architecture of approximately 1.2B parameters. The system combines a pretrained vision encoder, a lightweight language model with about 0.6B parameters, and a multi-layer perceptron aligner that maps visual representations into the language model’s embedding space. The aligner is trained from scratch, while the vision encoder and language model provide pretrained perception and reasoning foundations. As shown in the figure below.
The model is trained through four progressive stages. The first stage performs vision-language alignment. The language model remains frozen, while the vision encoder and the patch merger MLPs are optimized using OCR-oriented data, image captioning, interleaved image-text data, and visual question answering supervision. This establishes basic character recognition and layout understanding capabilities.
The second stage introduces deformation-aware training. The model learns to predict downsampled geometric control points, reducing deformation modeling to a smaller set of coordinates rather than a dense distortion field. Training combines digital layout data with synthetic camera-captured samples constructed from consensus-selected boundary points, global control points, and curvature-guided boundary representations. Additional parsed samples are augmented with distortion, shadows, and blur to better match realistic camera conditions. This stage strengthens the model’s ability to recognize documents that violate the flat rectangular layout assumption.
The third stage adopts content-structure decoupled learning. For formula parsing, the system builds a syntax token library and extracts structure labels from LaTeX annotations, allowing the model to learn formula content and grammatical structure separately. For table parsing, the model uses table topology tokens while removing cell contents, forcing it to focus on row-column relationships and merged-cell patterns. This separation supports unified modeling of text, formulas, tables, and scientific figures, especially when structural semantics must be preserved rather than merely recognized as characters.
The fourth stage applies reinforcement learning based on Group Relative Policy Optimization. Since supervised token-level loss does not directly optimize end-task parsing quality, the model is further aligned with task-specific verifiable rewards. For text, tables, and formulas, the reward is defined according to the output format and evaluation target:
Rtask(y,y^)=⎩⎨⎧1−NED(y,y^),TEDS(y,y^),CDM(y,y^),Text,Table,Formula.Here y denotes the reference target and y^ denotes the model prediction. Higher reward values indicate stronger structural or semantic consistency between prediction and ground truth. This final stage refines the parser under task-level objectives, improving robustness on complex real-world document parsing scenarios.
Experiment
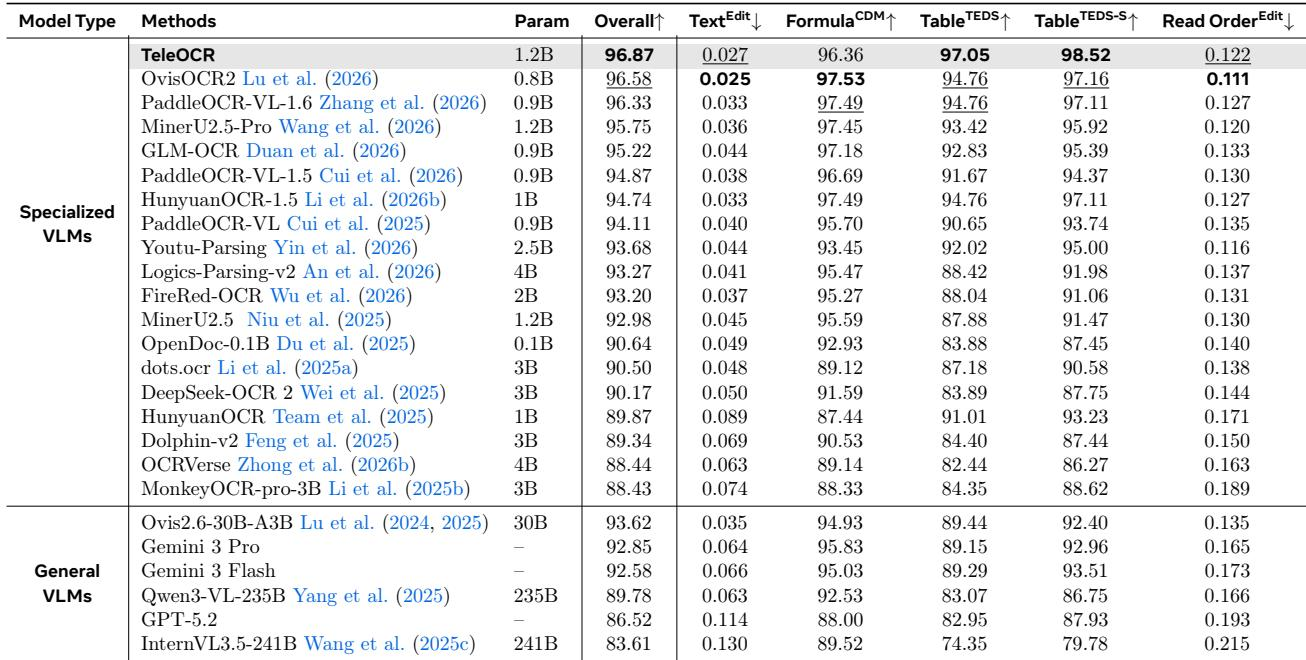
TeleOCR is evaluated on digital, real-captured, degraded, and scientific figure-to-table parsing benchmarks to assess accuracy, robustness, and generalization. It consistently outperforms pipeline and end-to-end baselines on clean digital pages, especially for text, tables, and reading order, while showing competitive formula handling. It also remains strong under realistic camera capture and degradation settings, and transfers effectively to scientific figure-to-table conversion through content-structure decoupled learning.
TeleOCR records the strongest overall result in the comparison, with the highest table reconstruction scores and near the strongest text and reading order results. Its formula recognition is competitive but trails the best formula metric, indicating that formula handling remains less dominant than its other outputs. The formula errors are associated with mismatches between early layout parsing and benchmark annotation granularity. Leads overall performance and both table reconstruction metrics among the evaluated models. Formula recognition is constrained by early layout parsing granularity and annotation consistency.
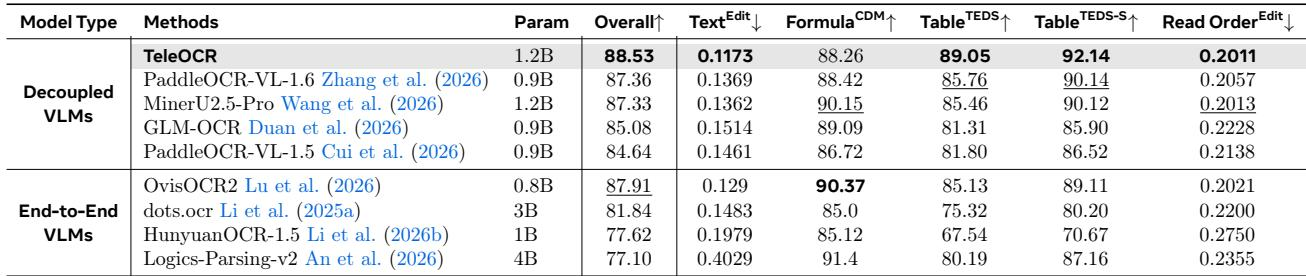
TeleOCR reaches the highest overall score among compared camera-captured document parsing methods and leads in text, table, and reading order metrics. Its advantage is especially clear in structured table extraction, while formula performance remains close to strong end-to-end baselines. These results support strong robustness under real-world capture degradations such as geometric distortion, illumination variation, and environmental noise. TeleOCR ranks first overall and achieves the best text edit error, table TEDS scores, and reading order error among the compared methods. OvisOCR2 shows competitive formula extraction but trails TeleOCR in overall quality and structured table recovery. Compared methods show more variation in table extraction than in formula extraction, indicating weaker robustness on degraded real-captured layouts.
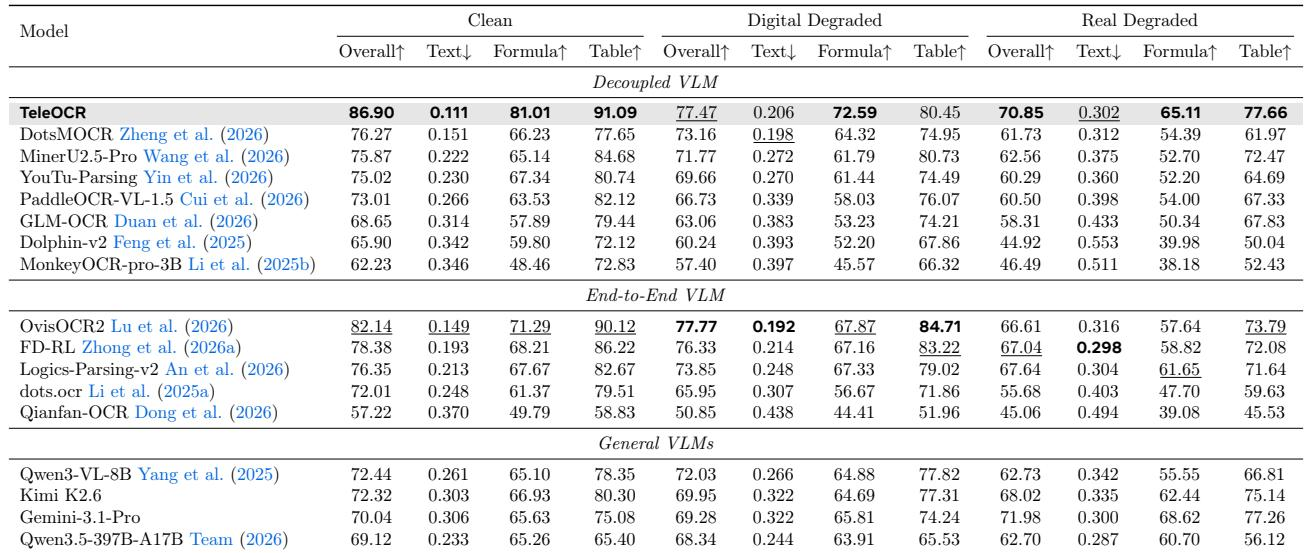
TeleOCR achieves the highest overall scores on clean, digital degraded, and real degraded document parsing tracks among the listed comparison models. The results show that parsing quality generally decreases as degradation becomes more severe, yet TeleOCR remains ahead of the other systems on overall performance. This pattern supports robust document parsing under high-quality rendering, simulated digital degradation, and real-world capture. TeleOCR leads overall on clean, digital degraded, and real degraded parsing tasks. It has the lowest text edit distance on clean and real degraded tracks and the strongest formula scores across tracks. Table reconstruction is highest on clean and real degraded tracks and remains competitive under digital degradation.
TeleOCR leads the data extraction comparison by achieving the highest overall weighted score and the highest TEDS among the listed teams. It also outperforms the best baseline clearly, while showing competitive RMS relative to the strongest competitors. TeleOCR ranks first overall, with the strongest TEDS and weighted performance. VLMinators is the closest competitor, with comparable RMS but lower TEDS and weighted score.
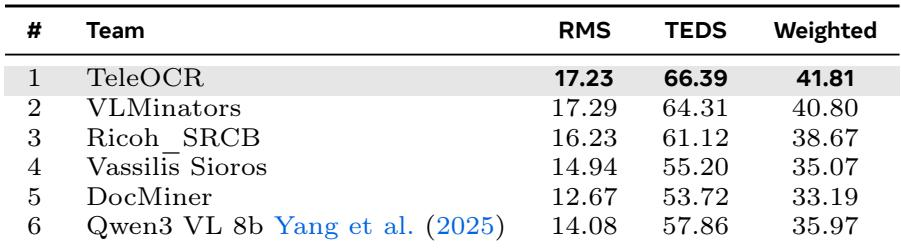
The experiments compare TeleOCR against other document parsing and extraction methods across overall parsing quality, camera-captured robustness, degradation tracks, and structured data extraction. The results consistently validate TeleOCR’s strength in document understanding, especially in table reconstruction, text quality, reading order, and robustness under real-world capture and simulated degradation. Formula recognition remains competitive but less dominant, likely due to mismatched layout parsing granularity and annotation consistency, while overall findings show that TeleOCR outperforms baselines in practical document parsing settings.