Command Palette
Search for a command to run...
DiaMoE-TTS: A Unified IPA-Based Dialect TTS Framework with Mixture-of-Experts and Parameter-Efficient Zero-Shot Adaptation
DiaMoE-TTS: A Unified IPA-Based Dialect TTS Framework with Mixture-of-Experts and Parameter-Efficient Zero-Shot Adaptation
Ziqi Chen Gongyu Chen Yihua Wang Chaofan Ding Zihao Chen Wei-Qiang Zhang
Abstract
Dialect speech embodies rich cultural and linguistic diversity, yet building text-to-speech (TTS) systems for dialects remains challenging due to scarce data, inconsistent orthographies, and complex phonetic variation. To address these issues, we present DiaMoE-TTS, a unified IPA-based framework that standardizes phonetic representations and resolves grapheme-to-phoneme ambiguities. Built upon the F5-TTS architecture, the system introduces a dialect-aware Mixture-of-Experts (MoE) to model phonological differences and employs parameter-efficient adaptation with Low-Rank Adaptors (LoRA) and Conditioning Adapters for rapid transfer to new dialects. Unlike approaches dependent on large-scale or proprietary resources, DiaMoE-TTS enables scalable, open-data-driven synthesis. Experiments demonstrate natural and expressive speech generation, achieving zero-shot performance on unseen dialects and specialized domains such as Peking Opera with only a few hours of data.
One-sentence Summary
Tsinghua University and Giant Network present DiaMoE-TTS, a unified IPA-based framework built on F5-TTS that standardizes phonetic representations and resolves grapheme-to-phoneme ambiguities, and employs a dialect-aware Mixture-of-Experts with parameter-efficient LoRA and conditioning adapters for zero-shot adaptation, enabling scalable natural synthesis and rapid transfer to unseen dialects and specialized domains such as Peking opera with minimal data.
Key Contributions
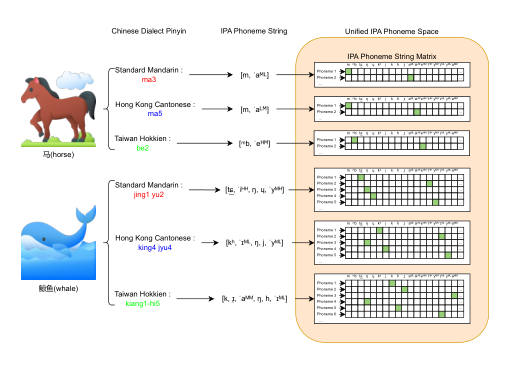
- A unified IPA-based front-end replaces conventional pinyin or character inputs with explicit phonetic sequences, ensuring precise pronunciation modeling across Chinese dialects.
- A dialect-aware Mixture-of-Experts (MoE) module in the text embedding layer captures dialect-aware phonological variations.
- Parameter-efficient adaptation with Low-Rank Adaptors (LoRA) and Conditioning Adapters enables rapid transfer to new dialects, achieving zero-shot performance on unseen dialects and specialized domains such as Peking Opera with only a few hours of data.
Introduction
Dialect text-to-speech is vital for preserving linguistic diversity in regions with many local languages, such as China and Europe, but development has been slowed by scarce training data, inconsistent writing systems, and the absence of TTS-ready corpora. Existing public resources for dialects are overwhelmingly designed for automatic speech recognition, leaving no unified open pipeline for zero-shot dialect speech synthesis. The authors bridge this gap by constructing a harmonized multilingual dataset from open ASR records and pairing it with an International Phonetic Alphabet (IPA) pronunciation lexicon, then propose a unified framework built on F5-TTS. Their system introduces an IPA-based frontend to replace character or pinyin inputs, a Mixture-of-Experts module in the text embedding layer to capture dialect-specific phonological variation, and an adaptation strategy that rapidly extends to extremely low-resource dialects while preserving knowledge from high-resource ones. The framework achieves performance nearing commercial systems and is released with open dataset, methodology, and code to support reproducible research.
Dataset
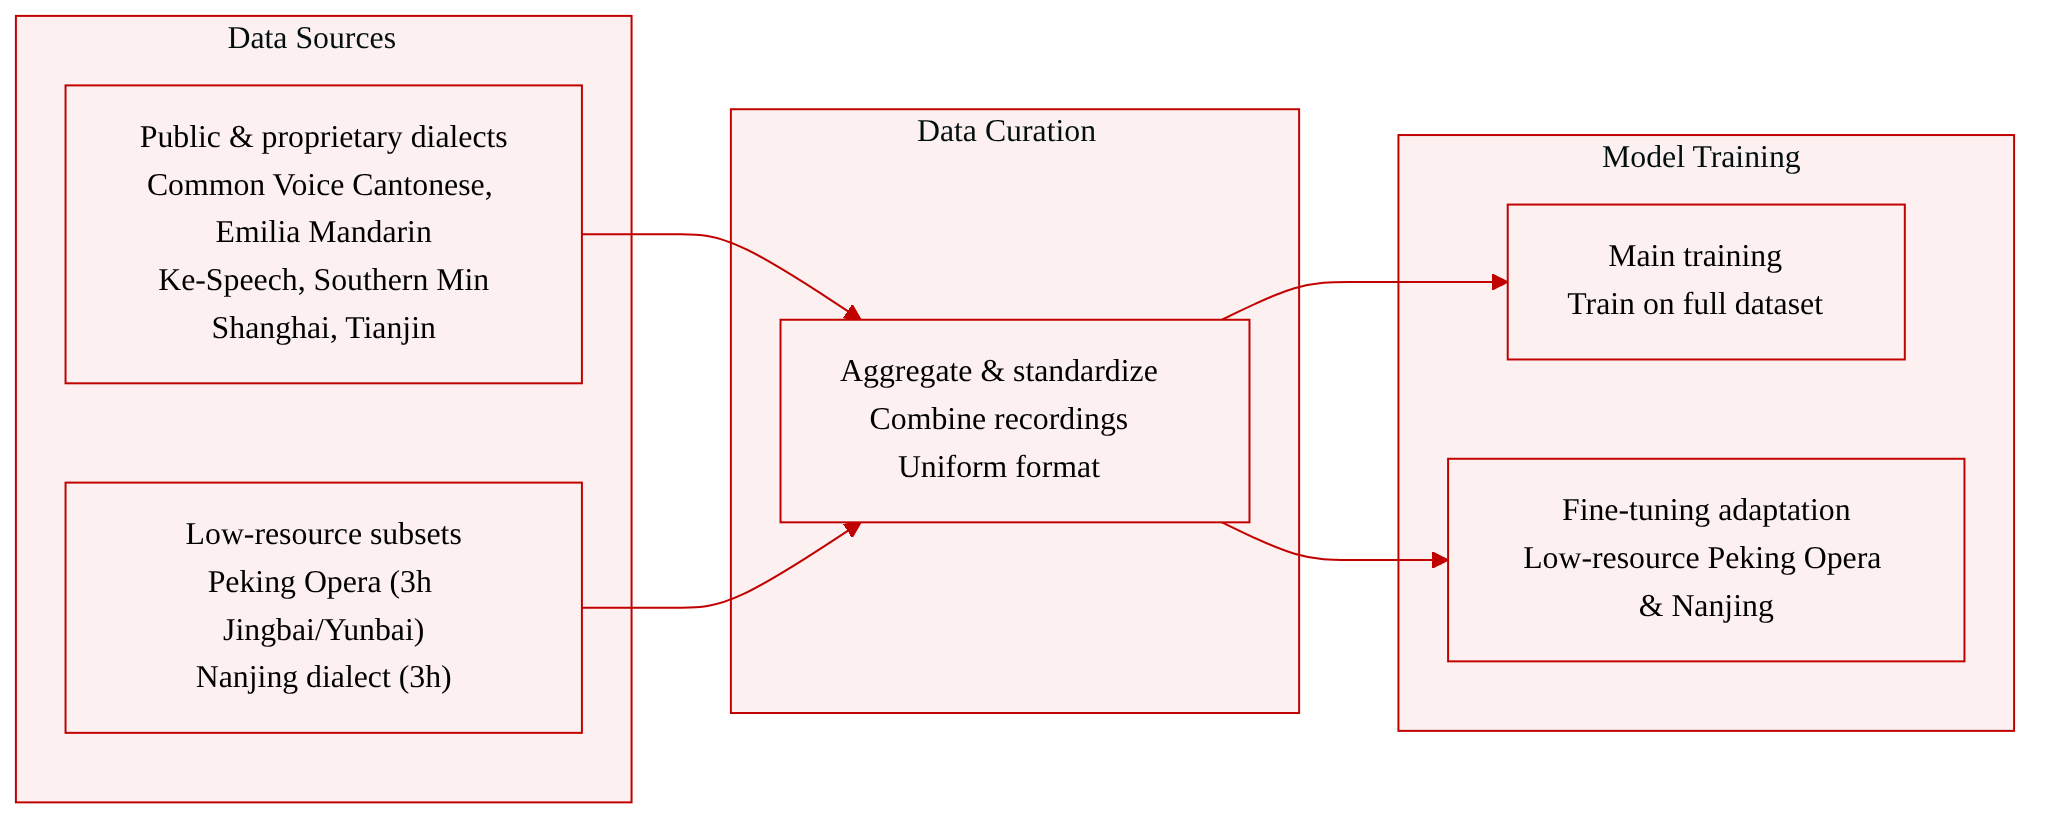
The authors construct a multi-dialect speech corpus from both public and proprietary sources to train and evaluate their model.
-
Public datasets:
-
Common Voice Cantonese (Mozilla)
-
Emilia Mandarin dataset
-
Dialectal speech from the Ke-Speech corpus
-
An open-source Southern Min dataset
-
Proprietary additions:
-
Commercially licensed speech in the Shanghai and Tianjin dialects, intended to extend dialect coverage.
-
Low-resource fine-tuning data:
-
Approximately 3 hours of professionally recorded Peking Opera recitation that includes both Jingbai and Yunbai performance styles.
-
An equal amount (3 hours) of Nanjing dialect speech, serving as a comparison condition for dialectal adaptation experiments.
The broader set of dialect recordings is used for the main training stage. For low-resource fine-tuning, only the small Peking Opera and Nanjing subsets are employed, allowing the authors to study adaptation to highly stylised or under-represented speech varieties. No additional filtering rules, cropping strategies, or metadata construction details are reported in this summary.
Method
The authors propose a unified framework for dialect text-to-speech (TTS) built on a four-stage training strategy that progressively extends a strong monolingual base model to handle multiple Chinese dialects and finally adapts to low-resource novel dialects. The process begins with Stage 0, where training is initialized from a pre-trained F5‑TTS checkpoint. This model was originally trained on large-scale Mandarin and English data, providing a robust generative prior for high-quality speech synthesis.
Stage 1 and Stage 2 perform joint training on a unified dataset of IPA‑aligned text‑speech pairs covering Standard Mandarin and several Chinese dialects. The model maps diverse input representations (such as pinyin or characters) into a shared IPA phoneme space. Stage 1 trains this alignment without dialect‑specific constraints. However, joint training can cause stylistic homogenisation and weaken dialect‑characteristic prosody. To counteract this, Stage 2 introduces a Dialect‑style Mixture of Experts (MoE) module placed after the text embedding. As shown in Equation 1, the module operates as a residual block:
h=Etext(pIPA),h′=MoE(h)+h
where pIPA is the input IPA sequence, h the original text representation, and h′ the dialect‑aware feature. The MoE contains multiple expert networks, each specialised for the phonological patterns of a particular dialect, and a learnable gating mechanism that dynamically routes the input to the most relevant experts. To guide the gate, an auxiliary dialect classification loss Ldialect is added. Gate logits g are obtained from a mean‑pooled sequence representation:
s=T1∑t=1Tht∈RD,g=Gate(s)∈RK
and a cross‑entropy loss is computed over a batch of N samples with ground‑truth dialect labels yi:
Ldialect=−N1∑i=1Nlog∑j=1Kexp(gi,j)exp(gi,yi)
The overall training objective in this stage combines the original flow‑matching loss LOT−CFM with a weighted term λ⋅Ldialect, where λ=0.1 during Stage 2 and λ=0 elsewhere. This design allows the shared text encoder to learn dialect‑aware representations while preserving computational efficiency through sparse expert activation.
For low‑resource dialects with only a few hours of data, Stage 3 performs rapid parameter‑efficient fine‑tuning. The backbone model remains frozen; only low‑rank adaptation (LoRA) matrices applied to the query and value projections of attention layers in the input embedding and diffusion‑transformer (DiT) blocks, together with a newly inserted Conditioning Adapter in the text embedding module, are trained. The MoE structure is kept frozen to retain the previously learned routing behaviour and to avoid overfitting. To further combat data scarcity, simple acoustic data augmentation is employed: each original utterance is modified with pitch and time‑scale factors of 0.85, 0.9, 0.95, 1.05, 1.1, and 1.15. These altered copies expand the training set without altering dialectal style, enabling the model to synthesise speech in a new dialect in a few‑shot setting while preserving its existing multilingual and multi‑dialect capabilities.
Experiment
The evaluation setup spans multiple Chinese dialects including Cantonese, Shanghai, Tianjin, and specialized Peking Opera styles, using objective metrics (word error rate, UTMOSv2) and subjective MOS. The model effectively learns from minimal data via continual learning, avoiding the forgetting observed with direct fine-tuning, and ablation studies confirm that incorporating the Mixture-of-Experts architecture and IPA phonetic representations improves performance. Although it trails commercial baselines on certain metrics, this gap is attributed to its broader dialect coverage and integrated voice cloning, demonstrating a viable low-resource TTS framework.
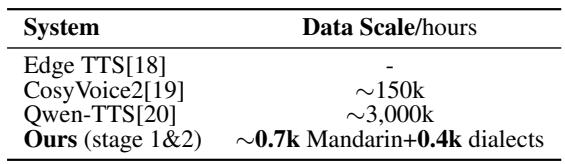
The proposed TTS system is trained on roughly 1.1k hours of speech, which is orders of magnitude less than the 150k to 3,000k hours used by commercial systems CosyVoice2 and Qwen-TTS. Despite this minimal data scale, the framework leverages continual learning to support a wide range of Chinese dialects and voice cloning, showing that effective low-resource TTS is achievable. The training data used by the system is approximately 0.7k hours of Mandarin and 0.4k hours of dialect speech, while CosyVoice2 uses around 150k hours and Qwen-TTS uses around 3,000k hours. Learning from such limited data becomes possible through continual learning, enabling the model to handle many dialects and voice cloning without the massive datasets typical of commercial systems.
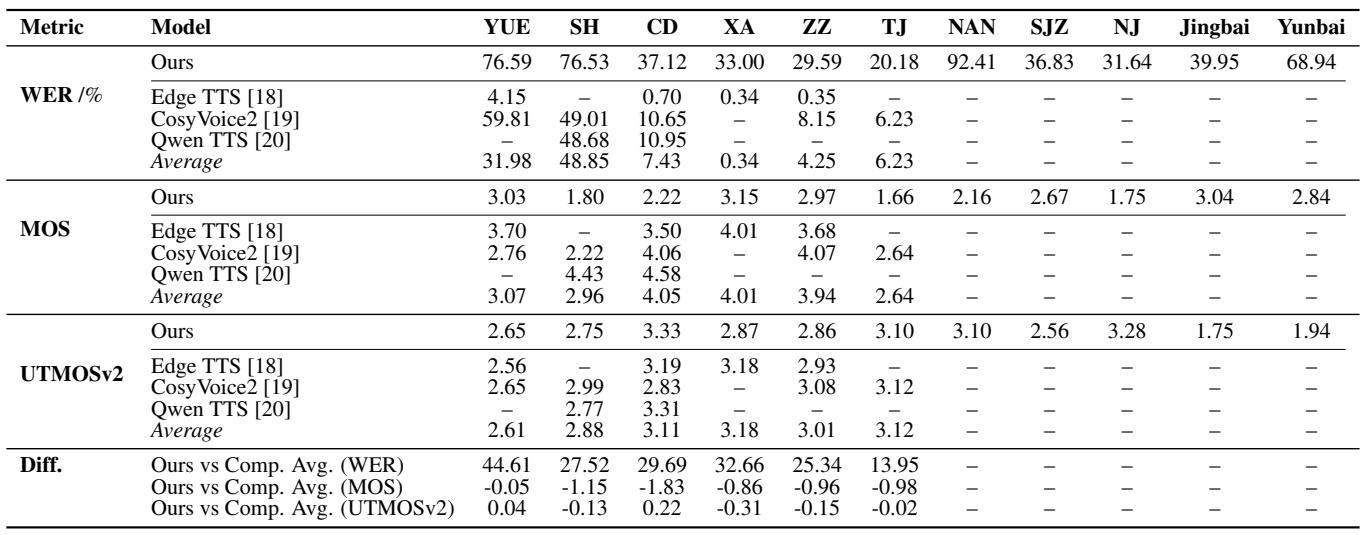
The proposed TTS system synthesizes speech for 11 Chinese dialects, including low-resource ones like Peking Opera and Nanjing that commercial baselines do not support. On the dialects shared with commercial models, the proposed system yields substantially higher word error rates and lower naturalness scores, highlighting a trade-off between wide dialect coverage and per-dialect performance. The model covers a wide dialect set, including low-resource varieties such as Jingbai, Yunbai, and Nanjing, whereas commercial systems were evaluated on at most five common dialects. For the dialects where comparisons are possible, commercial TTS models achieved far lower word error rates, often in the single digits, while the proposed model's rates were considerably higher. Mean opinion scores for the proposed model ranged from moderately low to moderate, while a commercial baseline reached consistently higher naturalness ratings on its limited dialect subset.
An ablation study across four Chinese dialects shows that both the Mixture of Experts architecture and IPA phonetic input contribute to better speech synthesis. The full model with MoE and IPA achieves the highest naturalness scores and lowest word error rates, while using pinyin drastically reduces quality. Removing MoE leads to modest degradation, confirming the benefit of both components. The full model with MoE and IPA achieves the highest MOS in three of the four dialects, with particularly large gains over the variant using pinyin. Switching from IPA to pinyin input causes a severe drop in MOS across all dialects, demonstrating the importance of precise phonetic representation. The version without MoE records higher word error rates, indicating that the MoE architecture improves the intelligibility of synthesized speech.
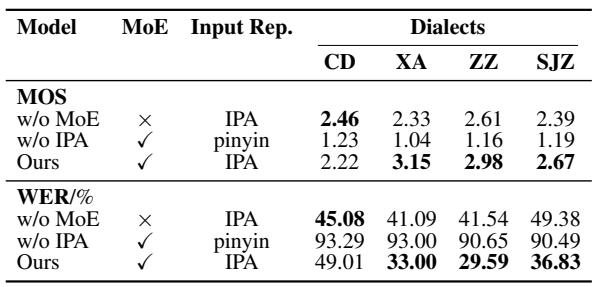
The proposed TTS system trains on only 1.1k hours of speech, using continual learning to support 11 Chinese dialects and voice cloning despite data scarcity. Evaluated against commercial systems, it achieves broader dialect coverage but at the cost of lower naturalness and higher word error rates on shared dialects. An ablation study confirms that both a Mixture of Experts architecture and IPA phonetic input are essential for maintaining synthesis quality.